P.S. Kostenlose und neue DP-300 Prüfungsfragen sind auf Google Drive freigegeben von PrüfungFrage verfügbar: https://drive.google.com/open?id=1kZePR5Fib8y-Xon1kRcYcvgQPchlmnqS
Um keine Reue und Bedauern in Ihrem Leben zu hinterlassen, sollen Sie jede Gelegenheit ergreifen, um das Leben zu vebessern. Haben Sie das gemacht? Die Fragenkataloge zur Microsoft DP-300 Zertifizierungsprüfung von PrüfungFrage helfen den IT-Fachleuten, die Erfolg erzielen wollen, die Microsoft DP-300 Zertifizierungsprüfung zu bestehen. Um den Erfolg nicht zu verpassen, machen Sie doch schnell.
Die Microsoft DP-300-Zertifizierungsprüfung ist ideal für Datenbankadministratoren, Datenbankentwickler und IT-Fachleute, die mit Microsoft Azure arbeiten. Die Zertifizierungsprüfung ist eine großartige Möglichkeit, Ihre Karriereaussichten zu verbessern und potenziellen Arbeitgebern Ihr Fachwissen zu demonstrieren. Durch die Abgabe der DP-300-Prüfung werden Sie ein Microsoft Certified: Azure Database Administrator Associate, eine hoch angesehene Zertifizierung in der Branche.
Wir versprechen, dass Sie die Microsoft DP-300 Zertifizierungsprüfung bestehen würden, wenn Sie die Fragenpool von PrüfungFrage zur Microsoft DP-300 Prüfung gekauft haben. Falls Sie die DP-300 Prüfung nicht bestehen oder die DP-300 Schulungsunterlagen irgendein Qualitätsproblem haben, erstatten wir Ihnen alle Ihre an uns geleistete Zahlung. Darüber hinaus werden Sie eihjähriger Aktualisierung genießen, nachdem Sie unsere Schulungsunterlagen zur Microsoft DP-300 Prüfung gekauft haben.
Die Microsoft DP-300 Zertifizierungsprüfung ist eine wertvolle Referenz für Fachleute, die ihre Expertise in der cloud-basierten Datenbankverwaltung demonstrieren möchten. Indem sie die Prüfung bestehen, können Kandidaten beweisen, dass sie die Fähigkeiten und Kenntnisse besitzen, um Datenbanken auf Microsoft Azure effektiv zu verwalten und zu optimieren, was sie zu einem begehrten Asset in der Technologiebranche macht.
343. Frage
You have an Azure Data Factory instance named ADF1 and two Azure Synapse Analytics workspaces named WS1 and WS2.
ADF1 contains the following pipelines:
P1:Uses a copy activity to copy data from a nonpartitioned table in a dedicated SQL pool of WS1 to an Azure Data Lake Storage Gen2 account P2:Uses a copy activity to copy data from text-delimited files in an Azure Data Lake Storage Gen2 account to a nonpartitioned table in a dedicated SQL pool of WS2 You need to configure P1 and P2 to maximize parallelism and performance.
Which dataset settings should you configure for the copy activity of each pipeline? To answer, select the appropriate options in the answer area.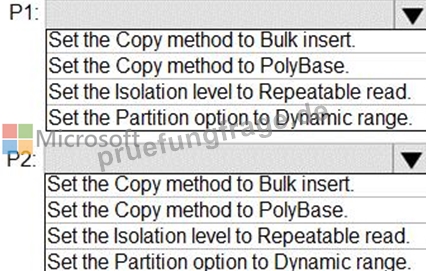
Antwort:
Begründung: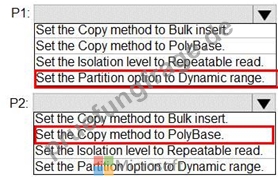
Reference:
https://docs.microsoft.com/en-us/azure/data-factory/connector-azure-sql-data-warehouse
https://docs.microsoft.com/en-us/azure/data-factory/load-azure-sql-data-warehouse
344. Frage
You are designing a security model for an Azure Synapse Analytics dedicated SQL pool that will support multiple companies.
You need to ensure that users from each company can view only the data of their respective company.
Which two objects should you include in the solution? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Antwort: B,D
Begründung:
Azure RBAC is used to manage who can create, update, or delete the Synapse workspace and its SQL pools, Apache Spark pools, and Integration runtimes.
Define and implement network security configurations for resources related to your dedicated SQL pool with Azure Policy.
Reference:
https://docs.microsoft.com/en-us/azure/synapse-analytics/security/synapse-workspace-synapse-rbac
https://docs.microsoft.com/en-us/security/benchmark/azure/baselines/synapse-analytics-security-baseline Basic Concept: This question tests Azure monitoring and performance management, including which metric, log destination, or alerting behavior fits the operational requirement.
Why D and E is Correct: a custom role-based access control (RBAC) role is a security-related control, but its value depends on whether the requirement is identity, encryption, auditing, network isolation, or data exposure reduction. This fits the case because the requested outcome is: You need to ensure that users from each company can view only the data of their respective company. The selected feature addresses that outcome directly rather than relying on a workaround. a security policy is correct because it is the feature whose normal purpose matches the stated requirement. a security policy is a security-related control, but its value depends on whether the requirement is identity, encryption, auditing, network isolation, or data exposure reduction. The scenario wording points to that specific behavior: You need to ensure that users from each company can view only the data of their respective company.
Why A is Wrong: a column encryption key is a security-related control, but its value depends on whether the requirement is identity, encryption, auditing, network isolation, or data exposure reduction. It is not the right enforcement point for this case; the scenario needs the control that governs the data or identity path being tested.
Why B is Wrong: asymmetric keys is a security-related control, but its value depends on whether the requirement is identity, encryption, auditing, network isolation, or data exposure reduction. It does not satisfy the required identity, encryption, firewall, auditing, or data-exposure boundary described in the scenario: You need to ensure that users from each company can view only the data of their respective company.
Why C is Wrong: a function is a security-related control, but its value depends on whether the requirement is identity, encryption, auditing, network isolation, or data exposure reduction. It protects or manages a different security layer, so the required database access or protection behavior would still be incomplete.
345. Frage
You have an Azure Synapse Analytics Apache Spark pool named Pool1.
You plan to load JSON files from an Azure Data Lake Storage Gen2 container into the tables in Pool1. The structure and data types vary by file.
You need to load the files into the tables. The solution must maintain the source data types.
What should you do?
Antwort: B
Begründung:
Synapse notebooks support four Apache Spark languages:
PySpark (Python)
Spark (Scala)
Spark SQL
.NET Spark (C#)
Note: Bring data to a notebook.
You can load data from Azure Blob Storage, Azure Data Lake Store Gen 2, and SQL pool as shown in the code samples below.
Read a CSV from Azure Data Lake Store Gen2 as a Spark DataFrame. from pyspark.sql import SparkSession from pyspark.sql.types import * account_name = "Your account name" container_name = "Your container name" relative_path = "Your path" adls_path =
'abfss://%s@%s.dfs.core.windows.net/%s' % (container_name, account_name, relative_path) df1
= spark.read.option('header', 'true') \
.option('delimiter', ',') \
.csv(adls_path + '/Testfile.csv')
Reference:
https://docs.microsoft.com/en-us/azure/synapse-analytics/spark/apache-spark-development-using-notebooks
346. Frage
You have a Microsoft SQL Server 2017 server that hosts five databases.
You Plan to migrate the databases to Azure.
You need to recommend a solution that meets the following requirements:
* Automatically scales compute based on the workload demand
* Provides per-second billing
What should you include in the recommendation? To answer, select the appropriate options in the answer area.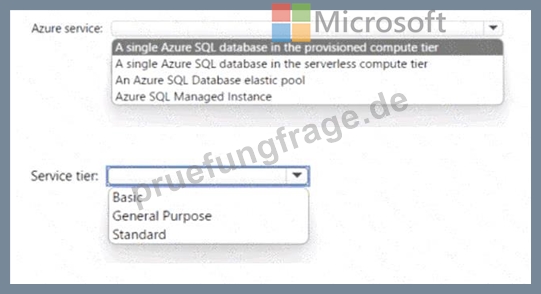
Antwort:
Begründung: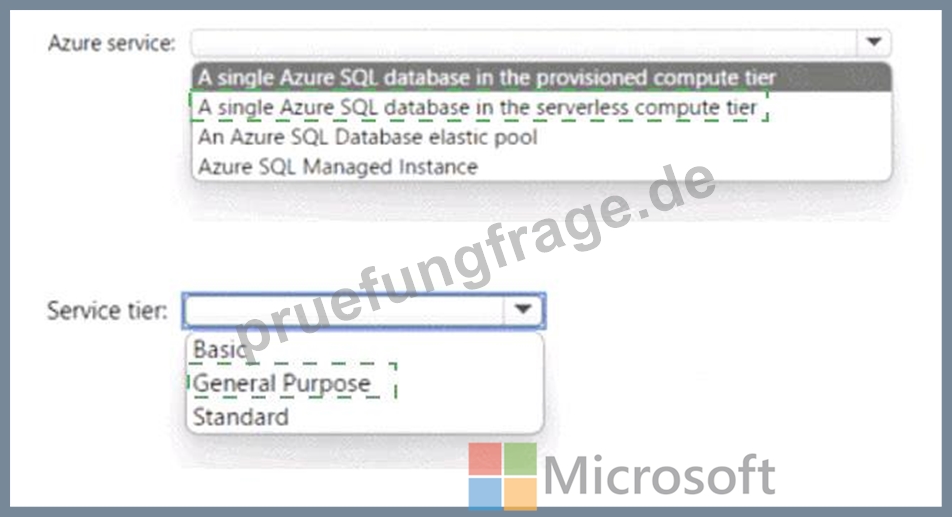
Explanation: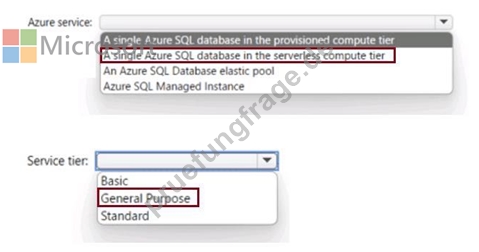
347. Frage
You have an Azure SQL database.
You identify a long running query.
You need to identify which operation in the query is causing the performance issue.
What should you use to display the query execution plan in Microsoft SQL Server Management Studio (SSMS)?
Antwort: B
Begründung:
Section: [none]
Explanation:
To include an execution plan for a query during execution
1. On the SQL Server Management Studio toolbar, click Database Engine Query. You can also open an existing query and display the estimated execution plan by clicking the Open File toolbar button and locating the existing query.
2. Enter the query for which you would like to display the actual execution plan.
3. On the Query menu, click Include Actual Execution Plan or click the Include Actual Execution Plan toolbar button.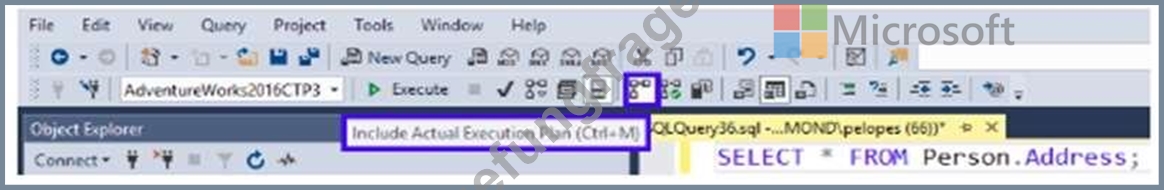
Note: Actual execution plans are generated after the Transact-SQL queries or batches execute. Because of this, an actual execution plan contains runtime information, such as actual resource usage metrics and runtime warnings (if any). The execution plan that is generated displays the actual query execution plan that the SQL Server Database Engine used to execute the queries.
Reference:
https://docs.microsoft.com/en-us/sql/relational-databases/performance/display-an-actual-execution-plan
348. Frage
......
DP-300 Prüfungs-Guide: https://www.pruefungfrage.de/DP-300-dumps-deutsch.html
P.S. Kostenlose und neue DP-300 Prüfungsfragen sind auf Google Drive freigegeben von PrüfungFrage verfügbar: https://drive.google.com/open?id=1kZePR5Fib8y-Xon1kRcYcvgQPchlmnqS