2026 High-quality Databricks-Certified-Professional-Data-Engineer–100% Free Free Test Questions | Databricks Certified Professional Data Engineer Exam Exam Engine

Our website can offer you the latest Databricks pass guide and learning materials, which enable you pass Databricks-Certified-Professional-Data-Engineer valid exam at your first attempt. Besides, there are Databricks-Certified-Professional-Data-Engineer free braindumps that you can download to learn about our products. Once you decide to buy our test answers, you will be allowed to free update your Databricks-Certified-Professional-Data-Engineer Top Dumps one-year.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview:
>> Free Databricks-Certified-Professional-Data-Engineer Test Questions <<
Databricks-Certified-Professional-Data-Engineer Exam Engine - Databricks-Certified-Professional-Data-Engineer Exams Training
If you have decided to participate in the Databricks Databricks-Certified-Professional-Data-Engineer exam, iPassleader is here. We can help you achieve your goals. We know that you need to pass your Databricks Databricks-Certified-Professional-Data-Engineer Exam, we promise that provide high quality exam materials for you, Which can help you through Databricks Databricks-Certified-Professional-Data-Engineer exam.
Databricks Certified Professional Data Engineer exam is a practical and hands-on exam that requires candidates to demonstrate their ability to design and implement data pipelines using Databricks. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and hands-on exercises that test the candidate's ability to apply their knowledge to real-world scenarios. Databricks-Certified-Professional-Data-Engineer Exam is designed to be challenging, but fair, and it is intended to accurately assess a candidate's skills and knowledge.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q73-Q78):
NEW QUESTION # 73
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.
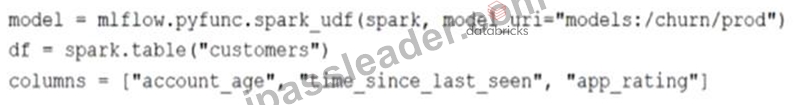
Which code block will output DataFrame with the schema'' customer_id LONG, predictions DOUBLE''?
- A. Df.apply(model, columns). Select (''customer_id, prediction''
- B. Model, predict (df, columns)
- C. Df, map (lambda k:midel (x [columns]) ,select (''customer_id predictions'')
- D. Df. Select (''customer_id''.
Model (''columns) alias (''predictions'')
Answer: B
Explanation:
Given the information that the model is registered with MLflow and assumingpredictis the method used to apply the model to a set of columns, we use themodel.predict()function to apply the model to the DataFrame dfusing the specifiedcolumns. Themodel.predict()function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictionscolumn.
When working with PySpark, this predictions column needs to be selected alongside thecustomer_idto create a new DataFrame with the schemacustomer_id LONG, predictions DOUBLE.
References:
* MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.
html#python-function-python
* PySpark MLlib documentation on model prediction:https://spark.apache.org/docs/latest/ml-pipeline.
html#pipeline
NEW QUESTION # 74
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
- A. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- B. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- D. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name DataEngineer_cluster
Answer: B
Explanation:
The Databricks CLI allows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type: databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version: '14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers: --num-workers 5 sets the number of worker nodes to 5.
* Node Type: --node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name: --cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect: databricks clusters create is not a valid command in the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect: databricks clusters add is not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect: databricks compute add is not a valid CLI command.
* Option D (databricks compute create ...)
* Correct: databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer is D.
References:
Databricks CLI Documentation
NEW QUESTION # 75
Which of the following data workloads will utilize a Silver table as its source?
- A. A job that ingests raw data from a streaming source into the Lakehouse
- B. A job that cleans data by removing malformatted records
- C. A job that aggregates cleaned data to create standard summary statistics
- D. A job that queries aggregated data that already feeds into a dashboard
- E. A job that enriches data by parsing its timestamps into a human-readable format
Answer: C
NEW QUESTION # 76
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format( " parquet " )
.load( " /mnt/raw_orders/ " )
.withWatermark( " time " , " 2 hours " )
.dropDuplicates([ " customer_id " , " order_id " ])
.writeStream
.trigger(once=True)
.table( " orders " )
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- B. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- C. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
- D. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
Answer: B
Explanation:
* Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay."
* Exact extract: "Records older than the event-time watermark are considered late and may be dropped." References: Structured Streaming watermarking and deduplication; One-time trigger.
NEW QUESTION # 77
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in abronzetable created with the propertydelta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
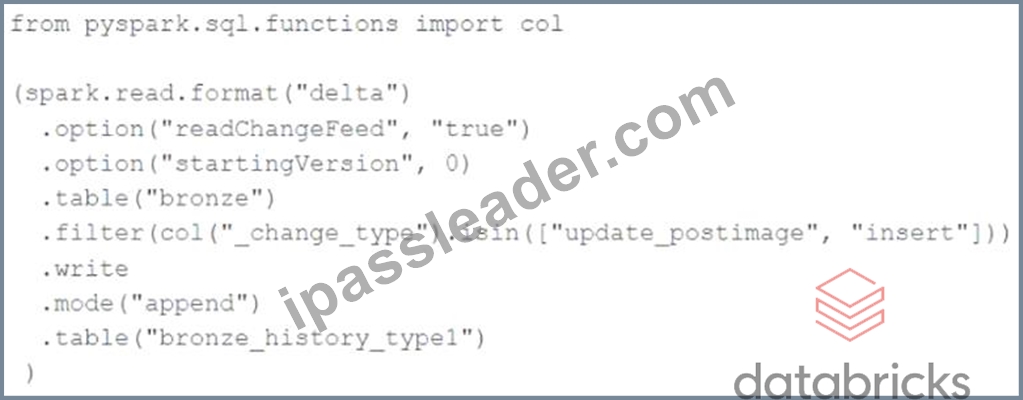
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- B. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- C. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- D. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- E. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
Answer: C
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 78
......
Databricks-Certified-Professional-Data-Engineer Exam Engine: https://www.ipassleader.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html
- Databricks-Certified-Professional-Data-Engineer Latest Learning Materials 🐺 Databricks-Certified-Professional-Data-Engineer New Study Plan 🏀 Databricks-Certified-Professional-Data-Engineer New Study Plan 👞 The page for free download of ➤ Databricks-Certified-Professional-Data-Engineer ⮘ on ▛ www.verifieddumps.com ▟ will open immediately 🍆Latest Databricks-Certified-Professional-Data-Engineer Test Pdf
- Free Databricks-Certified-Professional-Data-Engineer Test Questions - Databricks First-grade Databricks-Certified-Professional-Data-Engineer Exam Engine 📽 Go to website ➤ www.pdfvce.com ⮘ open and search for 【 Databricks-Certified-Professional-Data-Engineer 】 to download for free 🏆Exam Databricks-Certified-Professional-Data-Engineer Tutorial
- Latest Databricks-Certified-Professional-Data-Engineer Test Pdf 🔹 Databricks-Certified-Professional-Data-Engineer Latest Learning Materials 📎 Reliable Databricks-Certified-Professional-Data-Engineer Test Blueprint 🏵 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and download it for free immediately on ➽ www.prepawaypdf.com 🢪 ↕Databricks-Certified-Professional-Data-Engineer Exam Discount Voucher
- Quiz 2026 Authoritative Databricks Free Databricks-Certified-Professional-Data-Engineer Test Questions 🚆 Download 《 Databricks-Certified-Professional-Data-Engineer 》 for free by simply searching on ➤ www.pdfvce.com ⮘ 🤎Databricks-Certified-Professional-Data-Engineer Exam Simulator
- Guide Databricks-Certified-Professional-Data-Engineer Torrent 🧕 Databricks-Certified-Professional-Data-Engineer Latest Cram Materials 🧡 Reliable Databricks-Certified-Professional-Data-Engineer Test Blueprint 💺 Easily obtain free download of ➤ Databricks-Certified-Professional-Data-Engineer ⮘ by searching on “ www.exam4labs.com ” 🕍Exam Databricks-Certified-Professional-Data-Engineer Lab Questions
- Latest Databricks-Certified-Professional-Data-Engineer Test Pdf 🧏 Databricks-Certified-Professional-Data-Engineer Latest Learning Materials 🚨 New Databricks-Certified-Professional-Data-Engineer Test Vce 💑 The page for free download of 【 Databricks-Certified-Professional-Data-Engineer 】 on ➡ www.pdfvce.com ️⬅️ will open immediately 🔘Latest Databricks-Certified-Professional-Data-Engineer Test Pdf
- Latest Databricks-Certified-Professional-Data-Engineer Exam Bootcamp 📬 Databricks-Certified-Professional-Data-Engineer Latest Cram Materials 🥁 Databricks-Certified-Professional-Data-Engineer Latest Learning Materials 🔁 ➠ www.dumpsmaterials.com 🠰 is best website to obtain ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free download 🩳Databricks-Certified-Professional-Data-Engineer Exam Simulator
- Reliable Databricks-Certified-Professional-Data-Engineer Test Blueprint 📴 Databricks-Certified-Professional-Data-Engineer Exam Discount Voucher 🚻 Databricks-Certified-Professional-Data-Engineer Latest Cram Materials ☔ Immediately open ⏩ www.pdfvce.com ⏪ and search for { Databricks-Certified-Professional-Data-Engineer } to obtain a free download 🙁Databricks-Certified-Professional-Data-Engineer Latest Learning Materials
- Accurate 100% Free Databricks-Certified-Professional-Data-Engineer – 100% Free Free Test Questions | Databricks-Certified-Professional-Data-Engineer Exam Engine 🕴 Enter ( www.vce4dumps.com ) and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ to download for free 🖋Databricks-Certified-Professional-Data-Engineer New Study Plan
- Databricks-Certified-Professional-Data-Engineer PDF Question 🦦 Databricks-Certified-Professional-Data-Engineer Trustworthy Exam Torrent 😮 Guide Databricks-Certified-Professional-Data-Engineer Torrent 💼 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and download it for free on ⏩ www.pdfvce.com ⏪ website 🔽Latest Databricks-Certified-Professional-Data-Engineer Test Pdf
- Professional Databricks-Certified-Professional-Data-Engineer - Free Databricks Certified Professional Data Engineer Exam Test Questions ℹ Open ▶ www.vce4dumps.com ◀ and search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ to download exam materials for free 🤾Databricks-Certified-Professional-Data-Engineer Exam Discount Voucher
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes