無料でクラウドストレージから最新のTech4Exam AIF-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1B6ezgtIvPeM0aQbXDwN7ihz29WX7q9fR
誰もが良い仕事とまともな収入を望んでいます。 しかし、彼らが優れた能力と優れた主要な知識を持っていない場合、彼らはまともな仕事を見つけるのは難しいです。 AmazonテストAIF-C01認定に合格すると、夢を実現し、満足のいく仕事を見つけることができます。 AIF-C01学習教材は、AIF-C01のAWS Certified AI Practitioner試験に簡単に合格するのに役立つ優れたツールです。 時間をかけて学習する必要はありません。 AIF-C01試験ガイドは高品質であり、当社Amazonの製品を使用する場合、AIF-C01試験に合格する可能性は99%〜100%と非常に高くなっています。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
一つには、当社の最も先進的なオペレーションシステムであり、最速の配信速度を保証でき、お客様の個人情報は弊社のオペレーションシステムによって自動的に暗号化されます。また、AIF-C01の実際の試験のオンラインアプリバージョンを使用すると、あらゆる種類の電子デバイスに関するトレーニング資料の質問を気軽に練習できます。さらに、AIF-C01試験問題の助けを借りて、お客様の合格率は98%〜100%に達しました。近い将来、あなたの学習パートナーになることを楽しみにしています。
質問 # 218
A media company wants to analyze viewer behavior and demographics to recommend personalized content. The company wants to deploy a customized ML model in its production environment. The company also wants to observe if the model quality drifts over time.
Which AWS service or feature meets these requirements?
正解:D
解説:
A: Amazon Rekognition: This service is designed for image and video analysis, such as object detection, facial recognition, and text extraction. It is not suited for deploying custom ML models or monitoring model quality drift.
B: Amazon SageMaker Clarify: This feature helps detect bias in ML models and explains model predictions. While it addresses fairness and interpretability, it does not specifically focus on monitoring model quality drift over time in production.
C: Amazon Comprehend: This is a natural language processing (NLP) service for extracting insights from text, such as sentiment analysis or entity recognition. It does not support deploying custom ML models or monitoring model performance drift.
D: Amazon SageMaker Model Monitor: This feature is part of Amazon SageMaker and is specifically designed to monitor ML models in production. It tracks metrics such as data drift, model drift, and performance degradation over time, alerting users when issues are detected.
Exact Extract Reference: According to the AWS documentation on Amazon SageMaker, "Amazon SageMaker Model Monitor allows you to detect and remediate data and model quality issues in production. It continuously monitors the performance of deployed models, capturing data and model predictions to detect deviations from expected behavior, such as data drift or model performance degradation." (Source: AWS SageMaker Documentation - Model Monitoring, https://docs.aws.amazon.com/sagemaker/latest/dg/model-monitor.html).
This directly aligns with the requirement to observe model quality drift, making Amazon SageMaker Model Monitor the correct choice.
Explanation:
The requirement is to deploy a customized machine learning (ML) model and monitor its quality for potential drift over time in a production environment. Let's evaluate each option:
Reference:
AWS SageMaker Documentation: Model Monitoring (https://docs.aws.amazon.com/sagemaker/latest/dg/model-monitor.html) AWS AI Practitioner Study Guide (conceptual alignment with monitoring deployed ML models)
質問 # 219
A company wants to use a large language model (LLM) on Amazon Bedrock for sentiment analysis. The company wants to classify the sentiment of text passages as positive or negative.
Which prompt engineering strategy meets these requirements?
正解:A
解説:
Providing examples of text passages with corresponding positive or negative labels in the prompt followed by the new text passage to be classified is the correct prompt engineering strategy for using a large language model (LLM) on Amazon Bedrock for sentiment analysis.
* Example-Driven Prompts:
* This strategy, known as few-shot learning, involves giving the model examples of input-output pairs (e.g., text passages with their sentiment labels) to help it understand the task context.
* It allows the model to learn from these examples and apply the learned pattern to classify new text passages correctly.
* Why Option A is Correct:
* Guides the Model: Providing labeled examples teaches the model how to perform sentiment analysis effectively, increasing accuracy.
* Contextual Relevance: Aligns the model's responses to the specific task of classifying sentiment.
* Why Other Options are Incorrect:
* B. Detailed explanation of sentiment analysis: Unnecessary for the model's operation; it requires examples, not explanations.
* C. New text passage without context: Provides no guidance or learning context for the model.
* D. Unrelated task examples: Would confuse the model and lead to inaccurate results.
質問 # 220
What is tokenization used for in natural language processing (NLP)?
正解:A
解説:
The correct answer is C because tokenization is the NLP process of breaking down text into smaller units, such as words, subwords, or characters, that can be processed by ML models.
From AWS documentation:
"Tokenization is the process of splitting text into meaningful units, such as words or subwords, that are used as input tokens in NLP tasks. Tokenization is an essential step in preparing text data for models." This is a foundational concept used in language models, including those on Amazon Bedrock and SageMaker.
Explanation of other options:
A). Encryption is not related to NLP and is used for data security.
B). Compression reduces file size but is unrelated to language processing.
D). Translation is a separate NLP task that uses tokenization as a preprocessing step but is not the definition of tokenization itself.
Referenced AWS AI/ML Documents and Study Guides:
* AWS NLP on Amazon SageMaker Documentation
* AWS Machine Learning Specialty Guide - NLP Fundamentals
* Amazon Bedrock Foundation Model Documentation - Tokenization and Input Formatting
質問 # 221
A medical company deployed a disease detection model on Amazon Bedrock. To comply with privacy policies, the company wants to prevent the model from including personal patient information in its responses. The company also wants to receive notification when policy violations occur.
Which solution meets these requirements?
正解:B
解説:
Guardrails for Amazon Bedrock provide mechanisms to filter and control the content generated by models to comply with privacy and policy requirements. Using guardrails ensures that sensitive or personal information is not included in the model's responses. Additionally, integrating Amazon CloudWatch alarms allows for real-time notification when a policy violation occurs.
Option C (Correct): "Use Guardrails for Amazon Bedrock to filter content. Set up Amazon CloudWatch alarms for notification of policy violations": This is the correct answer because it directly addresses both the prevention of policy violations and the requirement to receive notifications when such violations occur.
Option A: "Use Amazon Macie to scan the model's output for sensitive data" is incorrect because Amazon Macie is designed to monitor data in S3, not to filter real-time model outputs.
Option B: "Configure AWS CloudTrail to monitor the model's responses" is incorrect because CloudTrail tracks API activity and is not suited for content moderation.
Option D: "Implement Amazon SageMaker Model Monitor to detect data drift" is incorrect because data drift detection does not address content moderation or privacy compliance.
AWS AI Practitioner Reference:
Guardrails in Amazon Bedrock: AWS provides guardrails to ensure AI models comply with content policies, and using CloudWatch for alerting integrates monitoring capabilities.
質問 # 222
Sated and order the steps from the following bat to correctly describe the ML Lifecycle for a new custom modal Select each step one time. (Select and order FOUR.)
* Define the business objective.
* Deploy the modal.
* Develop and tram the model.
* Process the data.
正解:
解説: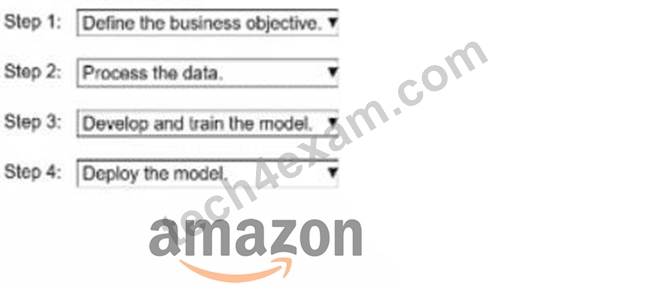
Step 1: Define the business objective.
Step 2: Process the data.
Step 3: Develop and train the model.
Step 4: Deploy the model.
The correct order represents the machine learning lifecycle as defined by AWS in the Amazon SageMaker documentation and AWS Certified Machine Learning Specialty Study Guide. The lifecycle describes the sequence of tasks required to build, train, and deploy a custom ML model effectively.
From AWS documentation:
"The machine learning process begins with defining the business problem, followed by collecting and processing data, developing and training models, and finally deploying them into production for inference." Step 1 - Define the business objective:
This step involves clearly identifying the business problem to be solved and determining the measurable outcomes expected from the ML model. This ensures alignment between business goals and ML outputs.
Step 2 - Process the data:
Data is collected, cleaned, transformed, and prepared for training. This includes handling missing values, normalizing data, and performing feature engineering - a crucial phase that influences model performance.
Step 3 - Develop and train the model:
The model is built and trained on the processed data using algorithms appropriate to the problem (e.g., regression, classification, clustering). Hyperparameters are tuned to optimize model accuracy.
Step 4 - Deploy the model:
Once validated, the model is deployed to a production environment (e.g., Amazon SageMaker endpoint) to make predictions on new data. Continuous monitoring and retraining ensure the model remains effective.
Referenced AWS AI/ML Documents and Study Guides:
Amazon SageMaker Developer Guide - Machine Learning Lifecycle
AWS Certified Machine Learning Specialty Study Guide - Model Development Lifecycle AWS ML Best Practices Whitepaper - End-to-End ML Workflow
質問 # 223
......
Tech4ExamのIT認証試験問題集は長年のトレーニング経験を持っています。Tech4Exam AmazonのAIF-C01試験トレーニング資料は信頼できる製品です。当社のスタッフ は受験生の皆様が試験で高い点数を取ることを保証できるように、巨大な努力をして皆様に最新版のAIF-C01試験トレーニング資料を提供しています。Tech4Exam AmazonのAIF-C01試験材料は最も実用的なIT認定材料を提供することを確認することができます。
AIF-C01最新日本語版参考書: https://www.tech4exam.com/AIF-C01-pass-shiken.html
さらに、Tech4Exam AIF-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1B6ezgtIvPeM0aQbXDwN7ihz29WX7q9fR