It is well known that even the best people fail sometimes, not to mention the ordinary people. In face of the AI-500 exam, everyone stands on the same starting line, and those who are not excellent enough must do more. Every year there are a large number of people who can't pass the AI-500 Exam smoothly. But we are professional in this career for over ten years. And our AI-500 study materials will help you pass the exam easily.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Design and implement evaluation and validation strategies
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
| Topic 4: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
>> New AI-500 Exam Preparation <<
AI-500 practice exam will provide you with wholehearted service throughout your entire learning process. This means that unlike other products, the end of your payment means the end of the entire transaction our AI-500 learning materials will provide you with perfect services until you have successfully passed the AI-500 Exam. And if you have any questions, just feel free to us and we will give you advice on AI-500 study guide as soon as possible.
NEW QUESTION # 16
You have a multi-agent customer support solution in a Microsoft Foundry project.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.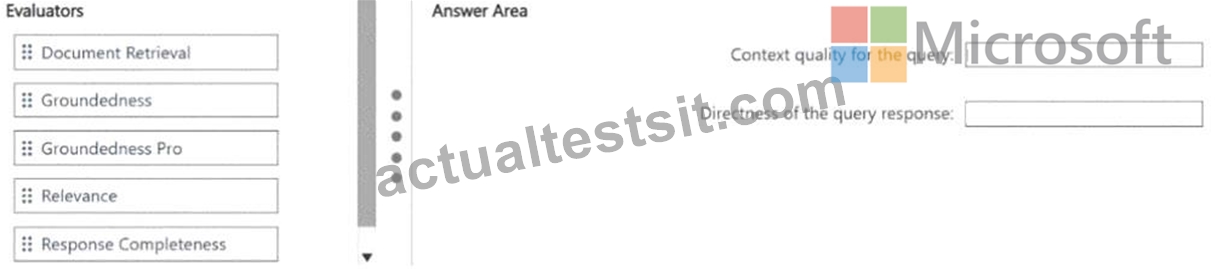
Answer:
Explanation:
Explanation:
Quality of retrieved context: Retrieval evaluator; Directness of response to query: Relevance evaluator.
The dataset contains query, context, and response but does not contain document relevance labels. Microsoft ' s Retrieval evaluator is designed for exactly that situation: it uses an LLM judge to rate how relevant the retrieved context chunks are to the query and returns a 1-to-5 score with pass/fail behavior. The Relevance evaluator operates on the final response and measures whether the answer accurately, completely, and directly addresses the query. Document Retrieval is not appropriate because it requires retrieval ground truth such as known relevant documents or qrels. Groundedness answers a different question: whether response claims are supported by the provided context. Therefore the correct mapping is Retrieval for context quality and Relevance for response directness. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 17
You have a Microsoft Foundry multi-agent solution. The solution includes a parent agent that can call an Azure logic app and delegate to two subagents.
You need to implement a review process for flagged interactions. The solution must meet the following requirements;
* Identify requests that call third-party services.
* Moderate the prompts, steps, and tool calls.
* Include a governance review.
What should you do?
Answer: A
Explanation:
The review process must cover the full sensitive interaction, including third-party calls, prompts, intermediate steps, and tool actions, and it must feed a governance review process. A centralized sensitive-use intake combined with guardrails and tracing provides the required evidence, while human reviewers must be able to approve, edit, or reject flagged interactions rather than reviewing only the final message. Content Safety alone does not provide full process governance over tool use. Routing only subagent findings or requiring approval only for the final response misses earlier third-party actions. CI/CD evaluation is important for release quality but does not control individual flagged production interactions. The source duplicated the label C for the final option; that final option should be labeled D. With that label correction, D is the best answer. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - governance, guardrails, tracing, and HITL
NEW QUESTION # 18
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator agent that sends a mix of simple requests, reasoning-heavy tasks, and tool-calling workflows to a single premium model deployment.
Response quality is acceptable, but costs are too high, and latency varies significantly across requests.
You need to recommend a solution to reduce token utilization based on the complexity of the user input.
What should you include in the recommendation?
Answer: C
Explanation:
The workload mixes simple prompts, reasoning-heavy tasks, and tool-calling workflows, so a single premium model is over-provisioned for many requests. Microsoft Foundry ' s model router evaluates request complexity and routes each request to an appropriate model from a configured pool. Simple work can use lower-cost, lower-latency models, while complex reasoning can still be assigned to a more capable model.
Structured outputs constrain response format but do not reduce model capability according to request complexity. Prompt Optimizer can improve prompt quality but does not perform per-request model selection, and choosing another flagship model would preserve the same all-requests-use-premium pattern. Therefore A directly addresses the cost and latency variability by matching model capacity to workload complexity. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - Model router
NEW QUESTION # 19
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.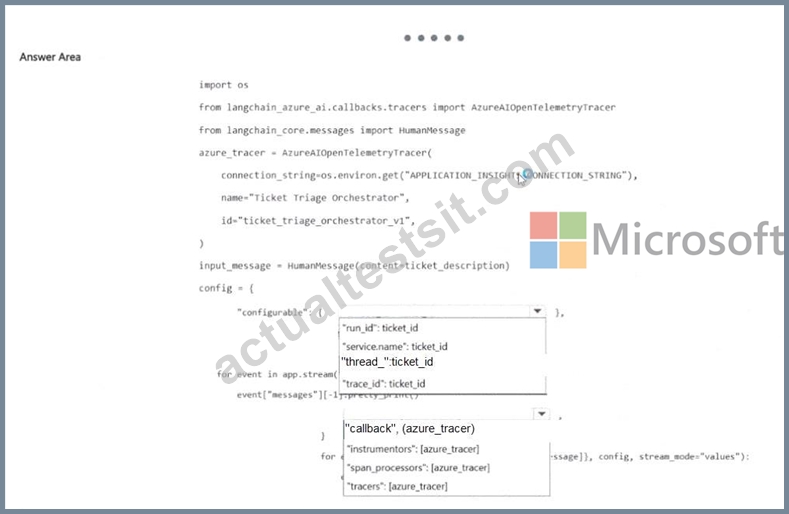
Answer:
Explanation:
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents
NEW QUESTION # 20
You have a multitenant platform that uses Microsoft Foundry agents. The agents use conversation-based history for active turns, and the platform runs on multiple stateless container instances. Each tenant has a different transcript retention period, and users expect preferences from previous conversations to influence future sessions.
You need to persist cross-session memory after a service conversation is deleted The solution must meet the following requirements:
* Apply tenant-specific retention to transcript exports.
* Keep the compute tier stateless during scale-out.
* Minimize operational complexity
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.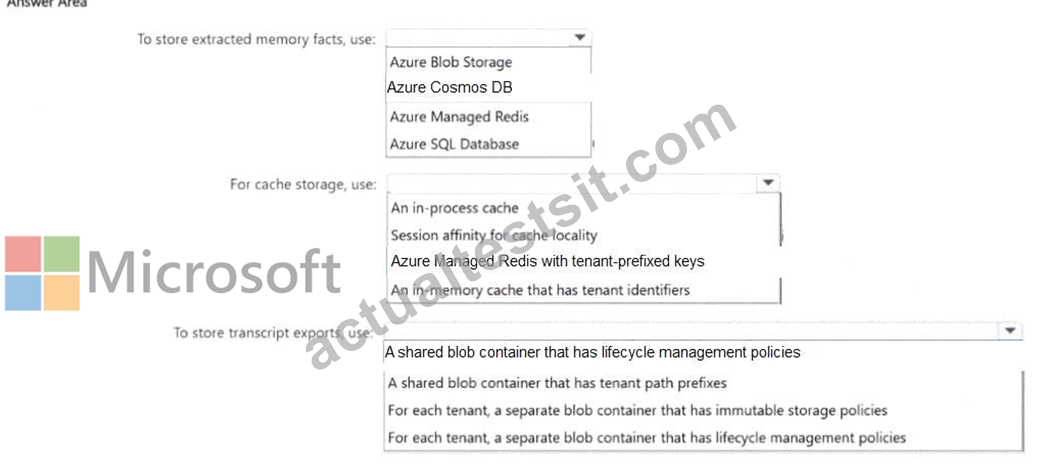
Answer:
Explanation: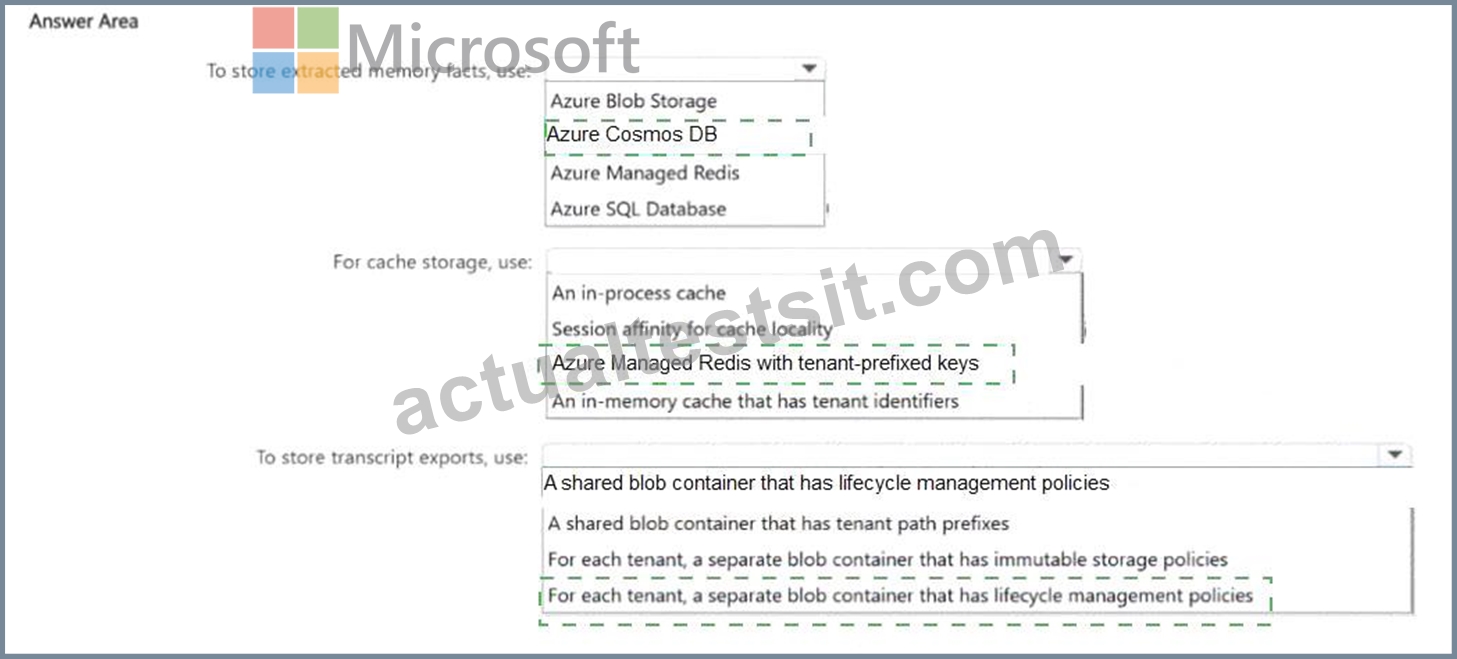
Explanation:
Extracted memory facts: Azure Cosmos DB; Cache: Azure Managed Redis with tenant-prefixed keys; Transcript exports: A shared blob container with lifecycle management policies.
The design separates durable memory, distributed cache, and retained transcripts. Azure Cosmos DB is appropriate for durable extracted facts that must survive deletion of a service conversation and remain available across stateless compute instances. Azure Managed Redis provides a shared low-latency cache; tenant-prefixed keys are a standard multitenant pattern that avoids local-process affinity. Transcript exports belong in Blob Storage, where lifecycle management rules can enforce retention and can be filtered by prefixes or tags so different tenant retention policies can coexist in one managed storage design. This combination keeps the compute tier stateless while avoiding unnecessary per-tenant infrastructure. The important security requirement is that every persistence layer also enforce tenant authorization, not just naming conventions. Within the options provided, the stated combination minimizes operational complexity while meeting cross-session persistence and retention needs. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure Architecture Center - multitenant data and cache patterns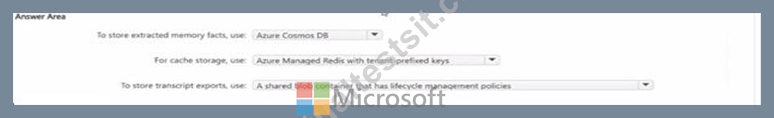
NEW QUESTION # 21
......
To make your success a certainty, ActualTestsIT offers free updates on our Microsoft AI-500 real dumps for up to three months. It means all users get the latest and updated Microsoft AI-500 practice material to clear the Designing and Implementing Multi-Agent AI Solutions AI-500 certification test on the first try. We are a genuine brand working to smoothen up your AI-500 exam preparation. ActualTestsIT allows all visitors to try a free demo of AI-500 pdf questions and practice tests to assess the quality of our AI-500 Study Material. Your money is 100% secure as we will ensure that you crack the Microsoft AI-500 test on the first attempt. You will also enjoy 24/7 efficient support from our customer support team before and after the purchase of Microsoft AI-500 exam dumps. If you face any issues while using our AI-500 PDF dumps or AI-500 practice exam software (desktop and web-based), contact ActualTestsIT customer service for guidance.
Exam AI-500 Question: https://www.actualtestsit.com/Microsoft/AI-500-exam-prep-dumps.html