2026 Latest Itcerttest AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=187HbjDSyTfosYHTT11sRS-XG0cB42zTO
Created on the exact pattern of the Actual AI-300 Tests, Itcerttest’s dumps comprise questions and answers and provide all important information in easy to grasp and simplified content. The easy language does not pose any barrier for any learner. The complex portions of the certification syllabus have been explained with the help of simulations and real-life based instances. The best part of Itcerttest’s dumps is their relevance, comprehensiveness and precision. You need not to try any other source for exam preparation. The innovatively crafted dumps will serve you the best; imparting you information in fewer number of questions and answers.
| Section | Weight | Objectives |
|---|---|---|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
>> AI-300 Reliable Exam Guide <<
With the advent of knowledge times, we all need some professional certificates such as AI-300 to prove ourselves in different working or learning condition. So making right decision of choosing useful practice materials is of vital importance. Here we would like to introduce our AI-300 practice materials for you with our heartfelt sincerity. With passing rate more than 98 percent from exam candidates who chose our AI-300 study guide, we have full confidence that your AI-300 actual test will be a piece of cake by them.
NEW QUESTION # 63
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to isolate training workloads while remaining cost-aware to address Fabrikam Inc.'s issues, constraints, and technical requirements. What should you implement?
Answer: C
Explanation:
Scenario: Issues and Constraints: Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Managed compute targets with autoscaling are the best choice for Azure Machine Learning training workloads when serverless or managed options are preferred and cost predictability is critical.
Best Implementation: Managed Compute with Autoscaling
This option, specifically using Azure Machine Learning compute clusters (AmlCompute), aligns with all your requirements:
Managed Infrastructure: Azure handles the creation, patching, and lifecycle of the virtual machines, reducing management overhead.
Cost Predictability & Efficiency: Autoscaling allows you to set a minimum of zero nodes. This ensures you only pay for compute while a job is running, preventing costs from idle resources.
Scalability: It can automatically scale up to a multi-node cluster to handle large datasets or distributed training jobs.
Enterprise Governance: Administrators can enforce cost control by setting quotas at the subscription or workspace level.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-serverless-compute
NEW QUESTION # 64
An Azure Machine Learning workspace contains multiple registered versions of a model that is used in production.
An older model version must no longer be deployable, but it must remain available for compliance review and potential rollback.
You need to change the state of the model version to meet the requirements.
What should you do?
Answer: B
Explanation:
To ensure that older Azure Machine Learning model versions are no longer deployable but remain available for reference or historical tracking, you should archive those specific versions.
How to Archive Model Versions
Archiving a model version effectively hides it from standard list queries and management interfaces, preventing accidental deployment while maintaining its metadata and files in the workspace.
Behavior of Archived Models:
Hidden by Default: They will no longer appear in the Azure Machine Learning Studio model list unless you explicitly filter for archived assets.
Referenceable: You can still reference and use an archived model version in existing workflows if you have its specific version number.
Restoreable: If you need to redeploy the model in the future, you can use the restore command to make it active again.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-manage-models
NEW QUESTION # 65
You are planning to register a trained model in an Azure Machine Learning workspace.
You must store additional metadata about the model in a key-value format. You must be able to add new metadata and modify or delete metadata after creation.
You need to register the model.
Which parameter should you use?
Answer: D
Explanation:
azureml.core.Model.properties:
Dictionary of key value properties for the Model. These properties cannot be changed after registration, however new key value pairs can be added.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.model.model
NEW QUESTION # 66
-
A team performs interactive experimentation during development. The team also runs scalable jobs for model training.
The team must minimize costs while ensuring compute resources scale when needed. Different workloads require different compute behaviors within the same workspace.
You need to configure compute targets that support each workload.
Which compute targets should you use? To answer, move the appropriate compute targets to the correct workload types. You may use each compute target once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.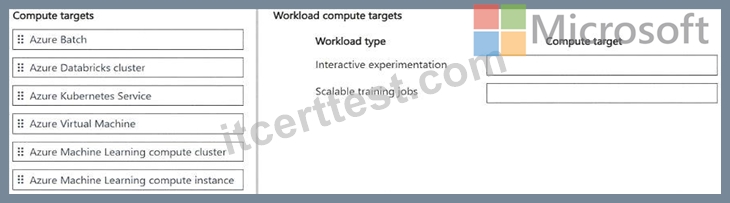
Answer:
Explanation: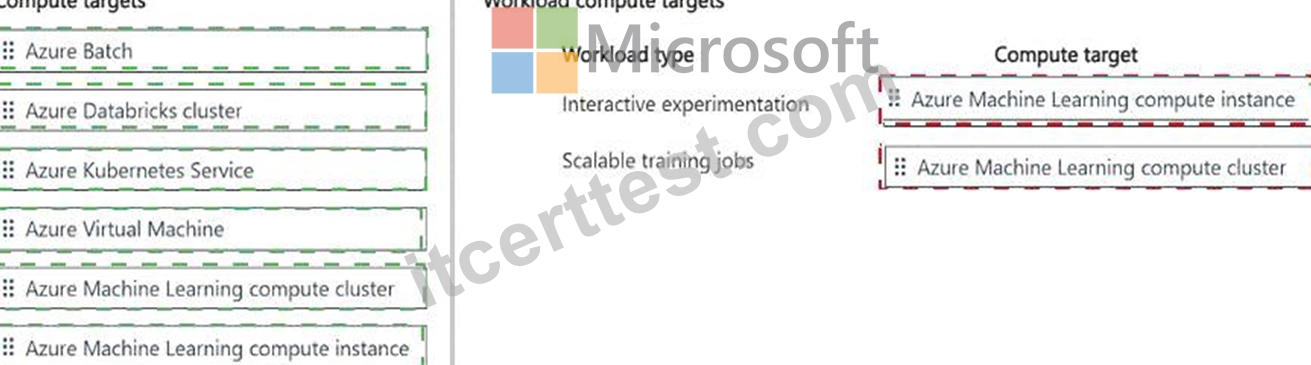
Explanation:
Interactive experimentation: Azure Machine Learning compute instance
Scalable training jobs: Azure Machine Learning compute cluster
For interactive experimentation , use an Azure Machine Learning compute instance . Microsoft defines a compute instance as a fully managed, cloud-based development workstation optimized for machine learning development. It integrates directly with Jupyter, JupyterLab, and other development tools in Azure Machine Learning studio, making it the appropriate target for notebook-driven experimentation, iterative coding, debugging, and development. A compute instance is a single-node environment and can be stopped or configured with idle shutdown to control costs.
For scalable training jobs , use an Azure Machine Learning compute cluster . Compute clusters are managed training targets that can scale from a minimum to a configured maximum number of nodes based on job demand. Microsoft specifically recommends them for larger datasets, distributed training, and workloads requiring elastic compute capacity. Setting the minimum node count to 0 allows the cluster to deallocate all worker nodes when no jobs are running, which is an important cost-optimization mechanism.
Azure Batch, Databricks, AKS, and standalone Azure VMs can support specialized workloads, but they do not match the native Azure Machine Learning development-versus-elastic-training pattern as directly as compute instance and compute cluster.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning compute targets, compute instances, compute clusters, autoscaling, distributed training, and cost optimization.
NEW QUESTION # 67
-
You complete the fine-tuning of a generative model in Microsoft Foundry. The fine-tuned model now appears as a new model variant in your development environment.
The deployment process must ensure that proper validation and control is maintained.
You need to promote the fine-tuned model from development to production.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.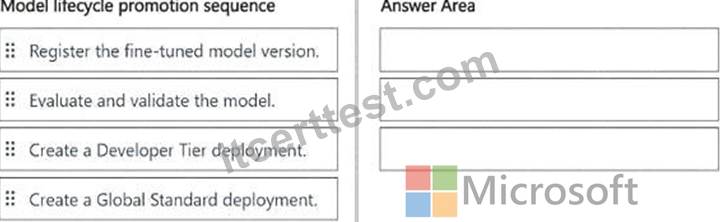
Answer:
Explanation: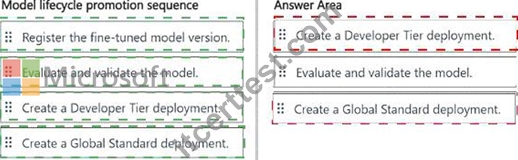
Explanation:
Correct sequence:
* Create a Developer Tier deployment.
* Evaluate and validate the model.
* Create a Global Standard deployment.
The fine-tuned model should first be deployed using the Developer Tier because Microsoft specifically positions this deployment type for fine-tuned model candidate evaluation rather than production use .
Developer Tier deployments provide a cost-efficient environment for testing custom models and do not provide a production SLA.
After deployment, the model should be evaluated and validated . Microsoft Foundry supports running the model through the playground and the Evaluations service to assess the deployed candidate against expected quality, safety, and task-performance criteria. Microsoft explicitly documents that evaluations can be executed against a deployed fine-tuned model candidate and compared with other model versions.
Only after the candidate satisfies the required validation criteria should it be promoted to a Global Standard deployment for production inference. Global Standard is designed for general production workloads and provides substantially more appropriate production characteristics than Developer Tier.
Register the fine-tuned model version is the distractor here. The scenario already states that fine-tuning is complete and the resulting model variant exists in Microsoft Foundry; the required promotion workflow is therefore test deployment # validation # production deployment .
Study Guide Reference: Implement machine learning model lifecycle and operations - fine-tuned model evaluation, controlled promotion, Developer Tier deployments, production deployment, and model lifecycle governance.
NEW QUESTION # 68
......
What do you think of using Itcerttest Microsoft AI-300 Exam Dumps? Itcerttest Microsoft AI-300 certification training dumps, it may be said, is the most excellent reference materials among all exam-related reference materials. Why? There are four reasons in the following. Firstly, Itcerttest exam dumps are researched by IT experts who used their experience for years and can figure out accurately the scope of the examinations. Secondly, Itcerttest exam dumps conclude all questions that can appear in the real exam. Thirdly, Itcerttest exam dumps ensures the candidate will pass their exam at the first attempt. If the candidate fails the exam, Itcerttest will give him FULL REFUND. Fourthly, Itcerttest exam dumps have two versions: PDF and SOFT version. With the two versions, the candidates can pass their exam with ease.
New AI-300 Exam Papers: https://www.itcerttest.com/AI-300_braindumps.html
2026 Latest Itcerttest AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=187HbjDSyTfosYHTT11sRS-XG0cB42zTO