2026 Latest TrainingDump DAA-C01 PDF Dumps and DAA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1HZiysQbhpxV7b-dZQA_odlZXl2B5xyhQ
The majority of people encounter the issue of finding extraordinary Snowflake DAA-C01 exam dumps that can help them prepare for the actual Snowflake DAA-C01 Exam. They strive to locate authentic and up-to-date Snowflake DAA-C01 practice questions for the SnowPro Advanced: Data Analyst Certification Exam exam, which is a tough ask.
| Section | Weight | Objectives |
|---|---|---|
| Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs) - Scalar, aggregate, table, system functions |
| Build and Troubleshoot Advanced SQL Queries | 20–25% | - Semi-structured data processing - Complex joins, subqueries, window functions - Query optimization and troubleshooting |
| Prepare and Load Data | 15–20% | - File formats: CSV, JSON, Parquet, Avro - Data ingestion methods: COPY INTO, stages, Snowpipe - External tables and data validation |
| Prepare and Present Data | 10–15% | - Snowsight dashboards and sharing results - Data visualization and reporting - Align outputs with business requirements |
| Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
| Perform Descriptive and Diagnostic Analysis | 10–15% | - Exploratory and ad-hoc analysis - Anomaly detection and root cause analysis - Statistical summarization and trend analysis |
| Perform Simple Data Transformations for Analysis | 15–20% | - Handling NULLs and structuring datasets - Data cleansing, standardization, type conversion - Views, materialized views, CTEs |
To make sure you have all the practice you need, our DAA-C01 practice test also includes numerous opportunities for you to put your skills to the DAA-C01 test. Our Snowflake DAA-C01 practice exams simulate the real thing, so you can experience the pressure and environment of the actual SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) test before the day arrives. You'll receive detailed feedback on your performance, so you know what areas to focus on and improve. At the TrainingDump, we're committed to your success and believe in the effectiveness of our DAA-C01 exam dumps.
NEW QUESTION # 11
You are analyzing the query execution plan of a complex data transformation pipeline in Snowflake. The plan shows a 'Remote Join' operation with high execution time. The two tables involved, 'CUSTOMER and 'ORDERS' , reside in different Snowflake accounts, and the join is performed on the 'CUSTOMER ID' column. Which of the following actions would MOST effectively optimize this query and reduce the 'Remote Join' execution time?
Answer: D,E
Explanation:
Options B and C are the most effective. B eliminates the need for a remote join altogether, and C reduces the amount of data transferred during the remote join. Clustering keys (A) don't directly affect remote joins in the same way they affect local joins. Increasing warehouse size (D) can improve performance but doesn't address the fundamental issue of the remote join data transfer. Option E can help if the aggregated data fulfills the query's requirement and reduces significant data transfer, so it might be partially correct, but replicating data or filtering before joining is optimal in most cases.
NEW QUESTION # 12
Why would an INFER_SCHEMA table function be used?
Answer: D
Explanation:
The INFER_SCHEMA function is a powerful tool in the Snowflake ingestion toolkit, specifically designed to bridge the gap between semi-structured data and relational tables. In modern data engineering, files like Parquet, Avro, and ORC are "self-describing," meaning they contain their own schema definitions (field names and data types) within the file header.
Before INFER_SCHEMA existed, a Data Analyst had to manually inspect a Parquet file, identify the keys, determine their data types, and then manually write a CREATE TABLE statement with the matching columns. INFER_SCHEMA automates this by scanning a set of files in a stage and returning a result set that describes the detected schema. This allows for the dynamic creation of tables that perfectly match the incoming data files.
Evaluating the Options:
* Option A is incorrect because "unstructured data" (like PDFs or Images) does not have a schema that can be "inferred" in a relational sense.
* Option C is incorrect because INFER_SCHEMA operates on files in a Stage, not on data already sitting in a table cell. To parse JSON in a table, you would use functions like FLATTEN or simple path notation.
* Option D is incorrect because the DESCRIBE TABLE or GET_DDL commands are used to retrieve definitions for existing tables.
* Option B is the Correct answer. It specifically identifies the role of the function: detecting metadata (schema) from staged semi-structured files. This function is often used in conjunction with GENERATE_COLUMN_DESCRIPTION and CREATE TABLE ... USING TEMPLATE to fully automate the schema evolution and ingestion process.
NEW QUESTION # 13
Data clustering is an example of which type of data analysis technique?
Answer: D
NEW QUESTION # 14
You have a table 'CUSTOMER LOCATIONS with customer IDs and their geographical locations in WGS 84 format stored in 'LATITUDE' (FLOAT) and 'LONGITUDE' (FLOAT) columns. You need to create a new table 'CUSTOMER GEOGRAPHY' with a 'LOCATION' column of GEOGRAPHY type derived from these latitude and longitude values. Which of the following statements, used individually or in combination, are necessary and correct to accomplish this?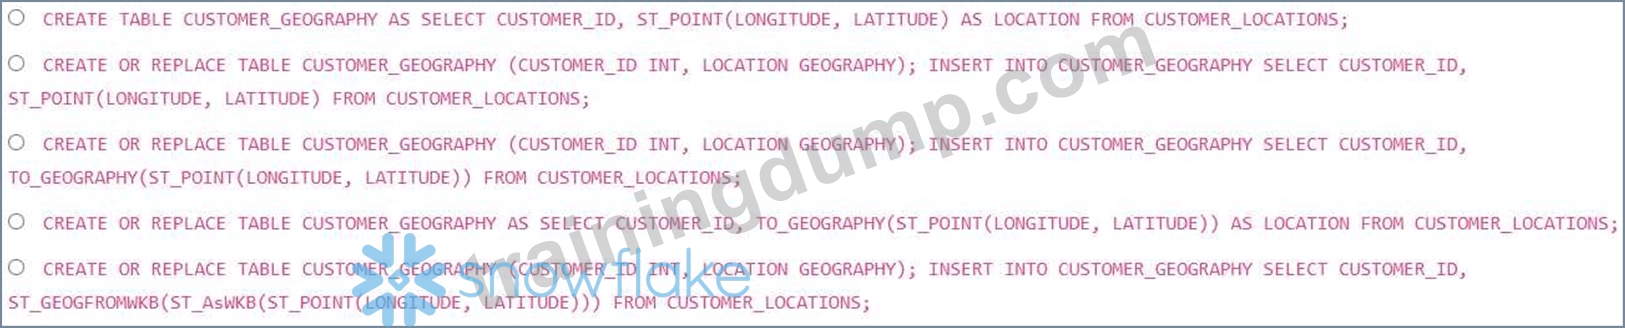
Answer: D
Explanation:
Option D correctly creates the table using a 'CREATE TABLE AS SELECT (CTAS) statement and uses TO LATITUDE))' to convert the latitude and longitude values into a GEOGRAPHY object. This is a concise and efficient way to create the new table with the desired GEOGRAPHY column.
NEW QUESTION # 15
You are building a sales performance dashboard in Snowflake. You need to incorporate a custom metric called 'Sales Efficiency', which is calculated as (Total Sales Revenue / Number of Sales Representatives) 1000. You want to expose this metric in your dashboard and allow users to filter data based on specific Sales Efficiency ranges. You also want to allow filtering by region and quarter. Which of the following approaches would be MOST performant and maintainable in Snowflake?
Answer: B
Explanation:
A materialized view (option C) is the most performant option. It pre-calculates the 'Sales Efficiency' metric and stores the results, allowing for fast retrieval. Proper indexing and partitioning further optimize query performance. Performing the calculation in the dashboard tool (option A) is inefficient for large datasets. IJDFs (option B) can be slower than native SQL. A regular view (option D) does not store the pre- calculated data, so the calculation is performed every time the view is queried. Stored procedures are typically less efficient for dashboard queries than materialized views, as they need to be executed each time.
NEW QUESTION # 16
......
We offer you free demo for DAA-C01 pdf dumps. You can check out the questions quality and usability of our training material before you buy. Snowflake DAA-C01 questions are written to the highest standards of technical accuracy with accurate answers. If you prepare for your exams using TrainingDump DAA-C01 practice torrent, it is easy to succeed for your certification in the first attempt. Besides, we offer the money refund policy, in case of failure, you can ask for full refund.
New DAA-C01 Exam Pdf: https://www.trainingdump.com/Snowflake/DAA-C01-practice-exam-dumps.html
2026 Latest TrainingDump DAA-C01 PDF Dumps and DAA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1HZiysQbhpxV7b-dZQA_odlZXl2B5xyhQ