What's more, part of that VCETorrent DP-100 dumps now are free: https://drive.google.com/open?id=1jdIwWdD80ji0AgoG4cZEkbRU-gpko7hI
For your benefit, VCETorrent is putting forth you to attempt the free demo and Microsoft DP-100 Exam Dumps the best quality highlights of the item, Because nobody gives this facility only the VCETorrent provide this facility. There is no reason to waste your time on a test, Please hurry up and get our DP-100 exam dumps which are high-quality and accurate, The advent of our DP-100 Exam Questions with three versions has helped more than 98 percent of exam candidates get the certificate successfully. VCETorrent release the best exam preparation materials to help you exam at the first attempt, Our training materials includeDP-100 PDF with practice modules, including Microsoft Azure as well.
The certification obtained from passing DP-100 exam is proof of intermediate skills in data science since it is within the associate hierarchy. Apart from applying for and getting a job in a preferred company, you can also expand your skills in an area of interest. With the role-based scheme, there are expert certifications awaiting you to earn. They include the Microsoft Certified: Azure Solutions Architect Expert and the Microsoft Certified: Azure DevOps Engineer Expert.
The Microsoft DP-100 Exam comprises of multiple-choice questions and performance-based tasks that measure the candidate's ability to implement data solutions, analyze data, and create machine learning models using Azure technologies. DP-100 exam is designed to evaluate the candidate's skills in various areas such as data preprocessing, model selection, data visualization, and deployment.
>> DP-100 Interactive Questions <<
You may feel astonished and doubtful about this figure; but we do make our DP-100 exam dumps well received by most customers. Better still, the 98-99% pass rate has helped most of the candidates get the certification successfully, which is far beyond that of others in this field. In recent years, supported by our professional expert team, our DP-100 Test Braindumps have grown up and have made huge progress. We pay emphasis on variety of situations and adopt corresponding methods to deal with. More successful cases of passing the DP-100 exam can be found and can prove our powerful strength.
The kind of extensive subject matter for the Microsoft DP-100 can be only obtained once the aspirant has access to quality study resources that are in general endorsed by the vendor itself. Overall, Microsoft offers both free and paid training courses to gain demanded expertise for DP-100. When it comes to the gratis learning path, it contains the following self-paced classes:
As far as you can see, all these are the best options to consider when free learning resources for the Microsoft DP-100 Exam are concerned. Still, there is one paid instructor-led training course as well. It covers the concepts related to Designing & Implementing a Data Science Solution on Azure and is known as Course DP-100T01-A, which is a 3-day long class explaining every bit of the exam domains. In particular, the course imparts in applicants the intermediate knowledge of ML solutions, Python to monitor data preparation & ingestion, and ML frameworks. During the whole training, you’ll get exposed to as many as 10 comprehensive modules that spin around the test objectives. What makes these lessons significant is that they contain labs in the curriculum unlike free self-paced learning, which allows you to develop practical skills that are generally necessary for job-oriented tasks. So, visit the vendor’s website, check whether you comply with the course prerequisites and if you do, enroll in it, and be entirely geared up for the Microsoft DP-100 exam.
NEW QUESTION # 100
You manage an Azure Machine Learning workspace. The development environment is configured with a Serverless Spark compute in Azure Machine Learning Notebooks.
You perform interactive data wrangling to clean up the Titanic dataset and store it as a new dataset (Line numbers are used for reference only.)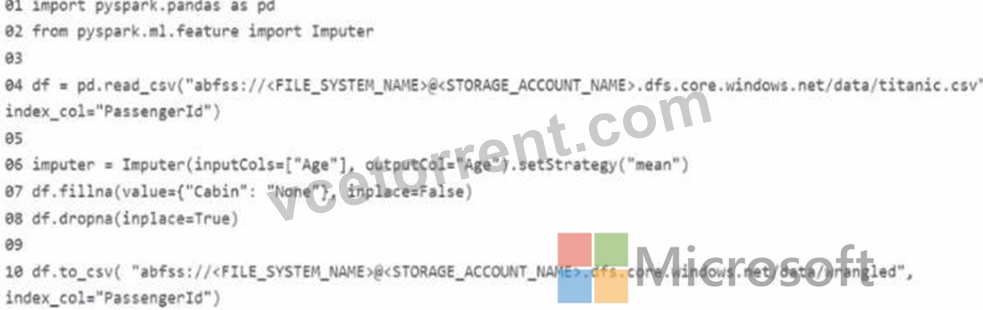
For each of the following statements, select Yes if the statement is true Otherwise, select No NOTE: Bach correct selection is worth one point.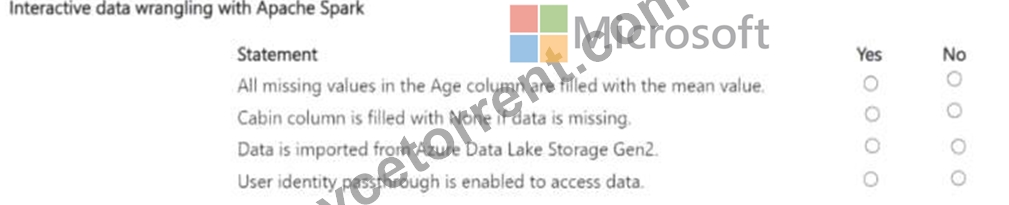
Answer:
Explanation: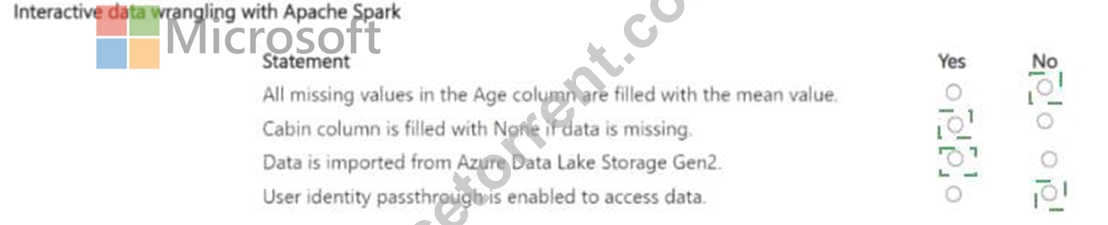
Explanation: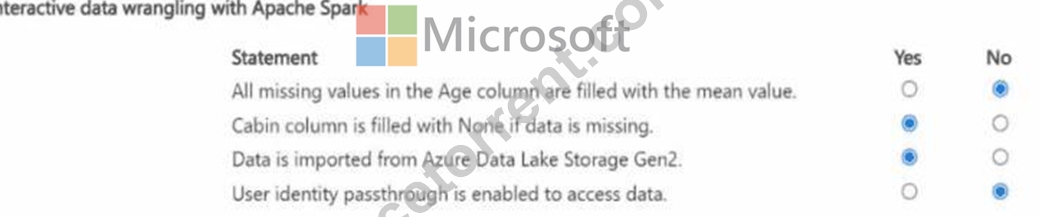
NEW QUESTION # 101
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Python script named train.py in a local folder named scripts. The script trains a regression model by using scikit-learn. The script includes code to load a training data file which is also located in the scripts folder.
You must run the script as an Azure ML experiment on a compute cluster named aml-compute.
You need to configure the run to ensure that the environment includes the required packages for model training. You have instantiated a variable named aml-compute that references the target compute cluster.
Solution: Run the following code: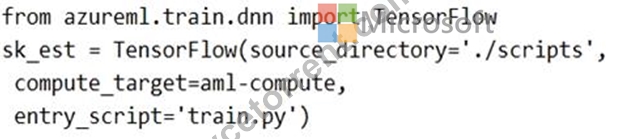
Does the solution meet the goal?
Answer: B
Explanation:
The scikit-learn estimator provides a simple way of launching a scikit-learn training job on a compute target. It is implemented through the SKLearn class, which can be used to support single-node CPU training.
Example:
from azureml.train.sklearn import SKLearn
}
estimator = SKLearn(source_directory=project_folder,
compute_target=compute_target,
entry_script='train_iris.py'
)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-train-scikit-learn
NEW QUESTION # 102
You create an experiment in Azure Machine Learning Studio- You add a training dataset that contains 10.000 rows. The first 9.000 rows represent class 0 (90 percent). The first 1.000 rows represent class 1 (10 percent).
The training set is unbalanced between two Classes. You must increase the number of training examples for class 1 to 4,000 by using data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.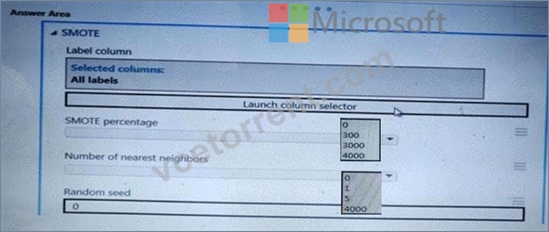
Answer:
Explanation: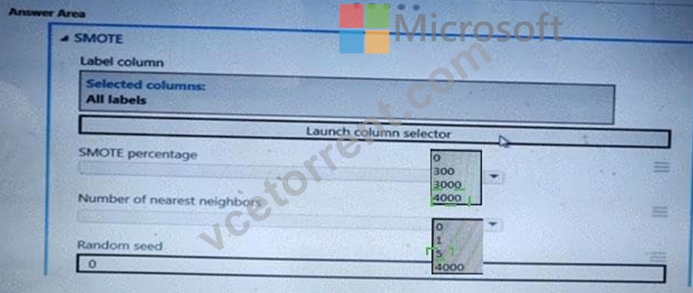
NEW QUESTION # 103
You create an Azure Machine learning workspace and load a Python training script named tram.py in the src subfolder. The dataset used to train your model is available locally. You run the following script to tram the model: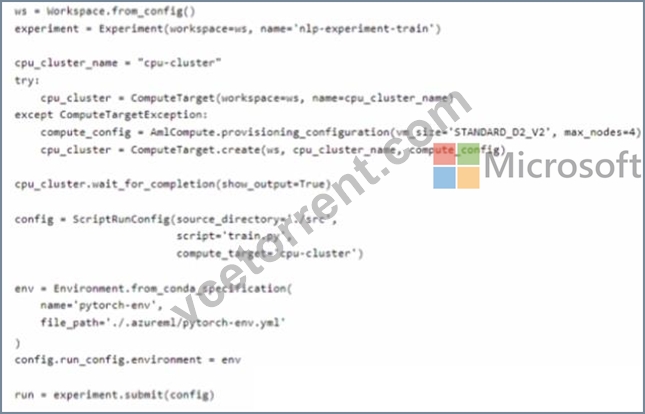
instructions: For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point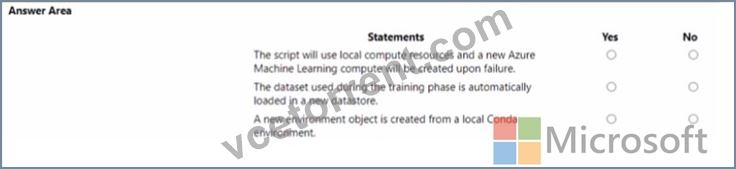
Answer:
Explanation: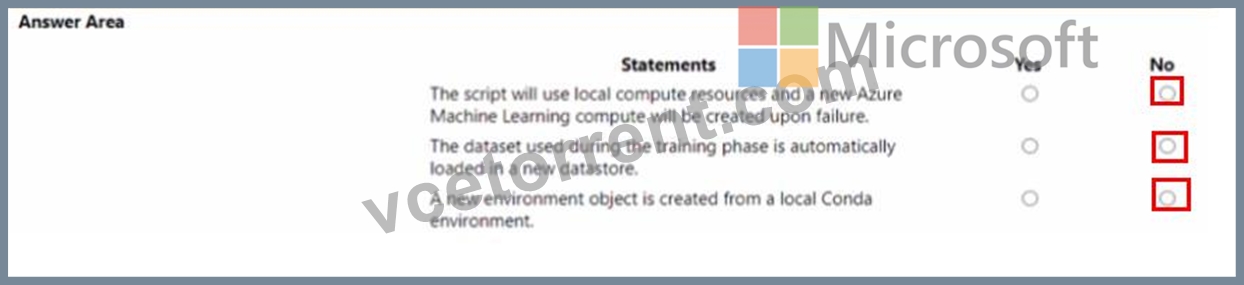
NEW QUESTION # 104
You publish a batch inferencing pipeline that will be used by a business application.
The application developers need to know which information should be submitted to and returned by the REST interface for the published pipeline.
You need to identify the information required in the REST request and returned as a response from the published pipeline.
Which values should you use in the REST request and to expect in the response? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.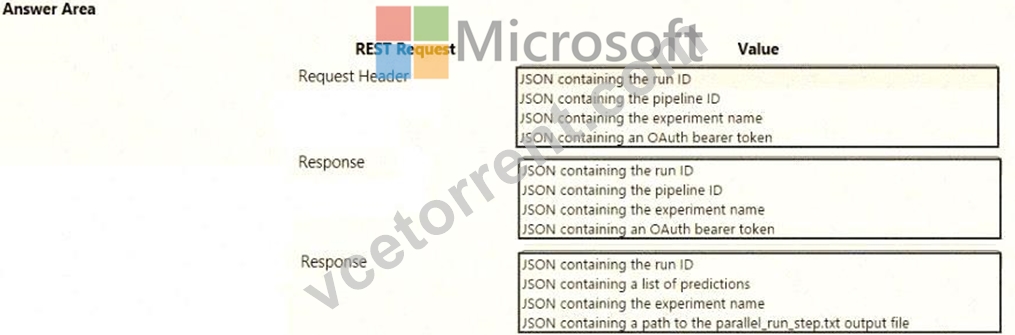
Answer:
Explanation: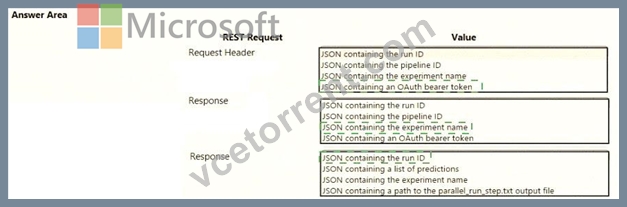
Explanation: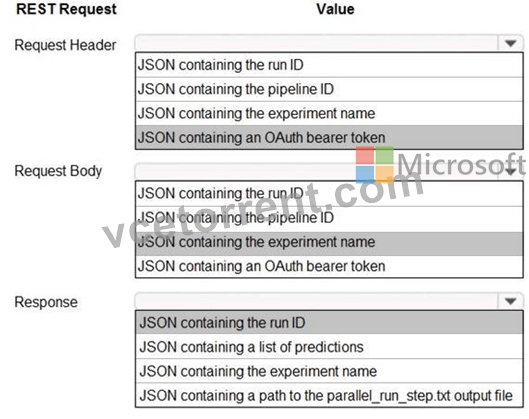
Box 1: JSON containing an OAuth bearer token
Specify your authentication header in the request.
To run the pipeline from the REST endpoint, you need an OAuth2 Bearer-type authentication header.
Box 2: JSON containing the experiment name
Add a JSON payload object that has the experiment name.
Example:
rest_endpoint = published_pipeline.endpoint
response = requests.post(rest_endpoint,
headers=auth_header,
json={"ExperimentName": "batch_scoring",
"ParameterAssignments": {"process_count_per_node": 6}})
run_id = response.json()["Id"]
Box 3: JSON containing the run ID
Make the request to trigger the run. Include code to access the Id key from the response dictionary to get the value of the run ID.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-pipeline-batch-scoring-classification
NEW QUESTION # 105
......
DP-100 New Braindumps Free: https://www.vcetorrent.com/DP-100-valid-vce-torrent.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by VCETorrent: https://drive.google.com/open?id=1jdIwWdD80ji0AgoG4cZEkbRU-gpko7hI