2026 PassTIP 최신 Databricks-Generative-AI-Engineer-Associate PDF 버전 시험 문제집과 Databricks-Generative-AI-Engineer-Associate 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1qKE9gjiYWFdU623waqzg2xlP-qZ95P4q
PassTIP의Databricks인증 Databricks-Generative-AI-Engineer-Associate시험덤프공부가이드 마련은 현명한 선택입니다. Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프구매로 시험패스가 쉬워지고 자격증 취득율이 제고되어 공을 많이 들이지 않고서도 성공을 달콤한 열매를 맛볼수 있습니다.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Exam Duration: | 90 minutes |
| Passing Score: | Scaled Score (approx. 70%) |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Format: | Multiple Select, Multiple Choice |
| Exam Price: | $200 USD |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 45 |
| Available Languages: | English, Korean, Japanese, Portuguese (Brazil) |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate시험대비 최신버전 문제 <<
PassTIP는 우수한 IT인증시험 공부가이드를 제공하는 전문 사이트인데 업계에서 높은 인지도를 가지고 있습니다. PassTIP에서는 IT인증시험에 대비한 모든 덤프자료를 제공해드립니다. Databricks인증 Databricks-Generative-AI-Engineer-Associate시험을 준비하고 계시는 분들은PassTIP의Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프로 시험준비를 해보세요. 놀라운 고득점으로 시험패스를 도와드릴것입니다.시험에서 불합격하면 덤프비용 전액환불을 약속드립니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
질문 # 78
A Generative Al Engineer wants their (inetuned LLMs in their prod Databncks workspace available for testing in their dev workspace as well. All of their workspaces are Unity Catalog enabled and they are currently logging their models into the Model Registry in MLflow.
What is the most cost-effective and secure option for the Generative Al Engineer to accomplish their gAi?
정답:D
설명:
The goal is to make fine-tuned LLMs from a production (prod) Databricks workspace available for testing in a development (dev) workspace, leveraging Unity Catalog and MLflow, while ensuring cost-effectiveness and security. Let's analyze the options.
Option A: Use an external model registry which can be accessed from all workspaces An external registry adds cost (e.g., hosting fees) and complexity (e.g., integration, security configurations) outside Databricks' native ecosystem, reducing security compared to Unity Catalog's governance.
Databricks Reference: "Unity Catalog provides a centralized, secure model registry within Databricks" ("Unity Catalog Documentation," 2023).
Option B: Setup a script to export the model from prod and import it to dev Export/import scripts require manual effort, storage for model artifacts, and repeated execution, increasing operational cost and risk (e.g., version mismatches, unsecured transfers). It's less efficient than a native solution.
Databricks Reference: Manual processes are discouraged when Unity Catalog offers built-in sharing: "Avoid redundant workflows with Unity Catalog's cross-workspace access" ("MLflow with Unity Catalog").
Option C: Setup a duplicate training pipeline in dev, so that an identical model is available in dev Duplicating the training pipeline doubles compute and storage costs, as it retrains the model from scratch. It's neither cost-effective nor necessary when the prod model can be reused securely.
Databricks Reference: "Re-running training is resource-intensive; leverage existing models where possible" ("Generative AI Engineer Guide").
Option D: Use MLflow to log the model directly into Unity Catalog, and enable READ access in the dev workspace to the model Unity Catalog, integrated with MLflow, allows models logged in prod to be centrally managed and accessed across workspaces with fine-grained permissions (e.g., READ for dev). This is cost-effective (no extra infrastructure or retraining) and secure (governed by Databricks' access controls).
Databricks Reference: "Log models to Unity Catalog via MLflow, then grant access to other workspaces securely" ("MLflow Model Registry with Unity Catalog," 2023).
Conclusion: Option D leverages Databricks' native tools (MLflow and Unity Catalog) for a seamless, cost-effective, and secure solution, avoiding external systems, manual scripts, or redundant training.
질문 # 79
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output "In Stock" if the product is available or only the term "Out of Stock" if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
정답:C
설명:
* Problem Context: The Generative AI Engineer needs a prompt that will enable an LLM trained on customer call transcripts to classify and respond correctly regarding product availability. The desired response should clearly indicate whether a product is "In Stock" or "Out of Stock," and it should be formatted in a way that is structured and easy to parse programmatically, such as JSON.
* Explanation of Options:
* Option A: Respond with "In Stock" if the customer asks for a product. This prompt is too generic and does not specify how to handle the case when a product is not available, nor does it provide a structured output format.
* Option B: This option is correctly formatted and explicit. It instructs the LLM to respond based on the availability mentioned in the customer call transcript and to format the response in JSON.
This structure allows for easy integration into systems that may need to process this information automatically, such as customer service dashboards or databases.
* Option C: Respond with "Out of Stock" if the customer asks for a product. Like option A, this prompt is also insufficient as it only covers the scenario where a product is unavailable and does not provide a structured output.
* Option D: While this prompt correctly specifies how to respond based on product availability, it lacks the structured output format, making it less suitable for systems that require formatted data for further processing.
Given the requirements for clear, programmatically usable outputs,Option Bis the optimal choice because it provides precise instructions on how to respond and includes a JSON format example for structuring the output, which is ideal for automated systems or further data handling.
질문 # 80
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = { " prompt_template " : " You are a trivia bot. Generate a question based on the user ' s input:
{user_input} " , " input_vars " : [ " user_input " ], " parameters " : { " temperature " : 0.01, " max_tokens " :
500}}
Which error is causing the problem?
정답:D
설명:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the " input_vars " or " input_variables " must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly " inject " the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user ' s actual question. This results in the model failing to provide relevant information because it essentially doesn ' t know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
질문 # 81
A Generative AI Engineer I using the code below to test setting up a vector store: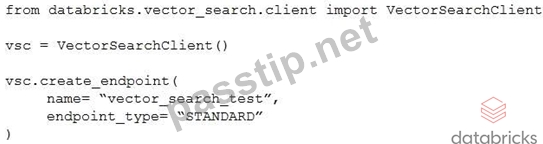
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
정답:B
설명:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
질문 # 82
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user' s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
정답:A,E
설명:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here
' s why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
* Define an evaluation metric : Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user ' s query and the expected response.
* Recall measures the proportion of relevant information retrieved.
* NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
* Experiment with chunking strategies : Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user ' s query than others.
* Evaluate performance : By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
* Use the LLM as an evaluator : After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a " judge " function, where the LLM compares how well a given chunk answers previous user queries.
* Optimize based on the LLM ' s judgment : By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
* This metric could be a qualitative judgment on how closely the retrieved information matches the user ' s intent.
* Tune chunking parameters : Based on the LLM ' s judgment, the engineer can adjust the chunk size or structure to better align with the LLM ' s responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
질문 # 83
......
Databricks-Generative-AI-Engineer-Associate최신 시험 기출문제 모음: https://www.passtip.net/Databricks-Generative-AI-Engineer-Associate-pass-exam.html
2026 PassTIP 최신 Databricks-Generative-AI-Engineer-Associate PDF 버전 시험 문제집과 Databricks-Generative-AI-Engineer-Associate 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1qKE9gjiYWFdU623waqzg2xlP-qZ95P4q