High Pass-Rate Databricks Best Certified-Data-Engineer-Professional Preparation Materials Are Leading Materials & Trustworthy Certified-Data-Engineer-Professional New Braindumps Questions

As you see, all of the three versions of our Certified-Data-Engineer-Professional exam dumps are helpful for you to get the Certified-Data-Engineer-Professional certification. So there is another choice for you to purchase the comprehensive version which contains all the three formats. And no matter which format of Certified-Data-Engineer-Professional study engine you choose, we will give you 24/7 online service and one year's free updates. Moreover, we can assure you a 99% percent pass rate.
| Section | Objectives |
|---|
| Topic 1: Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Topic 2: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 4: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Topic 5: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
| Topic 6: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 7: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 8: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
|
| Topic 9: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
|
| Topic 10: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
>> Best Certified-Data-Engineer-Professional Preparation Materials <<
Certified-Data-Engineer-Professional Exam Best Preparation Materials & Reliable Certified-Data-Engineer-Professional New Braindumps Questions Pass Success
Nowadays, a certificate is not only an affirmation of your ablity but also help you enter a better company. Certified-Data-Engineer-Professional learning materials will offer you an opportunity to get the certificate successfully. We have a professional team to search for the information about the exam, therefore Certified-Data-Engineer-Professional Exam Dumps of us are high-quality. We also pass guarantee and money back guarantee. Just think that, you just need to spend some money, and you can get a certificate, therefore you can have more competitive force in the job market as well as improve your salary.
Databricks Certified Data Engineer Professional Sample Questions (Q161-Q166):
NEW QUESTION # 161
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- B. Instruct the marketing team to download results as a CSV and email them to the sales organization.
- C. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
- D. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- E. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
Answer: A
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
NEW QUESTION # 162
A data engineer is designing a pipeline in Databricks that processes records from a Kafka stream where late-arriving data is common. Which approach should the data engineer use?
- A. Implement a custom solution using Databricks Jobs to periodically reprocess all historical data.
- B. Use batch processing and overwrite the entire output table each time to ensure late data is incorporated correctly.
- C. Use a watermark to specify the allowed lateness to accommodate records that arrive after their expected window, ensuring correct aggregation and state management.
- D. Use an Auto CDC pipeline with batch tables to simplify late data handling.
Answer: C
Explanation:
In Structured Streaming, event-time watermarks control how long the engine waits for late- arriving data before finalizing aggregations. By setting an appropriate watermark, Databricks can handle late data gracefully -- incorporating records that arrive within the defined window while discarding excessively delayed events.
This approach ensures accurate aggregations, minimizes state size, and prevents memory leaks.
Manual reprocessing (A) or overwriting entire datasets (B) is inefficient and costly, while Auto CDC (C) is used for change tracking in Delta tables, not for streaming event lateness.
Thus, using watermarking is the recommended and official approach for managing late data in streaming pipelines.
NEW QUESTION # 163
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
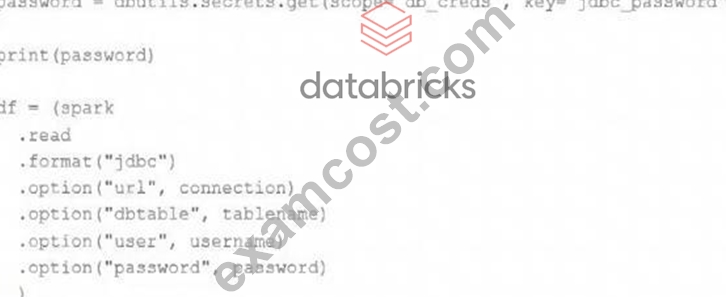
Which statement describes what will happen when the above code is executed?
- A. The connection to the external table will succeed; the string "redacted" will be printed.
- B. The connection to the external table will succeed; the string value of password will be printed in plain text.
- C. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- D. The connection to the external table will fail; the string "redacted" will be printed.
- E. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
Answer: A
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
NEW QUESTION # 164
The data architect has decided that once data has been ingested from external sources into the Databricks Lakehouse, table access controls will be leveraged to manage permissions for all production tables and views.
The following logic was executed to grant privileges for interactive queries on a production database to the core engineering group.
GRANT USAGE ON DATABASE prod TO eng;
GRANT SELECT ON DATABASE prod TO eng;
Assuming these are the only privileges that have been granted to the eng group and that these users are not workspace administrators, which statement describes their privileges?
- A. Group members are able to query and modify all tables and views in the prod database, but cannot create new tables or views.
- B. Group members are able to create, query, and modify all tables and views in the prod database, but cannot define custom functions.
- C. Group members have full permissions on the prod database and can also assign permissions to other users or groups.
- D. Group members are able to list all tables in the prod database but are not able to see the results of any queries on those tables.
- E. Group members are able to query all tables and views in the prod database, but cannot create or edit anything in the database.
Answer: E
Explanation:
The GRANT USAGE ON DATABASE prod TO eng command grants the eng group the permission to use the prod database, which means they can list and access the tables and views in the database. The GRANT SELECT ON DATABASE prod TO eng command grants the eng group the permission to select data from the tables and views in the prod database, which means they can query the data using SQL or DataFrame API. However, these commands do not grant the eng group any other permissions, such as creating, modifying, or deleting tables and views, or defining custom functions. Therefore, the eng group members are able to query all tables and views in the prod database, but cannot create or edit anything in the database.
NEW QUESTION # 165
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
- A. The job_id is returned in this field.
- B. The total number of jobs that have been run in the workspace.
- C. The globally unique ID of the newly triggered run.
- D. The job_id and number of times the job has been are concatenated and returned.
- E. The number of times the job definition has been run in the workspace.
Answer: C
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 166
......
Thus, it will allow you to examine the Databricks Certified-Data-Engineer-Professional Dumps before purchasing it. ExamCost proudly presents the exceptional Databricks Certified-Data-Engineer-Professional material that will meet your expectations. Beware that the sections of the exam change from time to time. Therefore, be alert by checking the updates frequently. It will prevent you from wasting time, material expenses, and inner peace.
Certified-Data-Engineer-Professional New Braindumps Questions: https://www.examcost.com/Certified-Data-Engineer-Professional-practice-exam.html
- Pdf Certified-Data-Engineer-Professional Free ↗ Testking Certified-Data-Engineer-Professional Exam Questions 📚 Valid Certified-Data-Engineer-Professional Test Guide 🧃 Go to website ➥ www.testkingpass.com 🡄 open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 👛Certified-Data-Engineer-Professional Reliable Braindumps Ebook
- Updated Databricks Certified-Data-Engineer-Professional Practice Material In 1 year 👼 Download [ Certified-Data-Engineer-Professional ] for free by simply entering “ www.pdfvce.com ” website 🏋New APP Certified-Data-Engineer-Professional Simulations
- Updated Databricks Certified-Data-Engineer-Professional Practice Material In 1 year 📈 Simply search for ➥ Certified-Data-Engineer-Professional 🡄 for free download on ➽ www.practicevce.com 🢪 ↪Latest Certified-Data-Engineer-Professional Practice Questions
- Free Updates for 365 Days on Databricks Certified-Data-Engineer-Professional Exam Questions 🌕 ⏩ www.pdfvce.com ⏪ is best website to obtain “ Certified-Data-Engineer-Professional ” for free download 🌼Pdf Certified-Data-Engineer-Professional Free
- Updated Databricks Certified-Data-Engineer-Professional Practice Material In 1 year 🔋 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and download it for free immediately on ⇛ www.prepawaypdf.com ⇚ 🔙Certified-Data-Engineer-Professional Questions Exam
- Excellent Best Certified-Data-Engineer-Professional Preparation Materials Help You to Get Acquainted with Real Certified-Data-Engineer-Professional Exam Simulation 👞 Open ➽ www.pdfvce.com 🢪 enter [ Certified-Data-Engineer-Professional ] and obtain a free download 😱Certified-Data-Engineer-Professional Reliable Exam Syllabus
- Updated Databricks Certified-Data-Engineer-Professional Practice Material In 1 year 🤟 “ www.dumpsquestion.com ” is best website to obtain ⮆ Certified-Data-Engineer-Professional ⮄ for free download 🐃Exam Certified-Data-Engineer-Professional Questions
- Certified-Data-Engineer-Professional Exam Preparation Files - Certified-Data-Engineer-Professional Study Materials - Certified-Data-Engineer-Professional Learning materials ☝ Easily obtain free download of ( Certified-Data-Engineer-Professional ) by searching on “ www.pdfvce.com ” 💚Exam Certified-Data-Engineer-Professional Questions
- Updated Databricks Certified-Data-Engineer-Professional Practice Material In 1 year ℹ Copy URL ( www.vce4dumps.com ) open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 😭Certified-Data-Engineer-Professional Valid Exam Blueprint
- Free Updates for 365 Days on Databricks Certified-Data-Engineer-Professional Exam Questions 🤲 Search on ⏩ www.pdfvce.com ⏪ for 【 Certified-Data-Engineer-Professional 】 to obtain exam materials for free download 🍜Certified-Data-Engineer-Professional Sure Pass
- Free Updates for 365 Days on Databricks Certified-Data-Engineer-Professional Exam Questions ⤵ Search for ➠ Certified-Data-Engineer-Professional 🠰 and obtain a free download on ☀ www.easy4engine.com ️☀️ 🎀Certified-Data-Engineer-Professional Questions Exam
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, scalar.usc.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes