BONUS!!! Download part of Real4Prep Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1YiMxn5AkSmNg2s19BNGlORDmqO8SF3Yp
Learn for your Google Professional-Machine-Learning-Engineer certification with confidence by utilizing the Real4Prep Professional-Machine-Learning-Engineer study guide, which is always forward-thinking, convenient, current, and dependable. If you are still unsure whether to pursue Real4Prep Professional-Machine-Learning-Engineer Exam Questions for Google Professional Machine Learning Engineer certification exam preparation, you are losing the game at the first stage in a fiercely competitive marketplace. Real4Prep Professional-Machine-Learning-Engineer questions are the best option.
| Section | Objectives |
|---|---|
| Topic 1: Data preparation and processing | - Data ingestion and pipelines
|
| Topic 2: Deployment and operations | - Monitoring and maintenance
|
| Topic 3: ML model development | - Model training and tuning
|
| Topic 4: ML pipeline automation and orchestration | - Pipeline design
|
| Topic 5: Designing ML solutions | - ML architecture design
|
>> Professional-Machine-Learning-Engineer Reliable Exam Blueprint <<
It is possible for you to easily pass Professional-Machine-Learning-Engineer exam. Many users who have easily pass Professional-Machine-Learning-Engineer exam with our Professional-Machine-Learning-Engineer exam software of Real4Prep. You will have a real try after you download our free demo of Professional-Machine-Learning-Engineer Exam software. We will be responsible for every customer who has purchased our product. We ensure that the Professional-Machine-Learning-Engineer exam software you are using is the latest version.
NEW QUESTION # 202
Your data science team needs to rapidly experiment with various features, model architectures, and hyperparameters. They need to track the accuracy metrics for various experiments and use an API to query the metrics over time. What should they use to track and report their experiments while minimizing manual effort?
Answer: D
Explanation:
https://codelabs.developers.google.com/codelabs/cloud-kubeflow-pipelines-gis Kubeflow Pipelines (KFP) helps solve these issues by providing a way to deploy robust, repeatable machine learning pipelines along with monitoring, auditing, version tracking, and reproducibility. Cloud AI Pipelines makes it easy to set up a KFP installation.
https://www.kubeflow.org/docs/components/pipelines/introduction/#what-is-kubeflow-pipelines
"Kubeflow Pipelines supports the export of scalar metrics. You can write a list of metrics to a local file to describe the performance of the model. The pipeline agent uploads the local file as your run-time metrics. You can view the uploaded metrics as a visualization in the Runs page for a particular experiment in the Kubeflow Pipelines UI." https://www.kubeflow.org/docs/components/pipelines/sdk/pipelines-metrics/
NEW QUESTION # 203
You need to train a natural language model to perform text classification on product descriptions that contain millions of examples and 100,000 unique words. You want to preprocess the words individually so that they can be fed into a recurrent neural network. What should you do?
Answer: C
Explanation:
https://developers.google.com/machine-learning/guides/text-classification/ it is a Word Embedding case
NEW QUESTION # 204
You work at a gaming startup that has several terabytes of structured data in Cloud Storage. This data includes gameplay time data, user metadata, and game metadata. You want to build a model that recommends new games to users that requires the least amount of coding. What should you do?
Answer: A
Explanation:
https://developers.google.com/machine-learning/recommendation/collaborative/matrix
NEW QUESTION # 205
You work for the AI team of an automobile company, and you are developing a visual defect detection model using TensorFlow and Keras. To improve your model performance, you want to incorporate some image augmentation functions such as translation, cropping, and contrast tweaking. You randomly apply these functions to each training batch. You want to optimize your data processing pipeline for run time and compute resources utilization. What should you do?
Answer: B
Explanation:
The best option for optimizing the data processing pipeline for run time and compute resources utilization is to embed the augmentation functions dynamically in the tf.Data pipeline. This option has the following advantages:
* It allows the data augmentation to be performed on the fly, without creating or storing additional copies of the data. This saves storage space and reduces the data transfer time.
* It leverages the parallelism and performance of the tf.Data API, which can efficiently apply the augmentation functions to multiple batches of data in parallel, using multiple CPU cores or GPU
* devices. The tf.Data API also supports various optimization techniques, such as caching, prefetching, and autotuning, to improve the data processing speed and reduce the latency.
* It integrates seamlessly with the TensorFlow and Keras models, which can consume the tf.Data datasets as inputs for training and evaluation. The tf.Data API also supports various data formats, such as images, text, audio, and video, and various data sources, such as files, databases, and web services.
The other options are less optimal for the following reasons:
* Option B: Embedding the augmentation functions dynamically as part of Keras generators introduces some limitations and overhead. Keras generators are Python generators that yield batches of data for training or evaluation. However, Keras generators are not compatible with the tf.distribute API, which is used to distribute the training across multiple devices or machines. Moreover, Keras generators are not as efficient or scalable as the tf.Data API, as they run on a single Python thread and do not support parallelism or optimization techniques.
* Option C: Using Dataflow to create all possible augmentations, and store them as TFRecords introduces additional complexity and cost. Dataflow is a fully managed service that runs Apache Beam pipelines for data processing and transformation. However, using Dataflow to create all possible augmentations requires generating and storing a large number of augmented images, which can consume a lot of storage space and incur storage and network costs. Moreover, using Dataflow to create the augmentations requires writing and deploying a separate Dataflow pipeline, which can be tedious and time-consuming.
* Option D: Using Dataflow to create the augmentations dynamically per training run, and stage them as TFRecords introduces additional complexity and latency. Dataflow is a fully managed service that runs Apache Beam pipelines for data processing and transformation. However, using Dataflow to create the augmentations dynamically per training run requires running a Dataflow pipeline every time the model is trained, which can introduce latency and delay the training process. Moreover, using Dataflow to create the augmentations requires writing and deploying a separate Dataflow pipeline, which can be tedious and time-consuming.
References:
* [tf.data: Build TensorFlow input pipelines]
* [Image augmentation | TensorFlow Core]
* [Dataflow documentation]
NEW QUESTION # 206
You work for a retail company. You have a managed tabular dataset in Vertex Al that contains sales data from three different stores. The dataset includes several features such as store name and sale timestamp. You want to use the data to train a model that makes sales predictions for a new store that will open soon You need to split the data between the training, validation, and test sets What approach should you use to split the data?
Answer: B
Explanation:
The best option for splitting the data between the training, validation, and test sets, using a managed tabular dataset in Vertex AI that contains sales data from three different stores, is to use Vertex AI default data split.
This option allows you to leverage the power and simplicity of Vertex AI to automatically and randomly split your data into the three sets by percentage. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can support various types of models, such as linear regression, logistic regression, k-means clustering, matrix factorization, and deep neural networks. Vertex AI can also provide various tools and services for data analysis, model development, model deployment, model monitoring, and model governance. A default data split is a data split method that is provided by Vertex AI, and does not require any user input or configuration. A default data split can help you split your data into the training, validation, and test sets by using a random sampling method, and assign a fixed percentage of the data to each set. A default data split can help you simplify the data split process, and works well in most cases.
A training set is a subset of the data that is used to train the model, and adjust the model parameters. A training set can help you learn the relationship between the input features and the target variable, and optimize the model performance. A validation set is a subset of the data that is used to validate the model, and tune the model hyperparameters. A validation set can help you evaluate the model performance on unseen data, and avoid overfitting or underfitting. A test set is a subset of the data that is used to test the model, and provide the final evaluation metrics. A test set can help you assess the model performance on new data, and measure the generalization ability of the model. By using Vertex AI default data split, you can split your data into the training, validation, and test sets by using a random sampling method, and assign the following percentages of the data to each set1: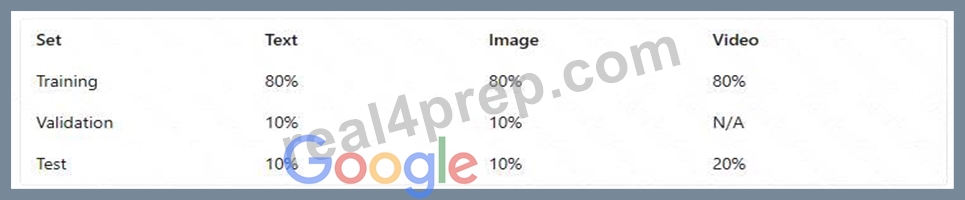
The other options are not as good as option B, for the following reasons:
* Option A: Using Vertex AI manual split, using the store name feature to assign one store for each set would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. A manual split is a data split method that allows you to control how your data is split into sets, by using the ml_use label or the data filter expression. A manual split can help you customize the data split logic, and handle complex or non-standard data formats. A store name feature is a feature that indicates the name of the store where the sales data was collected. A store name feature can help you identify the source of the data, and group the data by store. However, using Vertex AI manual split, using the store name feature to assign one store for each set would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. You would need to write code, create and configure the ml_use label or the data filter expression, and assign one store for each set. Moreover, this option would not ensure that the data in each set has the same distribution and characteristics as the data in the whole dataset, which could prevent you from learning the general pattern of the data, and cause bias or variance in the model2.
* Option C: Using Vertex AI chronological split and specifying the sales timestamp feature as the time variable would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. A chronological split is a data split method that allows you to split your data into sets based on the order of the data. A chronological split can help you preserve the temporal dependency and sequence of the data, and avoid data leakage. A sales timestamp feature is a feature that indicates the date and time when the sales data was collected. A sales timestamp feature can help you track the changes and trends of the data over time, and capture the seasonality and cyclicality of the data. However, using Vertex AI chronological split and specifying the sales timestamp feature as the time variable would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. You would need to write code, create and configure the time variable, and split the data by the order of the time variable. Moreover, this option would not ensure that the data in each set has the same distribution and characteristics as the data in the whole dataset, which could prevent you from learning the general pattern of the data, and cause bias or variance in the model3.
* Option D: Using Vertex AI random split, assigning 70% of the rows to the training set, 10% to the validation set, and 20% to the test set would not allow you to use the default data split method that is provided by Vertex AI, and could increase the complexity and cost of the data split process. A random split is a data split method that allows you to split your data into sets by using a random sampling method, and assign a custom percentage of the data to each set. A random split can help you split your data into representative and balanced sets, and avoid data leakage. However, using Vertex AI random split, assigning 70% of the rows to the training set, 10% to the validation set, and 20% to the test set would not allow you to use the default data split method that is provided by Vertex AI, and could increase the complexity and cost of the data split process. You would need to write code, create and
* configure the random split method, and assign the custom percentages to each set. Moreover, this option would not use the default data split method that is provided by Vertex AI, which can simplify the data split process, and works well in most cases1.
References:
* About data splits for AutoML models | Vertex AI | Google Cloud
* Manual split for unstructured data
* Mathematical split
NEW QUESTION # 207
......
Our Google Exam Questions greatly help Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam candidates in their preparation. Our Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) practice questions are designed and verified by prominent and qualified Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam dumps preparation experts. The qualified Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam questions preparation experts strive hard and put all their expertise to ensure the top standard and relevancy of Professional-Machine-Learning-Engineer exam dumps topics.
Professional-Machine-Learning-Engineer Trusted Exam Resource: https://www.real4prep.com/Professional-Machine-Learning-Engineer-exam.html
BTW, DOWNLOAD part of Real4Prep Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1YiMxn5AkSmNg2s19BNGlORDmqO8SF3Yp