通過AI-500 考試不是很簡單的。通過AI-500考試需要高度專業的知識,如果你還欠缺這方面的知識,NewDumps可以為你提供知識的來源。NewDumps的專家團隊以他們的豐富的專業知識和經驗幫助你增長知識,並且給你能提供AI-500認證考試的相關練習題和答案。NewDumps會盡全力幫助你一次性通過AI-500認證考試,並且還可以鞏固你的IT專業知識。選擇了NewDumps不僅可以保證你100%通過AI-500認證考試,並且還會為你提供一年的免費的練習題和答案的更新服務。如果你考試不小心失敗了,我們保證立刻地100%全額退款給您。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Topic 2: Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
在如今互聯網如此發達社會裏,選擇線上培訓已經是很普遍的現象。NewDumps就是眾多線上培訓網站之一。NewDumps的線上培訓有著多年的經驗,可以為參加Microsoft AI-500 認證考試的考生提供高品質的學習資料,來能滿足考生的所有需求。
問題 #30
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator agent that sends a mix of simple requests, reasoning-heavy tasks, and tool-calling workflows to a single premium model deployment.
Response quality is acceptable, but costs are too high, and latency varies significantly across requests.
You need to recommend a solution to reduce token utilization based on the complexity of the user input.
What should you include in the recommendation?
答案:D
解題說明:
The workload mixes simple prompts, reasoning-heavy tasks, and tool-calling workflows, so a single premium model is over-provisioned for many requests. Microsoft Foundry ' s model router evaluates request complexity and routes each request to an appropriate model from a configured pool. Simple work can use lower-cost, lower-latency models, while complex reasoning can still be assigned to a more capable model.
Structured outputs constrain response format but do not reduce model capability according to request complexity. Prompt Optimizer can improve prompt quality but does not perform per-request model selection, and choosing another flagship model would preserve the same all-requests-use-premium pattern. Therefore A directly addresses the cost and latency variability by matching model capacity to workload complexity. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - Model router
問題 #31
You have a Microsoft Foundry multi-agent customer support solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. A custom guardrail is assigned to the agents.
You discover that some legitimate support requests are blocked, and some injected instructions in retrieved documents are allowed.
You need to validate the updated guardrail. The solution must meet the following requirements:
* Identify false positives and false negatives.
* Verify policy coverage across the agent solution
* Prevent changing the production agent behavior during testing
* Measure intervention accuracy by using a control and intervention point.
What should you do?
答案:B
解題說明:
The updated guardrail must be evaluated with known benign and adversarial cases so false positives and false negatives can be measured explicitly. Running labeled cases through every relevant workflow path also tests whether the guardrail is applied consistently at the intended intervention points. Microsoft AI-500 guidance includes guardrail testing with synthetic or curated data and emphasizes evaluation before production rollout.
Playground-only spot checks are too narrow to establish coverage. Switching production to annotate-only would change live behavior and use customers as the test population, violating the requirement to avoid production changes. A compliance configuration review verifies that a policy exists but does not measure whether it correctly detects or misses real inputs. Option B is therefore the only approach that produces repeatable evidence of intervention accuracy and policy coverage without changing production behavior. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: AI-500 Study Guide - guardrail testing and evaluation
問題 #32
You need to implement the business rule for claim Approval. Which workflow node should you use?
答案:C
解題說明:
The business rule requires human review for refunds above the stated threshold before payment can continue.
A workflow therefore needs a user or operator interaction point that pauses progress and obtains an explicit response. In the workflow options provided, Ask a question is the node that introduces that human interaction.
Invoke agent simply delegates work to another agent; it does not itself guarantee human approval. Deliver a message sends information without collecting a decision, and Go to changes control flow without obtaining authorization. Microsoft Agent Framework and Foundry workflow guidance treat human-in-the-loop approval as a first-class orchestration requirement for consequential actions. The decisive requirement is not just to notify a reviewer, but to stop automated progression until the reviewer supplies a decision. Therefore the workflow must include an interactive question/approval step before the refund-processing action can proceed for amounts over the threshold. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - Human-in-the-loop workflows
問題 #33
You need to implement a logging solution for claim Approval.
What should you use for each process? To answer, drag the appropriate resources to the correct processes.
Each resource may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.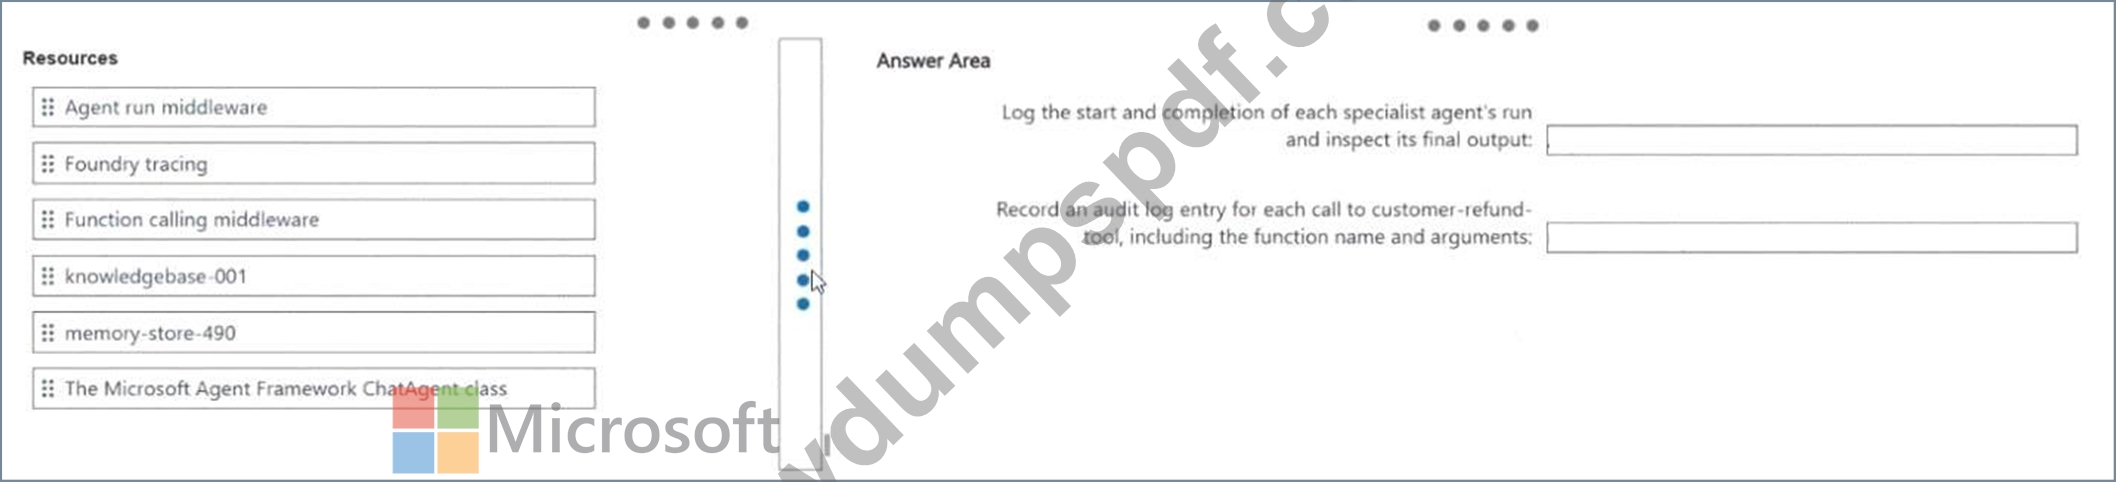
答案:
解題說明: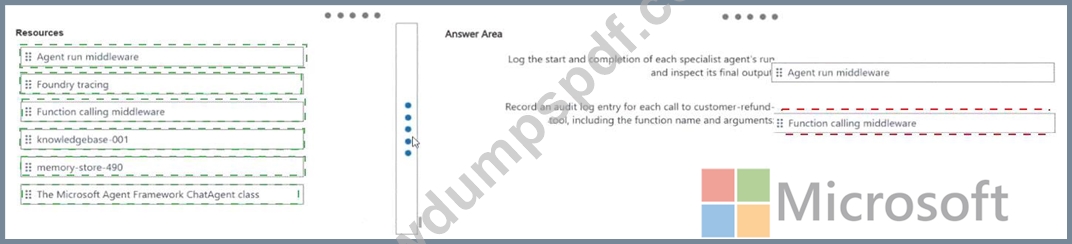
Explanation:
Log the start/completion of each specialist run and inspect the final output with Agent run middleware; record each customer-refund-tool call, including function name and arguments, with Function calling middleware.
The two logging requirements occur at different lifecycle boundaries. Agent run middleware surrounds an agent invocation, so it is the appropriate place to capture run start, run completion, exceptions, and the final agent result. Function calling middleware surrounds tool/function execution and can inspect the selected function, arguments, result, and failures. That makes it the correct boundary for an audit record of each customer-refund-tool invocation. Foundry tracing can provide broader distributed observability, but the question asks for reusable Microsoft Agent Framework middleware at the exact execution points. A knowledge store or memory store does not provide execution interception. Separating the two concerns also supports a cleaner audit model: agent-level middleware records specialist behavior, while function-level middleware records tool use. This aligns with Microsoft ' s middleware model, where cross-cutting concerns such as logging, validation, and exception handling can be implemented once and applied consistently rather than duplicated inside every agent or tool.
Official Microsoft reference: Microsoft Agent Framework - Defining middleware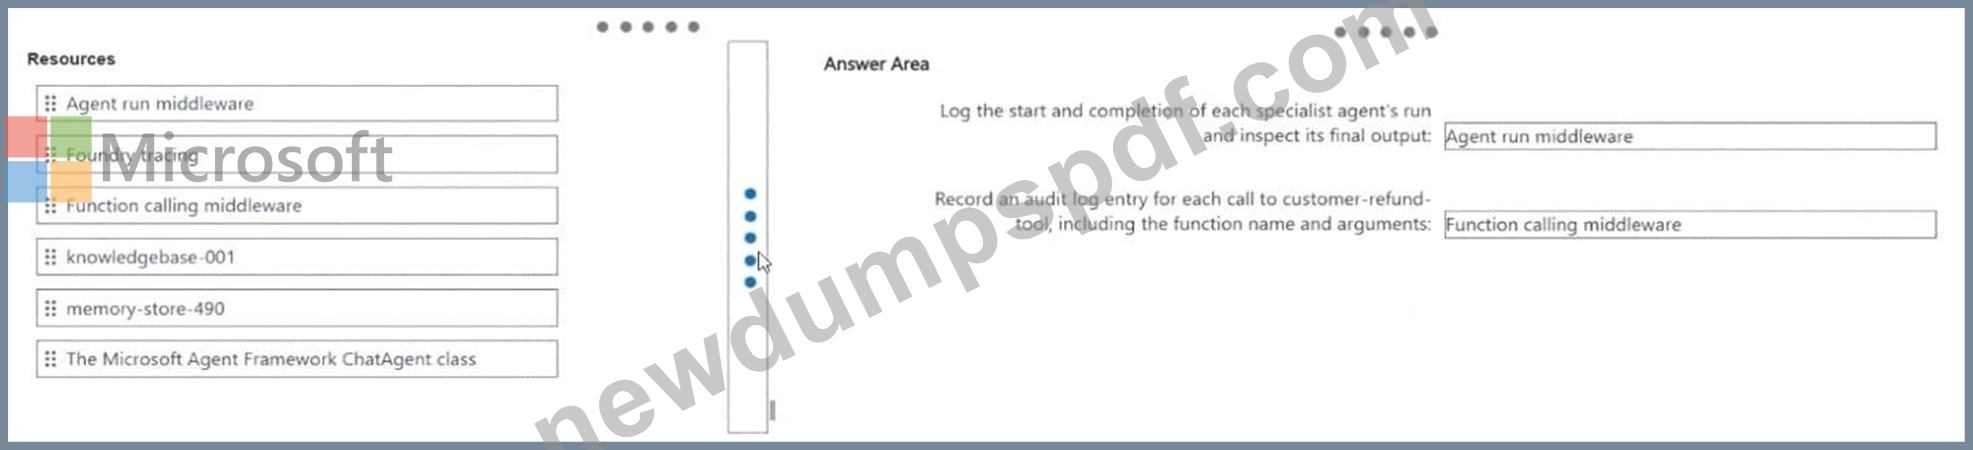
問題 #34
You have a Microsoft Foundry agent that answers questions about products. You evaluate the agent responses and discover the following issues:
* Questions about a product named product1 make up 40 percent of user traffic, and responses are returned in inconsistent formats.
* Questions about a product named product2 appear infrequently in the existing logs but have high escalation rates.
The available chat logs include customer names and contact details, and the labeling budget enables subject matter experts (SMEs) to review only a limited subset of training examples.
You need to design a dataset preparation plan to fine-tune the agent. The solution must meet the following requirements:
* Match usage patterns for the product1 questions.
* Cover the product2 questions.
* Meet General Data Protection Regulation < GDPR) and Health Insurance Portability and Accountability Act (HIPAA) privacy requirements for names and contact details.
* Minimize SME review efforts during labeling.
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.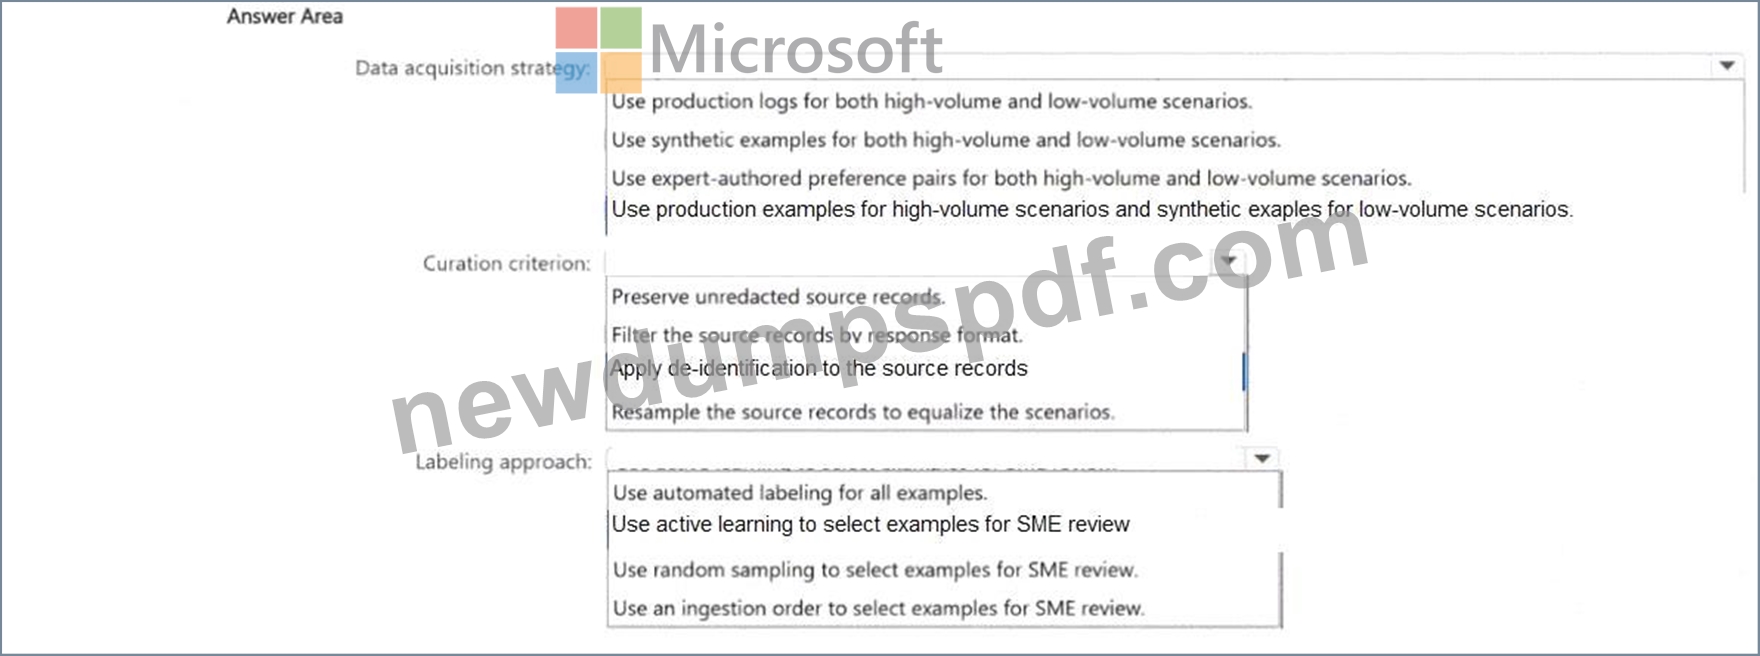
答案:
解題說明: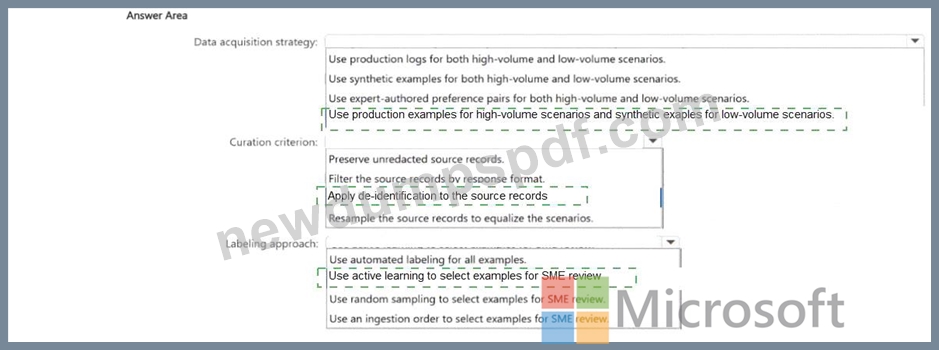
Explanation:
Data acquisition: Production examples for high-volume product1 and synthetic examples for sparse product2; Curation: De-identify source records; Labeling: Use active learning to prioritize SME review.
Product1 represents a large share of real traffic, so production examples best preserve its true usage distribution. Product2 appears infrequently but has high escalation impact, making synthetic generation appropriate for filling the coverage gap without waiting for more production traffic. Because the available logs contain names and contact information, those records should be de-identified before they are reused for training or labeling. Finally, the SME budget is limited, so active learning should prioritize the examples where expert labels are most informative instead of reviewing a uniform random sample. Microsoft Foundry guidance supports synthetic fine-tuning data when real examples are sparse, and Microsoft healthcare/privacy tooling supports de-identification of sensitive identifiers. This design balances representativeness, rare-case coverage, privacy, and labeling efficiency. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation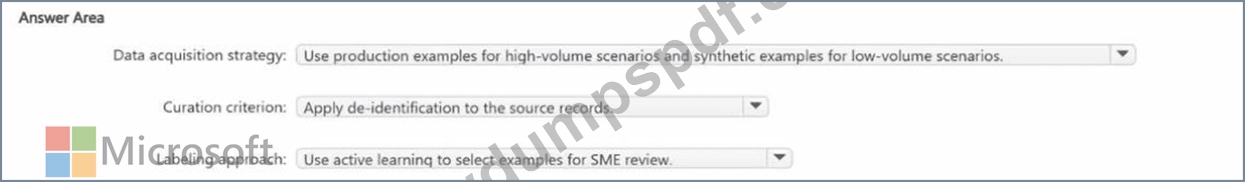
問題 #35
......
永遠不要說你已經盡力了。這個對每個人的忠告,就算你認為自己沒有能力通過苛刻的Microsoft的AI-500考試認證。因為就算你沒有通過Microsoft的AI-500考試認證,你可以找一個快捷又方便省時又不費力的培訓工具,來幫助你通過Microsoft的AI-500考試認證,NewDumps Microsoft的AI-500考試培訓資料就是個很不錯的黃金培訓資料,它可以幫助你順利通過考試,保證100%通過,而且價格很合理,保證你利用了它會受益匪淺,所以說永遠不要說自己已經盡力了,不放棄下一秒就是希望,趕緊抓住你的希望吧,就在NewDumps Microsoft的AI-500考試培訓資料裏。
AI-500考題資源: https://www.newdumpspdf.com/AI-500-exam-new-dumps.html