有効的なDatabricks-Certified-Professional-Data-Engineer英語版 &合格スムーズDatabricks-Certified-Professional-Data-Engineer勉強時間 |信頼できるDatabricks-Certified-Professional-Data-Engineer復習テキスト

さらに、PassTest Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1XSC9val4ptWBjSm9gnBndQFV-BGDA9Th
現在のネットワークの全盛期で、DatabricksのDatabricks-Certified-Professional-Data-Engineerの認証試験を準備するのにいろいろな方法があります。PassTestが提供した最も依頼できるトレーニングの問題と解答はあなたが気楽にDatabricksのDatabricks-Certified-Professional-Data-Engineerの認証試験を受かることに助けを差し上げます。PassTestにDatabricksのDatabricks-Certified-Professional-Data-Engineerの試験に関する問題はいくつかの種類がありますから、すべてのIT認証試験の要求を満たすことができます。
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Bronze, silver, gold data layers
- 2. Data governance fundamentals
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Topic 2: Delta Lake | 20-25% | - Delta Lake operations
- 1. Schema evolution and enforcement
- 2. Delta Live Tables
- 3. Merge, update, delete operations
- Delta Lake fundamentals
- 1. ACID transactions
- 2. Time travel and data versioning
- 3. Optimize and Z-order
|
| Topic 3: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Performance optimization techniques
- 3. Built-in and user-defined functions
- Spark DataFrames and Spark SQL
- 1. Window functions
- 2. DataFrame operations and transformations
- 3. Spark SQL queries and functions
|
| Topic 4: Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. DBR autoloader
- 3. Integration with external systems
- Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
|
| Topic 5: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Task dependencies and orchestration
- 3. Jobs and job scheduling
|
>> Databricks-Certified-Professional-Data-Engineer英語版 <<
Databricks Databricks-Certified-Professional-Data-Engineer勉強時間、Databricks-Certified-Professional-Data-Engineer復習テキスト
21世紀には、{Examcode}認定は受験者の特定の能力を表すため、社会でますます認知されるようになりました。ただし、{Examcode}認定を取得するには、Databricks-Certified-Professional-Data-Engineer試験の準備に多くの時間を費やす必要があります。Databricks-Certified-Professional-Data-Engineer模擬試験を購入すると、当社のウェブサイトはプロの技術を使用してすべてのユーザーのプライバシーを暗号化し、ハッカーの盗用を防ぎます。私たちは、ビジネスがお客様のために十分に考慮された場合にのみ継続できると考えているため、当社の評判を損なうような行為は一切行いません。 Databricks-Certified-Professional-Data-Engineer試験問題に完全な信頼を寄せていただければ幸いです。失望することはありません。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q50-Q55):
質問 # 50
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control. The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity.
Which SQL query should the team run from the System catalog to achieve this?
A)
SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
B)
SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10
C)
SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
D)
SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
- A. Option A
- B. Option D
- C. Option B
- D. Option C
- E. Option E
正解:C
解説:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non-existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
質問 # 51
The data engineering team maintains the following code:
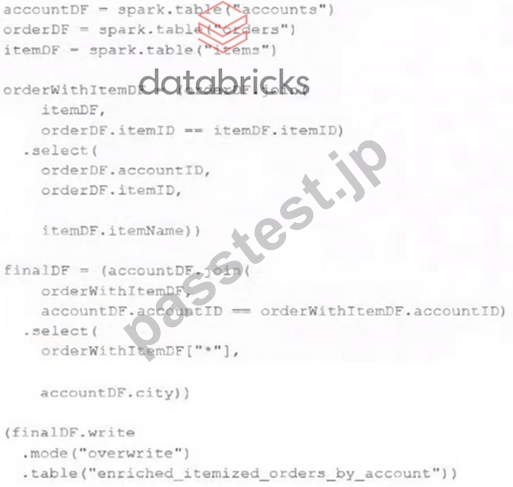
Assuming that this code produces logically correct results and the data in the source tables has been de- duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- B. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- C. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- D. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- E. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
正解:B
解説:
The provided PySpark code performs the following operations:
* Reads Data from silver_customer_sales Table:
* The code starts by accessing the silver_customer_sales table using the spark.table method.
* Groups Data by customer_id:
* The .groupBy( " customer_id " ) function groups the data based on the customer_id column.
* Aggregates Data:
* The .agg() function computes several aggregate metrics for each customer_id:
* F.min( " sale_date " ).alias( " first_transaction_date " ): Determines the earliest sale date for the customer.
* F.max( " sale_date " ).alias( " last_transaction_date " ): Determines the latest sale date for the customer.
* F.mean( " sale_total " ).alias( " average_sales " ): Calculates the average sale amount for the customer.
* F.countDistinct( " order_id " ).alias( " total_orders " ): Counts the number of unique orders placed by the customer.
* F.sum( " sale_total " ).alias( " lifetime_value " ): Calculates the total sales amount (lifetime value) for the customer.
* Writes Data to gold_customer_lifetime_sales_summary Table:
* The .write.mode( " overwrite " ).table( " gold_customer_lifetime_sales_summary " ) command writes the aggregated data to the gold_customer_lifetime_sales_summary table.
* The mode( " overwrite " ) specifies that the existing data in the
gold_customer_lifetime_sales_summary table will be completely replaced by the new aggregated data.
Conclusion:
When this code is executed, it reads all records from the silver_customer_sales table, performs the specified aggregations grouped by customer_id, and then overwrites the entire gold_customer_lifetime_sales_summary table with the aggregated results. Therefore, option D accurately describes this process: " The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job. " References:
PySpark DataFrame groupBy
PySpark Basics
質問 # 52
Which statement characterizes the general programming model used by Spark Structured Streaming?
- A. Structured Streaming relies on a distributed network of nodes that hold incremental state values for cached stages.
- B. Structured Streaming is implemented as a messaging bus and is derived from Apache Kafka.
- C. Structured Streaming leverages the parallel processing of GPUs to achieve highly parallel data throughput.
- D. Structured Streaming models new data arriving in a data stream as new rows appended to an unbounded table.
- E. Structured Streaming uses specialized hardware and I/O streams to achieve sub-second latency for data transfer.
正解:D
解説:
This is the correct answer because it characterizes the general programming model used by Spark Structured Streaming, which is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model, where users can express their streaming computation using the same Dataset/DataFrame API as they would use for static data. The Spark SQL engine will take care of running the streaming query incrementally and continuously and updating the final result as streaming data continues to arrive. Verified Reference: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Overview" section.
質問 # 53
The viewupdatesrepresents an incremental batch of all newly ingested data to be inserted or updated in the customerstable.
The following logic is used to process these records.
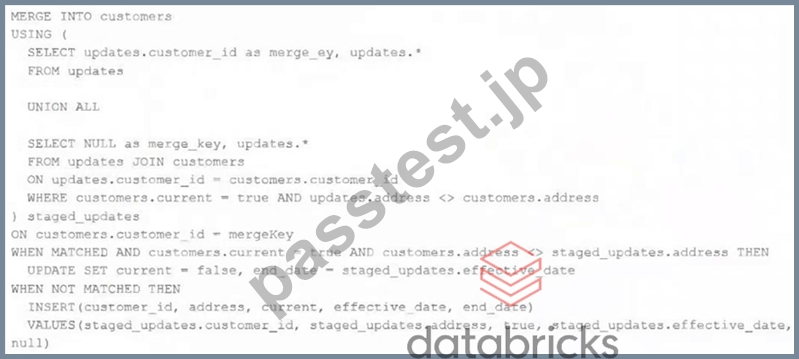
Which statement describes this implementation?
- A. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- B. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- C. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- D. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- E. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
正解:E
解説:
Explanation
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case, the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
質問 # 54
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- B. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
- C. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
- D. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
正解:A
解説:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
References:
* Databricks documentation on using SQL views in Delta Lake: https://docs.databricks.com/delta/quick- start.html#sql-views
質問 # 55
......
Databricks-Certified-Professional-Data-Engineerテストトレントは高品質で、主に合格率に反映されます。 Databricks-Certified-Professional-Data-Engineerテストトレントは、過去数年間の試験問題と業界動向に基づいて、業界の専門家によって慎重に編集されています。さらに重要なことは、時間の変化に基づいてDatabricks-Certified-Professional-Data-Engineer試験資料を速やかに更新し、タイムリーに送信することです。教材を使用している人の99%が試験に合格し、証明書に合格しています。これは、間違いなく、Databricks-Certified-Professional-Data-Engineerテストトレントの合格率が99%であることを示しています。
Databricks-Certified-Professional-Data-Engineer勉強時間: https://www.passtest.jp/Databricks/Databricks-Certified-Professional-Data-Engineer-shiken.html
- Databricks-Certified-Professional-Data-Engineer学習指導 🪂 Databricks-Certified-Professional-Data-Engineer日本語認定対策 🌕 Databricks-Certified-Professional-Data-Engineer専門知識内容 🌈 ➽ www.goshiken.com 🢪から簡単に➠ Databricks-Certified-Professional-Data-Engineer 🠰を無料でダウンロードできますDatabricks-Certified-Professional-Data-Engineer的中率
- 試験の準備方法-実用的なDatabricks-Certified-Professional-Data-Engineer英語版試験-信頼的なDatabricks-Certified-Professional-Data-Engineer勉強時間 🍎 ▛ www.goshiken.com ▟に移動し、▶ Databricks-Certified-Professional-Data-Engineer ◀を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer無料問題
- 試験の準備方法-実用的なDatabricks-Certified-Professional-Data-Engineer英語版試験-信頼的なDatabricks-Certified-Professional-Data-Engineer勉強時間 👶 最新▷ Databricks-Certified-Professional-Data-Engineer ◁問題集ファイルは▷ www.japancert.com ◁にて検索Databricks-Certified-Professional-Data-Engineerリンクグローバル
- Databricks-Certified-Professional-Data-Engineer PDF問題サンプル 🕢 Databricks-Certified-Professional-Data-Engineer日本語認定対策 📣 Databricks-Certified-Professional-Data-Engineer試験解説 🥙 サイト“ www.goshiken.com ”で⮆ Databricks-Certified-Professional-Data-Engineer ⮄問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer的中率
- Databricks-Certified-Professional-Data-Engineer試験対策書 👶 Databricks-Certified-Professional-Data-Engineer的中率 🥙 Databricks-Certified-Professional-Data-Engineer資格専門知識 🛑 ⏩ www.it-passports.com ⏪の無料ダウンロード( Databricks-Certified-Professional-Data-Engineer )ページが開きますDatabricks-Certified-Professional-Data-Engineer合格内容
- Databricks-Certified-Professional-Data-Engineer無料問題 🍏 Databricks-Certified-Professional-Data-Engineer模擬問題集 🖖 Databricks-Certified-Professional-Data-Engineer試験解説 🐍 《 www.goshiken.com 》にて限定無料の【 Databricks-Certified-Professional-Data-Engineer 】問題集をダウンロードせよDatabricks-Certified-Professional-Data-Engineer合格内容
- 高品質なDatabricks-Certified-Professional-Data-Engineer英語版 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer勉強時間 | 更新するDatabricks-Certified-Professional-Data-Engineer復習テキスト 🎒 Open Webサイト➽ jp.fast2test.com 🢪検索▛ Databricks-Certified-Professional-Data-Engineer ▟無料ダウンロードDatabricks-Certified-Professional-Data-Engineer日本語サンプル
- Databricks-Certified-Professional-Data-Engineer 試験勉強資料、Databricks-Certified-Professional-Data-Engineer 試験準備資料、Databricks Certified Professional Data Engineer Exam 試験内容 👭 { www.goshiken.com }に移動し、➽ Databricks-Certified-Professional-Data-Engineer 🢪を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Professional-Data-Engineer模試エンジン
- 効率的なDatabricks-Certified-Professional-Data-Engineer英語版 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer勉強時間 | 高品質なDatabricks-Certified-Professional-Data-Engineer復習テキスト 🆚 今すぐ( www.mogiexam.com )で《 Databricks-Certified-Professional-Data-Engineer 》を検索して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer模試エンジン
- Databricks-Certified-Professional-Data-Engineer学習指導 🦸 Databricks-Certified-Professional-Data-Engineer資格専門知識 🥍 Databricks-Certified-Professional-Data-Engineerリンクグローバル 🐵 《 www.goshiken.com 》サイトにて最新➠ Databricks-Certified-Professional-Data-Engineer 🠰問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer試験解説
- Databricks-Certified-Professional-Data-Engineer日本語サンプル 🆗 Databricks-Certified-Professional-Data-Engineer日本語認定対策 🕊 Databricks-Certified-Professional-Data-Engineer模擬試験問題集 📅 今すぐ➥ jp.fast2test.com 🡄で( Databricks-Certified-Professional-Data-Engineer )を検索して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer的中率
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、PassTest Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1XSC9val4ptWBjSm9gnBndQFV-BGDA9Th