VCEDumps is website that can take you access to the road of success. VCEDumps can provide the quickly passing Microsoft certification AI-500 exam training materials for you, which enable you to grasp the knowledge of the certification exam within a short period of time, and pass Microsoft Certification AI-500 Exam for only one-time.
| Section | Weight | Objectives |
|---|---|---|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
>> AI-500 Passing Score Feedback <<
The way to pass the AI-500 actual test is diverse. You can choose the one which is with high efficiency and less time and energy invested to get qualified by AI-500 certification. The AI-500 practice download pdf offered by VCEDumps can give you some reference. You just need to practice with AI-500 Vce Torrent for 1-2 days, then, you can be confident to face the AI-500 actual test with ease mood. The 99% pass rate of AI-500 training vce will ensure you 100% pass.
NEW QUESTION # 50
You have a Microsoft Foundry multi-agent solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. The retrieval agent uses a knowledge search tool.
Security testing reveals the following recurring issues:
* Some users submit jailbreak-style prompts at the start of a conversation.
* Some retrieved documents contain hidden instructions intended to manipulate the downstream agent The legal department at your company requires that final responses be flagged for review if they contain protected text. You need to configure guardrails to resolve the security issues and meet the legal requirements.
What should you configure?
Answer: B
Explanation:
The three risks occur at three different intervention points. Direct jailbreak attempts originate in the user prompt, so User input attacks should be evaluated at the User input boundary and blocked. Malicious instructions embedded in retrieved documents are indirect prompt-injection attacks and belong at the Tool response boundary before the retrieved content can influence downstream reasoning. Protected material in the final response must be flagged for legal review, not necessarily blocked, so an Output control using annotate- only behavior matches the requirement. Options A and B misplace at least one control or block content that the scenario says should only be flagged. Microsoft Foundry guardrails are explicitly designed around these intervention points, making C the configuration that aligns each risk with the stage where it can be detected and acted upon. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points
NEW QUESTION # 51
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.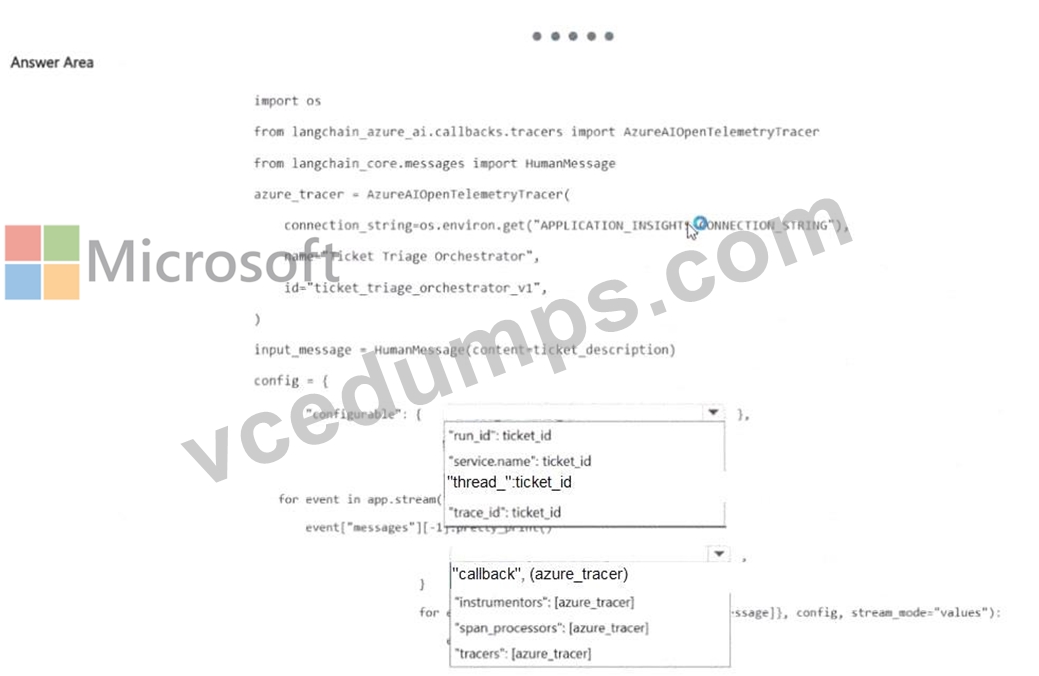
Answer:
Explanation: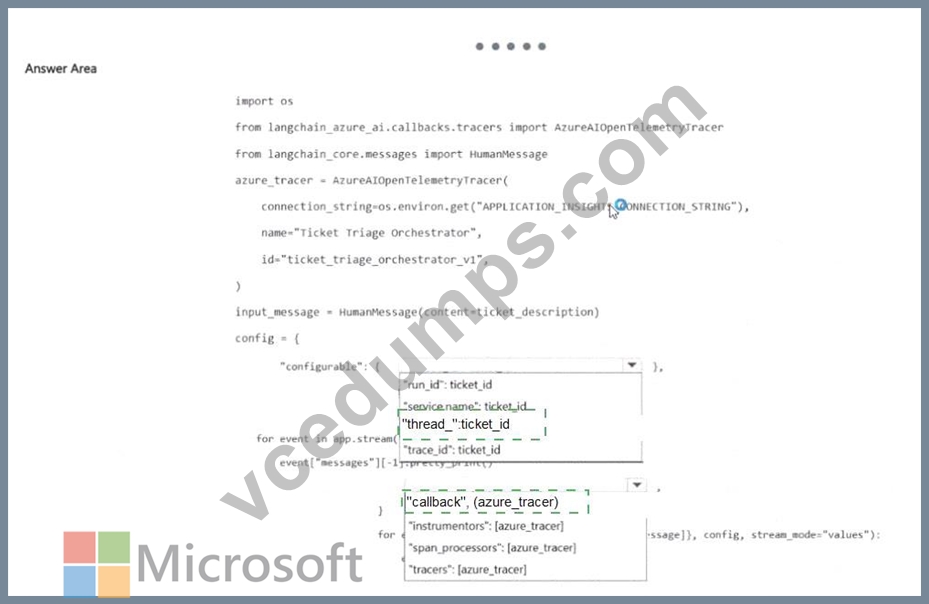
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents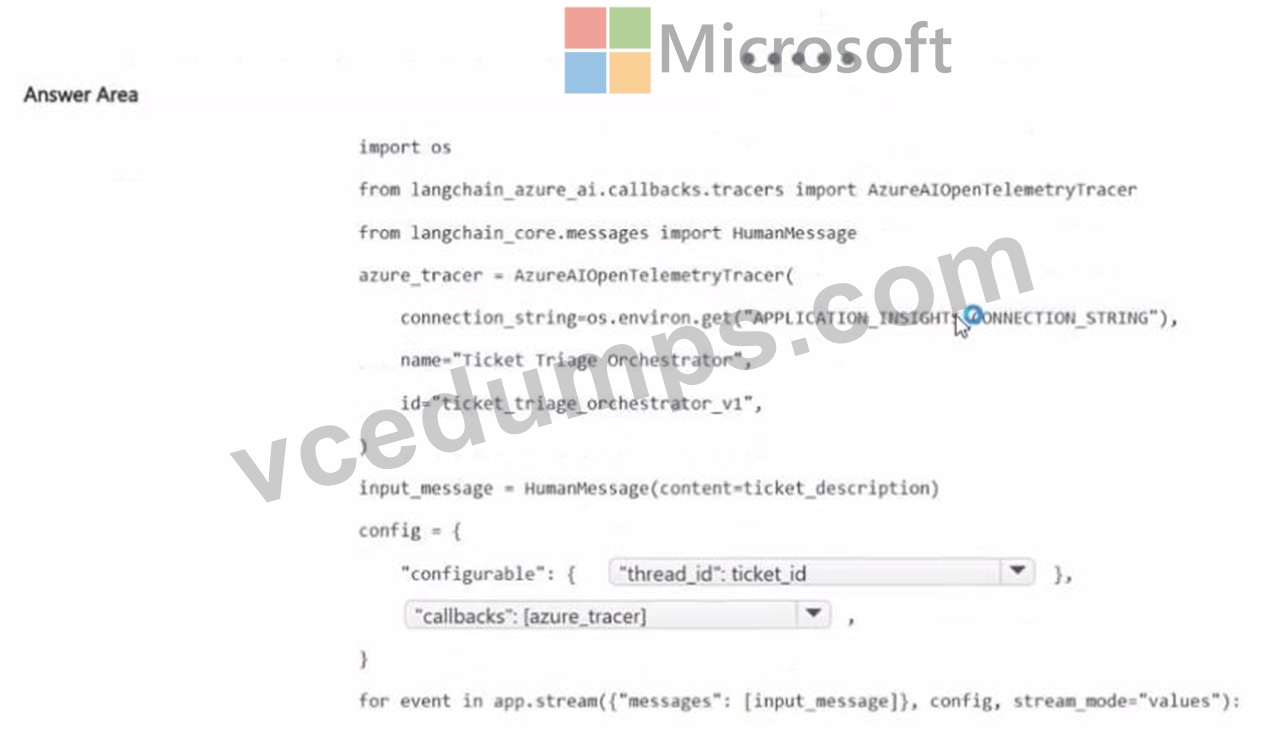
NEW QUESTION # 52
You have a Microsoft Foundry resource that hosts Azure OpenAI model deployments for three projects. Each project is for a different business unit. The projects share the same Foundry resource.
You need to implement a Microsoft Cost Management view that separates the shared model spend by the project The solution must meet the following requirements:
* Use cost data that can be reconciled by using Azure Cost Management.
* Minimize manual tagging.
What should you use?
Answer: C
Explanation:
When multiple projects share one Foundry resource, grouping costs only by Azure resource cannot distinguish project consumption because the resource boundary is shared. Microsoft Foundry integrates with Azure Cost Management by attributing model usage to project metadata/tags, allowing a Cost Analysis view to filter shared resource spending by project. This supports showback or chargeback without requiring administrators to manually tag every usage event. Subscription-level service filters or meter grouping identify the service or billing meter but not which of the three business-unit projects generated the usage. Therefore a Foundry-resource-scoped Cost Analysis view filtered by the project tag is the configuration that both reconciles to Azure Cost Management and minimizes manual tagging. D remains correct. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - Manage costs
NEW QUESTION # 53
You have a Microsoft Foundry multi-agent solution. The agents contain the CI/CD evaluation gates shown in the following table.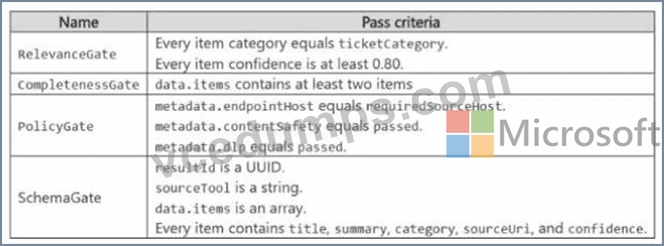
You call one of the agents by using the request context in the evaluation process as shown in the following table.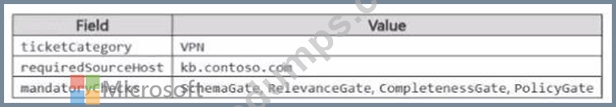
The agent receives the following results for the tool.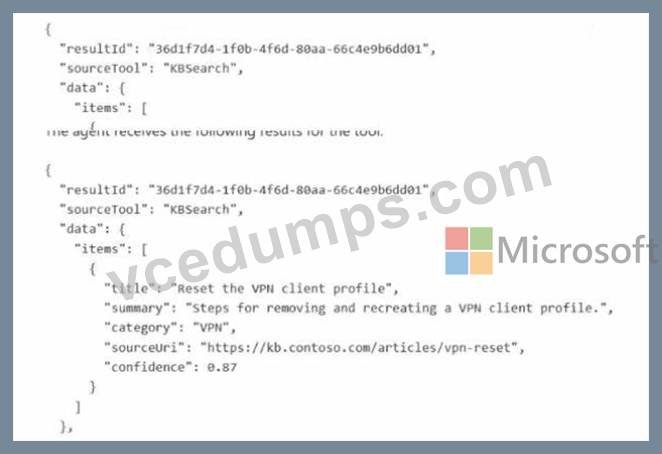
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.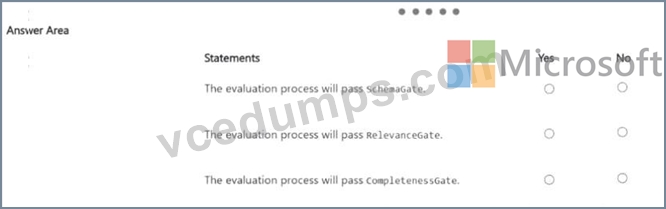
Answer:
Explanation: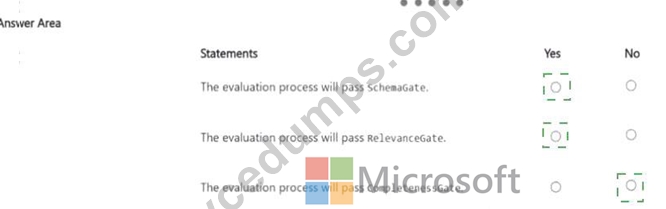
Explanation:
SchemaGate: Yes; RelevanceGate: Yes; CompletenessGate: No.
The supplied tool result satisfies the structural requirements of SchemaGate: it includes a valid-looking UUID result identifier, a string sourceTool value, an items array, and the required fields on the item. RelevanceGate also passes because the request category is VPN, the returned item category is VPN, and its confidence value of 0.87 is above the required 0.80 threshold. CompletenessGate fails because the rule requires at least two items while the response contains only one. This is a deterministic gate evaluation rather than an LLM-judge interpretation, so the values should be checked directly against the declared criteria. Microsoft Foundry evaluation datasets and CI/CD quality gates are designed to make exactly these regression checks repeatable before release. Therefore the correct sequence is Yes, Yes, No. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets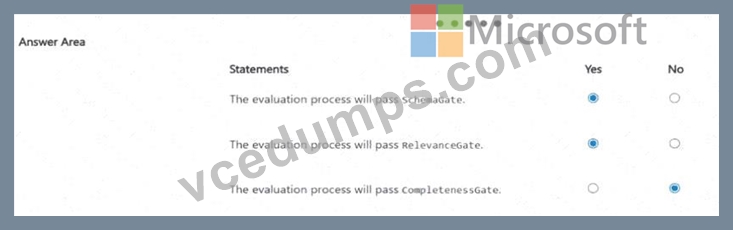
NEW QUESTION # 54
You have a Microsoft Agent Framework multi-agent workflow. The workflow includes a context provider that injects a condensed memory summary into each agent invocation. Requirements and acceptance criteria are stored in GitHub issues.
During a long-running workflow, the acceptance criteria changes. Later agents sometimes apply the earlier criteria. Token telemetry shows condensed summaries grow across handoffs. causing older content to be truncated.
You need to ensure that the later agents use the current requirements. The solution must limit context window growth.
What should you do?
Answer: A
Explanation:
GitHub issues are the authoritative source for current requirements, and those requirements can change while a long-running workflow is still executing. Each handoff should therefore reconstruct context from the current issue state and discard memory that has been invalidated by newer requirements. Keeping an accumulated summary allows obsolete criteria to remain present and also causes the prompt to grow until older content is truncated. Persisting the transcript in Cosmos DB preserves history but does not make that history current.
Giving subagents a GitHub lookup tool while continuing to inject the stale summary can expose the model to conflicting versions of the same requirement. Microsoft Agent Framework context providers are intended to inject current external context at invocation time, making C the approach that simultaneously preserves freshness and bounds context growth. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Context providers
NEW QUESTION # 55
......
Our AI-500 exam materials have helped many people improve their soft power. They are now more efficient than their colleagues, so they have received more attention from their leaders. We are all ordinary professional people. We must show our strength to show that we are worth the opportunity. Using AI-500 practice engine may be the most important step for you to improve your strength. You know, like the butterfly effect, one of your choices may affect your life. And our AI-500 Exam Questions will be the right exam tool for you to pass the AI-500 exam and obtain the dreaming certification.
Latest AI-500 Exam Fee: https://www.vcedumps.com/AI-500-examcollection.html