P.S. PDFExamDumps在Google Drive上分享了免費的、最新的Databricks-Certified-Professional-Data-Engineer考試題庫:https://drive.google.com/open?id=1rUpfMGgSOsZ-O1O4YRHjUsrHfOynR2Ih
Databricks Databricks-Certified-Professional-Data-Engineer 認證考試是一個檢驗IT專業知識的認證考試。PDFExamDumps是個能幫你快速通過Databricks Databricks-Certified-Professional-Data-Engineer 認證考試的網站,很多參加Databricks Databricks-Certified-Professional-Data-Engineer 認證考試的人花費大量的時間和精力,或者花錢報補習班,都是為了通過Databricks Databricks-Certified-Professional-Data-Engineer 認證考試。PDFExamDumps可以讓你不需要花費那麼多時間,金錢和精力,PDFExamDumps會為你提供針對性訓練來準備Databricks Databricks-Certified-Professional-Data-Engineer認證考試,僅需大約20個小時你就能通過考試。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 2: Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Topic 3: Ensuring Data Security and Compliance | 10% | - Access control and permissions - Compliance standards implementation - Data encryption and masking |
| Topic 4: Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
| Topic 5: Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs |
| Topic 6: Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Topic 7: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Data transformation and aggregation - Batch and incremental processing logic |
| Topic 8: Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Topic 9: Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Topic 10: Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Standardization and normalization - Handling missing or inconsistent data |
>> Databricks Databricks-Certified-Professional-Data-Engineer認證考試 <<
Databricks-Certified-Professional-Data-Engineer認證考試是現今很受歡迎的考試。還沒有取得這個考試的認證資的你,肯定也想參加這個考試了吧。確實,這是一個困難的考試,但是這也並不是說不能 取得高分輕鬆通過考試。那麼,還不知道通過考試的捷徑的你,想知道技巧嗎?我現在告訴你,那就是PDFExamDumps的Databricks-Certified-Professional-Data-Engineer考古題。
問題 #69
Which of the following python statements can be used to replace the schema name and table name in the query?
答案:C
解題說明:
Explanation
The answer is
1.table_name = "sales"
2.query = f"select * from {schema_name}.{table_name}"
It is always best to use f strings to replace python variables, rather than using string concatenation.
問題 #70
A data engineer is designing a data pipeline in Databricks that needs to process records from a Kafka stream where late-arriving data is common. Which approach should the data engineer use?
答案:C
解題說明:
Databricks and Apache Spark document watermarks as the standard mechanism for handling late-arriving data in Structured Streaming. A watermark defines how long the engine should continue waiting for out-of- order event-time data and helps manage state for aggregations, joins, and deduplication. ( Databricks Documentation ) This directly matches Kafka streaming scenarios where lateness is common. The other options are not the standard streaming solution for event-time late data: Auto CDC is for change data capture use cases, and repeated full historical reprocessing is inefficient and unnecessary when watermarking is the built-in feature designed for this problem. ( Databricks Documentation )
======
問題 #71
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.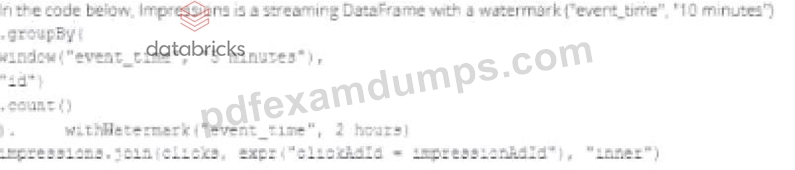
Which solution would improve the performance?




答案:B
解題說明:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
問題 #72
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales .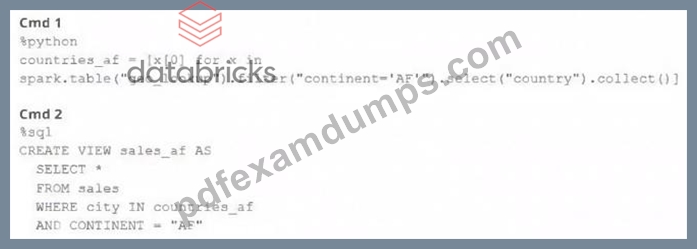
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
答案:C
解題說明:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified References: [Databricks Certified Data Engineer Professional], under
"Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
問題 #73
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
答案:D
解題說明:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned.
Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
Reference:
Delta Lake Documentation on Table Partitioning: Optimizing Layout with Partitioning
問題 #74
......
PDFExamDumps是唯一能供給你們需求的全部的Databricks Databricks-Certified-Professional-Data-Engineer 認證考試相關資料的網站。利用PDFExamDumps提供的資料通過Databricks Databricks-Certified-Professional-Data-Engineer 認證考試是不成問題的,而且你可以以很高的分數通過考試得到相關認證。
Databricks-Certified-Professional-Data-Engineer證照信息: https://www.pdfexamdumps.com/Databricks-Certified-Professional-Data-Engineer_valid-braindumps.html
2026 PDFExamDumps最新的Databricks-Certified-Professional-Data-Engineer PDF版考試題庫和Databricks-Certified-Professional-Data-Engineer考試問題和答案免費分享:https://drive.google.com/open?id=1rUpfMGgSOsZ-O1O4YRHjUsrHfOynR2Ih