Die Microsoft DP-750 Dumps von ExamFragen sind die Unterlagen, die von vielen Kadidaten geprüft sind. Und es kann die sehr hohe Durchlaufrate garantieren. Wenn Sie nach der Nutzung der Dumps bei der Microsoft DP-750 Zertifizierung durchgefallen sind, geben wir ExamFragen Ihnen voll Geld zurück. Oder können Sie auch die kostlosen aktualisierten Dumps bekommen. Mit der Garantie sorgen Sie sich bitte nicht.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
Sie haben einen großen Traum. Sie können viele Materialien zur Vorbereitung finden. Unsere Fragenkataloge zur Microsoft DP-750 Zertifizierungsprüfung können Ihren Traum verwirklichen. Die Fragen und Antworten zur Microsoft DP-750 Zertifizierungsprüfung von ExamFragen werden von den erfahrungsreichen IT-Fachleuten bearbeitet. Mit unseren Produkten können Sie alle Probleme versuchen. Wir würden Ihnen versprechen, dass die Kandidaten die realen Antworten 100% bekommen.
85. Frage
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.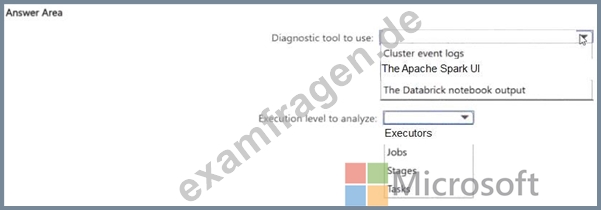
Antwort:
Begründung: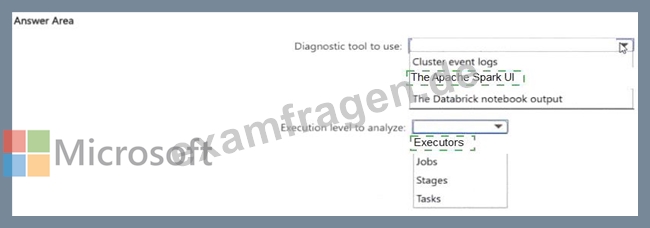
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
86. Frage
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.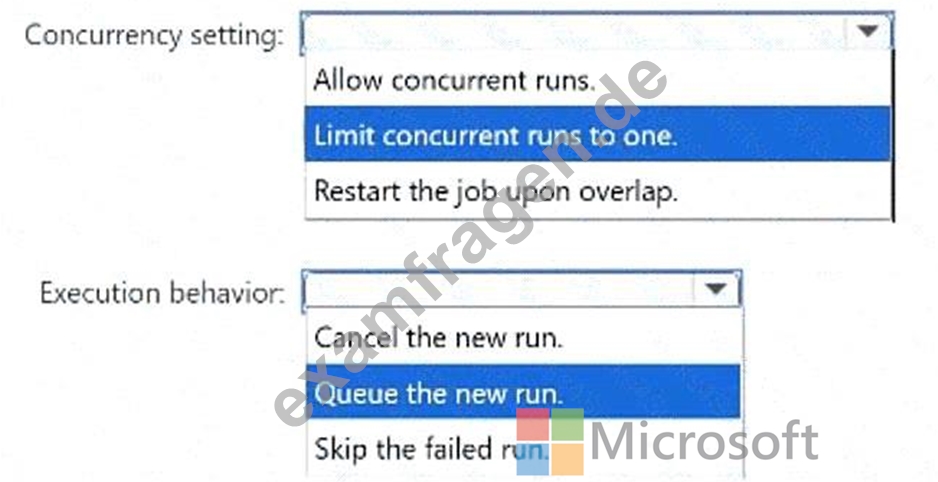
Antwort:
Begründung: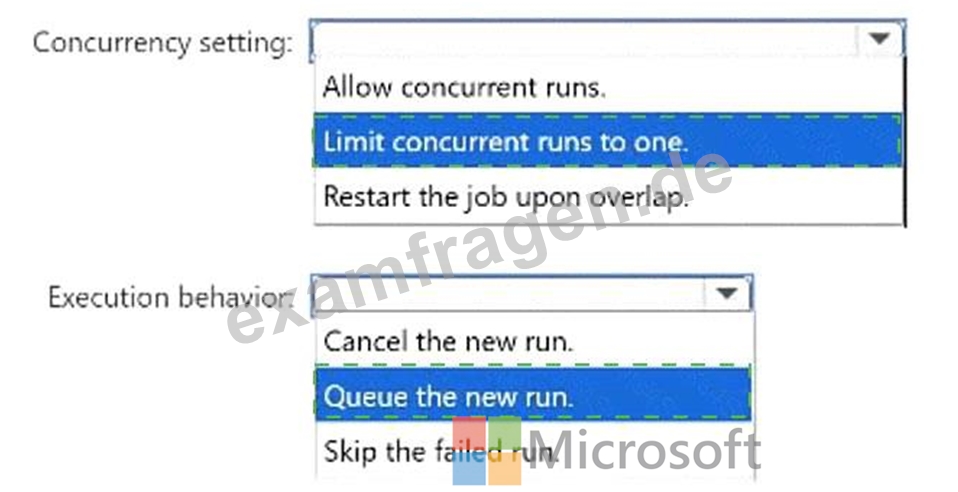
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
87. Frage
Drag and Drop Question
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1.
You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location. The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.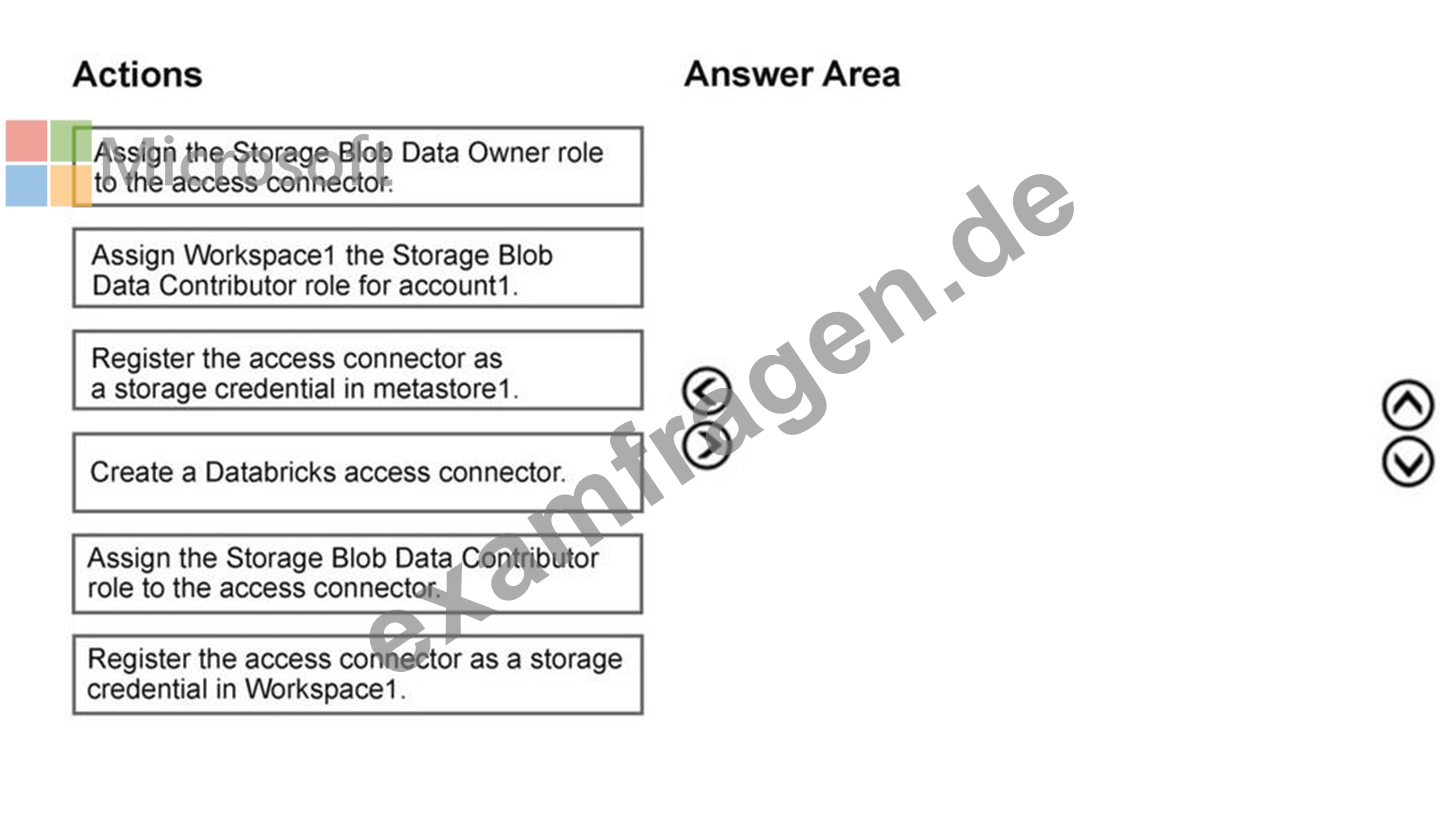
Antwort:
Begründung: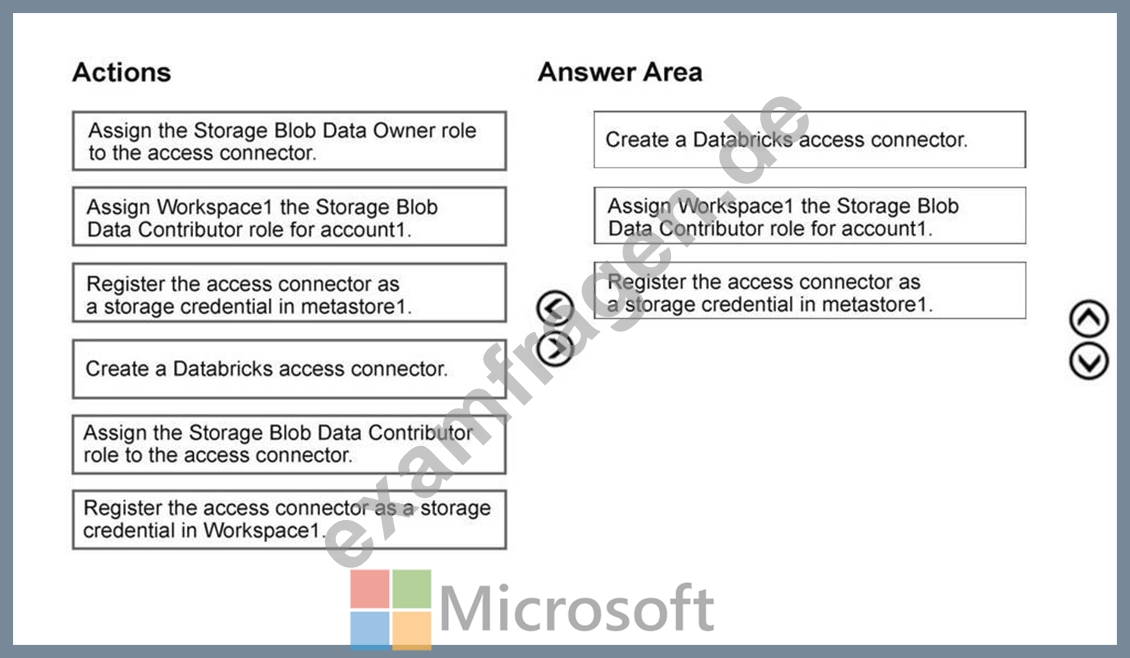
88. Frage
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it's accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it's processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that's data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
89. Frage
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.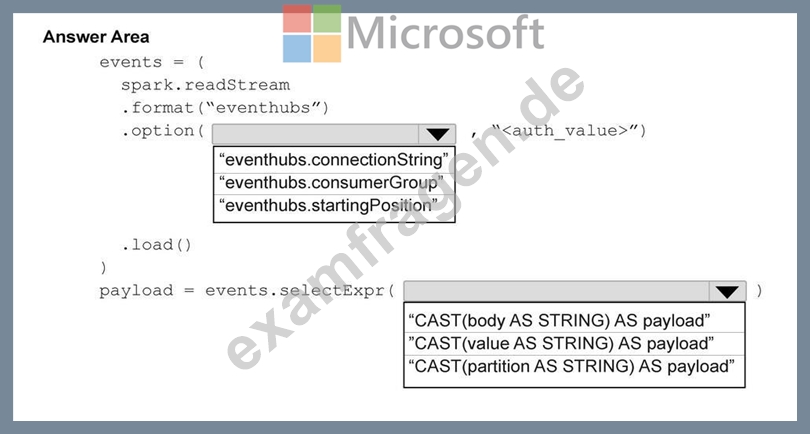
Antwort:
Begründung: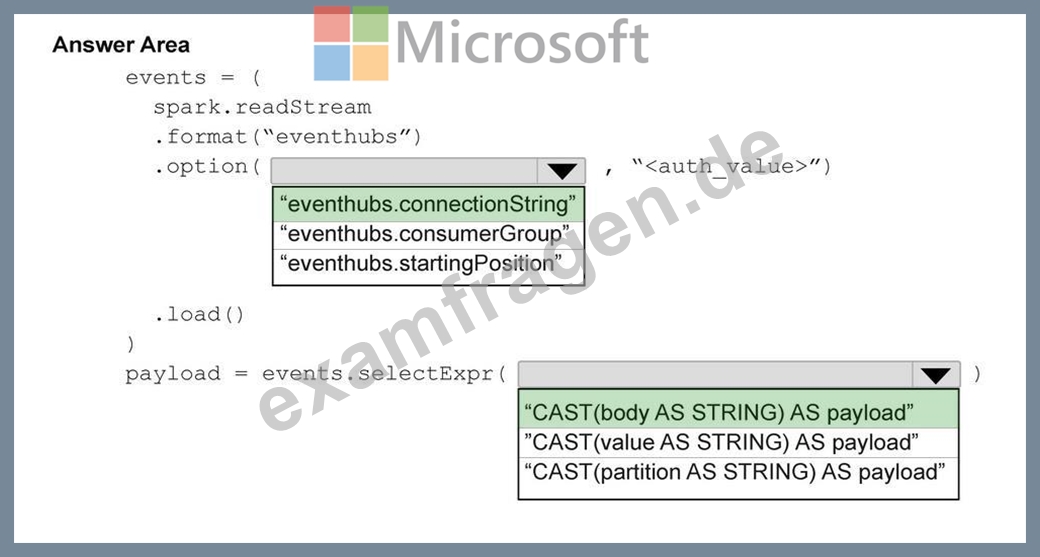
90. Frage
......
Die echten und originalen Prüfungsfragen und Antworten zu DP-750 Zertifizierung (Implementing Data Engineering Solutions Using Azure Databricks) bei ExamFragen wurden verfasst von unseren IT-Experten mit den Informationen von DP-750 Prüfungen (Implementing Data Engineering Solutions Using Azure Databricks) aus dem Testcenter wie PROMETRIC oder VUE.
DP-750 Prüfungsinformationen: https://www.examfragen.de/DP-750-pruefung-fragen.html