さらに、Japancert Databricks-Generative-AI-Engineer-Associateダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1dQWWiCJsIG3_qh7x2Oa0WC07_nZEs4qF
ここで説明したいのはJapancertにあるコアバリューです。全てのDatabricksのDatabricks-Generative-AI-Engineer-Associate「Databricks Certified Generative AI Engineer Associate」試験は非常に大切ですが、この情報技術が急速に発展している時代に、Japancertはただその中の一つだけです。ではなぜほとんどの人々はJapancertを選んだのですか。それはJapancertが提供する問題資料は絶対あなたが試験に受かることを助けられるからです。Japancertが提供する資料は最新のトレーニングツールが常にアップデートして認証試験の目標を変換するの結果です。Japancert はあなたに最新の試験研究資料を提供しますから、Japancert DatabricksのDatabricks-Generative-AI-Engineer-Associate問題集を持っていたら、試験に直面する自信に満ちることができ、合格しないなんて全然心配することはなく気楽に試験に受かることができます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
>> Databricks-Generative-AI-Engineer-Associate日本語版テキスト内容 <<
DatabricksのDatabricks-Generative-AI-Engineer-Associate試験の合格書は君の仕事の上で更に一歩の昇進と生活条件の向上を助けられて、大きな財産に相当します。DatabricksのDatabricks-Generative-AI-Engineer-Associate認定試験はIT専門知識のレベルの考察として、とっても重要な地位になりつつます。Japancertは最も正確なDatabricksのDatabricks-Generative-AI-Engineer-Associate試験資料を追求しています。
質問 # 47
A Generative AI Engineer is creating an LLM-powered application that will need access to up-to-date news articles and stock prices.
The design requires the use of stock prices which are stored in Delta tables and finding the latest relevant news articles by searching the internet.
How should the Generative AI Engineer architect their LLM system?
正解:A
解説:
To build an LLM-powered system that accesses up-to-date news articles and stock prices, the best approach is tocreate an agentthat has access to specific tools (option D).
* Agent with SQL and Web Search Capabilities:By using an agent-based architecture, the LLM can interact with external tools. The agent can query Delta tables (for up-to-date stock prices) via SQL and perform web searches to retrieve the latest news articles. This modular approach ensures the system can access both structured (stock prices) and unstructured (news) data sources dynamically.
* Why This Approach Works:
* SQL Queries for Stock Prices: Delta tables store stock prices, which the agent can query directly for the latest data.
* Web Search for News: For news articles, the agent can generate search queries and retrieve the most relevant and recent articles, then pass them to the LLM for processing.
* Why Other Options Are Less Suitable:
* A (Summarizing News for Stock Prices): This convoluted approach would not ensure accuracy when retrieving stock prices, which are already structured and stored in Delta tables.
* B (Stock Price Volatility Queries): While this could retrieve relevant information, it doesn't address how to obtain the most up-to-date news articles.
* C (Vector Store): Storing news articles and stock prices in a vector store might not capture the real-time nature of stock data and news updates, as it relies on pre-existing data rather than dynamic querying.
Thus, using an agent with access to both SQL for querying stock prices and web search for retrieving news articles is the best approach for ensuring up-to-date and accurate responses.
質問 # 48
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = { " prompt_template " : " You are a trivia bot. Generate a question based on the user ' s input:
{user_input} " , " input_vars " : [ " user_input " ], " parameters " : { " temperature " : 0.01, " max_tokens " :
500}}
Which error is causing the problem?
正解:B
解説:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the " input_vars " or " input_variables " must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly " inject " the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user ' s actual question. This results in the model failing to provide relevant information because it essentially doesn ' t know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
質問 # 49
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user's query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
正解:A、B
解説:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here's why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
Define an evaluation metric: Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user's query and the expected response.
Recall measures the proportion of relevant information retrieved.
NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
Experiment with chunking strategies: Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user's query than others.
Evaluate performance: By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
Use the LLM as an evaluator: After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a "judge" function, where the LLM compares how well a given chunk answers previous user queries.
Optimize based on the LLM's judgment: By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
This metric could be a qualitative judgment on how closely the retrieved information matches the user's intent.
Tune chunking parameters: Based on the LLM's judgment, the engineer can adjust the chunk size or structure to better align with the LLM's responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
質問 # 50
A company has a typical RAG-enabled, customer-facing chatbot on its website.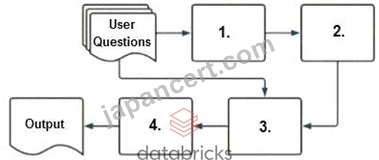
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
正解:C
解説:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
質問 # 51
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
正解:A
解説:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
質問 # 52
......
Japancert はDatabricks業界に認定試験大綱の主要なサプライヤーとして、Databricks-Generative-AI-Engineer-Associate専門家は一緻して品質の高い商品を開発し続けています。
Databricks-Generative-AI-Engineer-Associate対応内容: https://www.japancert.com/Databricks-Generative-AI-Engineer-Associate.html
さらに、Japancert Databricks-Generative-AI-Engineer-Associateダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1dQWWiCJsIG3_qh7x2Oa0WC07_nZEs4qF