2026 Latest ActualVCE Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1ketbzeh8EitX0-T0GBjhECNSjQ-YRJwk
If you buy our Databricks-Generative-AI-Engineer-Associate study materials, then you can enjoy free updates for one year. After you start learning, I hope you can set a fixed time to check emails. If the content of the Databricks-Generative-AI-Engineer-Associate practice guide or system is updated, we will send updated information to your e-mail address. Of course, you can also consult our e-mail on the status of the product updates. I hope we can work together to make you better use our Databricks-Generative-AI-Engineer-Associate simulating exam.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Exam Price: | $200 USD |
| Passing Score: | Scaled Score (approx. 70%) |
| Available Languages: | English, Japanese, Korean, Portuguese (Brazil) |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 90 minutes |
| Real Exam Qty: | 45 |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Format: | Multiple Choice, Multiple Select |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks Databricks-Generative-AI-Engineer-Associate Reliable Dumps Pdf <<
If only you provide the scanning copy of the Databricks-Generative-AI-Engineer-Associate failure marks we will refund you immediately. If you have any doubts about the refund or there are any problems happening in the process of refund you can contact us by mails or contact our online customer service personnel and we will reply and solve your doubts or questions timely. We provide the best service and Databricks-Generative-AI-Engineer-Associate Test Torrent to you to make you pass the exam fluently but if you fail in we will refund you in full and we won’t let your money and time be wasted. Our questions and answers are based on the real exam and conform to the popular trend in the industry.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 33
A Generative Al Engineer is helping a cinema extend its website's chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.
Which option will do this with the least effort and in the most performant way?
Answer: C
Explanation:
The task is to extend a cinema chatbot to provide movie showtime information using a RAG application, leveraging user location and a continuously updated Delta table, with minimal effort and high performance.
Let's evaluate the options.
* Option A: Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation
* Databricks Feature Serving provides low-latency access to real-time data from Delta tables via an online store. Syncing the Delta table to a Feature Serving Endpoint allows the chatbot to query showtimes efficiently, integrating seamlessly into the RAG agent'stool logic. This leverages Databricks' native infrastructure, minimizing effort and ensuring performance.
* Databricks Reference:"Feature Serving Endpoints provide real-time access to Delta table data with low latency, ideal for production systems"("Databricks Feature Engineering Guide," 2023).
* Option B: Query the Delta table directly via a SQL query constructed from the user's input using a text-to-SQL LLM in the agent logic / tool
* Using a text-to-SQL LLM to generate queries adds complexity (e.g., ensuring accurate SQL generation) and latency (LLM inference + SQL execution). While feasible, it's less performant and requires more effort than a pre-built serving solution.
* Databricks Reference:"Direct SQL queries are flexible but may introduce overhead in real-time applications"("Building LLM Applications with Databricks").
* Option C: Write the Delta table contents to a text column, then embed those texts using an embedding model and store these in the vector index. Look up the information based on the embedding as part of the agent logic / tool implementation
* Converting structured Delta table data (e.g., showtimes) into text, embedding it, and using vector search is inefficient for structured lookups. It's effort-intensive (preprocessing, embedding) and less precise than direct queries, undermining performance.
* Databricks Reference:"Vector search excels for unstructured data, not structured tabular lookups"("Databricks Vector Search Documentation").
* Option D: Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation
* Exporting to an external database (e.g., MySQL) adds setup effort (workflow, external DB management) and latency (periodic updates vs. real-time). It's less performant and more complex than using Databricks' native tools.
* Databricks Reference:"Avoid external systems when Delta tables provide real-time data natively"("Databricks Workflows Guide").
Conclusion: Option A minimizes effort by using Databricks Feature Serving for real-time, low-latency access to the Delta table, ensuring high performance in a production-ready RAG chatbot.
NEW QUESTION # 34
A Generative AI Engineer needs to allocate costs for an agent deployed via Agent Framework behind AI Gateway. The finance team requires daily reporting by workspace and endpoint, including token usage and request counts. The engineer wants to query this data with SQL and join it to an internal cost-center mapping table.
Which table type best serves their needs?
Answer: A
Explanation:
The AI Gateway usage table is designed to capture operational consumption information for SQL-based reporting. Its records include identifiers for the workspace, endpoint, and request, together with token-usage information and timestamps. The engineer can aggregate consumption by day and endpoint, then join those results to the company's cost-center mapping. Request counting should respect the table's request and invocation identifiers because a single logical request can involve multiple inference calls. Served-entity metadata describes deployed entities rather than providing the primary consumption records. Inference tables emphasize request and response payloads, while MLflow runs organize experiments and evaluations. Token consumption supports cost allocation, but calculating actual monetary charges may additionally require applicable pricing or billing records. Databricks documentation
NEW QUESTION # 35
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: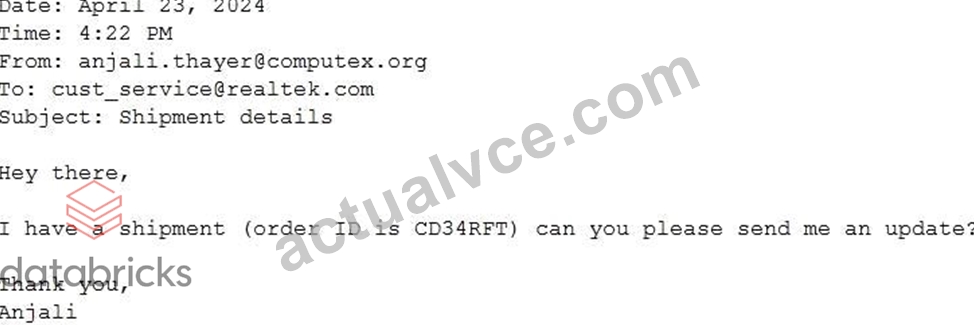
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: C
Explanation:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 36
A Generative AI Engineer is using LangGraph to define multiple tools in a single agentic application. They want to enable the main orchestrator LLM to decide on its own which tools are most appropriate to call for a given prompt. To do this, they must determine the general flow of the code. Which sequence will do this?
Answer: D
Explanation:
In modern agentic frameworks like LangGraph or LangChain, the standard workflow for creating an autonomous tool-calling agent follows a specific sequence. First, tools must be defined (often as Python functions with clear docstrings, which the LLM uses to understand the tool's purpose). Second, the agent logic is defined, which specifies how the LLM should think. Third, the agent is initialized using a logic pattern like ReAct (Reason + Act). The ReAct framework is essential here because it enables the "orchestrator" loop: the LLM receives a prompt, generates a "Thought" about which tool to use, generates an "Action" to call that tool, receives an "Observation" (the tool's output), and repeats until it can provide a final answer. Loading tools into "separate agents" (C) or defining tools "inside" agents (D) are non-standard patterns that add unnecessary complexity and do not align with the centralized orchestration model required for LangGraph.
NEW QUESTION # 37
An AI developer team wants to fine-tune an open-weight model to have exceptional performance on a code generation use case. They are trying to choose the best model to start with. They want to minimize model hosting costs and are using Hugging Face model cards and spaces to explore models. Which TWO model attributes and metrics should the team focus on to make their selection?
Answer: B,D
Explanation:
To optimize for code generation performance and hosting costs , a Generative AI engineer must look at specific metrics.
* Big Code Models Leaderboard (A): This is the industry-standard benchmark for code-specific LLMs (like StarCoder or CodeLlama). It measures performance on tasks like HumanEval and MBPP, providing a direct indicator of how well the model handles programming logic.
* Number of model parameters (B): This is the primary driver of hosting costs. Larger models (e.g.,
70B) require more GPU memory (VRAM) and more expensive compute instances (like A100s/H100s) than smaller models (e.g., 7B or 13B). To minimize costs, the team should look for the smallest model that achieves a high score on the Big Code Leaderboard.
Note: MTEB (C) is for embeddings, and Chatbot Arena (D) is for general-purpose chat, neither of which is the primary metric for specialized code generation fine-tuning.
NEW QUESTION # 38
......
Databricks-Generative-AI-Engineer-Associate Latest Exam Book: https://www.actualvce.com/Databricks/Databricks-Generative-AI-Engineer-Associate-valid-vce-dumps.html
DOWNLOAD the newest ActualVCE Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ketbzeh8EitX0-T0GBjhECNSjQ-YRJwk