Free PDF SPS-C01 - Marvelous Snowflake Certified SnowPro Specialty - Snowpark Reliable Source

DOWNLOAD the newest Easy4Engine SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=17GAZ-1r4f1Rt8HIlDmurTHO2o48WSf95
Profit from the opportunity to get these top-notch exam questions for the Snowflake SPS-C01 certification test. We guarantee you that our top-rated Snowflake SPS-C01 practice exam (PDF, desktop practice test software, and web-based practice exam) will enable you to pass the Snowflake SPS-C01 Certification Exam on the very first go.
| Section | Weight | Objectives |
|---|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
- 1. Lazy evaluation and DAG execution
- 2. Transformations vs actions
- 3. Client-side vs server-side processing
- Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
|
| Performance and Best Practices | 10% | - Security and governance
- 1. Data protection and compliance
- 2. Access control and permissions
- Optimization techniques
- 1. Query pushdown and execution plans
- 2. Caching and warehouse sizing
- 3. Minimizing data movement
|
| Snowpark API and Development | 30% | - Python API fundamentals
- 1. Column operations and functions
- 2. DataFrame creation from tables, views, SQL
- 3. Data persistence and writing results
- Multi-language support
- 1. Environment setup and dependencies
- 2. Java and Scala API basics
|
| Data Transformations and Operations | 35% | - Advanced operations
- 1. Pivot and unpivot transformations
- 2. Semi-structured data processing
- 3. Window functions and analytics
- User-defined logic
- 1. Stored procedures with Snowpark
- 2. UDFs, UDAFs, UDTFs
- DataFrame manipulation
- 1. Filtering, sorting, grouping, aggregation
- 2. Selection, projection, renaming, casting
- 3. Joins, unions, set operations
|
>> SPS-C01 Reliable Source <<
Dump Snowflake SPS-C01 Check | SPS-C01 Trustworthy Dumps
The Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test questions are customizable which means that the customers can customize the time and SPS-C01 exam questions types according to their needs. These Snowflake SPS-C01 Practice Tests are based on real based examination scenarios which help the students practice under real SPS-C01 exam questions pressure and learn to control it.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q208-Q213):
NEW QUESTION # 208
Consider the following Snowpark Python code snippet designed to calculate a custom metric on financial data, using a vectorized UDF for performance. Identify potential performance bottlenecks and recommend optimization strategies.
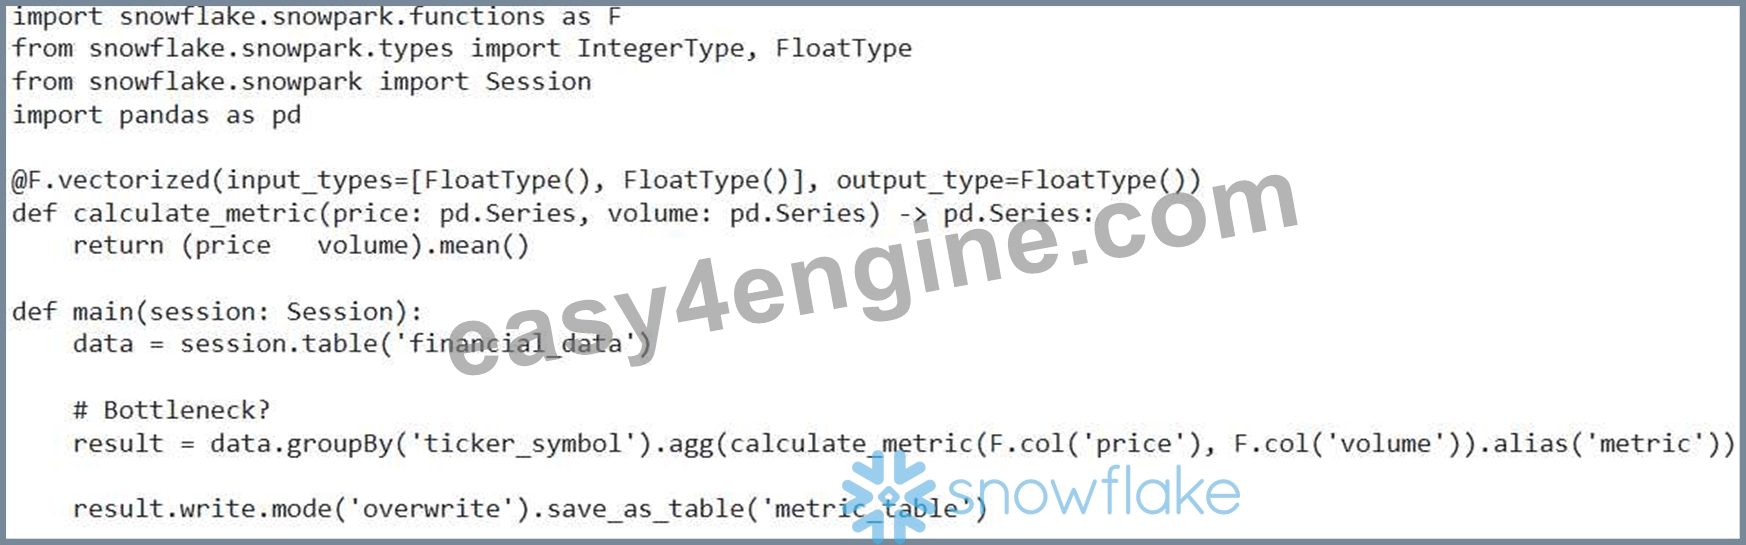
Which of the following actions (may be more than one) would MOST likely improve the performance of this Snowpark application?
- A. Repartition the 'data' DataFrame by 'ticker_symbol' before the 'groupBy' operation using to improve data locality.
- B. Use to explicitly declare the Pandas dependency.
- C. Ensure that the 'financial_data' table is clustered by 'ticker_symbor to optimize the 'groupBy' operation.
- D. Change 'FloatType' to 'DoubleType' as it provides more precision.
- E. Use before writing to the 'metric_table' , especially if the table is subsequently used downstream.
Answer: A,C,E
Explanation:
Clustering by 'ticker_symbol' significantly optimizes the 'groupBy' operation by organizing data physically for efficient retrieval. Caching the result before writing to a table is crucial if the intermediate result 'result' will be used multiple times, avoiding redundant computations. Repartitioning by 'ticker_symbol' before grouping helps distribute data evenly, improving parallelism and locality. While Pandas is generally available, explicitly declaring it might be necessary in certain isolated environments, so B can be considered a good practice, but not as impactful. Changing FloatType to DoubleType (C) will not lead to performnace improvement. It only changes precision level which is not required here.
NEW QUESTION # 209
You are working with Snowpark and need to persist the results of a DataFrame 'df to a Snowflake stage named 'my_stage'. You want to achieve the following: 1. Write the data in JSON format. 2. Use snappy compression. 3. Handle potential write errors gracefully. 4. Overwrite any existing files with the same name. Which of the following approaches can achieve these requirements? (Select all that apply)
- A. Use compression='snappy', mode='overwrite')' and handle potential exceptions using a 'try-except' block.
- B. Define a UDF to write the dataframe into stage along with exception handling logic.
- C. Configure the stage 'my_stage' with FILE_FORMAT = (TYPE = 'JSON', COMPRESSION = 'SNAPPY') and then use within a 'try-except' block.
- D. Wrap the entire write operation in a try-except block and implement retry logic with exponential backoff in case of transient errors.
- E. Use 'df.write.option('compression', inside a 'try-except block.
Answer: A,D,E
Explanation:
Option A directly utilizes the .json(V method for writing JSON files with snappy compression, specifying the 'overwrite' mode, and the 'try-except block adds error handling. Option C specifies the format to JSON using format('json') with snappy compression and specifying the 'overwrite' mode, and using a 'try-except' block for error handling. Option E deals with write errors by wrapping the entire process inside try-except block. Options D is not correct since creating a UDF just for this purpose introduces unnecessary overhead compared to the simple and direct approaches provided by A and C. Option B is incorrect, while configuring the stage with a default file format is useful, it won't apply in this specific write operation using DataFrameWriter. We need to explicitly define format and compression for the operation.
NEW QUESTION # 210
Consider the following Snowpark Python code snippet designed to aggregate sales data by region:
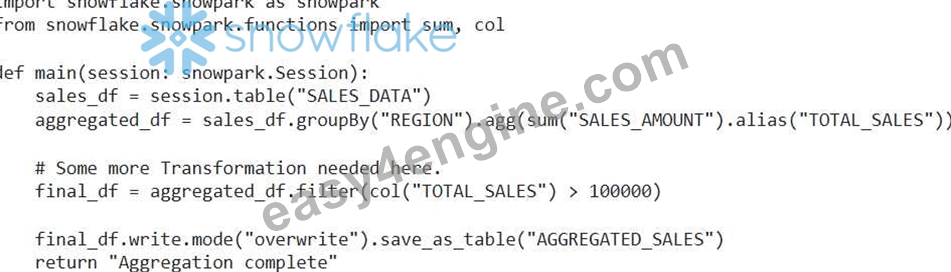
During testing, you observe that the performance of this code is suboptimal, especially when dealing with very large 'SALES DATA tables. Using Snowflake's query history, you notice that a significant amount of time is spent on data shuffling during the operation. What optimization strategies could you employ within this Snowpark code to minimize data shuffling and improve the overall performance?
- A. Apply a more selective 'filter operation to the 'sales_df' DataFrame before the 'groupBy' operation, reducing the amount of data that needs to be shuffled.
- B. store 'SALES_DATX as a clustered table using the 'REGION' column.
- C. Repartition the 'sales_df DataFrame using 'repartitionBy' before the 'groupBy' operation, specifying the 'REGION' column to ensure that data for each region is co-located on the same node.
- D. Utilize the 'hint' function in Snowpark to provide a join hint that suggests a specific join strategy to the Snowflake query optimizer.
- E. Increase the warehouse size to provide more resources for data processing, which will inherently reduce data shuffling.
Answer: A,B,C
Explanation:
Filtering early reduces data shuffling by reducing the volume of data that needs to be grouped. Repartitioning ensures that rows with the same region are on the same node before the group by which reduces shuffling significantly. Creating the source SALES_DATA table as a clustered table with REGION as the clustering key colocates the data for each region in the same micropartitions, reducing shuffling. Increasing warehouse size will help overall performance but will not directly reduce shuffling. Hints apply to Joins, not group by operations.
NEW QUESTION # 211
You have a Snowpark Python stored procedure named 'calculate_stats' that takes a table name as input and returns summary statistics. You need to modify the stored procedure to add a new optional parameter for specifying a filter condition. Which of the following SQL commands, used in conjunction with the Snowpark API for Python, is the MOST efficient way to alter the existing stored procedure without dropping and recreating it?
Answer: B
Explanation:
'CREATE OR REPLACE PROCEDURE is the standard and efficient way to modify stored procedures in Snowflake, including adding optional parameters. It avoids dropping and recreating the procedure, preserving grants and dependencies. Option B accurately defines a new procedure definition that incorporates both input parameters and sets a default NULL value for the filter condition which makes it optional. Other Options not efficient , Option A, drops old and creates new SP. Options C & D are invalid SQL Syntax, and E makes the FILTER_CONDITION mandatory.
NEW QUESTION # 212
A data engineering team wants to create a Snowpark stored procedure that takes a VARIANT column from a Snowflake table, parses a specific JSON element within each row, and returns a new DataFrame with the extracted data as a STRING column. The JSON structure is consistent across all rows. What is the MOST efficient and type-safe way to implement this, considering the need for performance and maintainability?
- A. Use Python type hints for the input VARIANT column, extract the JSON element using string manipulation within the stored procedure, and return a DataFrame with the extracted data as a string.
- B. Use Snowpark's 'get' function within the stored procedure to extract the JSON element, explicitly cast the extracted value to STRING using 'cast('string')' , and register the stored procedure with defining the output schema.
- C. Use the 'get' function on the VARIANT column to extract the JSON element, use the 'as_varchar' function to cast the VARIANT value to a String value, and register the stored procedure with explicit 'return_type' and schema definition for enhanced type safety
- D. Define the input column using and use the operator to implicitly convert the extracted JSON element to a string, relying on Snowpark's type inference for the return type.
- E. Define the input column as a generic 'object' type in Python, use Snowpark's 'get function with path navigation to extract the JSON element, and return the extracted data as a string using 'as_varchar'.
Answer: C
Explanation:
The most efficient and type-safe approach is Option E. Using 'get' function on the VARIANT column to extract the JSON element, use the 'as_varchar' function to cast the VARIANT value to a String value, and register the stored procedure with explicit 'return_type' and schema definition for enhanced type safety. Snowpark's 'get' function provides optimized JSON parsing capabilities. Explicit casting using 'as_varchar' ensures that the extracted data is properly converted to a string. Registering the stored procedure with and a schema definition enforces data type safety at the interface level, preventing potential runtime errors and improving maintainability. Options A and D are less efficient or may lead to runtime errors. Option B is less explicit and more error prone.
NEW QUESTION # 213
......
The design of our SPS-C01 guide training is ingenious and delicate. Every detail is perfect. For example, if you choose to study our SPS-C01 learning materials on our windows software, you will find the interface our SPS-C01 earning materials are concise and beautiful, so it can allow you to study SPS-C01 Exam Questions in a concise and undisturbed environment. In addition, you will find a lot of small buttons, which can give you a lot of help. If you are satisfied with our SPS-C01 exam questions, you can make a choice to purchase them.
Dump SPS-C01 Check: https://www.easy4engine.com/SPS-C01-test-engine.html
- Top SPS-C01 Dumps 😵 SPS-C01 Exam Score 🛣 SPS-C01 Valid Test Online 🚨 Simply search for ⮆ SPS-C01 ⮄ for free download on ➤ www.troytecdumps.com ⮘ ⤴SPS-C01 Certification Cost
- SPS-C01 Valid Test Review 🏐 SPS-C01 Latest Exam Price 🔤 SPS-C01 Interactive Course 🤡 Open website ➠ www.pdfvce.com 🠰 and search for ☀ SPS-C01 ️☀️ for free download 👏SPS-C01 Valid Test Online
- Practical SPS-C01 Reliable Source - Perfect Dump SPS-C01 Check - High-quality Snowflake Snowflake Certified SnowPro Specialty - Snowpark 😇 Search on ➡ www.easy4engine.com ️⬅️ for ⮆ SPS-C01 ⮄ to obtain exam materials for free download 🙁SPS-C01 Latest Real Exam
- SPS-C01 Latest Exam Price 🖊 SPS-C01 Latest Exam Price ♥ Reliable SPS-C01 Test Tutorial ⬆ Search for ⮆ SPS-C01 ⮄ and download it for free on 《 www.pdfvce.com 》 website 🦳SPS-C01 PDF Download
- Get 1 year Of Updated Snowflake SPS-C01 Exam Question Dumps 🥎 Easily obtain ✔ SPS-C01 ️✔️ for free download through ▷ www.easy4engine.com ◁ ⚗New SPS-C01 Dumps Free
- SPS-C01 Free Learning Cram 🐆 SPS-C01 Free Learning Cram 🎊 SPS-C01 Exam Collection 🤟 Open ➠ www.pdfvce.com 🠰 enter ➤ SPS-C01 ⮘ and obtain a free download 🕯Reliable SPS-C01 Test Tutorial
- Quiz 2026 Snowflake SPS-C01: The Best Snowflake Certified SnowPro Specialty - Snowpark Reliable Source ↩ The page for free download of ⏩ SPS-C01 ⏪ on ( www.troytecdumps.com ) will open immediately ⏰SPS-C01 Interactive Course
- SPS-C01 Exam Score 📽 SPS-C01 Pdf Format ⌛ SPS-C01 Valid Test Online 🤾 Download ( SPS-C01 ) for free by simply searching on ➡ www.pdfvce.com ️⬅️ 🔑SPS-C01 Valid Test Review
- Valid SPS-C01 Test Papers 🥈 SPS-C01 Pdf Format 😿 Study SPS-C01 Materials 👹 Copy URL ➡ www.prepawayete.com ️⬅️ open and search for ➥ SPS-C01 🡄 to download for free 🦖Study SPS-C01 Materials
- SPS-C01 Pdf Format ➖ SPS-C01 Latest Exam Price 🧭 SPS-C01 Free Learning Cram ❤ Copy URL ( www.pdfvce.com ) open and search for 《 SPS-C01 》 to download for free 🐘SPS-C01 Reliable Test Bootcamp
- Excellent SPS-C01 Reliable Source - Pass SPS-C01 Exam 🥊 Open ▶ www.dumpsmaterials.com ◀ enter 「 SPS-C01 」 and obtain a free download 🍉SPS-C01 Latest Exam Price
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.flirtic.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.4shared.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, rare-books.library.sites.carleton.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest Easy4Engine SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=17GAZ-1r4f1Rt8HIlDmurTHO2o48WSf95




