真實的Databricks-Certified-Data-Engineer-Associate證照&保證Databricks Databricks-Certified-Data-Engineer-Associate考試成功與頂級的Databricks-Certified-Data-Engineer-Associate真題

BONUS!!! 免費下載KaoGuTi Databricks-Certified-Data-Engineer-Associate考試題庫的完整版:https://drive.google.com/open?id=1X1X9JcpyrJI-Lvxq2DIEJOCKvZrbnwVn
你是IT人士嗎?你想成功嗎?如果你想成功你就購買我們KaoGuTi Databricks的Databricks-Certified-Data-Engineer-Associate考試認證培訓資料吧,我們的培訓資料是通過實踐檢驗了的,它可以幫助你順利通過IT認證,有了KaoGuTi Databricks的Databricks-Certified-Data-Engineer-Associate考試認證培訓資料你在IT行業的將有更好的發展,可以享受高級白領的待遇,可以在國際上闖出一片天地,擁有高端的技術水準,你還在擔心什麼,KaoGuTi Databricks的Databricks-Certified-Data-Engineer-Associate考試認證培訓資料將會滿足你這一欲望,我們與你同甘共苦,一起接受這挑戰。
Databricks Databricks-Certified-Data-Engineer-Associate Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Processing & Transformations | 31% | - Query optimization and performance
- 1. Understanding query plans
- 2. Optimization strategies
- Data transformation techniques
- 1. Aggregations, joins, and window functions
- 2. DataFrame operations and transformations
- 3. Complex data processing logic
|
| Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
- 1. Workspace navigation and management
- 2. Data layout and optimization: partitioning, file sizing, caching
- 3. Compute options: clusters, SQL warehouses, serverless
|
| Data Governance & Quality | 11% | - Data quality and reliability
- 1. Data validation and quality checks
- 2. Schema enforcement and evolution
- Unity Catalog implementation
- 1. Data governance model
- 2. Permissions and access control
|
| Productionizing Data Pipelines | 18% | - Monitoring and troubleshooting
- 1. Logging and error handling
- 2. Pipeline reliability and recovery
- Deployment and CI/CD
- 1. Version control integration
- 2. Databricks Asset Bundles
- Workflow orchestration
- 1. Scheduling, triggers, and dependencies
- 2. Lakeflow Jobs creation and management
|
| Development and Ingestion | 30% | - Notebook development fundamentals
- 1. Using PySpark and Spark SQL
- 2. Data exploration and validation
- Data ingestion patterns and methods
- 1. Delta Lake basics and usage
- 2. Connecting to external data sources
- 3. Batch and streaming ingestion
|
>> Databricks-Certified-Data-Engineer-Associate證照 <<
高質量的Databricks-Certified-Data-Engineer-Associate證照,免費下載Databricks-Certified-Data-Engineer-Associate學習資料幫助妳通過Databricks-Certified-Data-Engineer-Associate考試
KaoGuTi是個很好的為Databricks Databricks-Certified-Data-Engineer-Associate 認證考試提供方便的網站。根據過去的考試練習題和答案的研究,KaoGuTi能有效的捕捉Databricks Databricks-Certified-Data-Engineer-Associate 認證考試試題內容。KaoGuTi提供的Databricks Databricks-Certified-Data-Engineer-Associate考試練習題真實的考試練習題有緊密的相似性。
最新的 Databricks Certification Databricks-Certified-Data-Engineer-Associate 免費考試真題 (Q41-Q46):
問題 #41
A data engineer wants to create a relational object by pulling data from two tables. The relational object does not need to be used by other data engineers in other sessions. In order to save on storage costs, the data engineer wants to avoid copying and storing physical data.
Which of the following relational objects should the data engineer create?
- A. Database
- B. Delta Table
- C. Temporary view
- D. View
- E. Spark SQL Table
答案:C
解題說明:
Explanation
Temp view : session based Create temp view view_name as query All these are termed as session ended:
Opening a new notebook Detaching and reattaching a cluster Installing a python package Restarting a cluster
問題 #42
Which of the following benefits is provided by the array functions from Spark SQL?
- A. An ability to work with an array of tables for procedural automation
- B. An ability to work with data in a variety of types at once
- C. An ability to work with time-related data in specified intervals
- D. An ability to work with data within certain partitions and windows
- E. An ability to work with complex, nested data ingested from JSON files
答案:E
解題說明:
Explanation
Array functions in Spark SQL are primarily used for working with arrays and complex, nested data structures, such as those often encountered when ingesting JSON files. These functions allow you to manipulate and query nested arrays and structures within your data, making it easier to extract and work with specific elements or values within complex data formats. While some of the other options (such as option A for working with different data types) are features of Spark SQL or SQL in general, array functions specifically excel at handling complex, nested data structures like those found in JSON files.
問題 #43
A data engineer is attempting to drop a Spark SQL table my_table and runs the following command:
DROP TABLE IF EXISTS my_table;
After running this command, the engineer notices that the data files and metadata files have been deleted from the file system.
Which of the following describes why all of these files were deleted?
- A. The table was external
- B. The table did not have a location
- C. The table's data was larger than 10 GB
- D. The table's data was smaller than 10 GB
- E. The table was managed
答案:E
解題說明:
The reason why all of the data files and metadata files were deleted from the file system after dropping the table is that the table was managed. A managed table is a table that is created and managed by Spark SQL. It stores both the data and the metadata in the default location specified by the spark.sql.warehouse.dir configuration property. When a managed table is dropped, both the data and the metadata are deleted from the file system.
Option B is not correct, as the size of the table's data does not affect the behavior of dropping the table. Whether the table's data is smaller or larger than 10 GB, the data files and metadata files will be deleted if the table is managed, and will be preserved if the table is external.
Option C is not correct, for the same reason as option B.
Option D is not correct, as an external table is a table that is created and managed by the user. It stores the data in a user-specified location, and only stores the metadata in the Spark SQL catalog. When an external table is dropped, only the metadata is deleted from the catalog, but the data files are preserved in the file system.
Option E is not correct, as a table must have a location to store the data. If the location is not specified by the user, it will use the default location for managed tables. Therefore, a table without a location is a managed table, and dropping it will delete both the data and the metadata.
:
Managing Tables
[Databricks Data Engineer Professional Exam Guide]
問題 #44
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The cade block used by the data engineer is below:
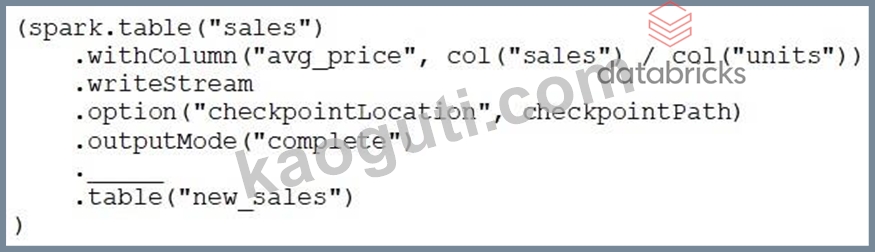
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
- A. trigger(continuous="5 seconds")
- B. trigger("5 seconds")
- C. trigger(processingTime="5 seconds")
- D. trigger(once="5 seconds")
- E. trigger()
答案:C
解題說明:
The processingTime option specifies a time-based trigger interval for fixed interval micro-batches. This means that the query will execute a micro-batch to process data every 5 seconds, regardless of how much data is available. This option is suitable for near-real time processing workloads that require low latency and consistent processing frequency. The other options are either invalid syntax (A, C), default behavior (B), or experimental feature (E). References: Databricks Documentation - Configure Structured Streaming trigger intervals, Databricks Documentation - Trigger.
問題 #45
Which of the following is a benefit of the Databricks Lakehouse Platform embracing open source technologies?
- A. Ability to scale storage
- B. Simplified governance
- C. Avoiding vendor lock-in
- D. Cloud-specific integrations
- E. Ability to scale workloads
答案:C
解題說明:
One of the benefits of the Databricks Lakehouse Platform embracing open source technologies is that it avoids vendor lock-in. This means that customers can use the same open source tools and frameworks across different cloud providers, and migrate their data and workloads without being tied to a specific vendor. The Databricks Lakehouse Platform is built on open source projects such as Apache Spark, Delta Lake, MLflow, and Redash, which are widely used and trusted by millions of developers. By supporting these open source technologies, the Databricks Lakehouse Platform enables customers to leverage the innovation and community of the open source ecosystem, and avoid the risk of being locked into proprietary or closed solutions. The other options are either not related to open source technologies (A, B, C, D), or not benefits of the Databricks Lakehouse Platform (A, B). References: Databricks Documentation - Built on open source, Databricks Documentation - What is the Lakehouse Platform?, Databricks Blog - Introducing the Databricks Lakehouse Platform.
問題 #46
......
作為Databricks相關認證考試大綱的主要供應商,KaoGuTi的Databricks-Certified-Data-Engineer-Associate專家一直不斷地提供品質較高的產品,不斷為客戶提供免費線上客戶服務,並以最快的速度更新考試大綱。
Databricks-Certified-Data-Engineer-Associate真題: https://www.kaoguti.com/Databricks-Certified-Data-Engineer-Associate_exam-pdf.html
- 高質量的Databricks-Certified-Data-Engineer-Associate證照,免費下載Databricks-Certified-Data-Engineer-Associate考試資料得到妳想要的Databricks證書 🎍 開啟( www.vcesoft.com )輸入⇛ Databricks-Certified-Data-Engineer-Associate ⇚並獲取免費下載Databricks-Certified-Data-Engineer-Associate指南
- Databricks Databricks-Certified-Data-Engineer-Associate證照:Databricks Certified Data Engineer Associate Exam可靠的認證資源 🚹 免費下載{ Databricks-Certified-Data-Engineer-Associate }只需進入▶ www.newdumpspdf.com ◀網站Databricks-Certified-Data-Engineer-Associate新版題庫上線
- Databricks-Certified-Data-Engineer-Associate下載 🏌 Databricks-Certified-Data-Engineer-Associate更新 😺 Databricks-Certified-Data-Engineer-Associate題庫更新 🧽 來自網站[ www.vcesoft.com ]打開並搜索( Databricks-Certified-Data-Engineer-Associate )免費下載Databricks-Certified-Data-Engineer-Associate題庫更新
- 最好的Databricks-Certified-Data-Engineer-Associate證照,最有效的學習資料幫助妳壹次性通過Databricks-Certified-Data-Engineer-Associate考試 🛷 免費下載☀ Databricks-Certified-Data-Engineer-Associate ️☀️只需進入➠ www.newdumpspdf.com 🠰網站Databricks-Certified-Data-Engineer-Associate熱門認證
- Databricks-Certified-Data-Engineer-Associate考試資料 🆑 Databricks-Certified-Data-Engineer-Associate考證 🚡 Databricks-Certified-Data-Engineer-Associate更新 ➡️ 立即到➡ www.newdumpspdf.com ️⬅️上搜索✔ Databricks-Certified-Data-Engineer-Associate ️✔️以獲取免費下載Databricks-Certified-Data-Engineer-Associate題庫資訊
- 準確的Databricks-Certified-Data-Engineer-Associate證照 |適用於Databricks Certified Data Engineer Associate Exam 😃 ➥ www.newdumpspdf.com 🡄提供免費▶ Databricks-Certified-Data-Engineer-Associate ◀問題收集Databricks-Certified-Data-Engineer-Associate更新
- Databricks-Certified-Data-Engineer-Associate熱門證照 🚆 Databricks-Certified-Data-Engineer-Associate最新考題 🐣 最新Databricks-Certified-Data-Engineer-Associate題庫 📖 打開「 www.pdfexamdumps.com 」搜尋「 Databricks-Certified-Data-Engineer-Associate 」以免費下載考試資料Databricks-Certified-Data-Engineer-Associate考試資料
- Databricks-Certified-Data-Engineer-Associate熱門認證 🥁 Databricks-Certified-Data-Engineer-Associate考試資料 🔏 Databricks-Certified-Data-Engineer-Associate考題資訊 🌖 在⏩ www.newdumpspdf.com ⏪搜索最新的➠ Databricks-Certified-Data-Engineer-Associate 🠰題庫Databricks-Certified-Data-Engineer-Associate考證
- Databricks-Certified-Data-Engineer-Associate認證考試資料匯總 🟧 立即在✔ www.pdfexamdumps.com ️✔️上搜尋[ Databricks-Certified-Data-Engineer-Associate ]並免費下載Databricks-Certified-Data-Engineer-Associate題庫更新
- Databricks-Certified-Data-Engineer-Associate下載 😗 Databricks-Certified-Data-Engineer-Associate題庫更新 🧗 Databricks-Certified-Data-Engineer-Associate更新 🐹 立即到➠ www.newdumpspdf.com 🠰上搜索⮆ Databricks-Certified-Data-Engineer-Associate ⮄以獲取免費下載Databricks-Certified-Data-Engineer-Associate熱門認證
- Databricks-Certified-Data-Engineer-Associate下載 ♥ Databricks-Certified-Data-Engineer-Associate熱門證照 📴 Databricks-Certified-Data-Engineer-Associate熱門認證 💿 在➡ www.newdumpspdf.com ️⬅️網站上免費搜索{ Databricks-Certified-Data-Engineer-Associate }題庫Databricks-Certified-Data-Engineer-Associate在線題庫
- amfettkesniya.blogspot.com, answers.themler.io, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, ifidir.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026 KaoGuTi最新的Databricks-Certified-Data-Engineer-Associate PDF版考試題庫和Databricks-Certified-Data-Engineer-Associate考試問題和答案免費分享:https://drive.google.com/open?id=1X1X9JcpyrJI-Lvxq2DIEJOCKvZrbnwVn