Our DP-750 actual exam can also broaden your horizon; activate your potential to deal with difficulties. You will not only get desirable goal with our DP-750 exam practice but with superior outcomes that others who dare not imagine. The scarcity of efficient resource impaired many customers’ chance of winning. So choosing materials blindly is dangerous to your exam and you must choose reliable and qualities like our DP-750 simulating questions.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
It is not easy to continue keeping the good quality of a product and at the same time to continue keeping innovating it to become better. But we persisted for so many years on the DP-750 exam questions. Our DP-750 practice guide just wants to give you a product that really makes you satisfied. I know that we don't say much better than letting you experience our DP-750 Training Questions yourself. You can free download the demos of the DP-750 learning quiz to have a try!
NEW QUESTION # 31
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to profile a table to meet the following requirements:
* The count of null values per column must be evaluated repeatedly as new records are added to the table.
* Changes in the count of null values must be observable over the progression of the dataset.
Which type of profile should you create?
Answer: C
Explanation:
A time series profile repeatedly calculates data-quality metrics as a table changes and preserves those measurements over time. This makes it possible to observe whether the number of null values in each column is increasing, decreasing, or remaining stable as new records are added. A snapshot profile evaluates the table at a particular point in time and is therefore insufficient when the requirement is to analyze metric progression across multiple updates. Inference is associated with deriving information such as a schema or statistical characteristics; it is not the profile type used to maintain a historical sequence of monitoring measurements.
Because the question requires repeated evaluation and the ability to observe changes throughout the dataset's progression, the time series profile satisfies both requirements.
NEW QUESTION # 32
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 33
Which feature provides end-to-end tracking of data movement in Databricks?
Answer: C
Explanation:
Unity Catalog provides data lineage tracking across ingestion, transformation, and consumption layers. It helps visualize dependencies and compliance auditing. Spark logs are low-level and not structured for lineage. Query history is partial only.
NEW QUESTION # 34
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.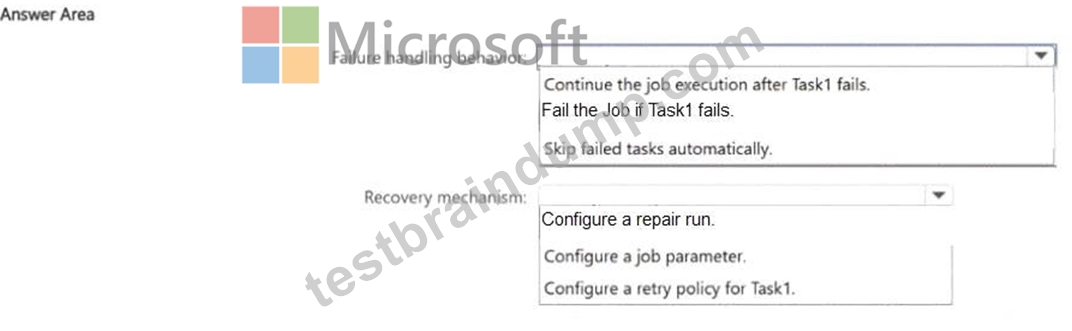
Answer:
Explanation: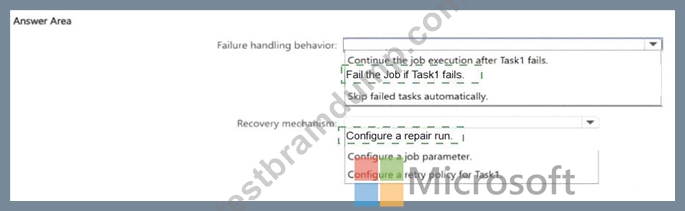
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 35
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
This is a common Python-to-PySpark trap. In pure Python, comparing a value to None with != works as expected. In PySpark, null comparisons follow SQL null semantics: any comparison involving NULL returns NULL (not True or False). So df.filter(df.order_amount != None) doesn't evaluate to True for non-null rows
- the comparison itself returns NULL for null values, and Spark interprets NULL in a filter as False, effectively dropping null rows. But the behaviour is undefined in edge cases and is not the documented approach.
More practically, Python's None and Spark's SQL NULL are different concepts. PySpark Column objects don't support Python's native equality/inequality semantics for null checking. The result is typically an empty DataFrame or incorrect filtering behaviour.
Always use .isNotNull() or .isNull() for null checks in PySpark column expressions. These methods are specifically designed for SQL-null-aware comparisons and produce correct, predictable results.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 36
......
The DP-750 study materials are mainly through three learning modes, Pdf, Online and software respectively. Among them, the software model is designed for computer users, can let users through the use of Windows interface to open the DP-750 study materials of learning. It is convenient for the user to read. The DP-750 study materials have a biggest advantage that is different from some online learning platform which has using terminal number limitation, the DP-750 Study Materials can meet the client to log in to learn more, at the same time, the user can be conducted on multiple computers online learning, greatly reducing the time, and people can use the machine online more conveniently at the same time. As far as concerned, the online mode for mobile phone clients has the same function.
DP-750 Training Questions: https://www.testbraindump.com/DP-750-exam-prep.html