DOWNLOAD the newest VCEPrep Databricks-Certified-Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1X3TDJMBtmQhLwRknMaqot_EDOTlp3T6u
With the rapid development of society, people pay more and more attention to knowledge and skills. So every year a large number of people take Databricks-Certified-Professional-Data-Engineer tests to prove their abilities. But even the best people fail sometimes. In addition to the lack of effort, you may also not make the right choice on our Databricks-Certified-Professional-Data-Engineer Exam Questions. A good choice can make one work twice the result with half the effort, and our Databricks-Certified-Professional-Data-Engineer study materials will be your right choice.
| Section | Objectives |
|---|---|
| Topic 1: Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs - Handle batch and streaming data pipelines |
| Topic 2: Data Modeling and Storage | - Design scalable data lakehouse architectures - Delta Lake table design and optimization - Schema evolution and data partitioning strategies |
| Topic 3: Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads - Cost optimization and performance tuning |
| Topic 4: Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance - Automate ETL pipelines and scheduling |
>> Databricks-Certified-Professional-Data-Engineer Valid Exam Sims <<
VCEPrep proudly says that its product is accurate and trustworthy because it was formulated according to the prescribed content of the Databricks Databricks-Certified-Professional-Data-Engineer actual test. We offer Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions free updates for up to 12 months after purchasing. These free updates of actual Databricks-Certified-Professional-Data-Engineer questions will follow the fresh updates in the exam content.
NEW QUESTION # 209
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: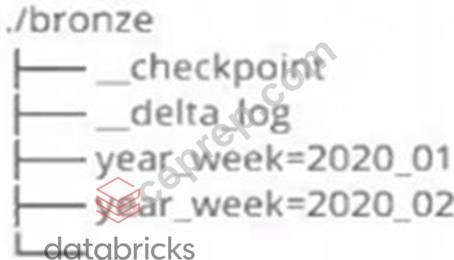
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: E
Explanation:
Explanation
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Checkpointing" section.
NEW QUESTION # 210
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
Answer: C
Explanation:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed. Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under
"CREATE VIEW" section.
NEW QUESTION # 211
A Data engineer wants to run unit's tests using common Python testing frameworks on python functions defined across several Databricks notebooks currently used in production.
How can the data engineer run unit tests against function that work with data in production?
Answer: B
Explanation:
The best practice for running unit tests on functions that interact with data is to use a dataset that closely mirrors the production data. This approach allows data engineers to validate the logic of their functions without the risk of affecting the actual production data. It's important to have a representative sample of production data to catch edge cases and ensure the functions will work correctly when used in a production environment.
References:
* Databricks Documentation on Testing: Testing and Validation of Data and Notebooks
NEW QUESTION # 212
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Answer: D
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column
NEW QUESTION # 213
A nightly job ingests data into a Delta Lake table using the following code: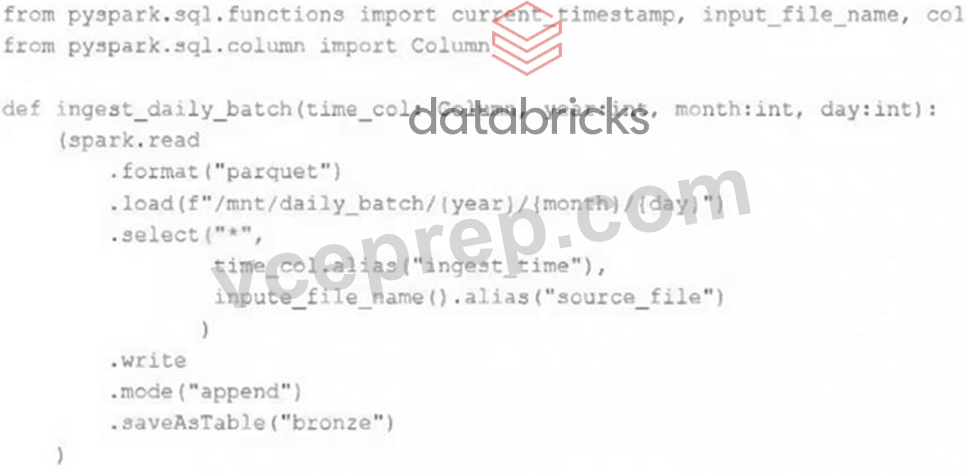
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
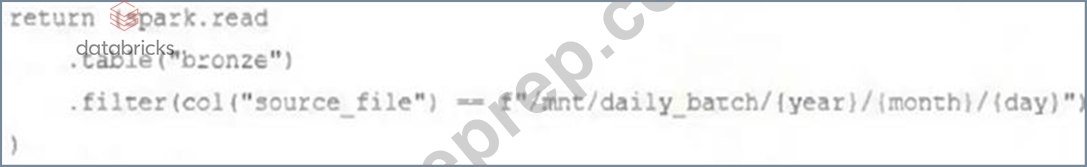
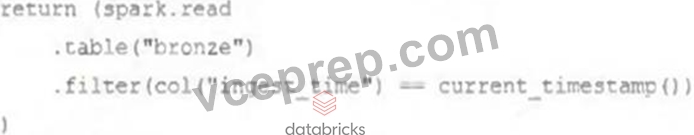
Answer: C
Explanation:
Explanation
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 214
......
As you know, the Databricks-Certified-Professional-Data-Engineer certificate is hard to get for most people. But our Databricks-Certified-Professional-Data-Engineer study guide will offer you the most professional guidance. As old saying goes, opportunities are always for those who prepare themselves well. In the end, you will easily pass the Databricks-Certified-Professional-Data-Engineer Exam through our assistance. Then you will find that your work ability is elevated greatly by studying our Databricks-Certified-Professional-Data-Engineer actual exam. In the end, you will become an excellent talent.
Databricks-Certified-Professional-Data-Engineer Reliable Exam Tips: https://www.vceprep.com/Databricks-Certified-Professional-Data-Engineer-latest-vce-prep.html
BTW, DOWNLOAD part of VCEPrep Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1X3TDJMBtmQhLwRknMaqot_EDOTlp3T6u