BONUS!!! Download part of ValidExam DP-600 dumps for free: https://drive.google.com/open?id=1rcj_-0vgiYo_uGV1u8aaifoVTQB3eFqX
The Microsoft DP-600 desktop practice test software and web-based practice test software, both are the mock Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam that provides you real-time DP-600 exam environment for quick and complete preparation. Whereas the Microsoft DP-600 PDF Dumps file is concerned, this file is simply a collection of real, valid, and updated Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam questions that also help you in preparation. So choose the right "ValidExam" exam questions format and start DP-600 exam preparation today. Order your DP-600 Dumps now to Avail 25% EXTRA Discount on the DP-600 Exam Dumps learning material and get your dream certification.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Real Exam Qty: | 40-60 |
| Exam Format: | Multiple choice, Case studies, Scenario-based questions, Drag and drop |
| Passing Score: | 700 (out of 1000) |
| Exam Duration: | 120 minutes |
| Certificate Validity Period: | 1 year (renewable via Microsoft certification renewal) |
| Available Languages: | German, Korean, Simplified Chinese, Spanish, Japanese, Portuguese (Brazil), English, French |
| Related Certifications: | DP-900 DP-203 PL-300 |
| Exam Price: | $165 USD (varies by country) |
| Recommended Training: | Microsoft Fabric Documentation DP-600 Learning Path (Microsoft Learn) |
| Exam Registration: | Microsoft Certification Dashboard Pearson VUE Microsoft Exams |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored exam or in-person at Pearson VUE test centers |
| Pre Condition: | No formal prerequisites required, but familiarity with data analytics, Power BI, and Azure data services is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/credentials/certifications/fabric-analytics-engineer/ |
Are you still worried about the exam? Don’t worry! Our DP-600 exam torrent can help you overcome this stumbling block during your working or learning process. Under the instruction of our DP-600 test prep, you are able to finish your task in a very short time and pass the exam without mistakes to obtain the Microsoft certificate. We will tailor services to different individuals and help them take part in their aimed exams after only 20-30 hours practice and training. Moreover for all your personal information, we will offer protection acts to avoid leakage and virus intrusion so as to guarantee the security of your privacy. What is most important is that when you make a payment for our DP-600 Quiz torrent, you will possess this product in 5-10 minutes and enjoy the pleasure and satisfaction of your study time.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 84
You have a Fabric tenant that contains a new semantic model in OneLake.
You use a Fabric notebook to read the data into a Spark DataFrame.
You need to evaluate the data to calculate the min, max, mean, and standard deviation values for all the string and numeric columns.
Solution: You use the following PySpark expression:
df.show()
Does this meet the goal?
Answer: B
NEW QUESTION # 85
You have a Fabric tenant that contains a lakehouse named Lakehouse1.
You need to prevent new tables added to Lakehouse1 from being added automatically to the default semantic model of the lakehouse.
What should you configure? (5)
Answer: D
Explanation:
To prevent new tables added to Lakehouse1 from being automatically added to the default semantic model, you should configure the semantic model settings. There should be an option within the settings of the semantic model to include or exclude new tables by default. By adjusting these settings, you can control the automatic inclusion of new tables.
NEW QUESTION # 86
You have a Fabric workspace that uses the default Spark starter pool and runtime version 1,2.
You plan to read a CSV file named Sales.raw.csv in a lakehouse, select columns, and save the data as a Delta table to the managed area of the lakehouse. Sales_raw.csv contains 12 columns.
You have the following code.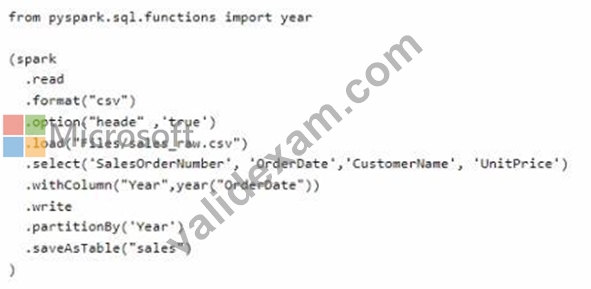
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.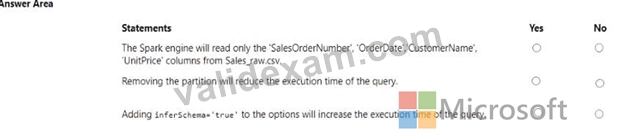
Answer:
Explanation: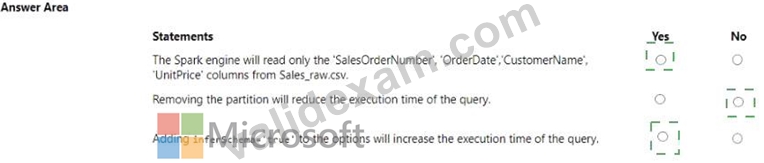
Explanation: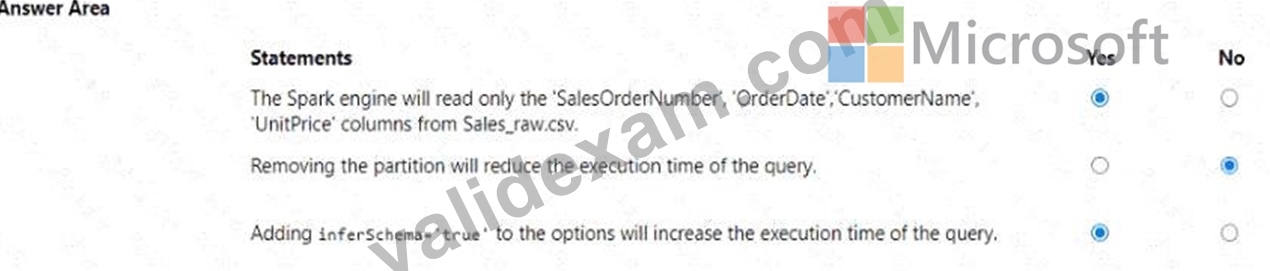
* The Spark engine will read only the 'SalesOrderNumber', 'OrderDate', 'CustomerName', 'UnitPrice' columns from Sales_raw.csv. - Yes
* Removing the partition will reduce the execution time of the query. - No
* Adding inferSchema='true' to the options will increase the execution time of the query. - Yes The code specifies the selection of certain columns, which means only those columns will be read into the DataFrame. Partitions in Spark are a way to optimize the execution of queries by organizing the data into parts that can be processed in parallel. Removing the partition could potentially increase the execution time because Spark would no longer be able to process the data in parallel efficiently. The inferSchema option allows Spark to automatically detect the column data types, which can increase the execution time of the initial read operation because it requires Spark to read through the data to infer the schema.
NEW QUESTION # 87
You are implementing two dimension tables named Customers and Products in a Fabric warehouse.
You need to use slowly changing dimension (SCO) to manage the versioning of data. The solution must meet the requirements shown in the following table.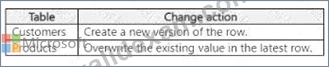
Which type of SCD should you use for each table? To answer, drag the appropriate SCD types to the correct tables. Each SCD type may be used once, more than once, or not at all. You may need to drag the split bar between panes o r scroll to view content.
NOTE: Each correct selection is worth one point.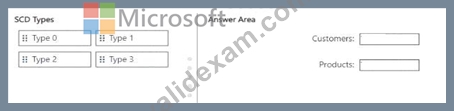
Answer:
Explanation: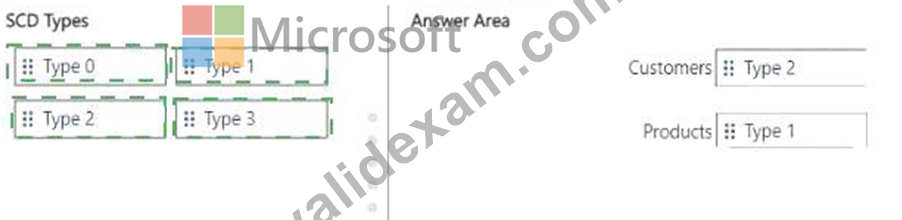
Explanation: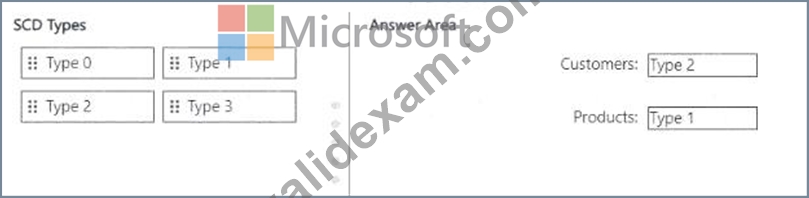
For the Customers table, where the requirement is to create a new version of the row, you would use:
Type 2 SCD: This type allows for the creation of a new record each time a change occurs, preserving the history of changes over time.
For the Products table, where the requirement is to overwrite the existing value in the latest row, you would use:
Type 1 SCD: This type updates the record directly, without preserving historical data.
NEW QUESTION # 88
You have a Fabric warehouse that contains a table named SalesOrderDetail. SalesOrderDetail contains three columns named OrderQty, ProductID and SalesOrderlD. SalesOrderDetail contains one row per combination of SalesOrderlD and ProductID.
You need to calculate the proportion of the total quantity of each sales order represented by each product within the sales order.
Which T-SQL statement should you run?
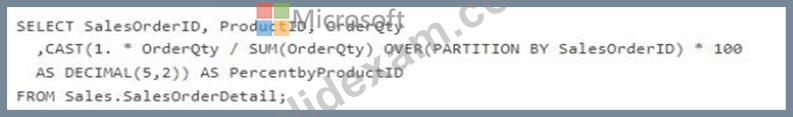
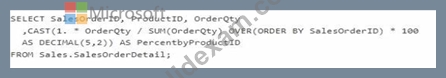
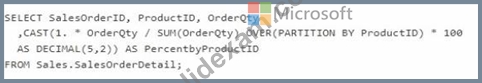
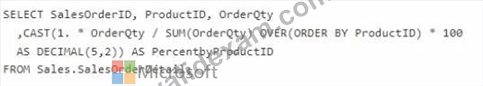
Answer: A
NEW QUESTION # 89
......
Valid Dumps DP-600 Sheet: https://www.validexam.com/DP-600-latest-dumps.html
P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by ValidExam: https://drive.google.com/open?id=1rcj_-0vgiYo_uGV1u8aaifoVTQB3eFqX