さらに、Jpshiken DP-100ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1GzKzqlzT0amYBpYyO41ayqnopxQvzCLH
テストに関する最も有用で効率的なDP-100トレーニング資料を提供するために最善を尽くし、クライアントが効率的に学習できるように複数の機能と直感的な方法を提供します。 DP-100の有用なテストガイドを学習すれば、時間と労力はほとんどかかりません。合格率とヒット率はともに高いため、テストに合格するための障害はほとんどありません。 Webで紹介を読んだ後、DP-100学習実践ガイドをさらに理解できます。
| Section | Objectives |
|---|---|
| Topic 1: Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
| Topic 2: Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Topic 3: Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Topic 4: Design and prepare a machine learning solution | - Manage compute and data assets - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads |
| Topic 5: Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
JpshikenのDP-100問題集を入手してから、非常に短い時間で試験に準備しても、あなたは順調に試験に合格することができます。Jpshikenの問題集には、実際の試験に出る可能性がある問題が全部含まれていますから、問題集における問題を覚える限り、簡単に試験に合格することができます。これは試験に合格する最速のショートカットです。仕事に忙しいから試験の準備をする時間はあまりないとしたら、絶対JpshikenのDP-100問題集を見逃すことはできないです。これはあなたがDP-100試験に合格できる最善で、しかも唯一の方法ですから。
質問 # 423
You plan to explore demographic data for home ownership in various cities. The data is in a CSV file with the following format:
age,city,income,home_owner
21,Chicago,50000,0
35,Seattle,120000,1
23,Seattle,65000,0
45,Seattle,130000,1
18,Chicago,48000,0
You need to run an experiment in your Azure Machine Learning workspace to explore the data and log the results. The experiment must log the following information:
the number of observations in the dataset
a box plot of income by home_owner
a dictionary containing the city names and the average income for each city You need to use the appropriate logging methods of the experiment's run object to log the required information.
How should you complete the code? To answer, drag the appropriate code segments to the correct locations.
Each code segment may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.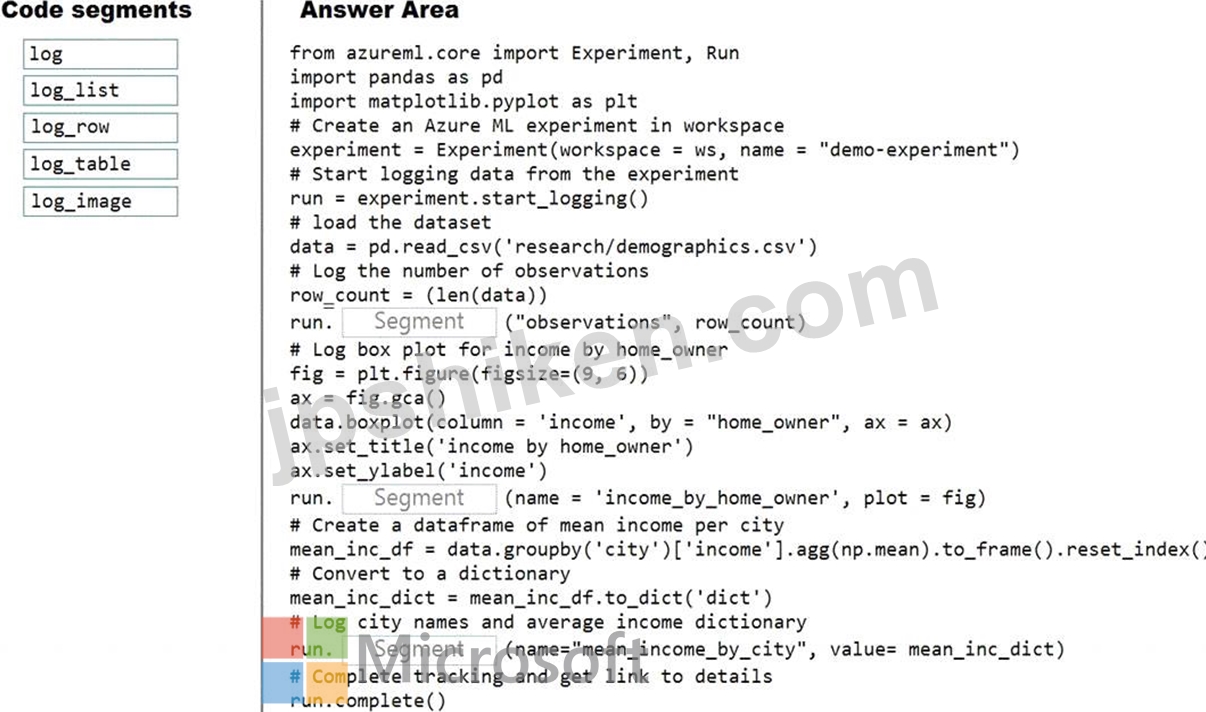
正解:
解説: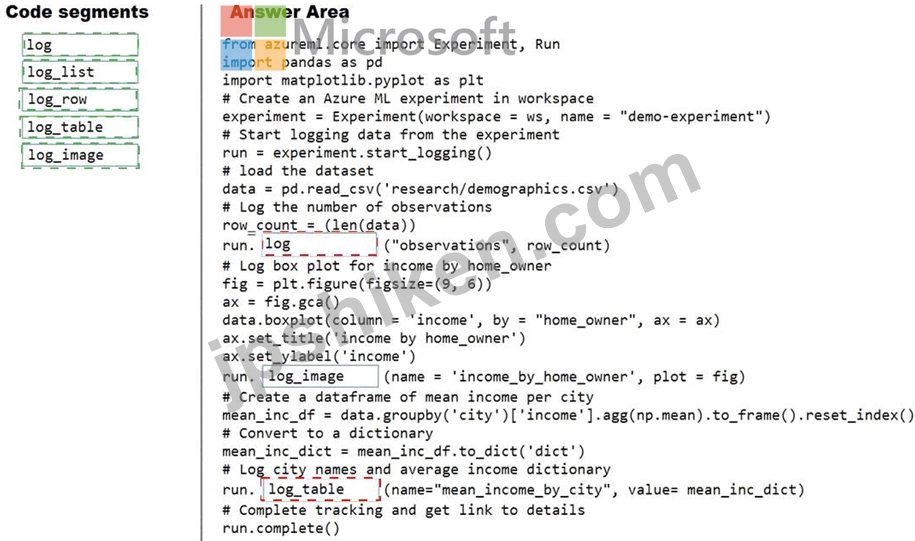
Explanation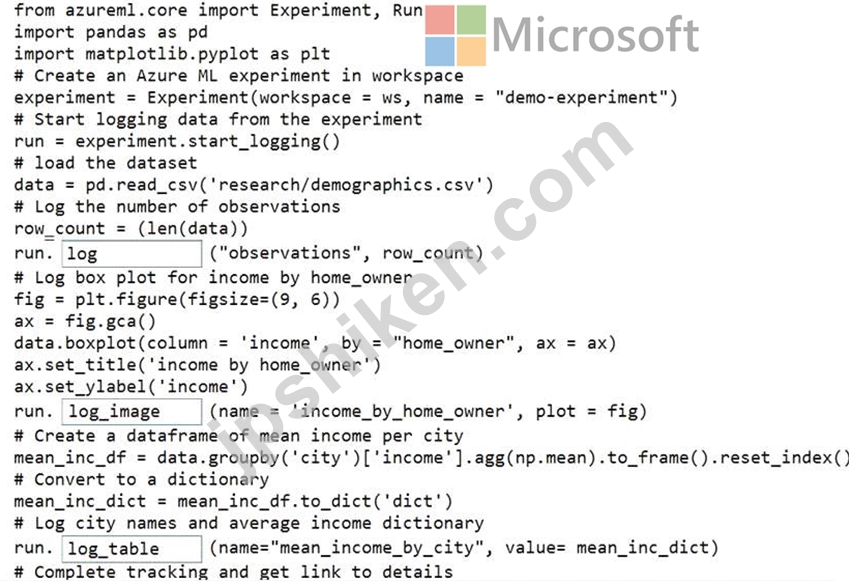
Box 1: log
The number of observations in the dataset.
run.log(name, value, description='')
Scalar values: Log a numerical or string value to the run with the given name. Logging a metric to a run causes that metric to be stored in the run record in the experiment. You can log the same metric multiple times within a run, the result being considered a vector of that metric.
Example: run.log("accuracy", 0.95)
Box 2: log_image
A box plot of income by home_owner.
log_image Log an image to the run record. Use log_image to log a .PNG image file or a matplotlib plot to the run. These images will be visible and comparable in the run record.
Example: run.log_image("ROC", plot=plt)
Box 3: log_table
A dictionary containing the city names and the average income for each city.
log_table: Log a dictionary object to the run with the given name.
質問 # 424
You need to implement early stopping criteria as suited in the model training requirements.
Which three code segments should you use to develop the solution? To answer, move the appropriate code segments from the list of code segments to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.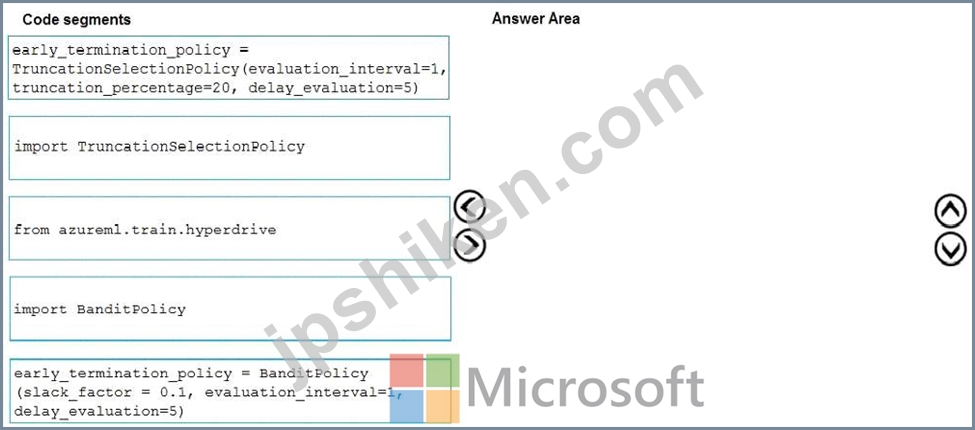
正解:
解説: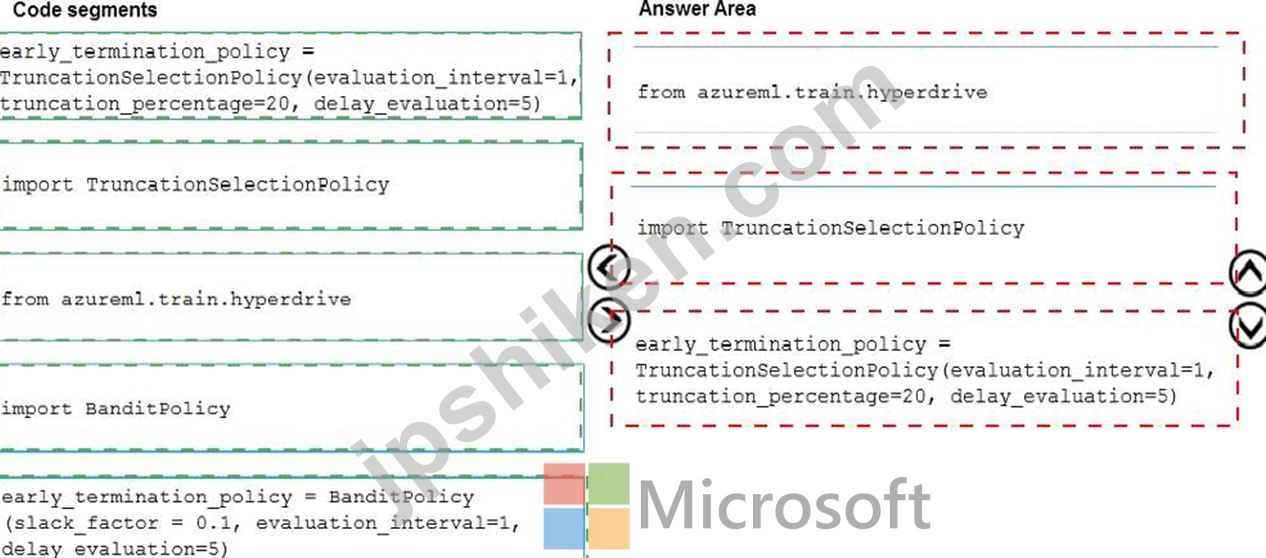
Explanation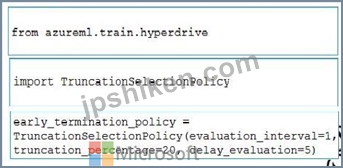
You need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Truncation selection cancels a given percentage of lowest performing runs at each evaluation interval. Runs are compared based on their performance on the primary metric and the lowest X% are terminated.
Example:
from azureml.train.hyperdrive import TruncationSelectionPolicy
early_termination_policy = TruncationSelectionPolicy(evaluation_interval=1, truncation_percentage=20, delay_evaluation=5)
質問 # 425
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data. The folder structure contains the following content:
You write Python SDK v2 code to materialize the data from the files in the sample.data folder into a Pandas data frame. You need to complete the Python SDK v2 code to use the MLTaWe folder as the materialization blueprint. How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.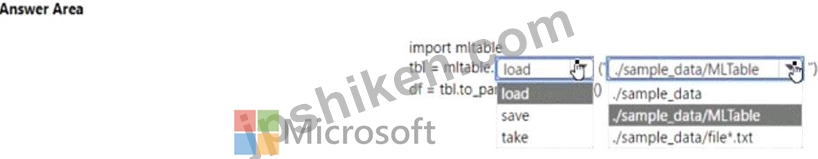
正解:
解説: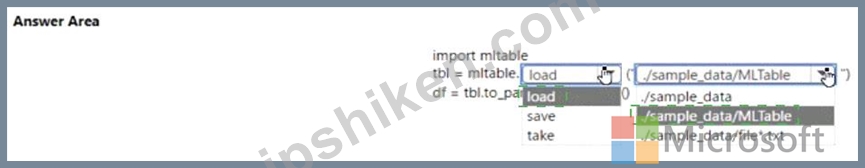
Explanation: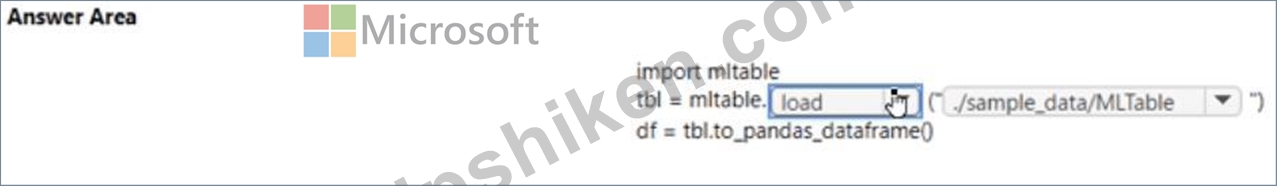
質問 # 426
You are using an Azure Machine Learning workspace. You set up an environment for model testing and an environment for production.
The compute target for testing must minimize cost and deployment efforts. The compute target for production must provide fast response time, autoscaling of the deployed service, and support real-time inferencing.
You need to configure compute targets for model testing and production.
Which compute targets should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.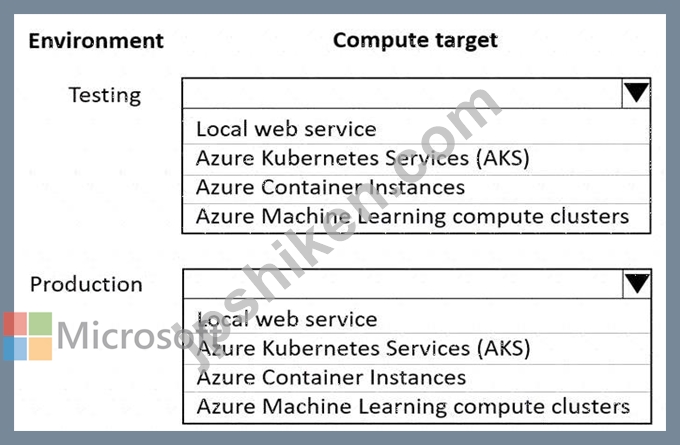
正解:
解説: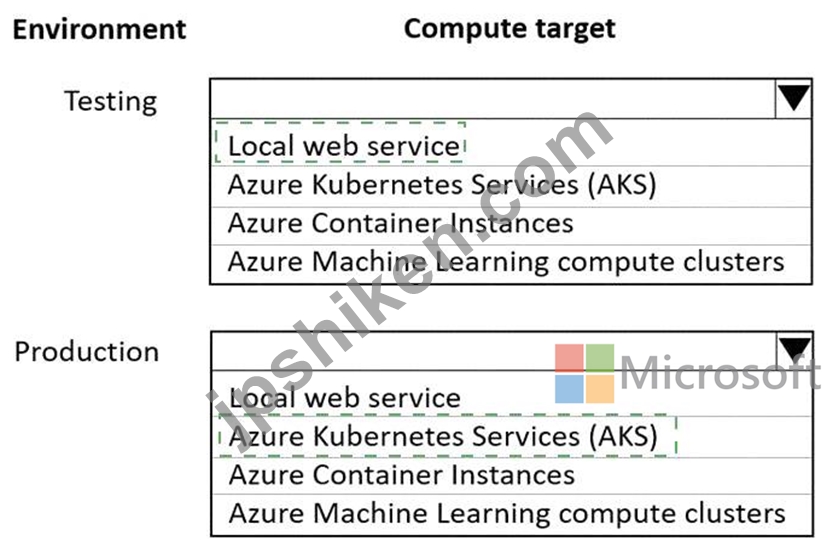
Explanation
Text, application Description automatically generated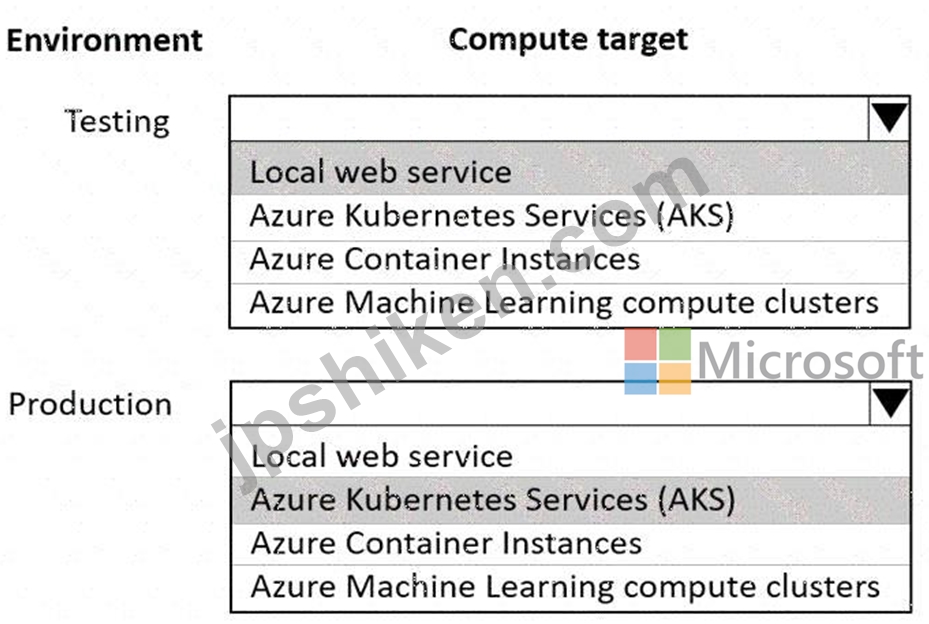
Box 1: Local web service
The Local web service compute target is used for testing/debugging. Use it for limited testing and troubleshooting. Hardware acceleration depends on use of libraries in the local system.
Box 2: Azure Kubernetes Service (AKS)
Azure Kubernetes Service (AKS) is used for Real-time inference.
Recommended for production workloads.
Use it for high-scale production deployments. Provides fast response time and autoscaling of the deployed service Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
質問 # 427
You manage an Azure Machine Learning workspace.
You build an image recognition training pipeline, which includes hyperparameter tuning. For each epoch run, you plan to log the following metrics:
* the transformed images used for training in an existing folder
* a description to explain the hyperparameter changes
You need to configure logging for the experiment.
Which two functions should you use? Each correct answer presents part of the solution. Choose two. NOTE:
Each correct selection is worth one point.
正解:A、C
質問 # 428
......
早急にDP-100認定試験に参加し、特定の分野での仕事に適格であることを証明する証明書を取得する必要があります。 DP-100学習教材を購入すると、ほとんど問題なくテストに合格します。 DP-100の学習教材は高い合格率とヒット率を高めるため、テストにあまり合格しなくても心配する必要はありません。購入前に無料トライアルを提供しています。 DP-100練習エンジンのメリットと機能をさらに理解するには、製品の紹介を詳細にご覧ください。
DP-100参考資料: https://www.jpshiken.com/DP-100_shiken.html
BONUS!!! Jpshiken DP-100ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1GzKzqlzT0amYBpYyO41ayqnopxQvzCLH