Databricks-Certified-Data-Engineer-Associate시험대비최신버전자료 - Databricks-Certified-Data-Engineer-Associate덤프내용

BONUS!!! PassTIP Databricks-Certified-Data-Engineer-Associate 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=19E8wjyTXCJF7Q_u-yBKiOc-jOGkGXL38
PassTIP는 유일하게 여러분이 원하는Databricks인증Databricks-Certified-Data-Engineer-Associate시험관련자료를 해결해드릴 수 잇는 사이트입니다. PassTIP에서 제공하는 자료로 응시는 문제없습니다, 여러분은 고득점으로 시험을 통과할 것입니다.
GAQM Databricks 인증 데이터 엔지니어 관련 (Databricks Certified Data Engineer Associate) 시험은 Databricks와 함께 일하는 데이터 엔지니어의 기술과 지식을 테스트하도록 설계된 인증입니다. 데이터 엔지니어는 데이터에 의존하여 의사 결정을 내리는 모든 조직에서 중요한 역할을합니다. 데이터 파이프 라인, 데이터 모델 및 데이터웨어 하우스의 설계, 구성 및 유지 관리를 담당합니다.
Databricks-Certified-Data-Engineer-Associate 시험을 준비하기 위해서는 Databricks 및 여러 구성 요소에 대한 깊은 이해가 필요합니다. 후보자는 Spark SQL, Spark Streaming 및 Spark MLlib에 대한 경험이 있어야 하며, 데이터 모델링, 데이터 구조 및 알고리즘에 대한 견고한 이해도가 필요합니다. 또한 Hadoop, Kafka 및 AWS S3와 같은 일반적인 데이터 저장 및 처리 기술에 익숙해야 합니다.
>> Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 <<
Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 100% 유효한 최신 공부자료
PassTIP는IT업계전문가들이 그들의 노하우와 몇 년간의 경험 등으로 자료의 정확도를 높여 응시자들의 요구를 만족시켜 드립니다. 우리는 꼭 한번에Databricks Databricks-Certified-Data-Engineer-Associate시험을 패스할 수 있도록 도와드릴 것입니다. 여러분은Databricks Databricks-Certified-Data-Engineer-Associate시험자료 구매로 제일 정확하고 또 최신시험버전의 문제와 답을 사용할 수 있습니다. Pass4Tes의 인증시험적중 율은 아주 높습니다. 때문에 많은 IT인증시험준비중인분들에세 많은 편리를 드릴수 있습니다.100%정확도 100%신뢰.여러분은 마음편히 응시하시면 됩니다.
Databricks Certified Data Engineer Associate 시험은 개인의 데이터 파이프라인 설계 및 구현 능력, 대용량 데이터 솔루션 최적화 및 튜닝, Databricks를 사용하여 데이터 워크플로우를 관리하는 능력을 측정합니다. 후보자들은 데이터 처리 기술, 데이터 저장 및 데이터 관리 개념에 대한 견고한 이해도가 요구됩니다. 이 자격증 프로그램은 대용량 데이터 엔지니어링 분야에서 개인의 기술을 포괄적으로 평가하며, 이 분야에서 경력을 발전시키고자 하는 사람들에게 가치 있는 자격증을 제공합니다.
최신 Databricks Certification Databricks-Certified-Data-Engineer-Associate 무료샘플문제 (Q296-Q301):
질문 # 296
A dataset has been defined using Delta Live Tables and includes an expectations clause:
CONSTRAINT valid_timestamp EXPECT (timestamp > '2020-01-01') ON VIOLATION DROP ROW What is the expected behavior when a batch of data containing data that violates these constraints is processed?
- A. Records that violate the expectation are dropped from the target dataset and recorded as invalid in the event log.
- B. Records that violate the expectation are added to the target dataset and flagged as invalid in a field added to the target dataset.
- C. Records that violate the expectation are dropped from the target dataset and loaded into a quarantine table.
- D. Records that violate the expectation cause the job to fail.
- E. Records that violate the expectation are added to the target dataset and recorded as invalid in the event log.
정답:E
질문 # 297
A data engineering team has two tables. The first table march_transactions is a collection of all retail transactions in the month of March. The second table april_transactions is a collection of all retail transactions in the month of April. There are no duplicate records between the tables.
Which of the following commands should be run to create a new table all_transactions that contains all records from march_transactions and april_transactions without duplicate records?
- A. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
OUTER JOIN SELECT * FROM april_transactions; - B. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
INTERSECT SELECT * from april_transactions; - C. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
INNER JOIN SELECT * FROM april_transactions; - D. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
MERGE SELECT * FROM april_transactions; - E. CREATE TABLE all_transactions AS
SELECT * FROM march_transactions
UNION SELECT * FROM april_transactions;
정답:E
설명:
Explanation
To create a new table all_transactions that contains all records from march_transactions and april_transactions without duplicate records, you should use the UNION operator, as shown in option B. This operator combines the result sets of the two tables while automatically removing duplicate records.
질문 # 298
A new data engineering team team has been assigned to an ELT project. The new data engineering team will need full privileges on the table sales to fully manage the project.
Which of the following commands can be used to grant full permissions on the database to the new data engineering team?
- A. GRANT ALL PRIVILEGES ON TABLE sales TO team;
- B. GRANT USAGE ON TABLE sales TO team;
- C. GRANT SELECT ON TABLE sales TO team;
- D. GRANT ALL PRIVILEGES ON TABLE team TO sales;
- E. GRANT SELECT CREATE MODIFY ON TABLE sales TO team;
정답:A
설명:
To grant full permissions on a table to a user or a group, you can use the GRANT ALL PRIVILEGES ON TABLE statement. This statement will grant all the possible privileges on the table, such as SELECT, CREATE, MODIFY, DROP, ALTER, etc. Option A is the only code block that follows this syntax correctly. Option B is incorrect, as it does not grant all the possible privileges on the table, but only a subset of them. Option C is incorrect, as it only grants the SELECT privilege on the table, which is not enough to fully manage the project. Option D is incorrect, as it grants the USAGE privilege on the table, which is not a valid privilege for tables. Option E is incorrect, as it grants all the privileges on the table team to the user or group sales, which is the opposite of what the question asks. References: Grant privileges on a table using SQL | Databricks on AWS, Grant privileges on a table using SQL - Azure Databricks, SQL Privileges - Databricks
질문 # 299
Which tool is used by Auto Loader to process data incrementally?
- A. Checkpointing
- B. Spark Structured Streaming
- C. Unity Catalog
- D. Databricks SQL
정답:B
설명:
Auto Loader in Databricks utilizes Spark Structured Streaming for processing data incrementally. This allows Auto Loader to efficiently ingest streaming or batch data at scale and to recognize new data as it arrives in cloud storage. Spark Structured Streaming provides the underlying engine that supports various incremental data loading capabilities like schema inference and file notification mode, which are crucial for the dynamic nature of data lakes.
질문 # 300
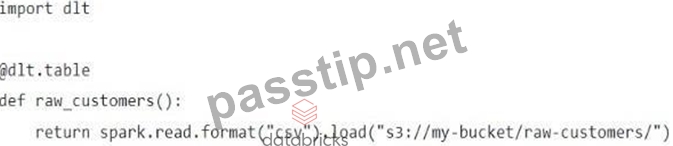
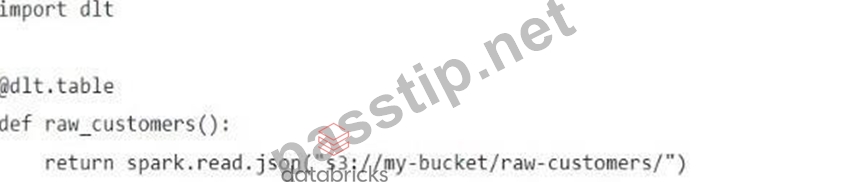
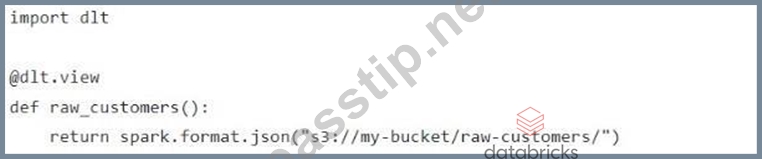
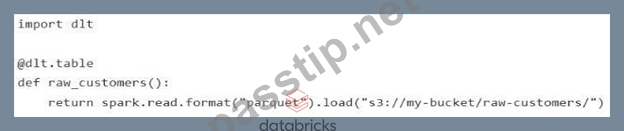
A Data Engineer is building a simple data pipeline using Delta Live Tables (DLT) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create a DLT pipeline that reads the raw JSON data and writes it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using DLT?
정답:B
설명:
The correct approach is to use @dlt.table to define a Delta Live Table and read the raw JSON data with spark.read.json("s3://..."). This properly ingests the JSON source data and materializes it as a managed Delta table in DLT.
질문 # 301
......
Databricks-Certified-Data-Engineer-Associate덤프내용: https://www.passtip.net/Databricks-Certified-Data-Engineer-Associate-pass-exam.html
- Databricks-Certified-Data-Engineer-Associate퍼펙트 인증공부자료 🤹 Databricks-Certified-Data-Engineer-Associate완벽한 인증시험덤프 🤬 Databricks-Certified-Data-Engineer-Associate완벽한 덤프공부자료 🅰 지금“ www.pass4test.net ”을(를) 열고 무료 다운로드를 위해[ Databricks-Certified-Data-Engineer-Associate ]를 검색하십시오Databricks-Certified-Data-Engineer-Associate최신 덤프공부자료
- Databricks-Certified-Data-Engineer-Associate응시자료 💸 Databricks-Certified-Data-Engineer-Associate최신 덤프문제 🍜 Databricks-Certified-Data-Engineer-Associate최신버전 인기 시험자료 👄 [ www.itdumpskr.com ]의 무료 다운로드➡ Databricks-Certified-Data-Engineer-Associate ️⬅️페이지가 지금 열립니다Databricks-Certified-Data-Engineer-Associate유효한 덤프자료
- Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 인기시험 덤프 샘플문제 🕊 “ www.exampassdump.com ”에서 검색만 하면[ Databricks-Certified-Data-Engineer-Associate ]를 무료로 다운로드할 수 있습니다Databricks-Certified-Data-Engineer-Associate적중율 높은 시험덤프공부
- Databricks-Certified-Data-Engineer-Associate높은 통과율 덤프공부 🪕 Databricks-Certified-Data-Engineer-Associate퍼펙트 인증공부자료 📝 Databricks-Certified-Data-Engineer-Associate퍼펙트 인증공부자료 📸 ( www.itdumpskr.com )의 무료 다운로드{ Databricks-Certified-Data-Engineer-Associate }페이지가 지금 열립니다Databricks-Certified-Data-Engineer-Associate높은 통과율 시험대비 공부문제
- 높은 적중율을 자랑하는 Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 공부자료 😃 ▛ www.itdumpskr.com ▟을(를) 열고➡ Databricks-Certified-Data-Engineer-Associate ️⬅️를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Certified-Data-Engineer-Associate최신 인증시험 기출자료
- 시험패스 가능한 Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 덤프문제 🕒 ( www.itdumpskr.com )에서✔ Databricks-Certified-Data-Engineer-Associate ️✔️를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Engineer-Associate퍼펙트 인증공부자료
- 시험패스 가능한 Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 덤프문제 ➕ ⇛ www.exampassdump.com ⇚웹사이트를 열고「 Databricks-Certified-Data-Engineer-Associate 」를 검색하여 무료 다운로드Databricks-Certified-Data-Engineer-Associate시험유형
- 최신버전 Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 완벽한 시험덤프 데모문제 다운 🙂 ➥ www.itdumpskr.com 🡄을(를) 열고⇛ Databricks-Certified-Data-Engineer-Associate ⇚를 입력하고 무료 다운로드를 받으십시오Databricks-Certified-Data-Engineer-Associate시험유형
- Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 100% 유효한 시험대비 자료 ⏳ 시험 자료를 무료로 다운로드하려면▷ www.koreadumps.com ◁을 통해《 Databricks-Certified-Data-Engineer-Associate 》를 검색하십시오Databricks-Certified-Data-Engineer-Associate최신버전 인기 시험자료
- 최근 인기시험 Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 덤프공부 🌺 《 Databricks-Certified-Data-Engineer-Associate 》를 무료로 다운로드하려면▷ www.itdumpskr.com ◁웹사이트를 입력하세요Databricks-Certified-Data-Engineer-Associate완벽한 인증시험덤프
- Databricks-Certified-Data-Engineer-Associate시험대비 최신버전 자료 인증시험정보 🍮 지금⇛ www.passtip.net ⇚을(를) 열고 무료 다운로드를 위해➽ Databricks-Certified-Data-Engineer-Associate 🢪를 검색하십시오Databricks-Certified-Data-Engineer-Associate최신 덤프공부자료
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.ganjingworld.com, app.parler.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026 PassTIP 최신 Databricks-Certified-Data-Engineer-Associate PDF 버전 시험 문제집과 Databricks-Certified-Data-Engineer-Associate 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=19E8wjyTXCJF7Q_u-yBKiOc-jOGkGXL38