Training SPS-C01 Material - SPS-C01 Unlimited Exam Practice

2026 Latest Braindumpsqa SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1WiE1na3FHvD-fr7XpwAbuJNKJPEQXd5f
We provide a wide range of learning and preparation methodologies to the customers for the SPS-C01 complete training. After using the SPS-C01 products, success would surely be the fate of customer because, self-evaluation, highlight of the mistakes, time management and sample question answers in comprehensive manner, are all the tools which are combined to provide best possible results. We are also offering 100% money back guarantee to the customers in case they don't achieve passing scores in the Snowflake SPS-C01 in the first attempt.
| Section | Weight | Objectives |
|---|
| Data Transformations and Operations | 35% | - Advanced operations
- 1. Semi-structured data processing
- 2. Pivot and unpivot transformations
- 3. Window functions and analytics
- User-defined logic
- 1. Stored procedures with Snowpark
- 2. UDFs, UDAFs, UDTFs
- DataFrame manipulation
- 1. Filtering, sorting, grouping, aggregation
- 2. Joins, unions, set operations
- 3. Selection, projection, renaming, casting
|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
- 1. Transformations vs actions
- 2. Lazy evaluation and DAG execution
- 3. Client-side vs server-side processing
- Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
|
| Performance and Best Practices | 10% | - Optimization techniques
- 1. Minimizing data movement
- 2. Caching and warehouse sizing
- 3. Query pushdown and execution plans
- Security and governance
- 1. Access control and permissions
- 2. Data protection and compliance
|
| Snowpark API and Development | 30% | - Python API fundamentals
- 1. DataFrame creation from tables, views, SQL
- 2. Data persistence and writing results
- 3. Column operations and functions
- Multi-language support
- 1. Environment setup and dependencies
- 2. Java and Scala API basics
|
>> Training SPS-C01 Material <<
Snowflake SPS-C01 Unlimited Exam Practice & New SPS-C01 Braindumps Questions
With online test engine, you will feel the atmosphere of Snowflake valid test. You can set limit-time when you do the SPS-C01 test questions so that you can control your time in SPS-C01 practice exam. Online version can point out your mistakes and remind you to practice it every day. What's more, you can practice SPS-C01 Pdf Torrent anywhere and anytime.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q236-Q241):
NEW QUESTION # 236
You are developing a Snowpark application to analyze customer data'. You need to create a Snowpark DataFrame from a list of dictionaries, where each dictionary represents a customer with 'id', 'name', and 'city' keys. The data should be loaded efficiently. Consider these scenarios: 1 . The input data can sometimes contain missing values (e.g., a customer might not have a city specified). 2. You want to ensure optimal performance when loading the data, as the list can be very large. 3. You need the resulting DataFrame's schema to correctly infer the datatypes based on the input dictionary's values. Which of the following methods and considerations should be used to create a Snowpark DataFrame from a list of dictionaries to meet these requirements?
- A. Use 'session.createDataFrame(data, and specify the 'nullable' property for each field within the schema. Additionally, define the data type explicitly. This optimizes performance.
- B. Use 'session.createDataFrame(data, where 'schema' is explicitly defined to handle missing data and ensure correct data types. This improves performance over schema inference.
- C. Use 'session.createDataFrame(data)' with default settings. Snowflake will automatically infer the schema and handle missing values as 'NULL'.
- D. Use 'session.createDataFrame(data)' and then explicitly cast columns with potential missing values to the correct datatype using method to ensure 'NULL' handling.
- E. Leverage Snowpark's optimized data loading by converting the list of dictionaries to a Pandas DataFrame first and then create a Snowpark DataFrame using 'session.createDataFrame(pandas_df)'. Pandas has optimized data loading.
Answer: A,B
Explanation:
Options B and D are the most appropriate. Providing an explicit schema, including specifying the 'nullable' property and datatypes, offers several advantages: 1. Handles missing values: By explicitly setting 'nullable=True' in the schema for columns that might contain missing values, you ensure that Snowflake correctly handles these as 'NULC. 2. Optimizes Performance: Specifying the schema avoids Snowflake's need to infer it, which can be a performance bottleneck, especially for large datasets. Explicit datatypes also help with storage and processing efficiency. 3. Data Type Control: You can ensure the correct data types are used for each column, preventing potential issues with data type conversions later om Option A relies on automatic schema inference, which can be inefficient and may not always correctly handle missing values or data types as expected. Option C requires explicit casting after DataFrame creation which is less efficient than specifying in the schema initially. Option E can add an unneccessary overhead since converting to Pandas DataFrame and then to Snowpark DataFrame may not be optimized.
NEW QUESTION # 237
You are working with a Snowpark DataFrame containing customer data'. One of the columns, 'phone number', contains phone numbers in various formats (e.g., '123-456-7890', '(123) 456-7890', '1234567890'). You need to standardize all phone numbers to the format '+1-123-456-7890' using Snowpark for Python. You also want to handle cases where the phone number is NULL gracefully, replacing them with '+1-000-000-0000'. Which of the following Snowpark code snippets is the most efficient and correct way to achieve this?
Answer: B
Explanation:
Option C is the most efficient because it uses built-in Snowpark functions (when, regexp_replace, substring, concat, length, and lit) to perform the transformation directly on the server-side. It first handles NULL values. It then removes non-numeric characters. Finally, it checks the length of the remaining digits before formatting, ensuring only valid 10-digit numbers are transformed, setting others to NULL. Options A, D, and E do not handle the case where after removing non-numeric characters, the length of phone number is not 10. Option B uses a UDF, which is generally less efficient than using built-in functions as it involves serialization/deserialization overhead .
NEW QUESTION # 238
A Snowpark Python application is experiencing significant performance degradation when processing a large dataset (100GB+) stored in Snowflake. The application performs a complex series of transformations, including window functions and joins with smaller lookup tables. You suspect data skew is contributing to the issue. Which of the following strategies would be MOST effective in mitigating the impact of data skew and improving performance?
- A. Convert the Snowpark DataFrame to a Pandas DataFrame before performing transformations.
- B. Disable query result caching to ensure fresh data is always used.
- C. Increase the warehouse size to a larger instance (e.g., from X-Small to Large).
- D. Implement salting or pre-partitioning of the data based on a hash of the skewed column before performing the joins and window functions.
- E. Cache the smaller lookup tables using 'session.createDataFrame' and broadcast them to all worker nodes.
Answer: D
Explanation:
Salting or pre-partitioning addresses data skew directly by distributing the skewed values more evenly across partitions. Increasing warehouse size (A) might help to some extent but doesn't solve the underlying skew issue. Broadcasting small tables (C) is a good optimization, but it's less effective if the larger dataset is skewed. Disabling query result caching (D) is irrelevant to data skew. Converting to Pandas (E) will likely make performance worse for large datasets due to data transfer overhead and limitations of single-node processing.
NEW QUESTION # 239
You are developing a Snowpark stored procedure in Python that needs to access and modify a temporary table within the same session.
Which of the following approaches is the MOST efficient and recommended way to achieve this?
- A. Using 'session.createOrReplaceTempView()' to create a temporary view based on a DataFrame, and then querying the view using 'session.sql('SELECT
- B. Using 'session.sql('CREATE TEMPORARY TABLE followed by subsequent 'session.sql('lNSERT INTO and 'session.sql('SELECT statements to interact with the temporary table.
- C. Using to create a DataFrame representing the temporary table, and then performing all operations using DataFrame transformations.
- D. Using the Python DB API (e.g., 'snowflake.connector' ) within the stored procedure to establish a separate connection to Snowflake and interact with the temporary table.
- E. Creating a global temporary table using 'CREATE GLOBAL TEMPORARY TABLE outside the stored procedure and then accessing it within the stored procedure using 'session.table()'.
Answer: C
Explanation:
Option B, using 'session.createDataFrame()' and DataFrame transformations, is the most efficient and recommended approach. Snowpark DataFrames are optimized for execution within the Snowflake engine. Using DataFrame transformations allows Snowpark to leverage its query optimization capabilities. Option A, using 'session.sql()' repeatedly, involves parsing and executing SQL statements for each operation, which is less efficient. Option C, using a separate connection, introduces unnecessary overhead and complexity. Option D, global temporary tables, are not session-specific. Option E, creating a temporary view and then querying it with SQL, is also less efficient than using DataFrame operations directly.
NEW QUESTION # 240
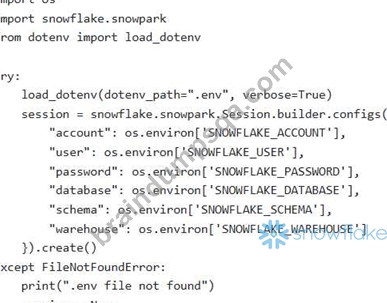
You have configured your Snowpark application to use a '.env' file for storing connection parameters. The ' .env' file contains the following:

Which of the following code snippets demonstrates the most secure and recommended method for creating a Snowpark session using these environment variables and also ensuring the file exists?
Answer: E
Explanation:
Option D is the most robust because it explicitly checks for the existence of the .env' file using 'pathlib' before attempting to load it, raising a FileNotFoundError' if it's missing, AND it utilizes 'os.environ.get()' which is safer than directly accessing 'os.environ[]" because it returns if the environment variable doesn't exist, preventing 'KeyError' exceptions, although in this case the .env' file not being present is detected. Options A, B, C and E don't proactively check for file existence prior to opening, and could thus potentially fail or crash the Snowpark session, or could inadvertently utilize invalid default values, which could lead to unexpected or incorrect behavior. Providing default values (Option E) might mask configuration errors.
NEW QUESTION # 241
......
We all know that the importance of the SPS-C01 certification exam has increased. Many people remain unsuccessful in its SPS-C01 exam because of using invalid SPS-C01 practice test material. If you want to avoid failure and loss of money and time, download actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) Questions of Braindumpsqa. This Snowflake SPS-C01 exam preparation material is important because it will help you cover each topic and understand it well.
SPS-C01 Unlimited Exam Practice: https://www.braindumpsqa.com/SPS-C01_braindumps.html
- 100% Pass-Rate Training SPS-C01 Material - Passing SPS-C01 Exam is No More a Challenging Task 🤥 Open ( www.prepawaypdf.com ) enter ⏩ SPS-C01 ⏪ and obtain a free download 🍶Official SPS-C01 Practice Test
- SPS-C01 Free Exam 🎰 SPS-C01 Exam Assessment ☎ SPS-C01 Reliable Exam Questions 🤬 Open website ▛ www.pdfvce.com ▟ and search for 《 SPS-C01 》 for free download 🏎SPS-C01 Fresh Dumps
- Instant SPS-C01 Download 👯 Latest Test SPS-C01 Simulations 〰 SPS-C01 Reliable Test Book 👊 Open [ www.verifieddumps.com ] and search for ✔ SPS-C01 ️✔️ to download exam materials for free 🛰New SPS-C01 Test Sample
- 2026 Realistic Training SPS-C01 Material - Snowflake Training Snowflake Certified SnowPro Specialty - Snowpark Material 100% Pass Quiz 🚠 Copy URL 「 www.pdfvce.com 」 open and search for ➽ SPS-C01 🢪 to download for free 🦔Instant SPS-C01 Download
- Valid SPS-C01 Test Duration 🔳 SPS-C01 Reliable Exam Questions 🎀 SPS-C01 Reliable Exam Questions 🏩 Search for ▶ SPS-C01 ◀ and download it for free on [ www.vce4dumps.com ] website 🍗SPS-C01 Test Dumps
- Pass Guaranteed 2026 SPS-C01: Snowflake Certified SnowPro Specialty - Snowpark Perfect Training Material 🤳 Search for ▷ SPS-C01 ◁ and download exam materials for free through [ www.pdfvce.com ] 💗Detailed SPS-C01 Study Plan
- Pass Guaranteed Quiz Snowflake - SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Newest Training Material 🗾 The page for free download of “ SPS-C01 ” on ⇛ www.prepawayexam.com ⇚ will open immediately 😑Reliable SPS-C01 Test Sample
- Latest Test SPS-C01 Simulations 🐯 Exam SPS-C01 Collection Pdf 📱 Instant SPS-C01 Download 🥞 Search for ☀ SPS-C01 ️☀️ and obtain a free download on 「 www.pdfvce.com 」 ▶Detailed SPS-C01 Study Plan
- Instant and Proven Way to Crack Snowflake SPS-C01 Exam ♣ Copy URL ⮆ www.vce4dumps.com ⮄ open and search for ▛ SPS-C01 ▟ to download for free 🎌SPS-C01 Reliable Exam Questions
- SPS-C01 Exam Assessment 🍩 Official SPS-C01 Practice Test 🍛 SPS-C01 Reliable Exam Questions ℹ Download “ SPS-C01 ” for free by simply searching on ➥ www.pdfvce.com 🡄 😖SPS-C01 Reliable Braindumps Pdf
- Free PDF Quiz Valid Snowflake - SPS-C01 - Training Snowflake Certified SnowPro Specialty - Snowpark Material 🎏 Copy URL ➽ www.prepawayete.com 🢪 open and search for ➠ SPS-C01 🠰 to download for free 🐳Instant SPS-C01 Download
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, nvinio.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.grepmed.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Braindumpsqa: https://drive.google.com/open?id=1WiE1na3FHvD-fr7XpwAbuJNKJPEQXd5f