The primary reason behind their failures is studying from Snowflake SPS-C01 exam preparation material that is invalid. Due to the massive popularity of the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam, Test4Engine have come forward to offer authentic and real Selling SPS-C01 Exam Questions so that its valued customers can prepare successfully in a short time. The product provided by Test4Engine are available in three formats. These formats contain Snowflake SPS-C01 Exam Questions that are relevant to the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) actual exam. The Selling Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test material for Test4Engine are there to download after your purchase.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 2: Performance and Best Practices | 10% | - Security and governance
|
| Topic 3: Data Transformations and Operations | 35% | - User-defined logic
|
| Topic 4: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
If you visit our website Test4Engine, then you will find that our SPS-C01 practice questions are written in three different versions: PDF version, Soft version and APP version. All types of SPS-C01 training questions are priced favorably on your wishes. Obtaining our SPS-C01 Study Guide in the palm of your hand, you can achieve a higher rate of success. Besides, there are free demos of our SPS-C01 learning guide for your careful consideration to satisfy individual needs.
NEW QUESTION # 329
You have a Python function that calculates a complex statistical measure on a given row of a DataFrame. You want to apply this function to each row of a Snowpark DataFrame in a distributed manner. Which of the following is the MOST efficient way to achieve this?
Answer: C
Explanation:
Pandas UDFs (User-Defined Functions) are designed for efficient row-wise operations on Snowpark DataFrames. The @pandas_udf decorator enables Snowpark to execute the function in a distributed manner across Snowflake's compute resources, maximizing performance for row-by-row calculations. 'apply' method doesn't exist directly on Snowpark DataFrames. Iterating through rows (Option C) is extremely inefficient. Option D involves RDD which is not exposed directly with Snowpark DataFrames. While option E is an alternative it introduces unnecessary overhead.
NEW QUESTION # 330
A data engineer is tasked with calculating a 3-month rolling average of sales data using Snowpark Python. The sales data is stored in a table named 'SALES DATA' with columns 'sale_date' (DATE) and (NUMBER). They need to use a table function to accomplish this efficiently. Which of the following Snowpark Python code snippets correctly implements this rolling average calculation using a table function?





Answer: B
Explanation:
Option E correctly defines a table function that takes a DataFrame as input and returns a DataFrame with the rolling average calculated using the 'avg()' function and a window specification. It then uses 'session.table_function' to apply the table function to the DataFrame and selects the required columns. Option A attempts to call directly within the table function definition which is invalid. Option B passes 'session' as the first argument to table function that's wrong. Option C defines that aren't compatible with DataFrame operations, this approach is not how you should do. Option D is same as C, and incorrect because, it attempts to use window functions inside the table function where the input is a table function input types.
NEW QUESTION # 331
You are using Snowpark Python to process a DataFrame containing customer data,. One of the columns, 'phone_number' , contains phone numbers in various formats (e.g., '123-456-7890', '(123) 456-7890', '1234567890'). You need to standardize these phone numbers to the format 'XXX-XXX-XXXX' using a User-Defined Function (UDF). You want to create a UDF called 'standardize_phone_number' that takes a string as input and returns the standardized phone number. Which of the following code snippets correctly defines and registers this UDF in Snowpark, and applies it to the 'phone_number' column of the 'customer df DataFrame? Assume a Snowflake session object called 'session' is already available.





Answer: D
Explanation:
Option E is the most concise and correct way to define and use the UDF. It uses the '@F.udf decorator, which simplifies the UDF registration process. It also correctly imports 'snowflake.snowpark.functions as F to use the decorator. Options A and D are less efficient because they use 'call_udf instead of directly calling the UDF. Option B registers UDF but does not import required libraries. Option C doesn't import necessary library for the functions.
NEW QUESTION # 332
You are developing a Snowpark application that performs complex data transformations on a large dataset using a UDF written in Scala.
After deploying the application, you observe that the performance is significantly slower than expected. Analyzing the query history in Snowflake, you identify that the UDF execution time is unusually high. Which of the following actions would be MOST effective in improving the performance of the UDF, considering Snowpark's execution context and Snowflake's query processing?
Answer: A,C
Explanation:
Using vectorized UDFs allows processing data in batches, significantly reducing overhead. Returning smaller datatypes optimizes I/O and memory usage. While increasing the warehouse size might offer some improvement, it doesn't directly address the UDF's inefficiency. Snowpark session memory is more relevant for the driver program and less so for the execution of the UDF within Snowflake's environment. SQL Stored procedures are useful but for functions already supported in SQL; vectorized UDFs provide a path fomard for scala code.
NEW QUESTION # 333
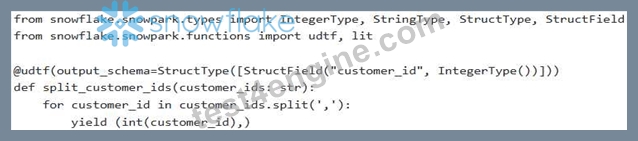
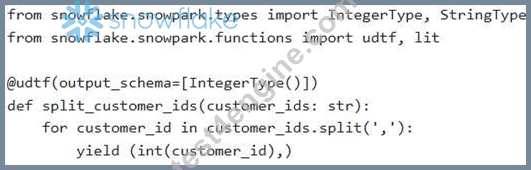
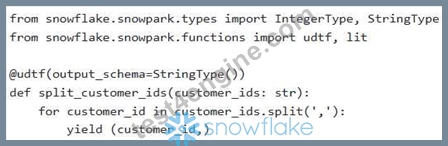
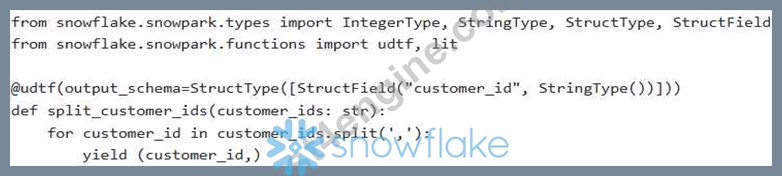
You are tasked with creating a UDTF using Snowpark Python that splits a comma-separated string of customer IDs into individual rows. The input is a string (VARCHAR) and the output should be a table with a single column named 'customer_id' of type INTEGER. Which of the following code snippets CORRECTLY defines and registers the UDTF, ensuring proper data type handling? Assume is a valid Snowpark Session object.
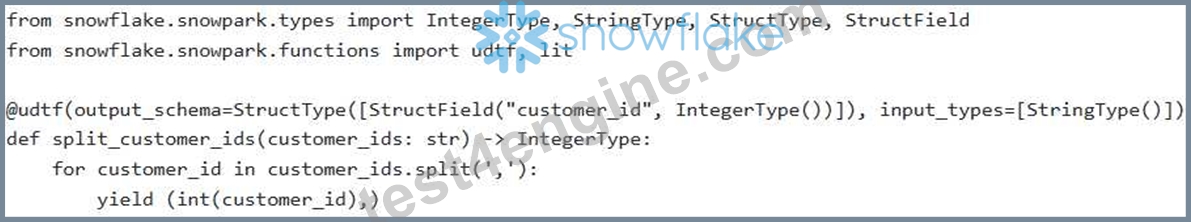
Answer: A
Explanation:
Option B correctly defines the UDTF. It uses 'StructType' and to define the output schema with a column named 'customer_id' of type "Integer Type'. The code also correctly converts the customer ID to an integer before yielding it. Option A defines the output schema as 'StringType' , which is incorrect. Option C does not correctly define a column name. Option D uses 'StringType' for the column, which violates the requirements. Option E adds and a return annotation which are valid, but the structure of the annotation is still not correct for a UDTF.
NEW QUESTION # 334
......
As the most important element that almost all the candidates will take into consider, the pass rate of our SPS-C01 exam questions is high as 98% to 100%, which is unique in the market and no one has made it. And also the exam passing guarantee that makes our SPS-C01 Study Guide superior in the market. As the best seller, our SPS-C01 learning braindumps are very popular among the candidates. Many of the loyal customers are introduced by their friends or classmates.
SPS-C01 Answers Real Questions: https://www.test4engine.com/SPS-C01_exam-latest-braindumps.html