P.S. Kostenlose und neue DP-700 Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=1LDiH6v2JPtJG7eepGSowlG0LS7Oud8gT
Sind Sie neugierig, warum so viele Menschen die schwierige Microsoft DP-700 Prüfung bestehen können? Ich können Sie beantworten. Der Kunstgriff ist, dass Sie haben die Prüfungsunterlagen der Microsoft DP-700 von unsere ZertSoft benutzt. Wir bieten Ihnen: reichliche Prüfungsaufgaben, professionelle Untersuchung und einjährige kostenlose Aktualisierung nach dem Kauf. Mit Hilfe der Microsoft DP-700 Prüfungsunterlagen können Sie wirklich die Erhöhung Ihrer Fähigkeit empfinden. Sie können auch das echte Zertifikat der Microsoft DP-700 erwerben!
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
Obwohl es auch andere Online- Prüfungsmaterialien zur Microsoft DP-700 Zertifizierungsprüfung auf dem Markt gibt, sind die Schulungsunterlagen zur Microsoft DP-700 Zertifizierungsprüfung von ZertSoft am besten. Weil wir ständig die genauen Materialien zur Microsoft DP-700 Zertifizierungsprüfung aktualisieren. Außerdem bietet ZertSoft Ihnen einen einjährigen kostenlosen Update-Service. Sie können die neuesten Prüfungsunterlagen zur Microsoft DP-700 Zertifizierung bekommen.
41. Frage
You have a Fabric workspace.
You plan to deploy two Apache Spark environments that will each contain one of the following notebooks:
* Notebook 1: A data ingestion notebook that will run as a scheduled Spark job
* Notebook2; An ad hoc notebook for interactive data analysis that will be used by a team of analysts and data scientists You need to configure the Spark environments to meet the following requirements:
* For the environment that contains Notebook 1, minimize compute costs.
* For the environment that contains Notebook2, support multiple concurrent users.
What should you use for each environment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.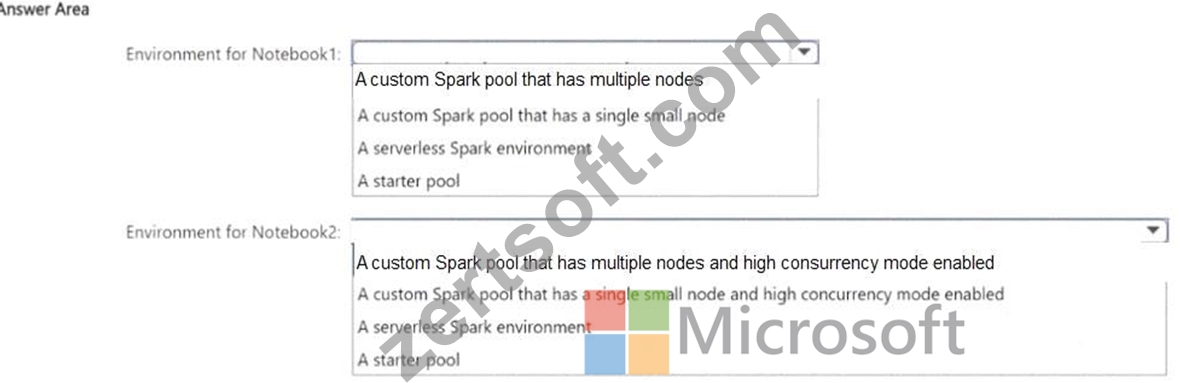
Antwort:
Begründung: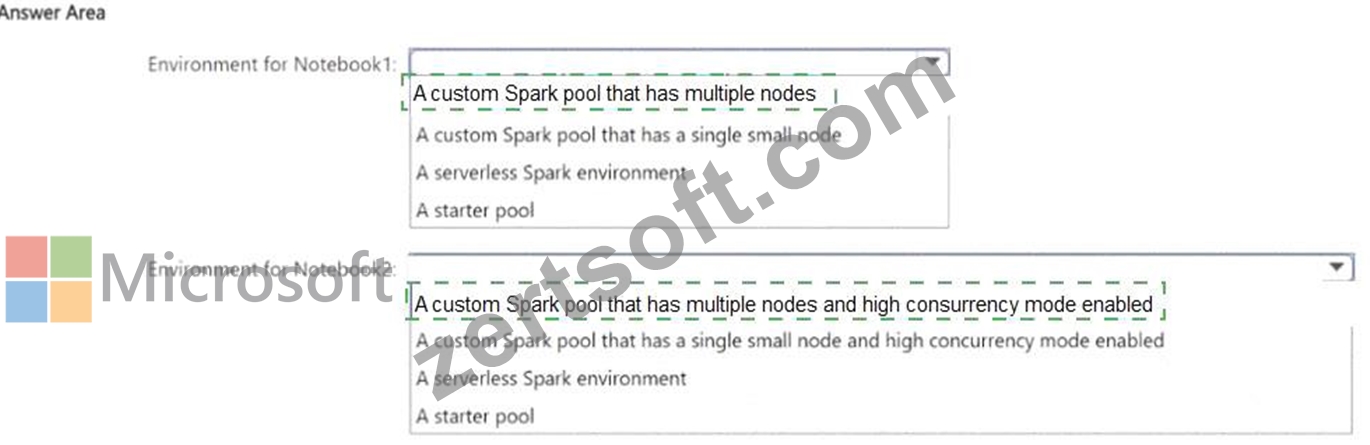
Explanation: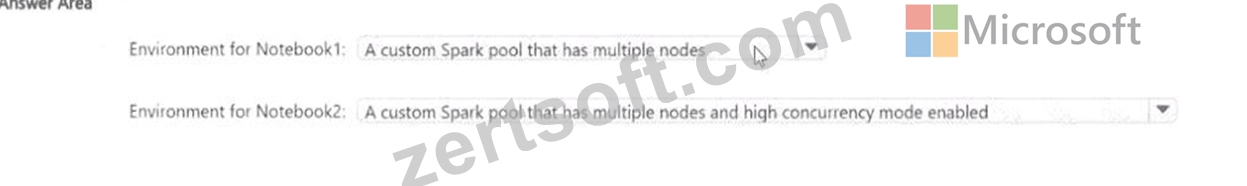
42. Frage
You have a Fabric deployment pipeline that uses three workspaces named Dev, Test, and Prod.
You need to deploy an eventhouse as part of the deployment process.
What should you use to add the eventhouse to the deployment process?
Antwort: A
Begründung:
A deployment pipeline in Fabric is designed to automate the process of deploying assets (such as reports, datasets, eventhouses, and other objects) between environments like Dev, Test, and Prod. Since you need to deploy an eventhouse as part of the deployment process, a deployment pipeline is the appropriate tool to move this asset through the different stages of your environment.
Topic 1, Litware, IncCase Study
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide.
Litware also manages an online advertising business for the authors it represents.
Existing Environment. Fabric Environment
Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
The company has a data engineering team that uses Python for data processing.
Existing Environment. Data Processing
The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse.
Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
Litware has i mag e files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
Existing Environment. Sales Data
Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
In the source system, the sales data refreshes every six hours starting at midnight each day.
The sales data is captured in a Dataflow Gen1 dataflow. When the dataflow runs, new and historical data is captured. The dataflow captures the following fields of the source:
Sales Date
Author
Price
Units
SKU
A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
Existing Environment. Security Groups
Litware has the following security groups:
Sales
Fabric Admins
Streaming Admins
Existing Environment. Performance Issues
Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: "The SQL query failed while running." The data engineering team wants to debug the issue and find queries that cause more than one failure.
When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
The company's sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
Requirements. Planned Changes
Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
Requirements. Version Control
Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
Requirements. Governance Requirements
To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
Requirements. Data Requirements
Litware identifies the following data requirements:
Process the SEO data in near-real-time (NRT).
Make the book reviews available in the lakehouse without making a copy of the data.
When a new book cover image arrives in the Files folder, process the image as soon as possible.
43. Frage
You have an Azure subscription that contains a blob storage account named sa1. Sa1 contains two files named Filelxsv and File2.csv.
You have a Fabric tenant that contains the items shown in the following table.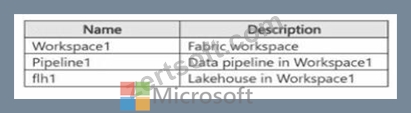
You need to configure Pipeline1 to perform the following actions:
* At 2 PM each day, process Filel.csv and load the file into flhl.
* At 5 PM each day. process File2.csv and load the file into flhl.
The solution must minimize development effort. What should you use?
Antwort: A
44. Frage
You need to recommend a method to populate the POS1 data to the lakehouse medallion layers.
What should you recommend for each layer? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.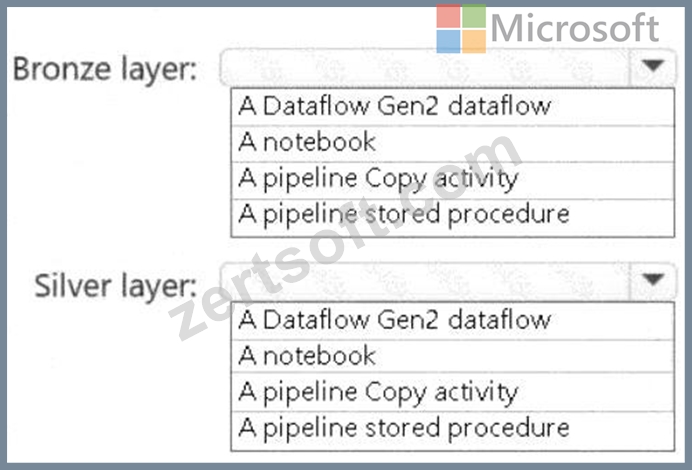
Antwort:
Begründung: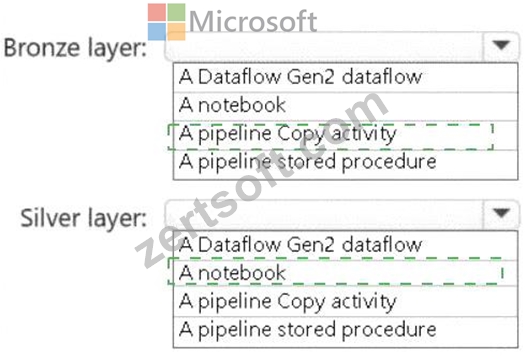
Explanation:
A screenshot of a computer Description automatically generated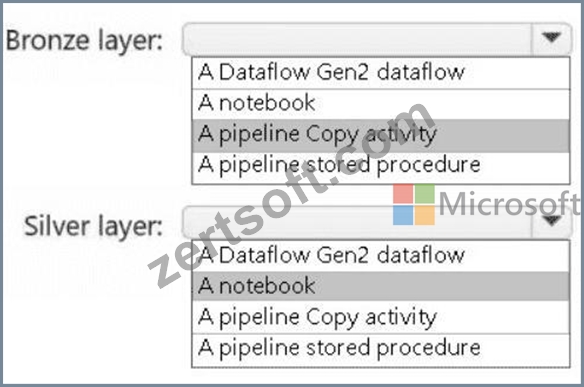
Bronze Layer: A pipeline Copy activity
The bronze layer is used to store raw, unprocessed data. The requirements specify that no transformations should be applied before landing the data in this layer. Using a pipeline Copy activity ensures minimal development effort, built-in connectors, and the ability to ingest the data directly into the Delta format in the bronze layer.
Silver Layer: A notebook
The silver layer involves extensive data cleansing (deduplication, handling missing values, and standardizing capitalization). A notebook provides the flexibility to implement complex transformations and is well-suited for this task.
45. Frage
You have an Azure Data Lake Storage Gen2 account named storage1 and an Amazon S3 bucket named storage2.
You have the Delta Parquet files shown in the following table.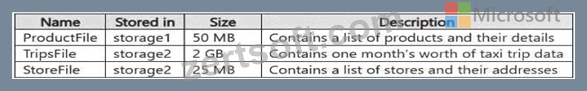
You have a Fabric workspace named Workspace1 that has the cache for shortcuts enabled. Workspace1 contains a lakehouse named Lakehouse1. Lakehouse1 has the following shortcuts:
A shortcut to ProductFile aliased as Products
A shortcut to StoreFile aliased as Stores
A shortcut to TripsFile aliased as Trips
The data from which shortcuts will be retrieved from the cache?
Antwort: B
Begründung:
When the cache for shortcuts is enabled in Fabric, the data retrieval is governed by the caching behavior, which generally retains data for a specific period after it was last accessed. The data from the shortcuts will be retrieved from the cache if the data is stored in locations that support caching. Here's a breakdown based on the data's location:
Products: The ProductFile is stored in Azure Data Lake Storage Gen2 (storage1). Since Azure Data Lake is a supported storage system in Fabric and the file is relatively small (50 MB), this data is most likely cached and can be retrieved from the cache.
Stores: The StoreFile is stored in Amazon S3 (storage2), and even though it is stored in a different cloud provider, Fabric can cache data from Amazon S3 if caching is enabled. This data (25 MB) is likely cached and retrievable.
Trips: The TripsFile is stored in Amazon S3 (storage2) and is significantly larger (2 GB) compared to the other files. While Fabric can cache data from Amazon S3, the larger size of the file (2 GB) may exceed typical cache sizes or retention windows, causing this file to likely be retrieved directly from the source instead of the cache.
46. Frage
......
Nun gibt es viele IT-Profis in der ganzen Welt und die Konkurrenz der IT-Branche ist sehr hart. So viele IT-Profis entscheiden sich dafür, an der IT-Zertifizierungsprüfung teilzunehmen, um ihre Position in der IT-Branche zu verstärken. Die DP-700 Prüfung ist eine sehr wichtige Microsoft-Zertifizierungsprüfung. Aber wenn Sie eine Microsoft-Zertifizierung erhalten wollen, müssen Sie die Prüfung bestehen.
DP-700 Prüfungsübungen: https://www.zertsoft.com/DP-700-pruefungsfragen.html
BONUS!!! Laden Sie die vollständige Version der ZertSoft DP-700 Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1LDiH6v2JPtJG7eepGSowlG0LS7Oud8gT