2026 Latest Lead2PassExam SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1DQPAV8_TJMFPAiRrJBXd7fJVi-OJ0xdo
Among all learning websites providing IT certification SPS-C01 dumps and training methods, whose SPS-C01 exam dumps and training materials are the most reliable? Of course, SPS-C01 exam dumps and certification training questions on Lead2PassExam site are the most reliable. Our Lead2PassExam have professional team, certification experts, technician and comprehensive language master, who always research the Latest SPS-C01 Exam Dumps and update SPS-C01 certification training material, so you can be fully sure that our SPS-C01 test training materials can help you pass the SPS-C01 exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API for Python | 30% | - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - DataFrame creation and manipulation - Establishing connections and session management |
| Topic 2: Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Complex data pipelines - Window functions - Persisting transformed data - Using built-in functions |
| Topic 3: Performance Optimization and Best Practices | 20% | - Caching strategies - Query pushdown and optimization - Warehouse sizing for Snowpark - Vectorized UDFs - Minimizing data transfer - Debugging and explain plans |
| Topic 4: Snowpark Concepts | 15% | - Snowpark Sessions and connection management - Stored procedures and conditional logic - Snowpark DataFrames and query plans - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark architecture and core concepts |
>> SPS-C01 Valid Exam Registration <<
Our SPS-C01 Exam Dumps with the highest quality which consists of all of the key points required for the SPS-C01 exam can really be considered as the royal road to learning. Lead2PassExam has already become a famous brand all over the world in this field since we have engaged in compiling the SPS-C01 practice materials for more than ten years and have got a fruitful outcome. You are welcome to download the free demos to have a general idea about our SPS-C01 training materials.
NEW QUESTION # 233
You are working with a Snowpark DataFrame 'products_df' that contains product information, including 'product_name', 'category', and 'price'. You need to perform several transformations: 1. Rename the 'product_name' column to 'item_name'. 2. Create a new column 'discounted_price' by applying a 10% discount to the 'price' column. 3. Filter the DataFrame to only include products in the 'Electronics' category where the 'discounted_price' is less than 100. Which of the following code sequences correctly and efficiently performs these transformations in Snowpark?





Answer: C
Explanation:
Option D is the most efficient. Option D is correct because it renames the column first, then filters for 'Electronics', creates the 'discounted_price' column, and finally filters based on the discounted price being less than 100, all correctly chained. Other options will not perform transformation correctly or not follow the correct sequence.
NEW QUESTION # 234
You are working with semi-structured data in Snowflake stored in a VARIANT column named 'payload'. You want to extract specific fields from this VARIANT column within a SQL query used to create a Snowpark DataFrame. Which of the following approaches allows you to access nested fields within the 'payload' column directly in the SQL query and create a corresponding column in your Snowpark DataFrame? Select all that apply.
Answer: A,C,D
Explanation:
Options A, B, and D are correct. Option A utilizes the Snowflake's native dot notation (e.g., 'payload:fieldl :field2) for direct access of nested fields. Option B provides the 'GET_PATH' function, also allowing access to nested fields. Option D leverages 'LATERAL FLATTEN' to unnest the VARIANT data, enabling subsequent field access. Option C is less efficient, adding unnecessary steps, and Option E involves Pandas, which is typically not the optimal path for leveraging Snowpark's capabilities directly. Remember that 'LATERAL FLATTEN' is best when you need to process the data in a relational format after extracting it from the VARIANT.
NEW QUESTION # 235
You have a Snowpark application that processes sensor data from a large number of devices. You've implemented a scalar UDF in Python to calculate a complex statistical metric for each sensor reading. Initial tests show poor performance. Which of the following strategies would be MOST effective in improving the performance of this application, considering the nature of the computation and the data volume?
Answer: C
Explanation:
Vectorized UDFs process data in batches (vectors), significantly reducing the overhead associated with individual row processing, which is the primary bottleneck of scalar UDFs. While increasing warehouse size (C) might provide some improvement, it doesn't address the fundamental inefficiency of scalar processing. Java might be faster (A), but the biggest gain comes from vectorization. Caching (D) is useful for repeated calculations, but doesn't address the inherent UDF overhead if computations are unique. SQL (E) is good, but might not be possible due to the complexity.
NEW QUESTION # 236
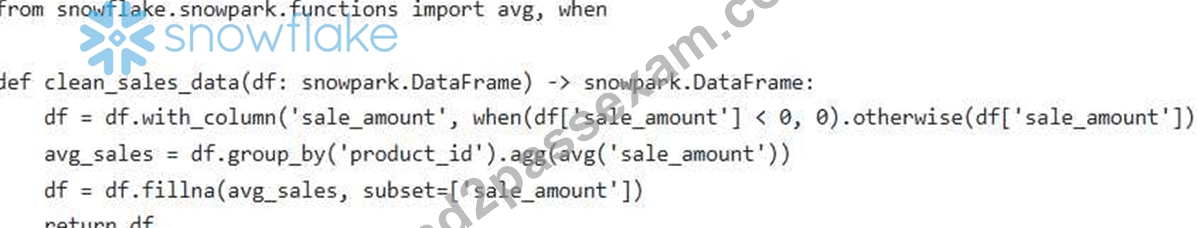
You have a Snowpark DataFrame with columns 'product_id', 'customer_id', and 'sale_amount'. Some values are negative, indicating returns, and others are null. You need to replace negative values with 0 and fill null values with the average 'sale_amount' for each 'product_id'. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark?
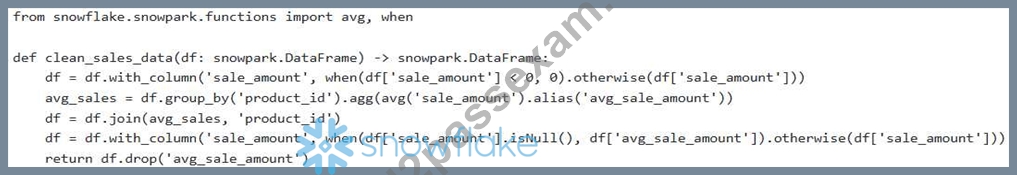
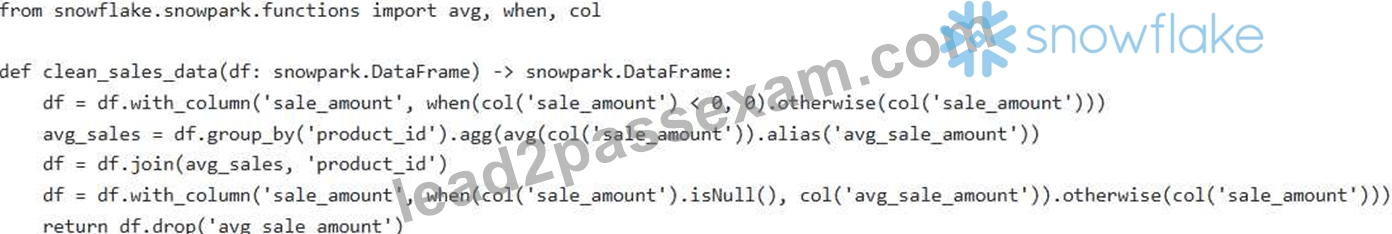
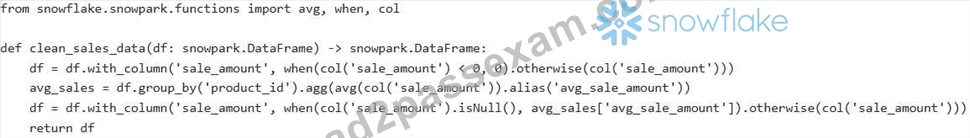
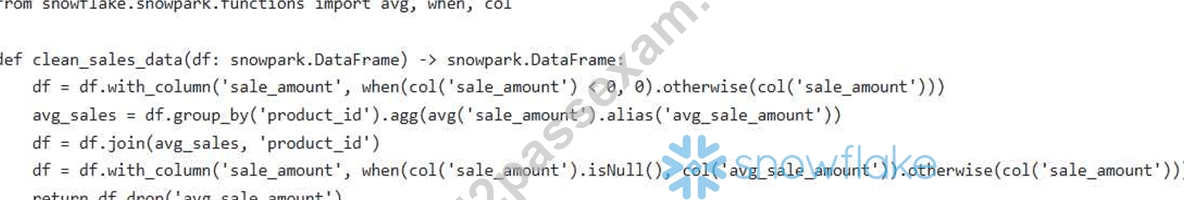
Answer: B
Explanation:
Option E first replaces negative values with 0. Then, it calculates the average sales amount per product and joins it back to the original DataFrame. Finally, it fills null values with the calculated average sales amount and drops the temporary column. This is efficient because it utilizes Snowpark's DataFrame operations. other options does not handle nulls or gives errors.
NEW QUESTION # 237
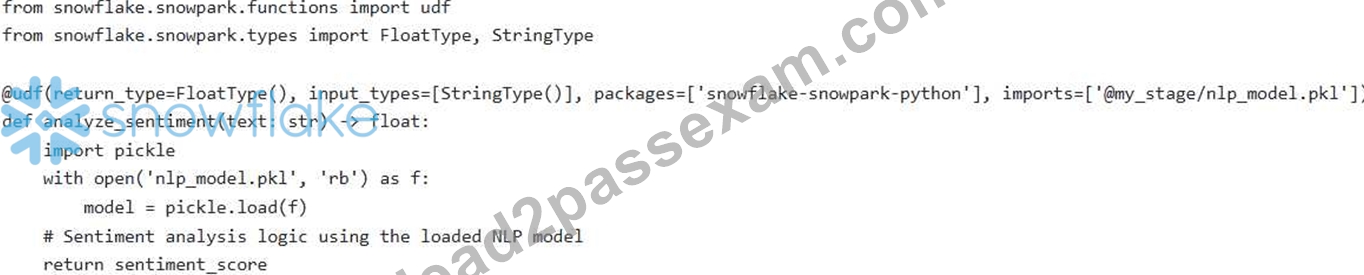
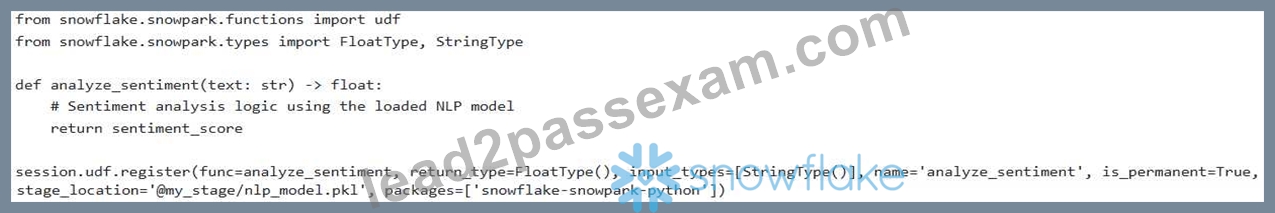
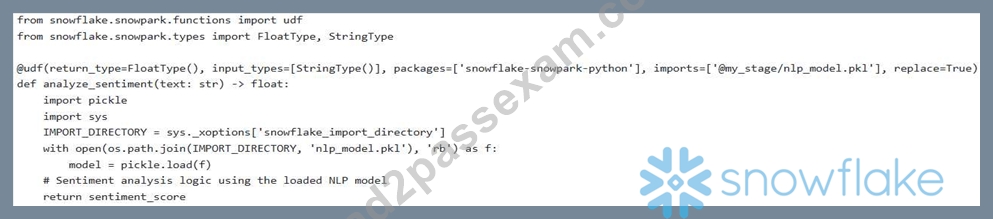
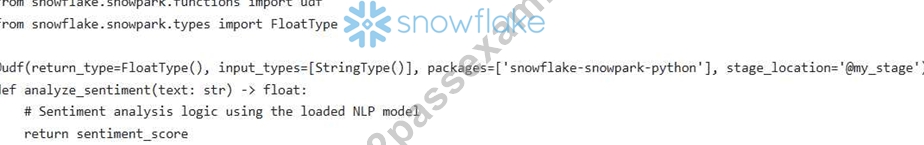
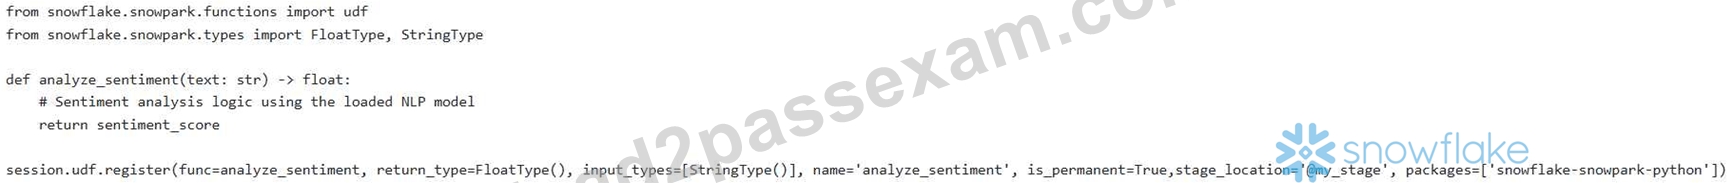
You are developing a Snowpark application to process customer sentiment from text reviews. You have a Python function, , that utilizes a pre-trained NLP model loaded from a file on a Snowflake stage named This function returns a sentiment score (float) between -1 and 1. You need to register this function as a UDF so that it can be used within Snowpark DataFrames. Which of the following code snippets correctly registers the UDF, ensuring the NLP model is available to the function during execution?
Answer: C
Explanation:
Option E correctly uses the '@udf decorator with the 'imports' parameter to specify the location of the pickled model on the stage. It also uses to correctly construct the path to the imported file within the UDF's execution environment. Replace=True prevents errors if the UDF already exists. Options A, C and D don't correctly handle importing the NLP model. Option B has a security issue of loading file without validating the Path.
NEW QUESTION # 238
......
SPS-C01 latest study guide is the trustworthy source which can contribute to your actual exam test. If you are not sure about to pass your exam, you can rely on the SPS-C01 practice test for 100% pass. Snowflake SPS-C01 free pdf cram simulate the actual test, with the study of it, you can get a general understanding at first. After further practice with Lead2PassExam SPS-C01 Original Questions, you will acquire the main knowledge which may be tested in the actual test. At last, a good score is a little case.
Test SPS-C01 Online: https://www.lead2passexam.com/Snowflake/valid-SPS-C01-exam-dumps.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Lead2PassExam: https://drive.google.com/open?id=1DQPAV8_TJMFPAiRrJBXd7fJVi-OJ0xdo