Mit der Hilfe von ZertSoft brauchen Sie nicht so viel Geld für die Kurse oder viel Zeit und Energie für die Prüfung auszugeben. Sie können ganz einfach die Microsoft DP-750 (Implementing Data Engineering Solutions Using Azure Databricks)Prüfung erfolgreich ablegen. Die Software zur Microsoft DP-750 Zertifizierungsprüfung wird ZertSoft nach den echten Prüfungen in den letzten Jahren erforscht. Die Fragen und Antworten zur Microsoft DP-750 Zertifizierungsprüfung von ZertSoft sind den realen Fragen und Antworten sehr ähnlich.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 4: Prepare and process data | 30-35% | - Data ingestion
|
Wollen Sie Ihre IT-Fähigkeiten in kürzester Zeit erhöhen, aber zugleich sorgen Sie noch darum, dass Ihnen geeignete Lernmaterialien fehlen? Machen Sie jetzt keine Sorgen, denn solange Sie über die Fragenkataloge zur Microsoft DP-750 Zertifizierungsprüfung von ZertSoft verfügen, können Sie mit jeder IT-Prüfung leicht fertig werden. Unsere Fragenkataloge zur Microsoft DP-750 Zertifizierungsprüfung sind von den erfahrenen IT-Experten durch langjährige ständige Untersuchung und Erforschung bearbeitet. ZertSoft wird Ihre beste Wahl sien.
39. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Antwort: C
40. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data.
You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Antwort: D
Begründung:
To prevent your Apache Spark Structured Streaming job from reprocessing previously ingested data after a cluster restart, you must configure a streaming checkpoint directory.
Core Solution
Enable Checkpointing: Define the checkpointLocation option in your streaming write configuration.
Track Progress: Spark uses this directory to save the exact offset ranges of processed data.
Automatic Recovery: Upon restart, the engine reads the checkpoint and resumes precisely where it left off.
Implementation Example in python
# Configure the streaming write with a checkpoint path
(df.writeStream
.format("delta")
.outputMode("append")
.option("checkpointLocation",
"/Volumes/catalog/schema/volume_name/checkpoints/job_name")
.toTable("catalog.schema.target_table"))
Reference:
https://medium.com/@salah.uddin_75300/architecture-of-a-streaming-machine-learning-data- pipeline-042200c8e7ff
41. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Antwort: B
Begründung:
Repairing the current job run allows Lakeflow Jobs to rerun the failed task while preserving the successful status of tasks that already completed. This prevents several hours of successful processing from being repeated and reduces both recovery time and compute consumption. If downstream tasks had been skipped because of the failure, they can also be included in the repair operation as appropriate. Updating job parameters changes configuration but does not retry the failed task in the existing run. Restarting Job1 creates a new run and ordinarily executes the workflow again from its beginning. Disabling and reenabling the schedule only changes whether future scheduled runs can start; it does not repair the failed execution. Repair Run is specifically designed for recovering selected failed or skipped tasks in a multi-task workflow.
42. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.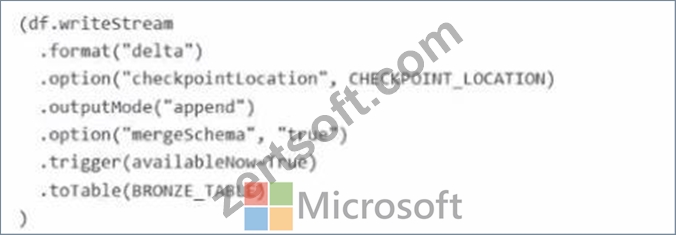
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.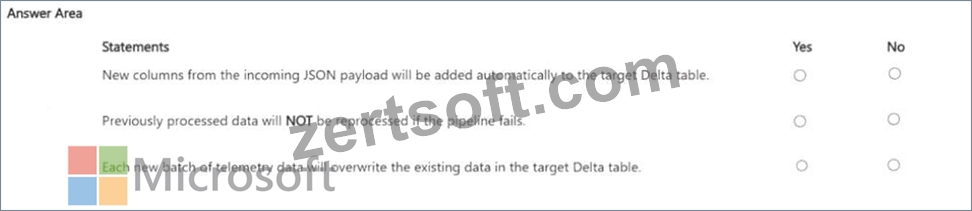
Antwort:
Begründung: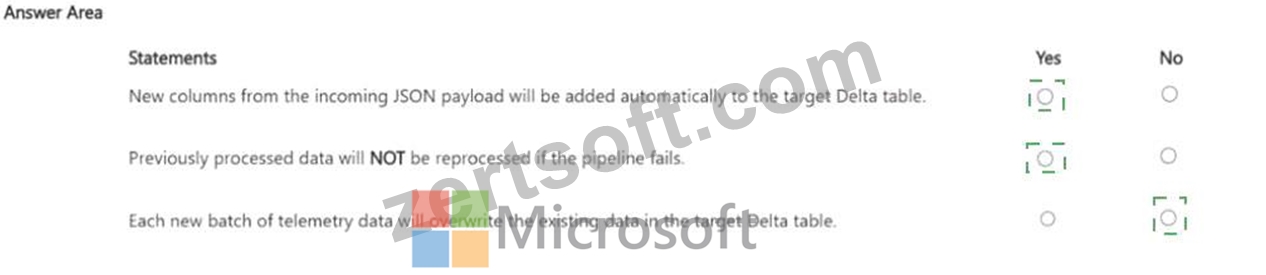
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
43. Frage
Which feature provides end-to-end tracking of data movement in Databricks?
Antwort: B
Begründung:
Unity Catalog provides data lineage tracking across ingestion, transformation, and consumption layers. It helps visualize dependencies and compliance auditing. Spark logs are low-level and not structured for lineage. Query history is partial only.
44. Frage
......
ZertSoft spezialisiert sich auf die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung. Mit ZertSoft brauchen Sie sich keine Sorgen für die Microsoft DP-750 Zertifizierungsprüfung zu machen. Die Zertifizierungsantworten von ZertSoft sind qualitativ hochwertig. Sobald Sie ZertSoft wählen, können Sie in kurzer Zeit die Prüfung mit einer hohen Note die Microsoft DP-750 Zertifizierungsprüfung effizient bestehen und bessere Resultate bei weniger Einsatz erzielen.
DP-750 Lernressourcen: https://www.zertsoft.com/DP-750-pruefungsfragen.html