さらに、CertShiken Databricks-Generative-AI-Engineer-Associateダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1wN8pH9vDtdlCCNajonEYby-zvJG-6VDH
CertShikenがもっと早くDatabricksのDatabricks-Generative-AI-Engineer-Associate認証試験に合格させるサイトで、DatabricksのDatabricks-Generative-AI-Engineer-Associate認証試験についての問題集が市場にどんどん湧いてきます。あなたがまだ専門知識と情報技術を証明しています強い人材で、CertShikenのDatabricksのDatabricks-Generative-AI-Engineer-Associate認定試験について最新の試験問題集が君にもっとも助けていますよ。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
>> Databricks-Generative-AI-Engineer-Associate資格準備 <<
CertShiken1年以内にDatabricks-Generative-AI-Engineer-Associate試験問題の更新を無料で提供し、購入者が1年後にサービス保証を延長したい場合は50%の割引特典を提供します。古いクライアントは、他の試験教材を購入する際に、ある程度の割引を受けています。 Databricks-Generative-AI-Engineer-Associateガイドトレントを頻繁に更新し、理論と実践の最新動向を反映した最新の学習資料を提供します。したがって、Databricks-Generative-AI-Engineer-Associateテストガイドを十分にマスターし、試験に合格することができます。メリットを享受しながら、試験に合格することができます。お気軽にDatabricks-Generative-AI-Engineer-Associateガイド急流を購入してください!
質問 # 77
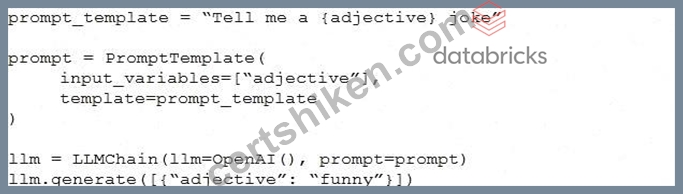
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.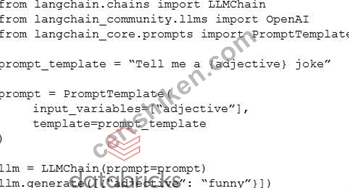
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
正解:A
解説:
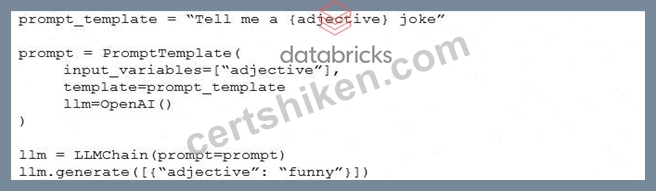
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
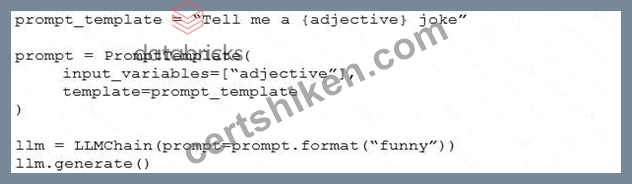
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
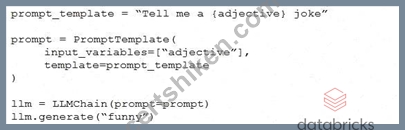
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
質問 # 78
A Generative AI Engineer is designing an LLM-powered live sports commentary platform. The platform provides real-time updates and LLM-generated analyses for any users who would like to have live summaries, rather than reading a series of potentially outdated news articles.
Which tool below will give the platform access to real-time data for generating game analyses based on the latest game scores?
正解:C
解説:
* Problem Context: The engineer is developing an LLM-powered live sports commentary platform that needs to provide real-time updates and analyses based on the latest game scores. The critical requirement here is the capability to access and integrate real-time data efficiently with the platform for immediate analysis and reporting.
* Explanation of Options:
* Option A: DatabricksIQ: While DatabricksIQ offers integration and data processing capabilities, it is more aligned with data analytics rather than real-time feature serving, which is crucial for immediate updates necessary in a live sports commentary context.
* Option B: Foundation Model APIs: These APIs facilitate interactions with pre-trained models and could be part of the solution, but on their own, they do not provide mechanisms to access real- time game scores.
* Option C: Feature Serving: This is the correct answer as feature serving specifically refers to the real-time provision of data (features) to models for prediction. This would be essential for an LLM that generates analyses based on live game data, ensuring that the commentary is current and based on the latest events in the sport.
* Option D: AutoML: This tool automates the process of applying machine learning models to real-world problems, but it does not directly provide real-time data access, which is a critical requirement for the platform.
Thus,Option C(Feature Serving) is the most suitable tool for the platform as it directly supports the real-time data needs of an LLM-powered sports commentary system, ensuring that the analyses and updates are based on the latest available information.
質問 # 79
A Generative AI Engineer is deploying an agent using Mosaic AI Model Serving. The agent needs to access various Databricks resources, including Vector Search, Databricks SQL, and Functions. They need to find the easiest and best-practice way to authenticate the deployed agent to access these resources.
What approach should they choose?
正解:A
質問 # 80
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint's incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
正解:A
解説:
* Problem Context: The goal is to monitor the serving endpoint for incoming requests and outgoing responses in a provisioned throughput model serving endpoint within a Retrieval-Augmented Generation (RAG) application. The current approach involves using a microservice to log requests and responses to a remote server, but the Generative AI Engineer is looking for a more streamlined solution within Databricks.
* Explanation of Options:
Option A: Vector Search: This feature is used to perform similarity searches within vector databases. It doesn't provide functionality for logging or monitoring requests and responses in a serving endpoint, so it's not applicable here.
Option B: Lakeview: Lakeview is not a feature relevant to monitoring or logging request-response cycles for serving endpoints. It might be more related to viewing data in Databricks Lakehouse but doesn't fulfill the specific monitoring requirement.
Option C: DBSQL: Databricks SQL (DBSQL) is used for running SQL queries on data stored in Databricks, primarily for analytics purposes. It doesn't provide the direct functionality needed to monitor requests and responses in real-time for an inference endpoint.
Option D: Inference Tables: This is the correct answer. Inference Tables in Databricks are designed to store the results and metadata of inference runs. This allows the system to log incoming requests and outgoing responses directly within Databricks, making it an ideal choice for monitoring the behavior of a provisioned serving endpoint. Inference Tables can be queried and analyzed, enabling easier monitoring and debugging compared to a custom microservice.
Thus, Inference Tables are the optimal feature for monitoring request and response logs within the Databricks infrastructure for a model serving endpoint.
質問 # 81
A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. Thematch should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.
How should the Generative Al Engineer architect their system?
正解:A
質問 # 82
......
Databricks-Generative-AI-Engineer-Associate試験問題の99%の合格率を確保できます。 Databricks-Generative-AI-Engineer-Associate学習ガイドを使用すると、Databricks-Generative-AI-Engineer-Associate試験に合格できます。そして、Databricksはあなたが想像できる正しいことです。必ずDatabricks-Generative-AI-Engineer-Associate認定を希望します。そこで、Databricks-Generative-AI-Engineer-Associate試験資料と同じくらい優れたツールを使用して、わずか20〜30時間勉強して練習してから試験に合格してみませんか。さまざまなバージョンのDatabricks Certified Generative AI Engineer Associate試験ブレーンダンプを使用すると、いつでもどこでも勉強と練習ができます。
Databricks-Generative-AI-Engineer-Associate対応問題集: https://www.certshiken.com/Databricks-Generative-AI-Engineer-Associate-shiken.html
BONUS!!! CertShiken Databricks-Generative-AI-Engineer-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1wN8pH9vDtdlCCNajonEYby-zvJG-6VDH