Here's a Quick and Proven Way to Pass Databricks Databricks-Machine-Learning-Professional Certification exam

P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by BraindumpStudy: https://drive.google.com/open?id=1Q2WWCwr3OkdC1nftFpHPsOrLtOSU5v_c
In order to cater to different needs of our customers, we have three versions for Databricks-Machine-Learning-Professional exam materials. Each version has its own feature, and you can choose the most suitable one according to your own needs. Databricks-Machine-Learning-Professional PDF version supports print, if you like hard one, you can choose this version and take notes on it. Databricks-Machine-Learning-Professional Online Test engine supports all electronic devices and you can also practice offline. Databricks-Machine-Learning-Professional Soft test engine can stimulate the real exam environment, and you can install this version in more than 200 computers. Just have a look, there is always a version is for you.
| Topic | Details |
|---|
| Topic 1 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 2 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 3 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 4 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 5 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 6 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 7 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 8 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 9 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 10 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 11 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
>> Databricks-Machine-Learning-Professional Valid Exam Experience <<
Databricks Databricks-Machine-Learning-Professional New Exam Camp & Databricks-Machine-Learning-Professional Latest Braindumps Files
BraindumpStudy offers Databricks Databricks-Machine-Learning-Professional exam dumps that every candidate can rely on to get success on the first take. The registration fee for the Databricks Databricks-Machine-Learning-Professional real certification test is considerably expensive. That is why a BraindumpStudy has launched a budget-friendly Databricks-Machine-Learning-Professional updated study material compared to other brands in the market.
Databricks Certified Machine Learning Professional Sample Questions (Q49-Q54):
NEW QUESTION # 49
A data scientist has run the following line of code to create a Feature Store table:
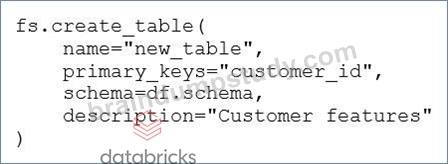
Which statement correctly describes the data in the Feature Store table new_table?
- A. The data in new_table is the customer-related features from df
- B. There is no data in new_table
- C. The data in new_table is the values in column customer_id from df
- D. The data in new_table is exactly the same as the data in df
Answer: B
Explanation:
The fs.create_table() command defines metadata for a Feature Store table, such as its name, primary key, schema, and description - but it does not insert any data into the table. This command simply registers an empty table structure based on the provided schema (df.schema).
To populate the table with data, a separate fs.write_table() or equivalent write operation must be executed afterward.
NEW QUESTION # 50
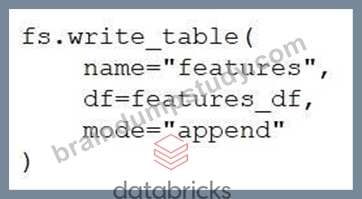
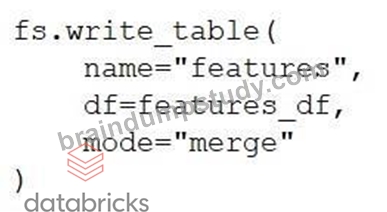
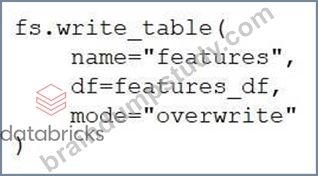
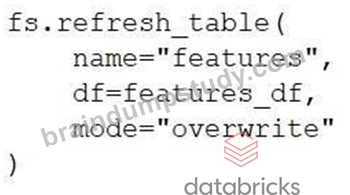
A data scientist has computed updated rows that contain new feature values for primary keys already stored in the Feature Store table features. The updated feature values are stored in the DataFrame features_df. They want to update the rows in features if the associated primary key is in features_df. If a row's primary key is not in features_df, they want the row to remain unchanged in features. Which code block can they use to perform this task using the Feature Store Client fs?
Answer: B
Explanation:
To update existing rows based on primary keys while leaving other rows unchanged, the correct mode to use with fs.write_table() is "merge". This performs an upsert operation - updating rows where keys match and keeping others intact - making it ideal for updating feature values in a Feature Store table.
NEW QUESTION # 51
A Machine Learning Engineer is building a fraud detection model that needs to use both pre- computed features from a feature table and real-time calculated features based on user location data sent with each inference request. The engineer has created a Python UDF called calculate_distance in Unity Catalog at main.fraud_detection.calculate_distance that computes the distance between a transaction location and the user's current location. The feature table main.fraud_detection.user_features contains historical user spending patterns with primary key user_id.
The engineer has written the following code to implement this scenario:
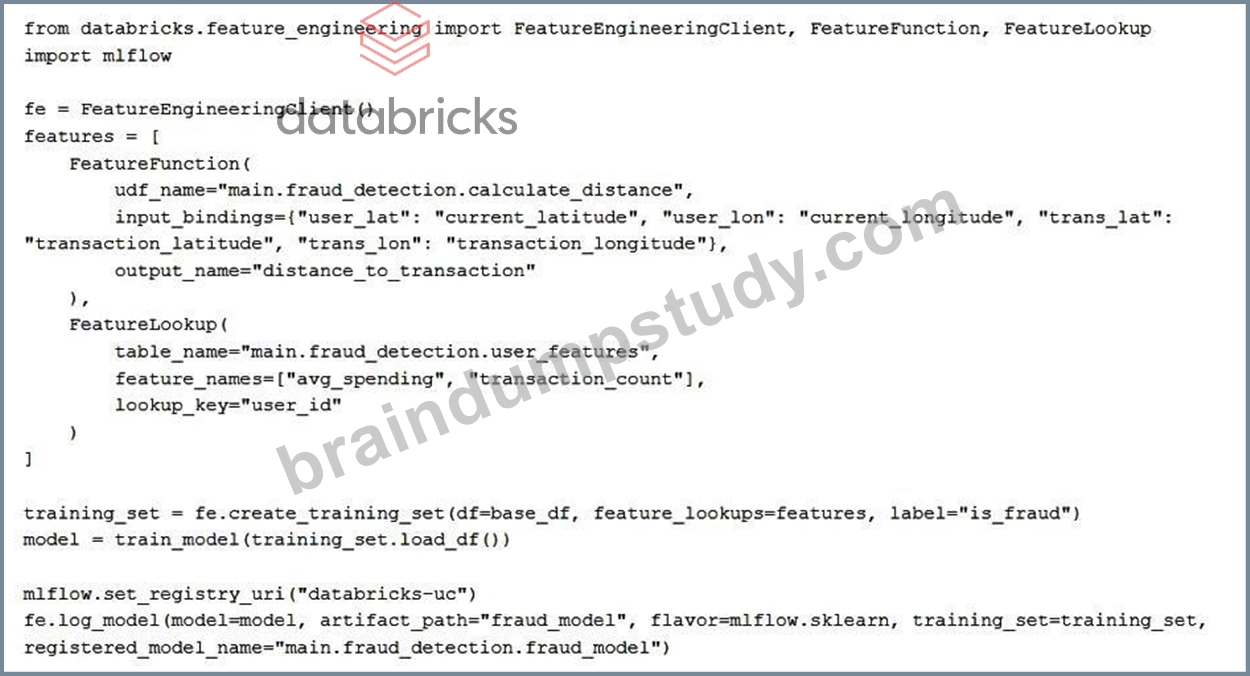
Which benefit of this implementation approach makes it suited to the real-time fraud detection use case?
- A. The Unity Catalog registry automatically creates REST API endpoints for UDF functions used in feature computation.
- B. The model automatically performs feature lookup and computation during inference without additional serving code.
- C. The FeatureLookup function avoids the need for joining the full table main.fraud_detection.user_features with training_set increasing efficiency.
- D. The FeatureFunction caches computed distance values in the online store to improve inference latency for location pairs.
Answer: B
Explanation:
By defining both FeatureLookup and FeatureFunction objects in the training set and logging the model with the FeatureEngineeringClient, the feature logic is packaged with the model. During inference, Databricks automatically performs feature lookups from the feature table and computes the on-demand distance feature using request-time inputs, without requiring any additional custom serving or feature-joining code. This makes the approach well suited for real-time fraud detection.
NEW QUESTION # 52
A machine learning engineer needs to select a deployment strategy for a new machine learning application. The feature values are not available until the time of delivery, and results are needed exceedingly fast for one record at a time. Which of the following deployment strategies can be used to meet these requirements?
- A. Real-time
- B. Batch
- C. Edge/on-device
- D. Streaming
- E. None of these strategies will meet the requirements.
Answer: A
NEW QUESTION # 53
A data scientist wants to remove the star_rating column from the Delta table at the location path. To do this, they need to load in data and drop the star_rating column.
Which of the following code blocks accomplishes this task?
- A. spark.read.format("delta").table(path).drop("star_rating")
- B. spark.read.format("delta").load(path).drop("star_rating")
- C. spark.read.table(path).drop("star_rating")
- D. Delta tables cannot be modified
- E. spark.sql("SELECT * EXCEPT star_rating FROM path")
Answer: C
NEW QUESTION # 54
......
Though our Databricks-Machine-Learning-Professional study guide has three formats which can meet your different needs, PDF version, software version and online version, i love the PDF version to the best. If you choose the PDF version, you can download our Databricks-Machine-Learning-Professional exam material and print it for studying everywhere. And you can take notes on them as long as any new thoughts come to you. If a new version of the Databricks-Machine-Learning-Professional learning guide comes out, we will send you a new link to your E-mail box and you can download it again.
Databricks-Machine-Learning-Professional New Exam Camp: https://www.braindumpstudy.com/Databricks-Machine-Learning-Professional_braindumps.html
- New Databricks-Machine-Learning-Professional Test Experience ☮ Clearer Databricks-Machine-Learning-Professional Explanation 🤴 Valid Exam Databricks-Machine-Learning-Professional Vce Free 🔰 Go to website ➽ www.pdfdumps.com 🢪 open and search for ▶ Databricks-Machine-Learning-Professional ◀ to download for free 🧦Databricks-Machine-Learning-Professional Examcollection Questions Answers
- Databricks-Machine-Learning-Professional Valid Exam Experience | Efficient Databricks Databricks-Machine-Learning-Professional New Exam Camp: Databricks Certified Machine Learning Professional 🤩 Open website [ www.pdfvce.com ] and search for ⇛ Databricks-Machine-Learning-Professional ⇚ for free download 👗Valid Exam Databricks-Machine-Learning-Professional Vce Free
- 2026 Databricks Databricks-Machine-Learning-Professional –Professional Valid Exam Experience 🌜 Open ⇛ www.examcollectionpass.com ⇚ and search for “ Databricks-Machine-Learning-Professional ” to download exam materials for free 👡Test Databricks-Machine-Learning-Professional Preparation
- Quiz Databricks Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Fantastic Valid Exam Experience 📪 Search for ➽ Databricks-Machine-Learning-Professional 🢪 and download it for free on ➠ www.pdfvce.com 🠰 website 🛺Databricks-Machine-Learning-Professional Latest Test Vce
- Databricks-Machine-Learning-Professional VCE Dumps 🧫 Databricks-Machine-Learning-Professional Latest Test Vce ➰ Databricks-Machine-Learning-Professional Reliable Braindumps Sheet 🦪 Immediately open ( www.pdfdumps.com ) and search for ➤ Databricks-Machine-Learning-Professional ⮘ to obtain a free download 📆Databricks-Machine-Learning-Professional Online Training
- Quiz Databricks Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Fantastic Valid Exam Experience 🎶 Download [ Databricks-Machine-Learning-Professional ] for free by simply searching on ➽ www.pdfvce.com 🢪 🤡Databricks-Machine-Learning-Professional Latest Test Vce
- Databricks-Machine-Learning-Professional Reliable Dump 🐹 New Databricks-Machine-Learning-Professional Test Experience 🚇 Databricks-Machine-Learning-Professional Reliable Braindumps Sheet 🩺 Open ➠ www.practicevce.com 🠰 enter { Databricks-Machine-Learning-Professional } and obtain a free download 🌱New Databricks-Machine-Learning-Professional Test Experience
- Free PDF 2026 Databricks Databricks-Machine-Learning-Professional: First-grade Databricks Certified Machine Learning Professional Valid Exam Experience 🏧 Search for ⏩ Databricks-Machine-Learning-Professional ⏪ and easily obtain a free download on 《 www.pdfvce.com 》 🆑New Databricks-Machine-Learning-Professional Test Tutorial
- Pass Guaranteed 2026 Fantastic Databricks Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Valid Exam Experience 🔅 Search for 「 Databricks-Machine-Learning-Professional 」 and download it for free on ✔ www.vceengine.com ️✔️ website 👵Certificate Databricks-Machine-Learning-Professional Exam
- Databricks-Machine-Learning-Professional VCE Dumps 🐛 Databricks-Machine-Learning-Professional Reliable Braindumps Sheet ✌ Databricks-Machine-Learning-Professional Latest Exam Practice 🐒 Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and download it for free on ✔ www.pdfvce.com ️✔️ website ✌Latest Databricks-Machine-Learning-Professional Test Dumps
- 100% Pass 2026 Databricks Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional –Efficient Valid Exam Experience 😑 Copy URL 【 www.troytecdumps.com 】 open and search for ⮆ Databricks-Machine-Learning-Professional ⮄ to download for free ❇Databricks-Machine-Learning-Professional VCE Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.intensedebate.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, aprenderfotografia.online, Disposable vapes
P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by BraindumpStudy: https://drive.google.com/open?id=1Q2WWCwr3OkdC1nftFpHPsOrLtOSU5v_c