P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by DumpExam: https://drive.google.com/open?id=1qN_wyFZcIWwxL47JtMrPSDWfzLK2Zs84
You still can pass the exam with our help. The key point is that you are serious on our Microsoft AI-300 exam questions and not just kidding. Our AI-300 practice engine can offer you the most professional guidance, which is helpful for your gaining the certificate. And our Operationalizing Machine Learning and Generative AI Solutions AI-300 learning guide contains the most useful content and keypoints which will come up in the real exam.
| Section | Objectives |
|---|---|
| Design and implement generative AI solutions | - Large language model integration
|
| Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
| Implement secure and scalable AI systems | - Security and governance
|
>> Reliable AI-300 Learning Materials <<
DumpExam provide you with the comprehensive Microsoft AI-300 Exam information to help you to succeed. Our training materials are the latest study materials which bring by experts. We help you achieve your success. You can get the most detailed and accurate exam questions and answers from us. Our Training Tools are updated in a timely manner in accordance with the changing of Exam Objectives. In fact, the success is not far away, go down along with DumpExam, then you will come to the road to success.
NEW QUESTION # 27
Hotspot Question
A team deploys a generative AI application built by using Microsoft Foundry to production and receives variable traffic throughout the day.
The team requires uninterrupted insight into the application s health and model behavior to detect issues without relying on manual inspection.
You need to select the monitoring capabilities that provide real-time operational visibility into the application.
Which monitoring capability should you use for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.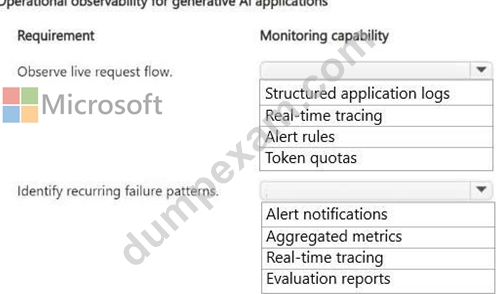
Answer:
Explanation: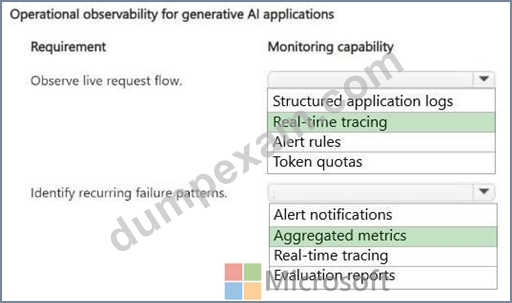
Explanation:
Box 1: Real-time tracing
Observe live request flow.
To best observe the live request flow in your generative AI application, you should use Real-time tracing.
Real-time tracing maps the end-to-end journey of a request as it flows through various microservices, APIs, and AI model endpoints. It provides the exact visibility needed to pinpoint bottlenecks, latencies, and failures in the live request path immediately.
Box 2: Aggregated metrics
Identify recurring failure patterns.
To best identify recurring failure patterns in a generative AI application with variable traffic, you should use aggregated metrics.
Aggregated metrics groups data points over specified time intervals to reveal long-term trends, error rates, and system anomalies. It allows you to track patterns (like a spike in 5xx errors or model timeouts during peak traffic) over hours or days without manually inspecting individual logs.
Reference:
https://docs.azure.cn/en-us/ai-services/metrics-advisor/glossary
NEW QUESTION # 28
Hotspot Question
A regression model is deployed to a production online endpoint and is actively serving predictions.
Business stakeholders report that the model's prediction quality has changed.
The endpoint remains available and responsive.
You need to determine which metric to examine to validate each quality concern.
Which metric should you review for each concern? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.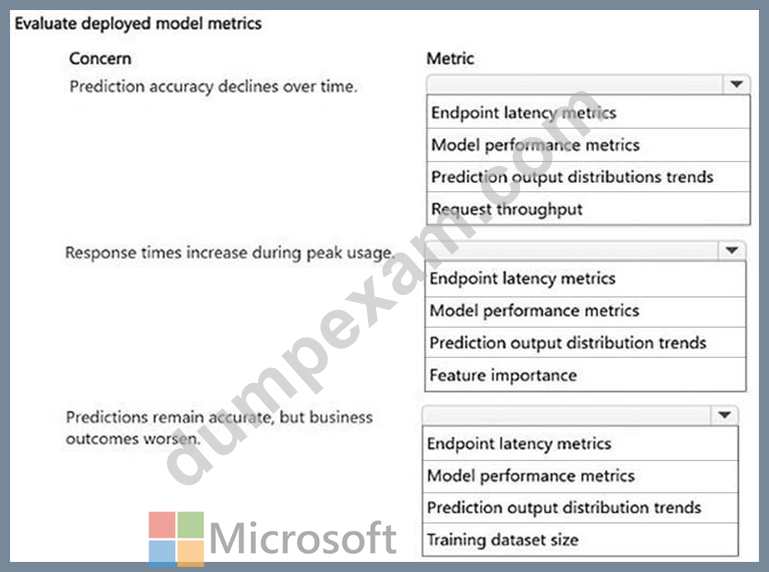
Answer:
Explanation: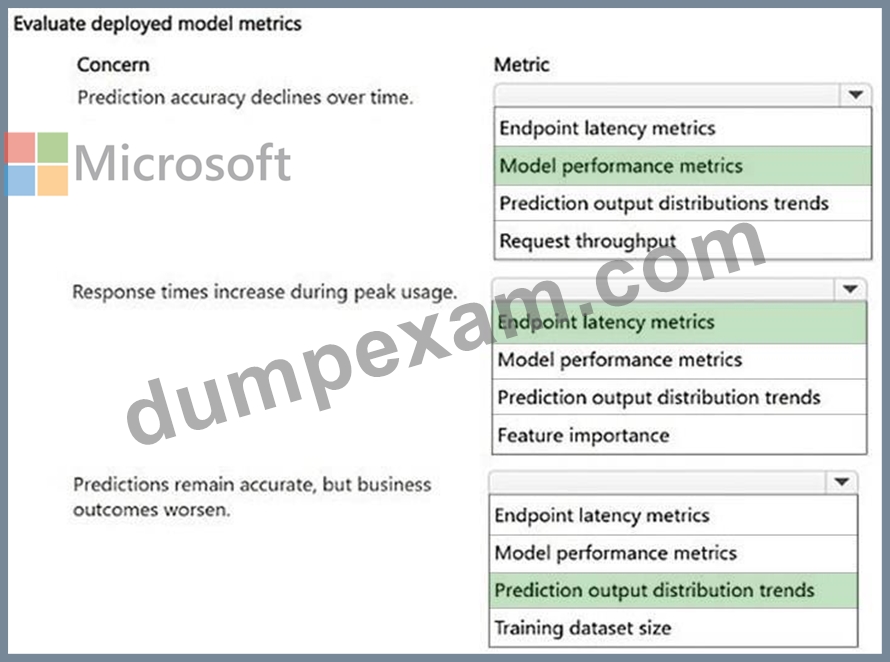
NEW QUESTION # 29
You have an Azure Machine Learning workspace.
You plan to run a job to tram a model as an MLflow model output.
You need to specify the output mode of the MLflow model.
Which three modes can you specify? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: A,B,C
NEW QUESTION # 30
A team deploys a classification model to production and monitors performance and data changes.
The team wants to ensure that significant drops in prediction accuracy automatically trigger the following:
Stakeholders must be notified of the drops.
Retraining must be initiated when thresholds are exceeded
You need to configure monitoring to meet the requirements.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.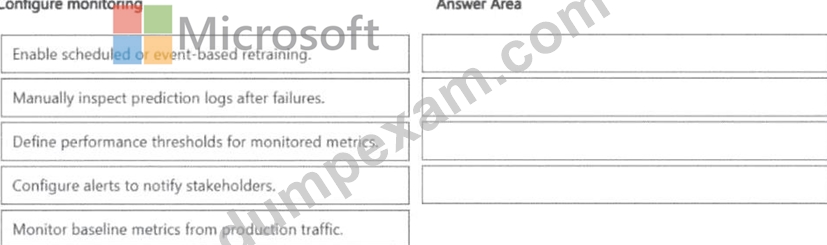
Answer:
Explanation: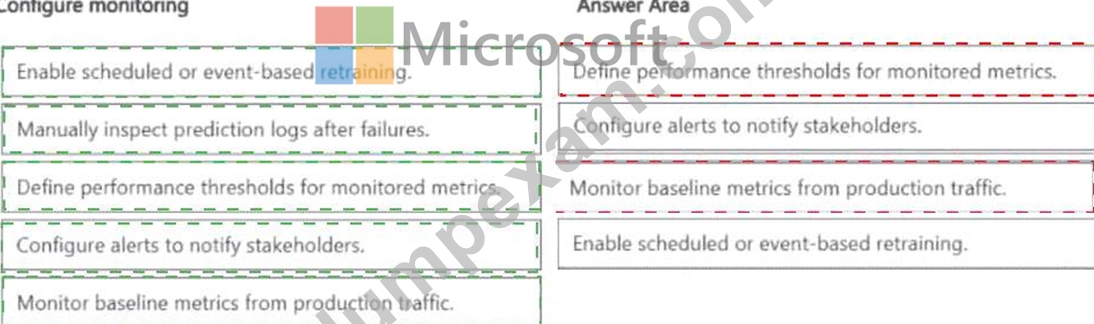
Explanation:
Microsoft ' s guidance on production model monitoring prescribes a four-stage sequence. First, configure an Azure ML model monitor on the deployed endpoint, specifying which metrics to track and on what schedule.
Second, define the threshold value below which model performance is considered unacceptable - this becomes the trigger condition. Third, create an Azure Monitor alert rule that evaluates the monitored metric against the threshold and fires when it is breached; the alert rule is associated with an action group that sends notifications to stakeholders via email, SMS, or Teams webhook. Fourth, the action group includes a webhook action pointing to an Azure Machine Learning pipeline ' s published REST endpoint, which starts the retraining job automatically. This sequence cleanly separates detection, notification, and remediation, matching Microsoft ' s recommended MLOps automation pattern.
Microsoft Learn Reference Topic: Automate model retraining based on monitoring alerts - Azure Machine Learning MLOps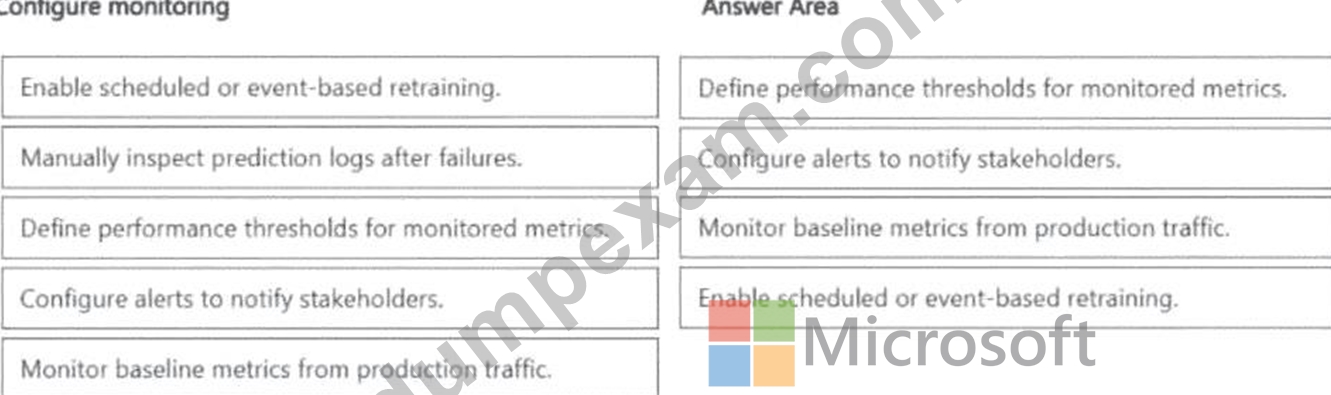
NEW QUESTION # 31
A real-time endpoint is deployed in Azure Machine Learning to serve predictions to a web application.
Users report intermittent failures and unexpected responses when calling the endpoint.
You need to identify the appropriate troubleshooting action for each reported issue.
Which troubleshooting action should you perform for each issue? To answer, move the appropriate troubleshooting actions to the correct issues. You may use each troubleshooting action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.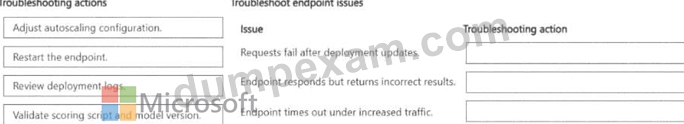
Answer:
Explanation: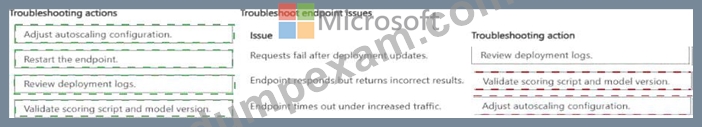
Explanation:
For deployment failures when containers do not start, review deployment logs in Azure ML Studio or use the CLI get-logs command to surface dependency installation errors, missing files, or scoring script import failures. For authentication errors such as 401 or 403 responses, check that client applications are using valid authentication keys or bearer tokens, as mismatched or expired credentials cause auth failures. For performance degradation and slow responses, review compute instance scaling configuration, since a surge in traffic saturates a fixed number of replicas causing queuing and high latency without autoscaling. For internal server errors such as HTTP 500, these typically originate in the scoring script, so inspect the init and run functions for unhandled exceptions and verify the environment has all required packages installed.
Microsoft Learn Reference Topic: Troubleshoot online endpoint deployment failures - Azure Machine Learning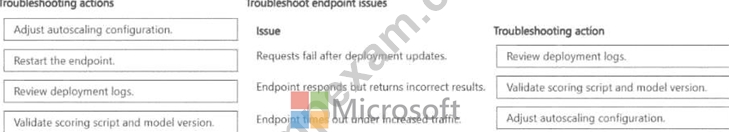
NEW QUESTION # 32
......
Microsoft AI-300 study materials will be very useful for all people to improve their learning efficiency. If you do all things with efficient, you will have a promotion easily. If you want to spend less time on preparing for your AI-300 Exam, if you want to pass your AI-300 exam and get the certification in a short time, our Operationalizing Machine Learning and Generative AI Solutions AI-300 study materials will be your best choice to help you achieve your dream.
Valid AI-300 Test Simulator: https://www.dumpexam.com/AI-300-valid-torrent.html
BTW, DOWNLOAD part of DumpExam AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1qN_wyFZcIWwxL47JtMrPSDWfzLK2Zs84