그리고 Fast2test SPS-C01 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1dvO8YIbGH1fhwbNjrYngoB_x2Wuk6RW3
불과 1,2년전만 해도 Snowflake SPS-C01덤프를 결제하시면 수동으로 메일로 보내드리기에 공휴일에 결제하시면 덤프를 보내드릴수 없어 고객님께 페를 끼쳐드렸습니다. 하지만 지금은 시스템이 업그레이드되어Snowflake SPS-C01덤프를 결제하시면 바로 사이트에서 다운받을수 있습니다. Fast2test는 가면갈수록 고객님께 편리를 드릴수 있도록 나날이 완벽해질것입니다.
| Section | Objectives |
|---|---|
| Topic 1: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 2: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 3: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 4: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 5: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 6: Data Engineering with Snowpark | - Pipeline development
|
Snowflake인증 SPS-C01시험을 패스하여 자격증을 취득하여 승진이나 이직을 꿈구고 있는 분이신가요? 이 글을 읽게 된다면Snowflake인증 SPS-C01시험패스를 위해 공부자료를 마련하고 싶은 마음이 크다는것을 알고 있어 시장에서 가장 저렴하고 가장 최신버전의 Snowflake인증 SPS-C01덤프자료를 강추해드립니다. 높은 시험패스율을 자랑하고 있는Snowflake인증 SPS-C01덤프는 여러분이 승진으로 향해 달리는 길에 날개를 펼쳐드립니다.자격증을 하루 빨리 취득하여 승진꿈을 이루세요.
질문 # 203
You have a Snowpark DataFrame containing customer transaction data'. Your goal is to save this DataFrame as a set of Parquet files in an existing Snowflake stage named , partitioned by the 'transaction_date' column. You want to ensure that the files are automatically compressed using the Zstandard codec and that existing files with the same name are overwritten. Which of the following Snowpark code snippet achieves this with the most optimal approach and respects best practices?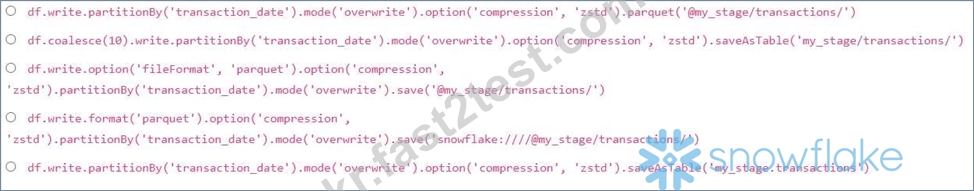
정답:A
설명:
Option A correctly uses the 'parquet' method directly for writing Parquet files to a stage. It specifies partitioning by 'transaction_date', overwrites existing files using , and sets the compression codec to 'zstd' using the 'option' method. The 'saveAsTable' method, used in option B & E, is intended for creating or overwriting tables, not writing files to a stage. Option D uses a fully qualified Snowflake URL to save the DataFrame, but using saveAsTable is not for writing files into stage . The 'option('fileFormat', 'parquet')' in option C is not the most direct way to specify the format; using .parquet()' is more concise and idiomatic.
질문 # 204
You have a complex data pipeline implemented using Snowpark Tasks in a Directed Acyclic Graph (DAG). One of the tasks, , depends on the successful completion of two parent tasks, and 'task B'. You need to implement error handling such that if 'task_R fails, 'task_C' should not be executed, but should still complete its execution regardless of status. If 'task B' fails, 'task_C' should not be executed. How do you configure the task dependencies and error handling in Snowflake to achieve this behavior?





정답:D
설명:
Setting to execute 'AFTER task_A, task_B' establishes the dependency. Configuring on both 'task_R and 'task_B' ensures that if either task fails, it will suspend itself and prevent 'task_C' from running. This achieves the required behavior. Option A is incorrect because setting the parameter on 'task_C' will not prevent the execution of 'task_C' if either 'task_R or failed, but only suspend it after it tries to execute and fails. Option B is not correct because Snowflake's default behavior does not inherently skip 'task_C' unless specifically configured through dependencies. Option C is overly complex and doesn't accurately reflect intended behaviour.Option E is overly complex and doesn't accurately reflect intended behaviour. Option D will ensure only if both 'task_A' and runs successfully then runs else it will suspend the further execution.
질문 # 205
You have a Snowpark Python application that reads data from multiple Snowflake tables, performs complex transformations using UDFs, and writes the results to a new table. During peak hours, the application experiences performance bottlenecks. The Snowflake warehouse associated with the Snowpark session is already configured with the 'SNOWPARK OPTIMIZED warehouse type. Which of the following strategies, when implemented together, would BEST improve the application's performance?
정답:A,C
설명:
Increasing the warehouse size provides more compute resources. Partitioning tables improves join performance. Optimizing UDFs reduces execution time. Utilizing vectorized UDFs allows for processing batches of data at once, reducing overhead. Snowpark's optimized join operations use efficient algorithms. Options A and C, while helpful, don't address the underlying issues as directly. Caching might help repetitive tasks, rewriting UDFs in SQL isn't always feasible or optimal if specialized logic is implemented. Option E is most optimal because it also utilizes vectorized UDFs where possible.
질문 # 206
You are developing a Snowpark application that processes high-volume event data stored in a Snowflake table named 'raw events'. The application aggregates data by session ID. You observe significant performance degradation during peak hours. Analyzing Snowflake query history reveals that the 'session_id' column has high cardinality and data skew. Which of the following strategies, or combination of strategies, would be MOST effective in optimizing the aggregation performance?
정답:A,B
설명:
Using BUCKET_ID hint improves parallel processing and mitigates data skew in Snowpark. Pre-aggregation reduces the amount of data processed by the Snowpark application, thus improving performance. Increasing the warehouse size (A) might help but doesn't address data skew. UDFs (D) can introduce overhead if not optimized. GROUP BY alone (B) will not address the data skew problem
질문 # 207
You have a Snowpark Python application that performs several data transformations on a DataFrame representing customer transactions. The application is experiencing performance issues, and you suspect that some transformations are unnecessarily expensive. Which of the following techniques can MOST effectively optimize the performance of your Snowpark application, specifically focusing on minimizing data movement and leveraging Snowflake's query optimization capabilities?
정답:D
설명:
Snowpark is designed to push down computations to Snowflake, allowing Snowflake's query optimizer to handle the execution. Using Snowpark's built-in DataFrame transformations allows Snowflake to understand the intent and optimize the query accordingly. Materializing intermediate results using .cache()' (A) can lead to unnecessary data movement. Python UDFs (B) can be useful for complex logic but should be avoided for simple transformations as they bypass Snowflake's optimization capabilities and are generally slower than native SQL functions. Warehouse size (E) is a factor, but optimizing the query logic is more crucial. Using Pandas dataframe is also costly and performance heavy.
질문 # 208
......
우리Fast2test에는 아주 엘리트 한 전문가들로 구성된 팀입니다 그들은 끈임 없는 연구와 자기자신만의 지식으로 많은 IT관연 덤프자료를 만들어 냄으로 여러분의 꿈을 이루어드립니다, 기존의 시험문제와 답과 시험문제분석 등입니다. Fast2test에서 제공하는Snowflake SPS-C01시험자료의 문제와 답은 실제시험의 문제와 답과 아주 비슷합니다. Fast2test덤프들은 모두 보장하는 덤프들이며 여러분은 과감히 Fast2test의 덤프를 장바구니에 넣으세요. Fast2test에서 여러분의 꿈을 이루어 드립니다.
SPS-C01시험유효자료: https://kr.fast2test.com/SPS-C01-premium-file.html
참고: Fast2test에서 Google Drive로 공유하는 무료, 최신 SPS-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1dvO8YIbGH1fhwbNjrYngoB_x2Wuk6RW3