Learning Snowflake SPS-C01 Materials, New SPS-C01 Test Tips
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Itbraindumps: https://drive.google.com/open?id=10uWM2BFuKxGSeo_5Lf9SMeo_4uWpqSWf
To increase your chances of success, consider utilizing the SPS-C01 Exam Questions, which are valid, updated, and reflective of the actual SPS-C01 Exam. Don't miss the opportunity to strengthen your Snowflake SPS-C01 exam preparation with these valuable questions.
| Section | Objectives |
|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Stored procedures in Snowpark
- 2. Python UDFs
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Pushdown optimization concepts
- 2. Resource utilization tuning
|
| DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Filtering, selecting, and aggregations
- 2. Joins and window functions
|
| Testing, Debugging, and Deployment | - Production readiness
- 1. Debugging Snowpark applications
- 2. Deployment strategies
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowpark APIs and supported languages
- 2. Snowflake execution model overview
|
| Data Engineering with Snowpark | - Pipeline development
- 1. Integration with Snowflake data pipelines
- 2. Batch processing workflows
|
>> Learning Snowflake SPS-C01 Materials <<
New Snowflake SPS-C01 Test Tips - New SPS-C01 Test Topics
If you just hold a diploma, it is very difficult to find a satisfactory job. Companies want you to come up with a SPS-C01 certificate that better proves your strength. SPS-C01 training materials can help you achieve this goal faster. Whether or not you believe it, there have been a lot of people who have obtained internationally certified certificates through SPS-C01 Exam simulation. And with the certification, they all live a better life now.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q355-Q360):
NEW QUESTION # 355
Consider the following Snowpark Python code snippet designed to aggregate sales data by region:
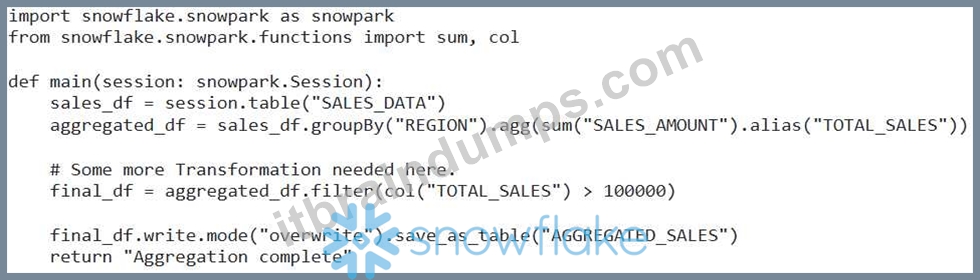
During testing, you observe that the performance of this code is suboptimal, especially when dealing with very large 'SALES DATA tables. Using Snowflake's query history, you notice that a significant amount of time is spent on data shuffling during the operation. What optimization strategies could you employ within this Snowpark code to minimize data shuffling and improve the overall performance?
- A. store 'SALES_DATX as a clustered table using the 'REGION' column.
- B. Utilize the 'hint' function in Snowpark to provide a join hint that suggests a specific join strategy to the Snowflake query optimizer.
- C. Apply a more selective 'filter operation to the 'sales_df' DataFrame before the 'groupBy' operation, reducing the amount of data that needs to be shuffled.
- D. Repartition the 'sales_df DataFrame using 'repartitionBy' before the 'groupBy' operation, specifying the 'REGION' column to ensure that data for each region is co-located on the same node.
- E. Increase the warehouse size to provide more resources for data processing, which will inherently reduce data shuffling.
Answer: A,C,D
Explanation:
Filtering early reduces data shuffling by reducing the volume of data that needs to be grouped. Repartitioning ensures that rows with the same region are on the same node before the group by which reduces shuffling significantly. Creating the source SALES_DATA table as a clustered table with REGION as the clustering key colocates the data for each region in the same micropartitions, reducing shuffling. Increasing warehouse size will help overall performance but will not directly reduce shuffling. Hints apply to Joins, not group by operations.
NEW QUESTION # 356
You are tasked with optimizing a Snowpark Python application that performs complex data transformations using a large DataFrame. The application is running slower than expected. You suspect that data skew is causing uneven distribution of work across the Snowflake warehouse nodes. Which of the following techniques could be used to mitigate data skew and improve the performance of your Snowpark application? (Select TWO)
- A. Use the function to sort the data before performing the transformations.
- B. Use the function to redistribute the data evenly across the warehouse nodes based on a specific column or set of columns.
- C. Utilize Snowflake's automatic clustering feature on the underlying table to improve data locality.
- D. Increase the warehouse size to the largest possible option.
- E. Use the function with the 'BROADCAST' strategy for smaller DataFrames that are joined with the large DataFrame.
Answer: B,E
Explanation:
Options B and E are effective techniques for mitigating data skew. Option B, allows you to explicitly redistribute the data based on a specific column or set of columns, ensuring a more even distribution across the warehouse nodes. Option E, using the 'BROADCAST' hint, is useful when joining a smaller DataFrame with a large DataFrame, as it broadcasts the smaller DataFrame to all nodes, preventing skew during the join operation. Option A, increasing the warehouse size, might provide more resources but doesn't address the underlying data skew issue directly. Option C, sorting the data, doesn't necessarily address data skew and might even worsen it in some cases. Option D, Snowflake's automatic clustering, helps with data locality for queries but doesn't directly address data skew within the Snowpark application during transformations.
NEW QUESTION # 357
You are developing a Snowpark application that needs to train a machine learning model on a large dataset stored in Snowflake. You want to optimize the performance of your model training process. Which of the following strategies would be MOST effective in leveraging Snowpark's architecture to achieve this, considering both client-side and server-side capabilities?
- A. Define a Snowpark DataFrame that transforms the data, then write that data back to Snowflake as a new table, then create a separate Python process running outside of Snowflake's environment to train the model.
- B. Use Snowpark to execute SQL queries to pre-aggregate the data on the server-side before transferring the smaller aggregated data to the client for model training.
- C. Use Snowpark's 'sproc' feature to define a stored procedure that loads the data in chunks and trains the model directly within Snowflake's secure environment, leveraging its compute resources.
- D. Load the entire dataset into a Pandas DataFrame on the client machine and then use a local machine learning library (e.g., scikit-learn) to train the model.
- E. Create a UDF (User-Defined Function) that uses a pre-trained model stored locally on the client machine and applies it to the data within Snowflake.
Answer: C
Explanation:
Using a stored procedure ('sproc') allows the model training to occur entirely within the Snowflake environment, leveraging its scalable compute resources and eliminating the need to transfer large datasets to the client. This minimizes data transfer overhead and maximizes performance. Options A, D and E involve data transfer or execution outside the Snowflake environment which contradicts Snowpark's server-side processing advantages. Option C is a good preprocessing step, but doesn't train the model inside Snowflake.
NEW QUESTION # 358
You are developing a Snowpark application to analyze customer data'. You need to create a Snowpark DataFrame from a list of dictionaries, where each dictionary represents a customer with 'id', 'name', and 'city' keys. The data should be loaded efficiently. Consider these scenarios: 1 . The input data can sometimes contain missing values (e.g., a customer might not have a city specified). 2. You want to ensure optimal performance when loading the data, as the list can be very large. 3. You need the resulting DataFrame's schema to correctly infer the datatypes based on the input dictionary's values. Which of the following methods and considerations should be used to create a Snowpark DataFrame from a list of dictionaries to meet these requirements?
- A. Use 'session.createDataFrame(data)' and then explicitly cast columns with potential missing values to the correct datatype using method to ensure 'NULL' handling.
- B. Use 'session.createDataFrame(data, and specify the 'nullable' property for each field within the schema. Additionally, define the data type explicitly. This optimizes performance.
- C. Use 'session.createDataFrame(data)' with default settings. Snowflake will automatically infer the schema and handle missing values as 'NULL'.
- D. Use 'session.createDataFrame(data, where 'schema' is explicitly defined to handle missing data and ensure correct data types. This improves performance over schema inference.
- E. Leverage Snowpark's optimized data loading by converting the list of dictionaries to a Pandas DataFrame first and then create a Snowpark DataFrame using 'session.createDataFrame(pandas_df)'. Pandas has optimized data loading.
Answer: B,D
Explanation:
Options B and D are the most appropriate. Providing an explicit schema, including specifying the 'nullable' property and datatypes, offers several advantages: 1. Handles missing values: By explicitly setting 'nullable=True' in the schema for columns that might contain missing values, you ensure that Snowflake correctly handles these as 'NULC. 2. Optimizes Performance: Specifying the schema avoids Snowflake's need to infer it, which can be a performance bottleneck, especially for large datasets. Explicit datatypes also help with storage and processing efficiency. 3. Data Type Control: You can ensure the correct data types are used for each column, preventing potential issues with data type conversions later om Option A relies on automatic schema inference, which can be inefficient and may not always correctly handle missing values or data types as expected. Option C requires explicit casting after DataFrame creation which is less efficient than specifying in the schema initially. Option E can add an unneccessary overhead since converting to Pandas DataFrame and then to Snowpark DataFrame may not be optimized.
NEW QUESTION # 359
You have developed a Snowpark application that uses a Python UDF to perform sentiment analysis on text data extracted from JSON files stored in a Snowflake stage. The UDF relies on a large pre-trained machine learning model that is loaded during the UDF initialization. After deploying the application, you observe that the UDF initialization is taking a significant amount of time, causing slow query performance. What are the three MOST effective strategies to optimize the UDF initialization time in this scenario?
- A. Load the model outside the UDF definition within the Snowpark session, pass it as an argument to the UDF, then use the model as part of a vectorized UDF.
- B. Use the 'cachetools' library to cache the loaded model within the UDF. This will help to avoid reloading the model every time the UDF is called.
- C. Use the 'streamlit' library and its caching capabilities to cache loaded models. The UDF should call the streamlit api to retrieve the already loaded model.
- D. Use the 'snowflake.snowpark.files.SnowflakeFile' class to load the model directly from the Snowflake stage within the UDF initializer, but only if the model is smaller than 256M
- E. Utilize the 'context.add_dependency' method in Snowpark to specify the model file as a dependency. Snowflake will automatically distribute and cache the model file to the worker nodes.
Answer: A,B,E
Explanation:
Optimizing UDF initialization is crucial for performance. Option A is correct because caching the model using 'cachetoolS avoids reloading it for each UDF call. Option C is also correct; 'context.add_dependency' tells Snowflake to distribute and cache the model on worker nodes, further reducing load times. Option D avoids the need for the UDF to load the model, reducing the initialization step down entirely. Streamlit caching is not valid for Snowflake operations, making option E incorrect. 'SnowflakeFile' isn't best used within a UDF initializer as its inefficient, making option B incorrect.
NEW QUESTION # 360
......
All these three Snowflake SPS-C01 exam questions formats are easy to use and perfectly work with all devices, operating systems, and the latest web browsers. The Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) PDF dumps file is the collection of real and updated Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions that are being presented in PDF format. You can install SPS-C01 Pdf Dumps file on your desktop computer, laptop, tab, or even on your smartphone devices. Just install the SPS-C01 PDF dumps file and start Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam preparation anywhere and anytime.
New SPS-C01 Test Tips: https://www.itbraindumps.com/SPS-C01_exam.html
- The Ideal Solution for Snowflake SPS-C01 Exam Questions Preparation 😉 Easily obtain ▶ SPS-C01 ◀ for free download through ➥ www.practicevce.com 🡄 💚SPS-C01 Test Dumps Pdf
- SPS-C01 New Exam Materials 🍾 SPS-C01 Valid Dumps Book 🅱 SPS-C01 Reliable Exam Vce 🚬 Copy URL { www.pdfvce.com } open and search for ▷ SPS-C01 ◁ to download for free 😆Valid SPS-C01 Exam Dumps
- Trustworthy Snowflake Learning SPS-C01 Materials With Interarctive Test Engine - Newest New SPS-C01 Test Tips 😋 The page for free download of ▶ SPS-C01 ◀ on ⮆ www.prepawaypdf.com ⮄ will open immediately 🛰SPS-C01 Reliable Exam Online
- Free PDF 2026 SPS-C01: Updated Learning Snowflake Certified SnowPro Specialty - Snowpark Materials 🚗 Immediately open ▷ www.pdfvce.com ◁ and search for ➤ SPS-C01 ⮘ to obtain a free download 🧉SPS-C01 Reliable Exam Vce
- Learning SPS-C01 Materials - Efficient New SPS-C01 Test Tips and First-Grade New Snowflake Certified SnowPro Specialty - Snowpark Test Topics 🌉 Search for ➤ SPS-C01 ⮘ and download exam materials for free through ➤ www.easy4engine.com ⮘ 🧇Exam SPS-C01 Course
- The Ideal Solution for Snowflake SPS-C01 Exam Questions Preparation 🕰 [ www.pdfvce.com ] is best website to obtain [ SPS-C01 ] for free download 🏦Reliable SPS-C01 Dumps Book
- Unparalleled Learning SPS-C01 Materials - Find Shortcut to Pass SPS-C01 Exam 🦪 Go to website 【 www.exam4labs.com 】 open and search for ( SPS-C01 ) to download for free 🛢SPS-C01 Reliable Exam Dumps
- Free PDF 2026 SPS-C01: Updated Learning Snowflake Certified SnowPro Specialty - Snowpark Materials 🚜 Download 「 SPS-C01 」 for free by simply entering ➡ www.pdfvce.com ️⬅️ website 📔Reliable SPS-C01 Cram Materials
- SPS-C01 Reliable Exam Vce 💾 New SPS-C01 Test Vce 🎲 Valid SPS-C01 Exam Dumps 🤍 Search for 【 SPS-C01 】 and download it for free on { www.prepawaypdf.com } website 🌏SPS-C01 Valid Test Sample
- SPS-C01 Valid Test Sample 🐨 Valid SPS-C01 Exam Dumps 🖼 SPS-C01 Valid Exam Cram 💛 Search for ➽ SPS-C01 🢪 and easily obtain a free download on ✔ www.pdfvce.com ️✔️ 🎥SPS-C01 Reliable Exam Vce
- Exam SPS-C01 Course 💭 Practice SPS-C01 Exams 🍡 SPS-C01 Valid Test Sample 😥 Search for ☀ SPS-C01 ️☀️ and easily obtain a free download on ⏩ www.vce4dumps.com ⏪ 💋Popular SPS-C01 Exams
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Itbraindumps: https://drive.google.com/open?id=10uWM2BFuKxGSeo_5Lf9SMeo_4uWpqSWf