我們VCESoft的IT認證考題擁有多年的培訓經驗,VCESoft Microsoft的AI-300考試培訓資料是個值得信賴的產品,我們的IT精英團隊不斷為廣大考生提供最新版的AI-300考試培訓資料,我們的工作人員作出了巨大努力,以確保你們在考試中總是取得好成績,可以肯定的是,VCESoft Microsoft的AI-300考試材料是為你提供最實際的IT認證材料。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 2: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 3: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 4: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 5: Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
每個需要通過AI-300考試認證的考生都知道,這次的認證關係著他們人生的重大轉變,我們VCESoft提供的考試認證培訓資料是用超低的價格和高品質的擬真試題和答案來奉獻給廣大考生,我們的產品還具備成本效益,並提供了一年的免費更新期,我們認證培訓資料都是現成的。我們網站是答案轉儲的領先供應商,我們有你們需要的最新最準確的考試認證培訓資料,也就是答案和考題。
問題 #166
A team runs training jobs by using multiple Azure Machine Learning pipelines.
The team must ensure that all runs use the same Python packages and system libraries. The solution must allow dependency updates to be versioned without modifying training code.
You need to configure the workspace so that runtime dependencies are consistent and reusable.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.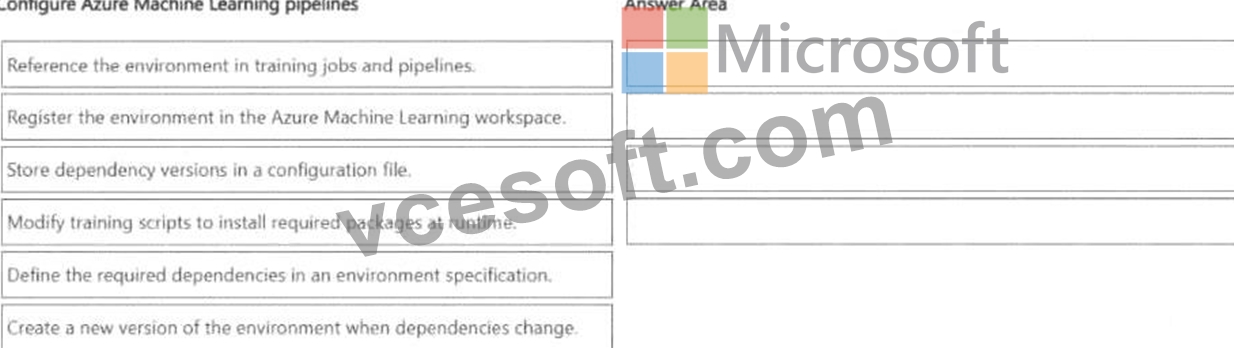
答案:
解題說明: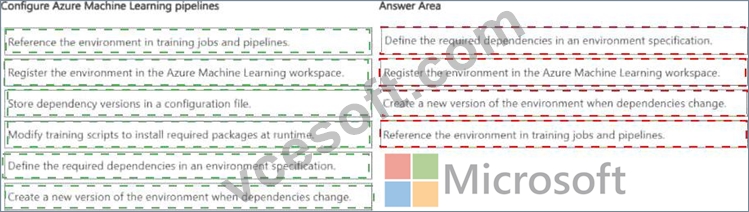
Explanation:
To ensure runtime dependencies are consistent and reusable, first create a conda.yaml or requirements.txt file that lists all Python packages and system libraries required by your training code - this file is the single source of truth for your runtime. Next, create an Environment object using the Azure ML Python SDK v2 with a name and reference to the conda.yaml file, specifying the base Docker image. Then register the Environment by calling ml_client.environments.create_or_update, which publishes it to the workspace registry with an auto-incremented version. Finally, reference the registered environment by name and version in all pipeline job steps. Azure ML will build or retrieve the cached Docker image and use it as the execution container. This approach means updating dependencies only requires modifying the conda.yaml and registering a new version - training code remains unchanged.
Microsoft Learn Reference Topic: Create and manage Azure Machine Learning environments - Reusable curated environments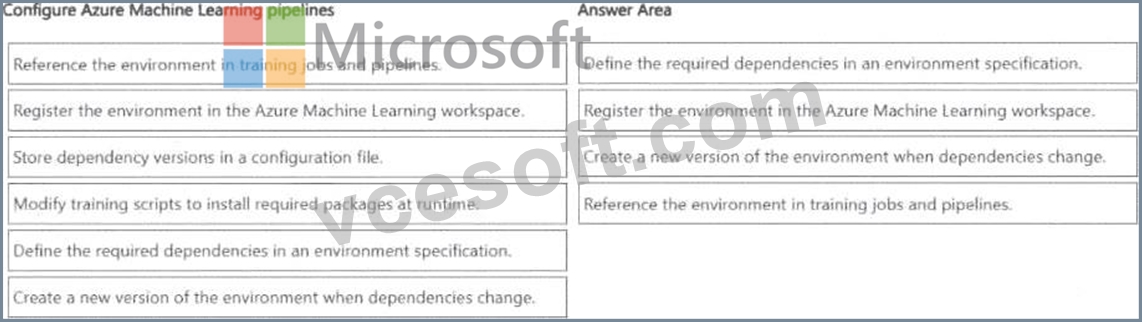
問題 #167
-
A team performs interactive experimentation during development. The team also runs scalable jobs for model training.
The team must minimize costs while ensuring compute resources scale when needed. Different workloads require different compute behaviors within the same workspace.
You need to configure compute targets that support each workload.
Which compute targets should you use? To answer, move the appropriate compute targets to the correct workload types. You may use each compute target once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.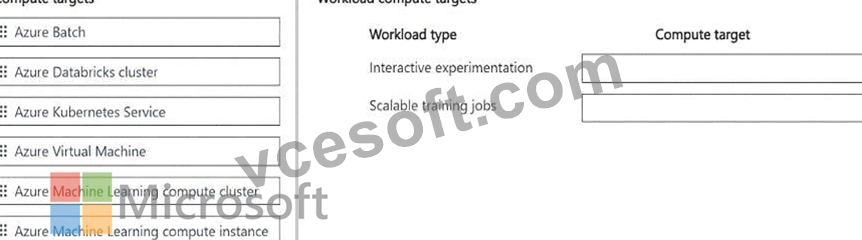
答案:
解題說明: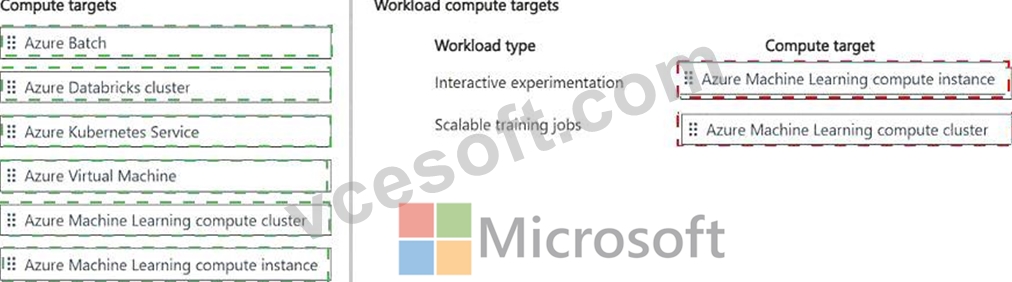
Explanation:
Interactive experimentation: Azure Machine Learning compute instance
Scalable training jobs: Azure Machine Learning compute cluster
For interactive experimentation , use an Azure Machine Learning compute instance . Microsoft defines a compute instance as a fully managed, cloud-based development workstation optimized for machine learning development. It integrates directly with Jupyter, JupyterLab, and other development tools in Azure Machine Learning studio, making it the appropriate target for notebook-driven experimentation, iterative coding, debugging, and development. A compute instance is a single-node environment and can be stopped or configured with idle shutdown to control costs.
For scalable training jobs , use an Azure Machine Learning compute cluster . Compute clusters are managed training targets that can scale from a minimum to a configured maximum number of nodes based on job demand. Microsoft specifically recommends them for larger datasets, distributed training, and workloads requiring elastic compute capacity. Setting the minimum node count to 0 allows the cluster to deallocate all worker nodes when no jobs are running, which is an important cost-optimization mechanism.
Azure Batch, Databricks, AKS, and standalone Azure VMs can support specialized workloads, but they do not match the native Azure Machine Learning development-versus-elastic-training pattern as directly as compute instance and compute cluster.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning compute targets, compute instances, compute clusters, autoscaling, distributed training, and cost optimization.
問題 #168
A company is standardizing generative AI development across multiple teams.
Each team requires an isolated workspace. Governance and shared connections must be centrally managed.
You need to implement a Microsoft Foundry environment structure that supports centralized governance and team isolation.
Which type of configuration should you use for each requirement? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.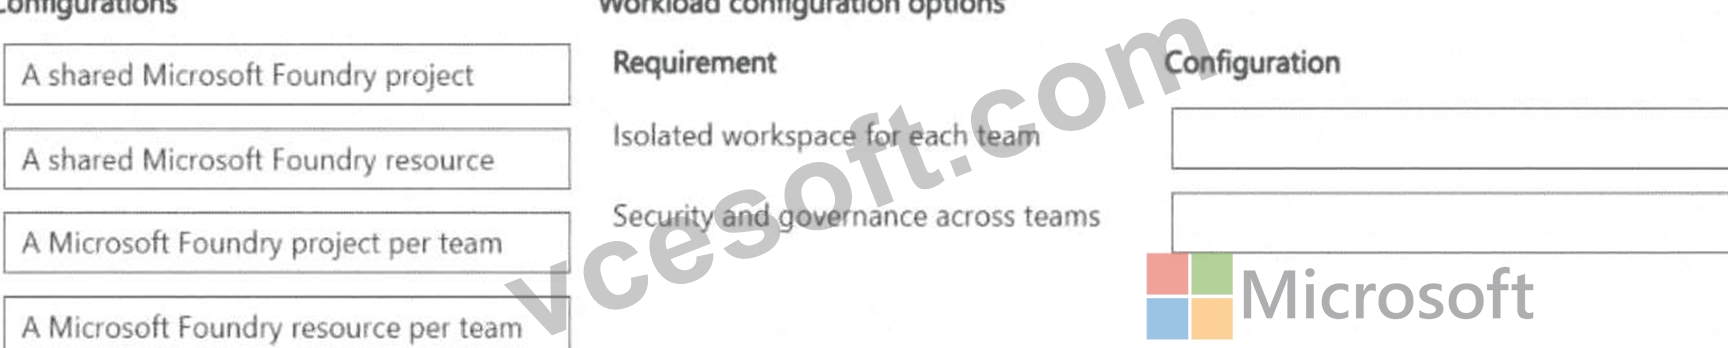
答案:
解題說明: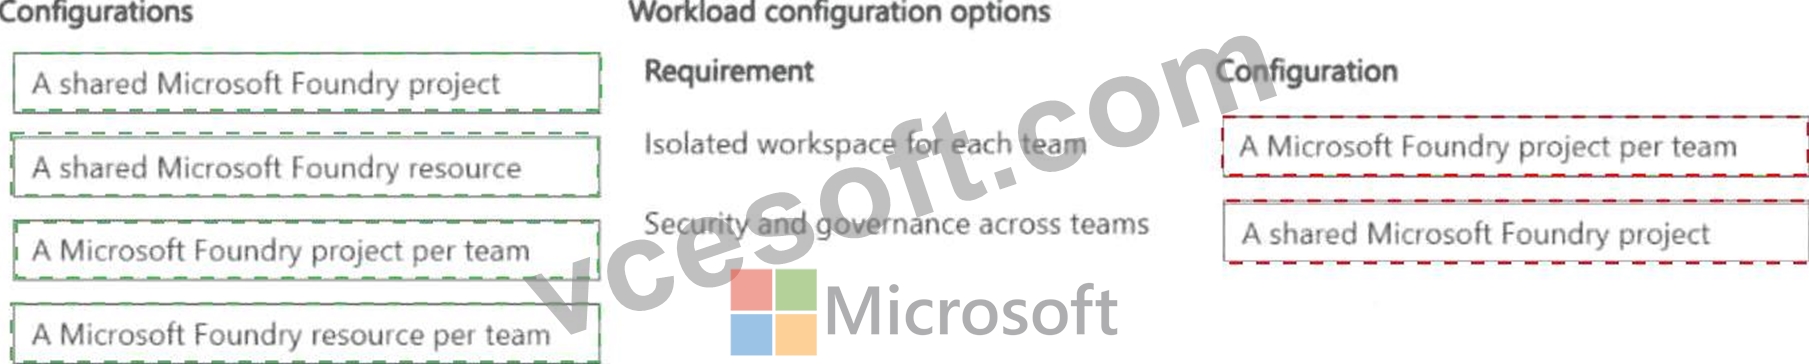
Explanation:
An Azure AI Hub is the top-level governance container in Microsoft Foundry: it holds shared connections to Azure OpenAI, Azure AI Search, Azure Storage, and other services; it defines network isolation policies; it manages billing and quota at the organizational level. Multiple teams share these resources without each team needing to configure their own connections or negotiate quota independently. An Azure AI Project sits inside the Hub and provides team-level isolation: each project has its own experiments, deployments, prompt flows, evaluations, and fine-tuning jobs, all governed by the Hub ' s shared infrastructure. Different teams get their own project with independent access controls via RBAC, while the platform team manages the shared Hub.
This pattern eliminates redundant resource configurations across teams while maintaining clear team-level boundaries - the correct structure for centralized governance with team isolation.
Microsoft Learn Reference Topic: Microsoft Azure AI Foundry hub and project architecture - Centralized governance and team isolation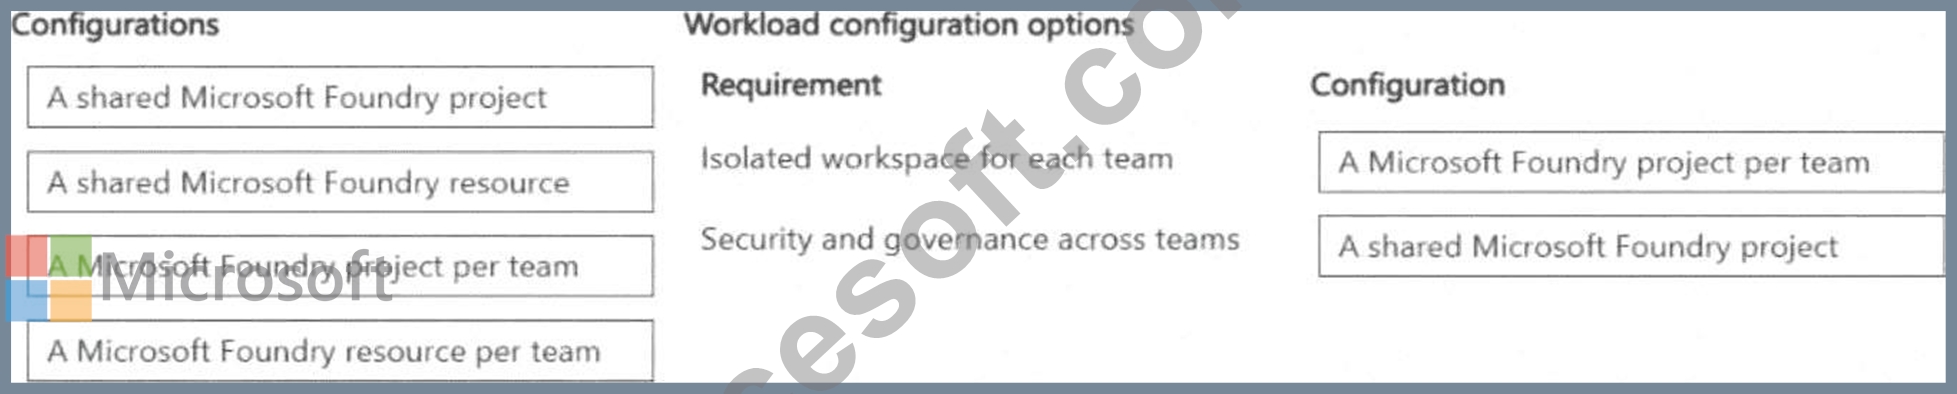
問題 #169
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to recommend an experiment-tracking strategy that ensures consistent experiment results. What should you recommend?
答案:D
解題說明:
Scenario:
The current challenges faced by the data science team include the following: Experiment tracking is inconsistent To support the business goals, Fabrikam Inc. identifies these technical requirements: Implement experiment tracking and model versioning for all training jobs.
In Azure-based AI operations, integrating MLflow with Azure Machine Learning (Azure ML) provides a unified interface to track experiments, version models, and manage the lifecycle of both traditional ML and Generative AI workloads.
Direct Implementation Strategy
To ensure consistent experiment results and comparison of prompt strategies versus fine-tuned models, use the following architectural approach:
Centralized Tracking: Configure the MLflow tracking URI to point to your Azure ML Workspace.
This allows all logs (from local notebooks, remote training jobs, or Prompt Flow) to aggregate in a single "Experiments" dashboard.
Prompt Strategy Comparison: Use Azure ML Prompt Flow to develop and test prompt variants.
Prompt Flow automatically logs metrics (like groundedness and relevance) which can be viewed alongside fine-tuned model metrics in the Azure ML Studio.
Model Versioning: Use the MLflow Model Registry hosted within Azure ML. Each successful training or fine-tuning run should be registered as a new version of a named model, providing a clear lineage from data to deployment.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-mlflow-cli-runs
問題 #170
A team develops and manages a conversational assistant by using Microsoft Foundry.
The team must be able to validate that the assistant does not produce hateful responses before the application is exposed to any users.
You need to evaluate the model output for hateful responses as part of a repeatable validation process.
Which evaluator should you configure first?
答案:D
解題說明:
You should use the Hate and Unfairness Evaluator (a specific type of Content Safety Evaluator) in Microsoft Azure AI Foundry. This tool is designed to identify and measure the severity of hateful content toward protected groups, ensuring your assistant aligns with responsible AI standards.
Why Use the Content Safety Evaluator?
Targeted Detection: It identifies language attacking or discriminating against people based on race, religion, gender, and other identity factors.
Severity Scoring: It provides a numerical severity score (often 0-7) to help you understand the level of risk in a response.
Reasoning: It often includes a "reason" or "explanation" column that explains why a specific response was flagged.
Multilingual Support: These models are trained to work across multiple languages, including English, Spanish, French, and Japanese.
Reference:
https://arize.com/blog/evaluating-and-improving-ai-agents-at-scale-with-microsoft-foundry
問題 #171
......
有了Microsoft AI-300認證考試的證書就相當於人生有了個新的里程牌,工作將會有很大的提升,相信作為IT行業人士的每個人都很想擁有吧。很多人都在討論說這麼好的一個證書是很難通過的,實際上確實通過率是相當的低。沒有做過任何的努力當然是不容易通過的,畢竟通過Microsoft AI-300認證考試需要相當過硬的專業知識。我們VCESoft是可以為你提供通過Microsoft AI-300認證考試捷徑的網站。我們VCESoft有針對Microsoft AI-300認證考試的培訓工具,可以有效的確保你通過Microsoft AI-300認證考試,獲得Microsoft AI-300認證考試證書。而且我們還可以幫你節約很多時間,這樣一個可以花更少時間更少金錢就可以獲得如此有價值的證書的方案對你是非常划算的。
AI-300最新考題: https://www.vcesoft.com/AI-300-pdf.html