
BONUS!!! Download part of RealVCE Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1tIxFasRVXhNnXiun7QvClbH_i27KVVcQ
RealVCE can develop well until now. Our developmental force comes from those who have obtained Data-Engineer-Associate exam certification with using our products. Today the Data-Engineer-Associate exam software provided by our RealVCE has been tested by more and more candidates, which has helped them get the Data-Engineer-Associate exam certification. You can download our free demo after you enter the homepage of our website. We hope that you can recognize our product. Once there is any update of Data-Engineer-Associate Exam software coming out after you purchased, we will immediately inform you, and make you ease to prepare for the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Operations and Support | 22% | - Monitor data pipelines
|
| Topic 2: Data Store Management | 26% | - Understand data cataloging
|
| Topic 3: Data Ingestion and Transformation | 34% | - Apply programming concepts
|
| Topic 4: Data Security and Governance | 18% | - Apply authentication and authorization
|
>> Amazon Data-Engineer-Associate Exam <<
Our evaluation system for Data-Engineer-Associate test material is smart and very powerful. First of all, our researchers have made great efforts to ensure that the data scoring system of our Data-Engineer-Associate test questions can stand the test of practicality. Once you have completed your study tasks and submitted your training results, the evaluation system will begin to quickly and accurately perform statistical assessments of your marks on the Data-Engineer-Associate Exam Torrent. You only need to spend 20 to 30 hours on practicing and consolidating of our Data-Engineer-Associate learning material, you will have a good result. After years of development practice, our Data-Engineer-Associate test torrent is absolutely the best. You will embrace a better future if you choose our Data-Engineer-Associate exam materials.
NEW QUESTION # 105
A data engineer must orchestrate a series of Amazon Athena queries that will run every day. Each query can run for more than 15 minutes.
Which combination of steps will meet these requirements MOST cost-effectively? (Choose two.)
Answer: A,B
Explanation:
Option A and B are the correct answers because they meet the requirements most cost-effectively. Using an AWS Lambda function and the Athena Boto3 client start_query_execution API call to invoke the Athena queries programmatically is a simple and scalable way to orchestrate the queries. Creating an AWS Step Functions workflow and adding two states to check the query status and invoke the next query is a reliable and efficient way to handle the long-running queries.
Option C is incorrect because using an AWS Glue Python shell job to invoke the Athena queries programmatically is more expensive than using a Lambda function, as it requires provisioning and running a Glue job for each query.
Option D is incorrect because using an AWS Glue Python shell script to run a sleep timer that checks every 5 minutes to determine whether the current Athena query has finished running successfully is not a cost- effective or reliable way to orchestrate the queries, as it wastes resources and time.
Option E is incorrect because using Amazon Managed Workflows for Apache Airflow (Amazon MWAA) to orchestrate the Athena queries in AWS Batch is an overkill solution that introduces unnecessary complexity and cost, as it requires setting up and managing an Airflow environment and an AWS Batch compute environment.
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 5: Data Orchestration, Section 5.2: AWS Lambda, Section 5.3: AWS Step Functions, Pages 125-135 Building Batch Data Analytics Solutions on AWS, Module 5: Data Orchestration, Lesson 5.1: AWS Lambda, Lesson 5.2: AWS Step Functions, Pages 1-15 AWS Documentation Overview, AWS Lambda Developer Guide, Working with AWS Lambda Functions, Configuring Function Triggers, Using AWS Lambda with Amazon Athena, Pages 1-4 AWS Documentation Overview, AWS Step Functions Developer Guide, Getting Started, Tutorial: Create a Hello World Workflow, Pages 1-8
NEW QUESTION # 106
A retail company stores data from a product lifecycle management (PLM) application in an on-premises MySQL database. The PLM application frequently updates the database when transactions occur.
The company wants to gather insights from the PLM application in near real time. The company wants to integrate the insights with other business datasets and to analyze the combined dataset by using an Amazon Redshift data warehouse.
The company has already established an AWS Direct Connect connection between the on-premises infrastructure and AWS.
Which solution will meet these requirements with the LEAST development effort?
Answer: D
Explanation:
Problem Analysis:
The company needs near real-time replication of MySQL updates to Amazon Redshift.
Minimal development effort is required for this solution.
Key Considerations:
AWS DMS provides a full load + CDC (Change Data Capture) mode for continuous replication of database changes.
DMS integrates natively with both MySQL and Redshift, simplifying setup.
Solution Analysis:
Option A: AWS Glue Job
Glue is batch-oriented and does not support near real-time replication.
Option B: DMS with Full Load + CDC
Efficiently handles initial database load and continuous updates.
Requires minimal setup and operational overhead.
Option C: AppFlow SDK
AppFlow is not designed for database replication. Custom connectors increase development effort.
Option D: DataSync
DataSync is for file synchronization and not suitable for database updates.
Final Recommendation:
Use AWS DMS in full load + CDC mode for continuous replication.
Reference:
AWS Database Migration Service Documentation
Setting Up DMS with Redshift
NEW QUESTION # 107
A company runs an AWS Glue workflow every day to process time series data from an Amazon S3 bucket.
The workflow loads the data into an Amazon Redshift Serverless table. The company observes that some of the jobs in the workflow occasionally fail.
A data engineer must receive a notification when the Redshift table does not contain the most recent data.
Which solution will meet this requirement in the MOST operationally efficient way?
Answer: D
Explanation:
Option B is the most operationally efficient because it checks the business requirement directly: whether the target table contains the most recent data, not merely whether a job failed. Monitoring only failures (Options C and D) can produce false positives (a job failure might not impact freshness) and false negatives (a job can succeed but still load stale or incomplete data). The study material emphasizes implementing data quality validation as part of the ETL process so data can be verified before or as it is stored, rather than relying only on pipeline execution status.
Using a data quality rule focused on freshness (for example, validating that a "max event timestamp" or
"latest partition date" meets today's expected value) lets the pipeline detect stale loads even when the workflow runs. Then, an EventBridge rule can route failures of that data quality check to SNS for immediate notification, keeping operations serverless and centralized. Macie (Option A) is designed for sensitive-data discovery/classification, not operational "freshness" checks on Redshift tables, so it adds unnecessary services and effort compared to a Glue-native data quality validation approach.
NEW QUESTION # 108
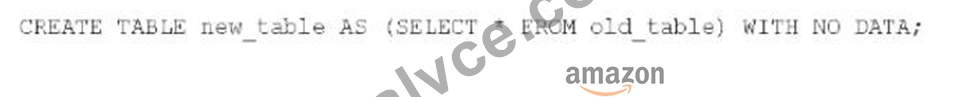
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?



Answer: B
Explanation:
Problem Analysis:
The goal is to create a new empty table in Athena with the same schema as an existing table (old_table).
The solution must avoid copying any data.
Key Considerations:
CREATE TABLE AS (CTAS) is commonly used in Athena for creating new tables based on an existing table.
Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
Solution Analysis:
Option A: Copies both schema and data. Does not meet the requirement for an empty table.
Option B: Inserts data into an existing table, which does not create a new table.
Option C: Creates an empty table but does not copy the schema.
Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
Final Recommendation:
Use D. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATA to create an empty table with the same schema.
Athena CTAS Queries
CREATE TABLE Statement in Athena
NEW QUESTION # 109
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Answer: B
Explanation:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using Amazon Timestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
* A. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream.
These steps can increase the latency and complexity of the solution.
* B. Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
* D. Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
References:
* 1: Amazon Managed Streaming for Apache Flink
* 2: Amazon Timestream
* 3: Amazon QuickSight
* : Analyze data in Amazon Timestream using Grafana
* : Amazon Kinesis Data Firehose
* : Amazon Aurora
* : AWS Glue Bookmarks
* : AWS Glue Job and Crawler Scheduling
NEW QUESTION # 110
......
While making revisions and modifications to the Amazon Data-Engineer-Associate practice exam, our team takes reports from over 90,000 professionals worldwide to make the Amazon Data-Engineer-Associate Exam Questions foolproof. To make you capable of preparing for the Data-Engineer-Associate exam smoothly, we provide actual Amazon Data-Engineer-Associate exam dumps.
Data-Engineer-Associate Latest Dumps Pdf: https://www.realvce.com/Data-Engineer-Associate_free-dumps.html
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by RealVCE: https://drive.google.com/open?id=1tIxFasRVXhNnXiun7QvClbH_i27KVVcQ