100% Pass-Rate Valid Braindumps Certified-Data-Engineer-Professional Ppt - Win Your Databricks Certificate with Top Score

People from all walks of life all work hard for the future. You must work hard to upgrade your IT skills. Then, do you have obtained Databricks Certified-Data-Engineer-Professional certificate which is very popular? How much do you know about Certified-Data-Engineer-Professional test? If you want to pass Certified-Data-Engineer-Professional exam without enough exam related knowledge, how should you do? But don't you worry: ITExamSimulator will give assistance to you.
| Section | Objectives |
|---|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Create pipeline components using control flow operators such as if/else and foreach
- 4. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 7. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
>> Valid Braindumps Certified-Data-Engineer-Professional Ppt <<
Latest updated Databricks Valid Braindumps Certified-Data-Engineer-Professional Ppt Are Leading Materials & Top Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional
It is important to mention here that the Databricks Certified Data Engineer Professional practice questions played important role in their Databricks Certified-Data-Engineer-Professional Exams preparation and their success. So we can say that with the Databricks Certified-Data-Engineer-Professional exam questions you will get everything that you need to learn, prepare and pass the difficult Databricks Certified-Data-Engineer-Professional exam with good scores. The ITExamSimulator Certified-Data-Engineer-Professional Exam Questions are designed and verified by experienced and qualified Databricks Certified-Data-Engineer-Professional exam trainers. They work together and share their expertise to maintain the top standard of Databricks Certified-Data-Engineer-Professional exam practice test. So you can get trust on Databricks Certified-Data-Engineer-Professional exam questions and start preparing today.
Databricks Certified Data Engineer Professional Sample Questions (Q103-Q108):
NEW QUESTION # 103
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
- A. Use &Pip install in a notebook cell
- B. Install libraries from PyPi using the cluster UI
- C. Use &sh install in a notebook cell
- D. Run source env/bin/activate in a notebook setup script
Answer: B
Explanation:
Installing a Python package scoped at the notebook level to all nodes in the currently active cluster in Databricks can be achieved by using the Libraries tab in the cluster UI. This interface allows you to install libraries across all nodes in the cluster. While the %pip command in a notebook cell would only affect the driver node, using the cluster UI ensures that the package is installed on all nodes.
NEW QUESTION # 104
The following table consists of items found in user carts within an e-commerce website.
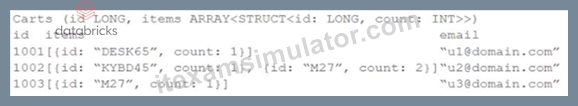
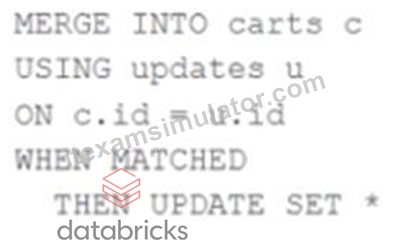
The following MERGE statement is used to update this table using an updates view, with schema evolution enabled on this table.
How would the following update be handled?
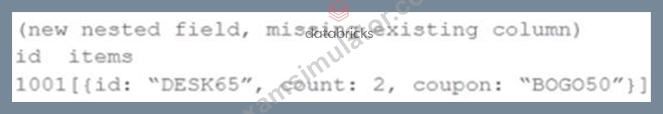
- A. The update is moved to separate ''restored'' column because it is missing a column expected in the target schema.
- B. The new restored field is added to the target schema, and dynamically read as NULL for existing unmatched records.
- C. The update throws an error because changes to existing columns in the target schema are not supported.
- D. The new nested field is added to the target schema, and files underlying existing records are updated to include NULL values for the new field.
Answer: D
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
NEW QUESTION # 105
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
- A. Use Partner Connect to create linked datasets, and apply table ACLs at the source system to govern access through Databricks.
- B. Create external locations and storage credentials to connect to each database, then register foreign tables in Unity Catalog.
- C. Mirror the external datasets into Delta Lake using Auto Loader, and govern them using Data Lineage and System Tables.
- D. Configure connections and foreign catalog in Unity Catalog, then grant access to foreign catalogs, schemas, and tables using Unity Catalog permissions.
Answer: D
Explanation:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
NEW QUESTION # 106
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
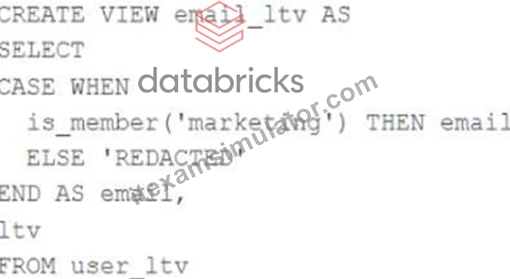
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. Only the email and itv columns will be returned; the email column will contain all null values.
- B. The email and ltv columns will be returned with the values in user itv.
- C. The email, age. and ltv columns will be returned with the values in user ltv.
- D. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- E. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row.
Answer: E
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
NEW QUESTION # 107
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
- A. Execute DESCRIBE HISTORY customer_churn_params to obtain the full operation metrics for the update, including a log of all records that have been added or modified.
- B. Parse the Spark event logs to identify those rows that were updated, inserted, or deleted.
- C. Execute a query to calculate the difference between the new version and the previous version using Delta Lake's built-in versioning and time travel functionality.
- D. Parse the Delta Lake transaction log to identify all newly written data files.
Answer: C
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 108
......
The ITExamSimulator is one of the top-rated and renowned platforms that have been offering real and valid Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice test questions for many years. During this long time period countless Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam candidates have passed their dream Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam and they are now certified Databricks professionals and pursuing a rewarding career in the market.
Exam Certified-Data-Engineer-Professional Assessment: https://www.itexamsimulator.com/Certified-Data-Engineer-Professional-brain-dumps.html
- Certified-Data-Engineer-Professional Pass4sure Questions - Certified-Data-Engineer-Professional Vce Training - Certified-Data-Engineer-Professional Free Demo 📳 Enter ⏩ www.dumpsmaterials.com ⏪ and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download for free 😜Latest Braindumps Certified-Data-Engineer-Professional Ebook
- Certified-Data-Engineer-Professional Question Explanations 🍌 Certified-Data-Engineer-Professional Trustworthy Practice 💐 PDF Certified-Data-Engineer-Professional Cram Exam 🗾 Copy URL { www.pdfvce.com } open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 👉Latest Braindumps Certified-Data-Engineer-Professional Ebook
- 2026 Valid Braindumps Certified-Data-Engineer-Professional Ppt | Pass-Sure Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass ☑ Search for ▛ Certified-Data-Engineer-Professional ▟ and obtain a free download on ➡ www.vce4dumps.com ️⬅️ 🎭Certified-Data-Engineer-Professional Dumps Free
- Certified-Data-Engineer-Professional Exam Voucher 📳 Certified-Data-Engineer-Professional Certification 😿 Real Certified-Data-Engineer-Professional Torrent 🛥 Search for [ Certified-Data-Engineer-Professional ] and obtain a free download on ⮆ www.pdfvce.com ⮄ ↩Certified-Data-Engineer-Professional Certification
- Pass Guaranteed Databricks Certified-Data-Engineer-Professional - First-grade Valid Braindumps Databricks Certified Data Engineer Professional Ppt 🥴 Search on ( www.dumpsmaterials.com ) for ➡ Certified-Data-Engineer-Professional ️⬅️ to obtain exam materials for free download 🦳Certified-Data-Engineer-Professional Review Guide
- Newest Valid Braindumps Certified-Data-Engineer-Professional Ppt | Certified-Data-Engineer-Professional 100% Free Exam Assessment 🚵 Simply search for ➥ Certified-Data-Engineer-Professional 🡄 for free download on ▶ www.pdfvce.com ◀ 🚆Certified-Data-Engineer-Professional Valid Braindumps Files
- Pass Guaranteed Databricks Certified-Data-Engineer-Professional - First-grade Valid Braindumps Databricks Certified Data Engineer Professional Ppt 🦢 Easily obtain free download of ▷ Certified-Data-Engineer-Professional ◁ by searching on ✔ www.pdfdumps.com ️✔️ 💬Technical Certified-Data-Engineer-Professional Training
- Pass Guaranteed Databricks Certified-Data-Engineer-Professional - First-grade Valid Braindumps Databricks Certified Data Engineer Professional Ppt 🏹 Simply search for 【 Certified-Data-Engineer-Professional 】 for free download on ➤ www.pdfvce.com ⮘ 🚪Certified-Data-Engineer-Professional Dumps Free
- Certified-Data-Engineer-Professional Dumps Free ❗ Real Certified-Data-Engineer-Professional Torrent 🚗 Technical Certified-Data-Engineer-Professional Training 📻 Search for 【 Certified-Data-Engineer-Professional 】 and download exam materials for free through ▷ www.verifieddumps.com ◁ ✍Real Certified-Data-Engineer-Professional Torrent
- New Certified-Data-Engineer-Professional Dumps Sheet 📎 New Certified-Data-Engineer-Professional Dumps Sheet 🗓 Test Certified-Data-Engineer-Professional Objectives Pdf ☃ Open ➡ www.pdfvce.com ️⬅️ enter ⇛ Certified-Data-Engineer-Professional ⇚ and obtain a free download 🏗Real Certified-Data-Engineer-Professional Torrent
- Certified-Data-Engineer-Professional Certification 🟫 PDF Certified-Data-Engineer-Professional Cram Exam 🕖 Certified-Data-Engineer-Professional Trustworthy Practice 🐡 The page for free download of ➽ Certified-Data-Engineer-Professional 🢪 on ⇛ www.troytecdumps.com ⇚ will open immediately 📥Online Certified-Data-Engineer-Professional Training Materials
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes