P.S. Free & New Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by VCE4Dumps: https://drive.google.com/open?id=1Ltb_ZpHScJgUc1aHuL_ze-0B4yfcOpkt
Now, I am glad to introduce a secret weapon for all of the candidates to pass the exam as well as get the related certification without any more ado-- our Databricks-Certified-Data-Analyst-Associate study materials. We aim to help as many people as possible rather than earning as much money as possible. With our Databricks-Certified-Data-Analyst-Associate practice test, you only need to spend 20 to 30 hours in preparation since there are all essence contents in our study materials. What's more, if you need any after service help on our Databricks-Certified-Data-Analyst-Associate Exam Guide, our after service staffs will always here to offer the most thoughtful service for you.
| Section | Weight | Objectives |
|---|---|---|
| Analyzing Queries | 15% | - Execution plans and analysis - Query history and auditing - Liquid clustering and indexing - Performance optimization |
| Importing Data | 5% | - S3 and cloud storage integration - Databricks Marketplace - Delta Sharing - API and Auto Loader - UI-based data ingestion |
| Understanding of Databricks Data Intelligence Platform | 11% | - Lakehouse platform fundamentals - Core architecture and components - Workspace navigation and interface |
| Data Modeling with Databricks SQL | 5% | - Performance-oriented modeling - Delta table structure - Schema design principles |
| Securing Data | 8% | - Access control and permissions - Secure storage and compliance - Data governance policies |
| Executing Queries using Databricks SQL and Databricks SQL Warehouses | 20% | - ANSI SQL syntax and functions - Warehouse configuration and performance - Creating and managing views - Aggregations and grouping - Joining and combining datasets |
| Developing, Sharing, and Maintaining AI/BI Genie Spaces | 12% | - Natural language query setup - Genie space setup and configuration - Access control and sharing - Maintenance and improvement |
| Managing Data | 8% | - Dataset versioning and management - Unity Catalog usage - Discovering and registering datasets - Data cleaning and preparation |
| Creating Dashboards and Visualizations in Databricks | 16% | - Visualization types and best practices - Scheduling and sharing dashboards - Filtering and interactivity - Dashboard creation and layout |
>> Latest Databricks-Certified-Data-Analyst-Associate Exam Pass4sure <<
Undoubtedly, passing the Databricks Databricks-Certified-Data-Analyst-Associate certification exam is one big achievement. Regardless of how tough the Databricks-Certified-Data-Analyst-Associate exam is, it serves an important purpose of improving your skills and knowledge of a specific field. Once you become certified by Databricks Databricks-Certified-Data-Analyst-Associate, a whole new career scope will open up to you.
NEW QUESTION # 38
In which of the following situations will the mean value and median value of variable be meaningfully different?
Answer: D
Explanation:
The mean value of a variable is the average of all the values in a data set, calculated by dividing the sum of the values by the number of values. The median value of a variable is the middle value of the ordered data set, or the average of the middle two values if the data set has an even number of values. The mean value is sensitive to outliers, which are values that are very different from the rest of the data. Outliers can skew the mean value and make it less representative of the central tendency of the data. The median value is more robust to outliers, as it only depends on the middle values of the data. Therefore, when the variable contains a lot of extreme outliers, the mean value and the median value will be meaningfully different, as the mean value will be pulled towards the outliers, while the median value will remain close to the majority of the data1. References: Difference Between Mean and Median in Statistics (With Example) - BYJU'S
NEW QUESTION # 39
A data analyst needs to use the Databricks Lakehouse Platform to quickly create SQL queries and data visualizations. It is a requirement that the compute resources in the platform can be made serverless, and it is expected that data visualizations can be placed within a dashboard.
Which of the following Databricks Lakehouse Platform services/capabilities meets all of these requirements?
Answer: B
Explanation:
Databricks SQL is a serverless data warehouse on the Lakehouse that lets you run all of your SQL and BI applications at scale with your tools of choice, all at a fraction of the cost of traditional cloud data warehouses1. Databricks SQL allows you to create SQL queries and data visualizations using the SQL Analytics UI or the Databricks SQL CLI2. You can also place your data visualizations within a dashboard and share it with other users in your organization3. Databricks SQL is powered by Delta Lake, which provides reliability, performance, and governance for your data lake4. References:
* Databricks SQL
* Query data using SQL Analytics
* Visualizations in Databricks notebooks
* Delta Lake
NEW QUESTION # 40
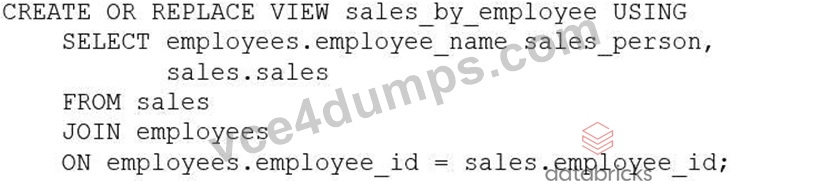
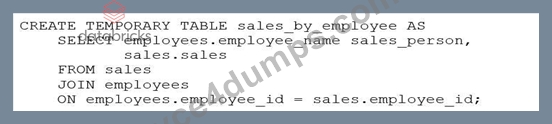
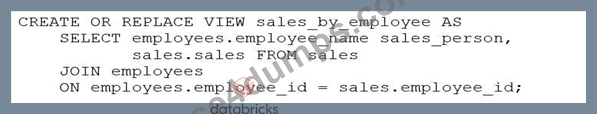
A business analyst has been asked to create a data entity/object called sales_by_employee. It should always stay up-to-date when new data are added to the sales table. The new entity should have the columns sales_person, which will be the name of the employee from the employees table, and sales, which will be all sales for that particular sales person. Both the sales table and the employees table have an employee_id column that is used to identify the sales person.
Which of the following code blocks will accomplish this task?
Answer: C
Explanation:
The SQL code provided in Option D is the correct way to create a view named sales_by_employee that will always stay up-to-date with the sales and employees tables. The code uses the CREATE OR REPLACE VIEW statement to define a new view that joins the sales and employees tables on the employee_id column. It selects the employee_name as sales_person and all sales for each employee, ensuring that the data entity
/object is always up-to-date when new data are added to these tables.
The answer can be verified from Databricks SQL documentation which provides insights on creating views using SQL queries, joining tables, and selecting specific columns to be included in the view. Reference link: Databricks SQL
NEW QUESTION # 41
Which of the following is a benefit of the Databricks Lakehouse Platform embracing open source technologies?
Answer: A
Explanation:
Option E is correct. A major benefit of open source technologies and open data formats is avoiding vendor lock-in. Databricks supports open formats and interfaces so data can be used across tools and systems rather than being locked into a proprietary platform. Cloud integrations, governance, and workload scalability are Databricks benefits, but the specific benefit of embracing open source is avoiding vendor lock-in. Official Databricks extract: "Using open data formats and interfaces helps to avoid" vendor lock-in, and Databricks states that no proprietary data formats are used because Delta Lake and Iceberg are open source.
NEW QUESTION # 42
A data analyst runs the following command:
INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers;
What is the result of running this command?
Answer: A
Explanation:
The command INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers is not a valid syntax for inserting data into a table in Databricks SQL. According to the documentation12, the correct syntax for inserting data into a table is either:
* INSERT { OVERWRITE | INTO } [ TABLE ] table_name [ PARTITION clause ] [ ( column_name [,
...] ) | BY NAME ] query
* INSERT INTO [ TABLE ] table_name REPLACE WHERE predicate query
The command in the question is missing the OVERWRITE or INTO keyword, and the query part that specifies the source of the data to be inserted. The TABLE keyword is optional and can be omitted.
The PARTITION clause and the column list are also optional and depend on the table schema and the data source. Therefore, the command in the question will fail with a syntax error.
INSERT | Databricks on AWS
INSERT - Azure Databricks - Databricks SQL | Microsoft Learn
NEW QUESTION # 43
......
You can also become part of this skilled and qualified community. To do this just enroll in the Databricks Certified Data Analyst Associate Exam Exam and start preparation with real and valid Databricks-Certified-Data-Analyst-Associate practice test questions right now. The Databricks Certified Data Analyst Associate Exam practice test questions are checked and verified by experienced and qualified Databricks-Certified-Data-Analyst-Associate Exam trainers. So you can trust VCE4Dumps Databricks Certified Data Analyst Associate Exam practice test questions and start preparation with confidence.
Databricks-Certified-Data-Analyst-Associate Exam Cost: https://www.vce4dumps.com/Databricks-Certified-Data-Analyst-Associate-valid-torrent.html
BTW, DOWNLOAD part of VCE4Dumps Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1Ltb_ZpHScJgUc1aHuL_ze-0B4yfcOpkt