Die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung von It-Pruefung können Ihnen helfen, Ihren Traum zu realisieren, weil es alle Zertifizierungsantworten zur Microsoft DP-750 Prüfung hat. Mit It-Pruefung können Sie sich ganz gut auf die Prüfung vorbereiten. Per unsere guten Schulungsunterlagen von guter Qualität können Sie sicher die Microsoft DP-750 Prüfung bestehen und eine glänzende Zukunft haben.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
Aus der Perspektive der Prüfung ist es notwendig, Ihnen die Prüfungstechnik zu lehren. Sie sollen weise wählen und keine Chance verpassen. It-Pruefung ist eine großartige Website, die gute Schulungsressourcen bietet, die Prüfungs- und Untersuchungsmaterialien und ausführliche Fragen und Antworten enthalten. Die Prüfungswebsites nehmen in den letzten Jahren rasch zu. Das ist vielleicht der Grund, wieso Sie so verwirrt gegenüber der Microsoft DP-750 Zertifizierungsprüfung sind. Die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung von It-Pruefung werden von einigen Fachleuten und vielen Kandidaten bewiesen, dass sie effizient sind. Sie können Ihnen helfen, die Microsoft DP-750 Zertifizierungsprüfung zu bestehen.
91. Frage
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
Drag and Drop Question
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.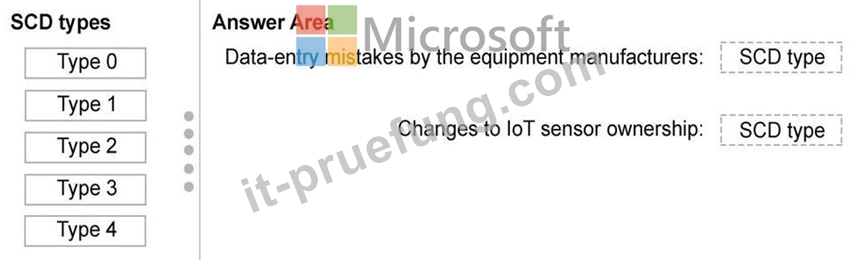
Antwort:
Begründung: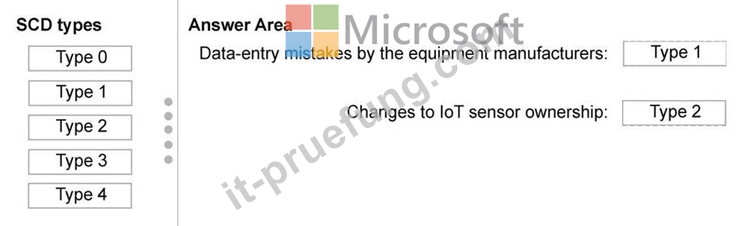
92. Frage
You have an Azure Databricks workspace named Workspace1 that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1. Another user commits changes to Notebook1 in main.
When you attempt to merge Branch1 into main, the merge fails due to conflicts.
You need to merge Branch1 into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Antwort: D
Begründung:
To resolve the merge conflict and keep all changes from both branches, you must pull the updated main branch into your feature branch, resolve the conflicts manually within Databricks or a local Git tool, and then merge.
Reference:
https://devactivity.com/insights/streamlining-your-git-workflow-resolving-branch-behind-main- issues-in-your-git-repo/
93. Frage
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to run the following PySpark code.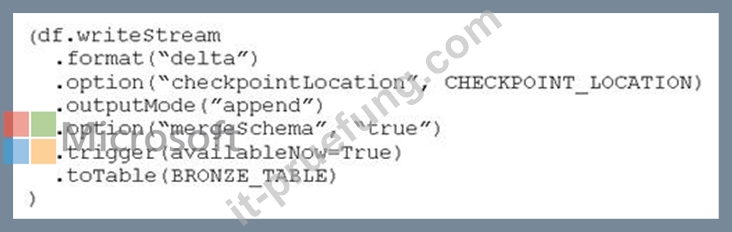
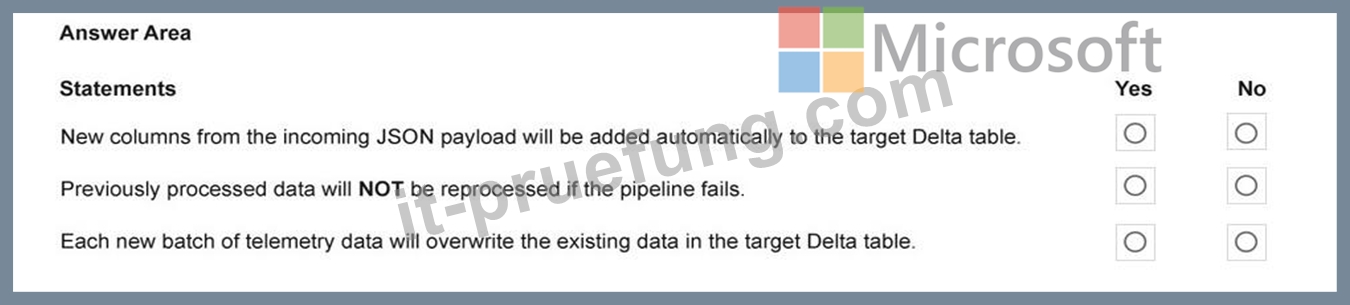
Antwort:
Begründung: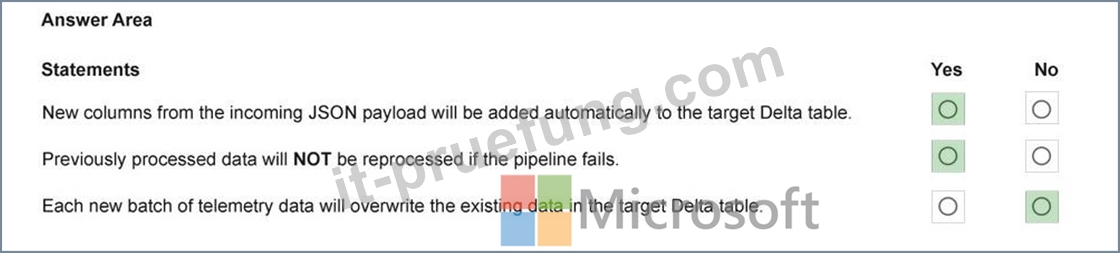
94. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Antwort: C
Begründung:
The correct answer is B - configure a checkpoint location.
A checkpoint is the Structured Streaming mechanism for fault tolerance. Databricks writes the committed offset (i.e., how far through the source stream the job has successfully read and processed) to a durable path in ADLS Gen2 or DBFS after each micro-batch. When the cluster restarts, the engine reads that offset and resumes from the next unprocessed record - nothing is reprocessed, nothing is skipped.
Option A (increase trigger interval) affects how frequently micro-batches run but does nothing to record progress between runs. Option C (watermark) handles late-arriving events in event-time windows but doesn't control source offset tracking. Option D (enable CDF on the target table) tracks changes made to a Delta table for downstream consumers - it has no bearing on the streaming job's own fault tolerance or offset management.
Checkpointing is a required configuration for any production streaming job. Without it, every cluster restart triggers a full replay from the source.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
95. Frage
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Antwort: D
Begründung:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
96. Frage
......
Die Produkte von PassTest sind für diejenigen, die sich an der Microsoft DP-750 Zertifizierungsprüfung beteiligen,geeignet. Die Schulungsmaterialien von It-Pruefung enthalten nicht nur Trainingsmaterialien zur Microsoft DP-750 Zertifizierungsprüfung, um Ihre Fachkenntnisse zu konsolidieren, sondern auch die genauen Prüfungsfragen und Antworten. Wir versprechen, dass Sie die Microsoft DP-750 Zertifizierungsprüfung beim ersten Versuch mit einer hohen Note bestehen können.
DP-750 Zertifikatsdemo: https://www.it-pruefung.com/DP-750.html