Databricks - Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam–Updated Reliable Test Guide

Even in a globalized market, the learning material of similar Databricks-Certified-Professional-Data-Engineer doesn't have much of a share, nor does it have a high reputation or popularity. In this dynamic and competitive market, the Databricks-Certified-Professional-Data-Engineer study materials can be said to be leading and have absolute advantages. In order to facilitate the user real-time detection of the learning process, we Databricks-Certified-Professional-Data-Engineer practice materials provided by the questions and answers are all in the past.it is closely associated, as our experts in constantly update products every day to ensure the accuracy of the problem, so all Databricks-Certified-Professional-Data-Engineer practice materials are high accuracy.
| Section | Weight | Objectives |
|---|
| Data Governance | 7% | - Policy enforcement
- Unity Catalog management
- Data lineage and metadata tracking
|
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks
- Standardization and normalization
- Handling missing or inconsistent data
|
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing)
- Cluster configuration and scaling
- Query optimization and caching
|
| Data Sharing and Federation | 5% | - Unity Catalog data sharing
- Cross-workspace and cross-cloud access
|
| Data Modelling | 6% | - Medallion Architecture implementation
- Schema design and management
- Delta Lake table design
|
| Monitoring and Alerting | 10% | - Pipeline observability and logging
- Performance and health monitoring
- Setting up alerts and notifications
|
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors
- Deployment using bundles, CLI, and APIs
- CI/CD and DevOps practices
|
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic
- Integration with Databricks APIs and tools
- Data transformation and aggregation
|
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution
- Connecting to diverse data sources
- Auto Loader and streaming ingestion
|
| Ensuring Data Security and Compliance | 10% | - Data encryption and masking
- Access control and permissions
- Compliance standards implementation
|
>> Databricks-Certified-Professional-Data-Engineer Reliable Test Guide <<
Valid Databricks-Certified-Professional-Data-Engineer Reliable Test Guide offer you accurate Latest Exam Duration | Databricks Databricks Certified Professional Data Engineer Exam
In recent years, the market has been plagued by the proliferation of learning products on qualifying examinations, so it is extremely difficult to find and select our Databricks-Certified-Professional-Data-Engineer test questions in many similar products. However, we believe that with the excellent quality and good reputation of our study materials, we will be able to let users select us in many products. Our study materials allow users to use the Databricks-Certified-Professional-Data-Engineer Certification guide for free to help users better understand our products better. Even if you find that part of it is not for you, you can still choose other types of learning materials in our study materials. We can meet all your requirements and solve all your problems by our Databricks-Certified-Professional-Data-Engineer certification guide.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q127-Q132):
NEW QUESTION # 127
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
- A. Databricks has autotuned to a smaller target file size based on the amount of data in each partition
- B. Databricks has autotuned to a smaller target file size based on the overall size of data in the table
- C. Z-order indices calculated on the table are preventing file compaction C Bloom filler indices calculated on the table are preventing file compaction
- D. Databricks has autotuned to a smaller target file size to reduce duration of MERGE operations
Answer: D
Explanation:
Explanation
This is the correct answer because Databricks has a feature called Auto Optimize, which automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones and sorting data within each file by a specified column. However, Auto Optimize also considers the trade-off between file size and merge performance, and may choose a smaller target file size to reduce the duration of merge operations, especially for streaming workloads that frequently update existing records. Therefore, it is possible that Auto Optimize has autotuned to a smaller target file size based on the characteristics of the streaming production job. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Optimize" section.https://docs.databricks.com/en/delta/tune-file-size.html#autotune-table 'Autotune file size based on workload'
NEW QUESTION # 128
Which of the following commands results in the successful creation of a view on top of the delta stream(stream on delta table)?
- A. Spark.read.format("delta").table("sales").trigger("stream").createOrReplaceTempView("streaming_vw")
- B. Spark.readStream.format("delta").table("sales").createOrReplaceTempView("streaming_vw")
- C. You can not create a view on streaming data source.
- D. Spark.read.format("delta").table("sales").mode("stream").createOrReplaceTempView("streaming_vw")
- E. Spark.read.format("delta").table("sales").createOrReplaceTempView("streaming_vw")
- F. Spark.read.format("delta").stream("sales").createOrReplaceTempView("streaming_vw")
Answer: B
Explanation:
Explanation
The answer is
Spark.readStream.table("sales").createOrReplaceTempView("streaming_vw") When you load a Delta table as a stream source and use it in a streaming query, the query processes all of the data present in the table as well as any new data that arrives after the stream is started.
You can load both paths and tables as a stream, you also have the ability to ignore deletes and changes(updates, Merge, overwrites) on the delta table.
Here is more information,
https://docs.databricks.com/delta/delta-streaming.html#delta-table-as-a-source
NEW QUESTION # 129
You were asked to write python code to stop all running streams, which of the following command can be used to get a list of all active streams currently running so we can stop them, fill in the blank.
1.for s in _______________:
2. s.stop()
- A. getActiveStreams()
- B. Spark.getActiveStreams()
- C. activeStreams()
- D. spark.streams.getActive
- E. spark.streams.active
Answer: E
NEW QUESTION # 130
Which of the following techniques structured streaming uses to ensure recovery of failures during stream processing?
- A. Checkpointing and write-ahead logging
- B. Write ahead logging and watermarking
- C. Checkpointing and Watermarking
- D. Checkpointing and Idempotent sinks
- E. Delta time travel
- F. The stream will failover to available nodes in the cluster
Answer: A
Explanation:
Explanation
The answer is Checkpointing and write-ahead logging.
Structured Streaming uses checkpointing and write-ahead logs to record the offset range of data being processed during each trigger interval.
NEW QUESTION # 131
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
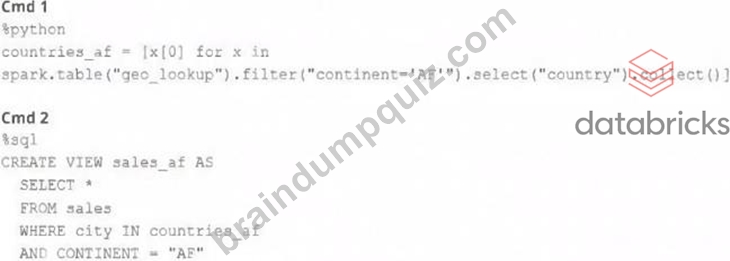
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
- B. Both commands will fail. No new variables, tables, or views will be created.
- C. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- D. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
- E. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
Answer: A
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified Reference: [Databricks Certified Data Engineer Professional], under "Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
NEW QUESTION # 132
......
Together, the after-sale service staffs in our company share a passion for our customers, an intense focus on teamwork, speed and agility, and a commitment to trust and respect for all individuals. At present, our company is a leading global provider of Databricks-Certified-Professional-Data-Engineer preparation exam in the international market. Therefore, after buying our Databricks-Certified-Professional-Data-Engineer Study Guide, if you have any questions about our Databricks-Certified-Professional-Data-Engineer study materials, please just feel free to contact with our online after sale service staffs on our Databricks-Certified-Professional-Data-Engineer exam questions.
Databricks-Certified-Professional-Data-Engineer Latest Exam Duration: https://www.braindumpquiz.com/Databricks-Certified-Professional-Data-Engineer-exam-material.html
- Databricks-Certified-Professional-Data-Engineer Reliable Exam Materials 💭 Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet 🍕 Databricks-Certified-Professional-Data-Engineer Mock Exams 🏊 Search on ▷ www.vceengine.com ◁ for ▶ Databricks-Certified-Professional-Data-Engineer ◀ to obtain exam materials for free download 🦠Databricks-Certified-Professional-Data-Engineer Latest Exam Practice
- 100% Pass Databricks - Pass-Sure Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam Reliable Test Guide 📖 Open website ➤ www.pdfvce.com ⮘ and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free download 〰Databricks-Certified-Professional-Data-Engineer Reliable Test Voucher
- 100% Pass Databricks - Pass-Sure Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam Reliable Test Guide 🔒 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and easily obtain a free download on ☀ www.examcollectionpass.com ️☀️ 🍗Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet
- 2026 High Pass-Rate Databricks-Certified-Professional-Data-Engineer Reliable Test Guide | Databricks Certified Professional Data Engineer Exam 100% Free Latest Exam Duration 🦍 Search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ and obtain a free download on ➤ www.pdfvce.com ⮘ 🐲Databricks-Certified-Professional-Data-Engineer Reliable Test Voucher
- Valid Databricks-Certified-Professional-Data-Engineer Reliable Test Guide - Fast Download Databricks-Certified-Professional-Data-Engineer Latest Exam Duration - Latest Valid Databricks-Certified-Professional-Data-Engineer Study Materials ↙ Search on ▛ www.exam4labs.com ▟ for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to obtain exam materials for free download ⬛Databricks-Certified-Professional-Data-Engineer Mock Exams
- Exam Databricks-Certified-Professional-Data-Engineer Material 🏳 Sample Databricks-Certified-Professional-Data-Engineer Questions Answers 🚬 Databricks-Certified-Professional-Data-Engineer Latest Exam Practice 🐮 Download ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free by simply searching on ✔ www.pdfvce.com ️✔️ 🦓Pdf Databricks-Certified-Professional-Data-Engineer Version
- Download www.prepawayete.com Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps Today and Start this Journey 🎳 Search for 「 Databricks-Certified-Professional-Data-Engineer 」 and download exam materials for free through ⮆ www.prepawayete.com ⮄ 🏦Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf
- Databricks-Certified-Professional-Data-Engineer Quiz 🚐 Databricks-Certified-Professional-Data-Engineer Reliable Test Voucher 🔨 Databricks-Certified-Professional-Data-Engineer Practice Questions 💸 Easily obtain free download of ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ by searching on [ www.pdfvce.com ] 🚚Databricks-Certified-Professional-Data-Engineer Reliable Exam Materials
- Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet 🕥 Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet 🎨 Detailed Databricks-Certified-Professional-Data-Engineer Answers 😱 Enter ▷ www.pdfdumps.com ◁ and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to download for free 🎍Databricks-Certified-Professional-Data-Engineer Test Lab Questions
- Databricks-Certified-Professional-Data-Engineer Reliable Test Voucher 🔢 Test Databricks-Certified-Professional-Data-Engineer Practice 🥼 Databricks-Certified-Professional-Data-Engineer Quiz 🔐 Easily obtain { Databricks-Certified-Professional-Data-Engineer } for free download through “ www.pdfvce.com ” 🦇Databricks-Certified-Professional-Data-Engineer Practice Questions
- Free PDF Databricks - Databricks-Certified-Professional-Data-Engineer Authoritative Reliable Test Guide 🍩 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and obtain a free download on [ www.troytecdumps.com ] ☃Databricks-Certified-Professional-Data-Engineer Test Guide Online
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, zenwriting.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes