You can use your smart phones, laptops, the tablet computers or other equipment to download and learn our AI-500 learning dump. Moreover, our customer service team will reply the clients’ questions patiently and in detail at any time and the clients can contact the online customer service even in the midnight. The clients at home and abroad can purchase our AI-500 Certification Questions online. Our service covers all around the world and the clients can receive our AI-500 study practice guide as quickly as possible.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Design and implement evaluation and validation strategies
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Specify technology components for multi-agent solutions
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Implement agent memory, context management, and knowledge integration
|
>> AI-500 Valid Exam Objectives <<
High quality and high accuracy AI-500 real materials like ours can give you confidence and reliable backup to get the certificate smoothly because our experts have extracted the most frequent-tested points for your reference, because they are proficient in this exam who are dedicated in this area over ten years. Besides, from economic perspective, our AI-500 study dumps are priced reasonably so we made a balance between delivering satisfaction to customers and doing our own jobs. So in this critical moment, our AI-500 real materials will make you satisfied. Our AI-500 exam materials can provide integrated functions. You can learn a great deal of knowledge and get the certificate of the exam at one order like win-win outcome at one try.
NEW QUESTION # 51
You have a Microsoft Foundry project that includes four independent analysis agents. Each agent invocation consumes 500 tokens per minute (TPM) from a Foundry deployment that has a TPM rate limit of 1,000.
After each agent completes, it writes 200 small records to Microsoft Dataverse. Running multiple agents simultaneously causes write bursts that result in HTTP 429 (Too Many Requests) responses.
You need to reduce the end-to-end task duration, while preventing provider and platform throttling. The solution must meet the following requirements:
* Keep as much agent parallelism as the TPM rate limit permits.
* Handle Dataverse throttling without sending premature retries.
How should you configure the orchestration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.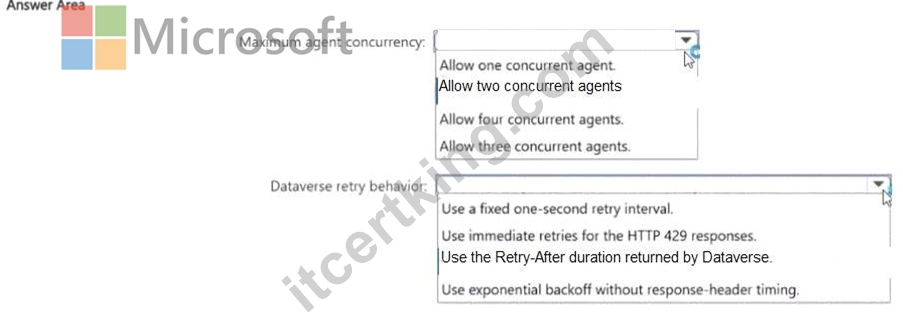
Answer:
Explanation: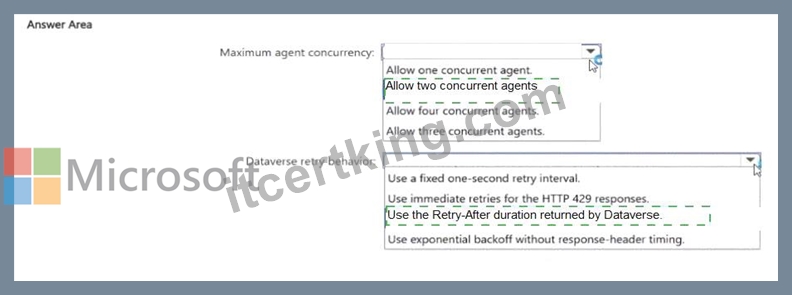
Explanation:
Maximum agent concurrency: Two agents; Dataverse retry behavior: Respect the Retry-After duration returned by Dataverse.
Each analysis agent consumes 500 TPM and the deployment permits 1,000 TPM, so at most two agents can run simultaneously without exceeding the stated model limit. Running only one wastes available parallelism; running three or four violates the limit. The separate Dataverse problem is HTTP 429 service-protection throttling. Microsoft Dataverse returns a `Retry-After` duration that tells clients how long to wait before retrying. Respecting that value prevents premature retries from worsening the overload condition. A fixed retry interval or immediate retry ignores the server ' s current capacity signal. The orchestration should therefore cap model-side concurrency at two and, after each agent finishes, pace Dataverse writes according to the returned retry guidance. This combination minimizes task duration while honoring both provider and platform throttling constraints. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Dataverse service protection API limits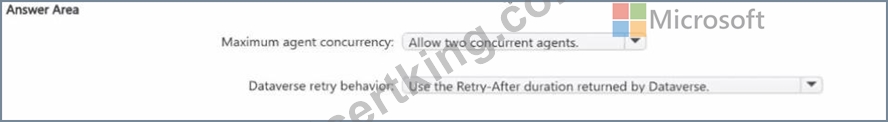
NEW QUESTION # 52
You have a Microsoft Foundry Agent Sen/ice solution that includes two agents.
You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create a dedicated memory store for each agent and set scope for each memory search tool to
{{Suserld}} Does this meet the goal?
Answer: B
Explanation:
A dedicated memory store for each agent establishes agent-domain isolation. Setting each memory search tool
' s scope to the current user identity establishes the second isolation dimension: users within the same agent domain receive separate logical memory collections. Microsoft Foundry Memory documents `scope` as the partitioning mechanism and specifically supports `{{$userId}}` for automatic per-user isolation. Memory associated with one scope can be deleted without removing memories stored under other scopes, which satisfies the deletion requirement. The source text renders the token imperfectly as `{{Suserld}}`; the current documented syntax is `{{$userId}}`. Interpreting the question as the documented user-scope token, the design satisfies domain isolation, user isolation, and per-user deletion. Therefore A, Yes, is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 53
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
Answer: A
Explanation:
Microsoft Foundry Agent Service is the managed option that best satisfies containerized production agent execution, dynamic scaling, and low administrative overhead. Hosted agents run in Foundry-managed container compute and scale according to workload demand while the platform manages much of the runtime, endpoint, identity, and operational plumbing. AKS could provide strong tenant/workload isolation and autoscaling, but it also requires Kubernetes cluster operations, policy, upgrades, node pools, and scaling configuration, which conflicts with the requirement to minimize administration as the tenant count grows.
Azure Container Instances is simpler but lacks the same managed autoscaling model, and GPU virtual machines create the highest infrastructure burden. Therefore C is the strongest fit for a SaaS platform that wants production agent compute without owning the orchestration platform. From an architecture perspective, the selection also creates explicit ownership and boundaries that can be tested independently. That matters in multi-agent systems because implicit sharing or loosely defined authority often becomes the source of cross- agent coupling, security drift, and difficult incident diagnosis.
Official Microsoft reference: Microsoft Foundry Agent Service overview
NEW QUESTION # 54
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.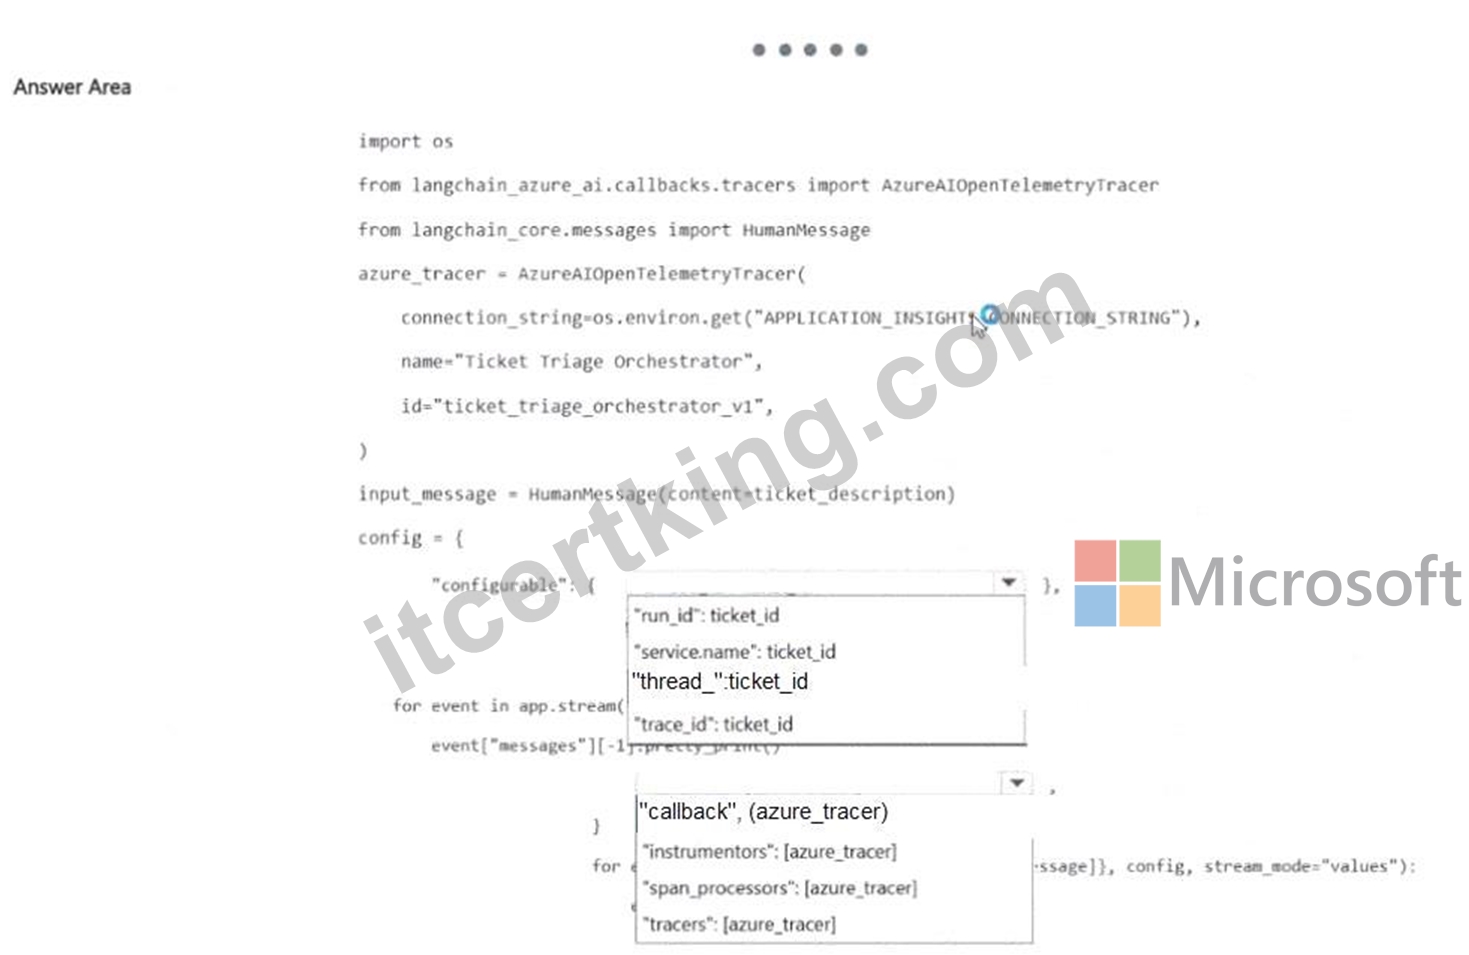
Answer:
Explanation: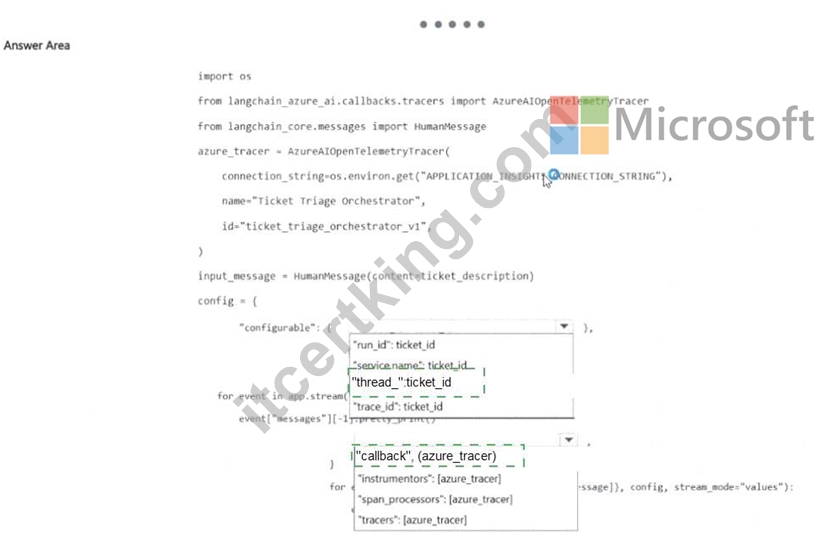
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents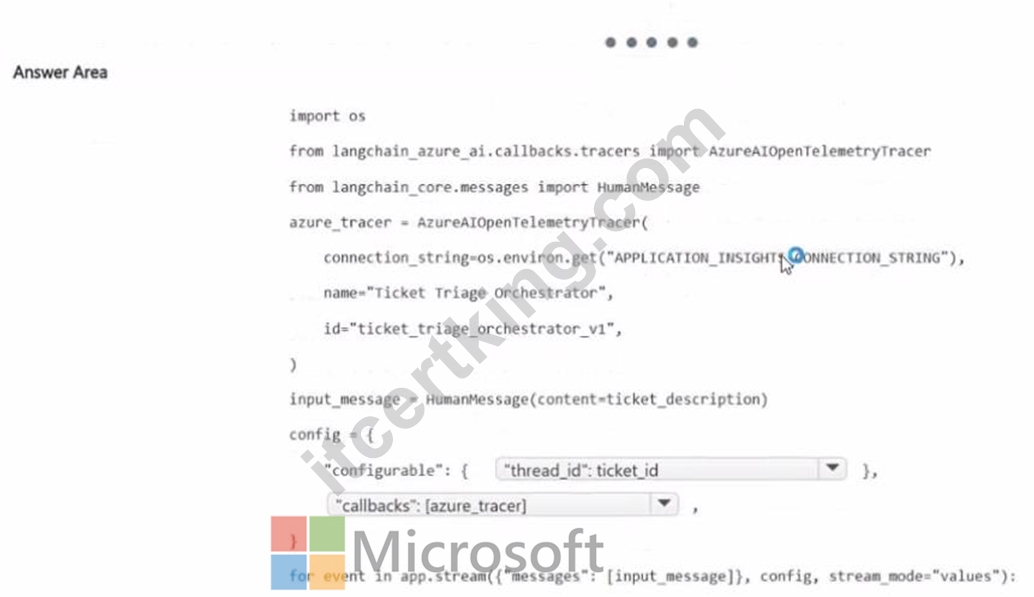
NEW QUESTION # 55
You need to implement an advanced prompt engineering strategy to resolve the Patient Intake agent issues.
The solution must prevent hardcoding new logic into the agent ' s core prompt.
What should you do?
Answer: B
Explanation:
The intake problem involves verbose, variable patient narratives and a requirement to avoid hardcoding new logic into the core prompt. Injecting dynamic context with curated few-shot examples gives the model representative demonstrations of how to identify clinically relevant symptoms while ignoring irrelevant narrative details. Microsoft AI-500 objectives explicitly include examples and dynamic context injection as advanced prompt-engineering techniques. Removing defensive guidance would weaken safety. Reducing the context window would not teach the model what information matters and could simply discard useful details.
Frequent full-model fine-tuning is operationally heavier and unnecessary for a behavior that can be demonstrated through curated examples. Dynamic few-shot context also allows the examples to be versioned and updated without rewriting the agent ' s base persona or application logic. Therefore C best addresses the extraction problem while preserving prompt lifecycle flexibility. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: AI-500 Study Guide - advanced prompt engineering
NEW QUESTION # 56
......
Now, if you use AI-500 preparation materials, you only need to learn twenty to thirty hours to go to the exam. And, you will have a 99% chance to pass the exam. Of course, you don't have to buy any other study materials. AI-500 exam questions can satisfy all your learning needs. During this time, you must really be learning. If you just put AI-500 Real Exam in front of them and didn't look at them, then we have no way. AI-500 exam questions want to work with you to help you achieve your dreams.
AI-500 Practice Questions: https://www.itcertking.com/AI-500_exam.html