P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by ActualTorrent: https://drive.google.com/open?id=1Q7yImm-UePJ_hZuFv7NBhKtzN2kzPTYG
Many users report to us that they are very fond of writing their own notes while they are learning. This will enhance their memory and make it easier to review. Our Databricks-Generative-AI-Engineer-Associate exam questions have created a PDF version of the Databricks-Generative-AI-Engineer-Associate practice material to meet the needs of this group of users. You can print the PDF version of the Databricks-Generative-AI-Engineer-Associate learning guide so that you can carry it with you. As long as you have time, you can take it out to read and write your own experience.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate Exam |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Exam Format: | Multiple choice |
| Passing Score: | 700/1000 or 70% |
| Exam Price: | USD 200 |
| Real Exam Qty: | 45 |
| Exam Duration: | 90 minutes |
| Available Languages: | Korean, Brazilian Portuguese, Japanese, English |
| Certificate Validity Period: | 2 years |
| Recommended Training: | Generative AI Engineering with Databricks |
| Exam Registration: | Databricks Certification Registration |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person test center |
| Pre Condition: | No formal prerequisites; recommended 6+ months hands-on experience building generative AI solutions |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate Updated Test Cram <<
Dear, when you find Databricks Databricks-Generative-AI-Engineer-Associate practice training, please assess it with careful analysis and do not miss it any more. The Databricks-Generative-AI-Engineer-Associate free demo is available and accessible for download. You can have a try and do your decision. In addition, it is very easy to make an order with our streamline process. Then you can get the Databricks-Generative-AI-Engineer-Associate Test Dumps in about 5-10 mins after payment and instant download it, and start study.100% is the guarantee of us, so please test assured to purchase Databricks-Generative-AI-Engineer-Associate practice torrent.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 70
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user's query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: A,D
Explanation:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here's why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
Define an evaluation metric: Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user's query and the expected response.
Recall measures the proportion of relevant information retrieved.
NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
Experiment with chunking strategies: Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user's query than others.
Evaluate performance: By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
Use the LLM as an evaluator: After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a "judge" function, where the LLM compares how well a given chunk answers previous user queries.
Optimize based on the LLM's judgment: By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
This metric could be a qualitative judgment on how closely the retrieved information matches the user's intent.
Tune chunking parameters: Based on the LLM's judgment, the engineer can adjust the chunk size or structure to better align with the LLM's responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
NEW QUESTION # 71
A Generative AI Engineer I using the code below to test setting up a vector store: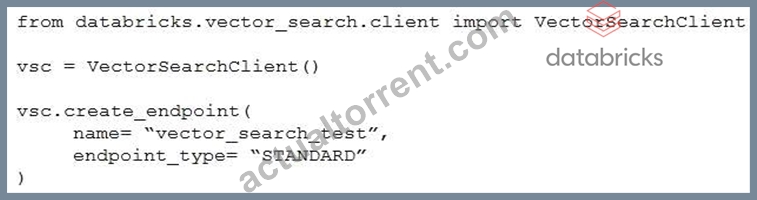
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
NEW QUESTION # 72
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: A
Explanation:
* Problem Context : When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options :
* Option A : Reaching out to data curators before using the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B : Using original data that you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C : Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D : Reaching out to the data curators after you have already started using the trained model is not appropriate . If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications.
It's essential to clarify the licensing terms before using the data, not after.
Thus, Option D is not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 73
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user's query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: A,D
NEW QUESTION # 74
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint's incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
Answer: D
Explanation:
* Problem Context: The goal is to monitor the serving endpoint for incoming requests and outgoing responses in a provisioned throughput model serving endpoint within a Retrieval-Augmented Generation (RAG) application. The current approach involves using a microservice to log requests and responses to a remote server, but the Generative AI Engineer is looking for a more streamlined solution within Databricks.
* Explanation of Options:
Option A: Vector Search: This feature is used to perform similarity searches within vector databases. It doesn't provide functionality for logging or monitoring requests and responses in a serving endpoint, so it's not applicable here.
Option B: Lakeview: Lakeview is not a feature relevant to monitoring or logging request-response cycles for serving endpoints. It might be more related to viewing data in Databricks Lakehouse but doesn't fulfill the specific monitoring requirement.
Option C: DBSQL: Databricks SQL (DBSQL) is used for running SQL queries on data stored in Databricks, primarily for analytics purposes. It doesn't provide the direct functionality needed to monitor requests and responses in real-time for an inference endpoint.
Option D: Inference Tables: This is the correct answer. Inference Tables in Databricks are designed to store the results and metadata of inference runs. This allows the system to log incoming requests and outgoing responses directly within Databricks, making it an ideal choice for monitoring the behavior of a provisioned serving endpoint. Inference Tables can be queried and analyzed, enabling easier monitoring and debugging compared to a custom microservice.
Thus, Inference Tables are the optimal feature for monitoring request and response logs within the Databricks infrastructure for a model serving endpoint.
NEW QUESTION # 75
......
Test Databricks-Generative-AI-Engineer-Associate Testking: https://www.actualtorrent.com/Databricks-Generative-AI-Engineer-Associate-questions-answers.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by ActualTorrent: https://drive.google.com/open?id=1Q7yImm-UePJ_hZuFv7NBhKtzN2kzPTYG