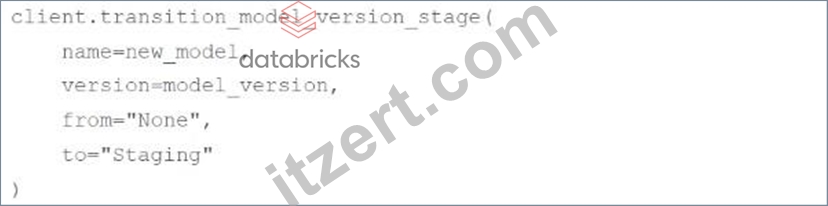
Databricks-Machine-Learning-Professional Dumps und Test Überprüfungen sind die beste Wahl für Ihre Databricks Databricks-Machine-Learning-Professional Testvorbereitung

BONUS!!! Laden Sie die vollständige Version der ITZert Databricks-Machine-Learning-Professional Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1yXfN21LeoIVF_BUdaDusdCOBg4Wj5Tce
Die Schulungsunterlagen zur Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung von unserem ITZert finden bei Kandidaten große Resonanz und somit genießen einen guten Ruf, das heißt, solange Sie die Schulungsunterlagen zur Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung von unserem ITZert wählen, werden Sie erfolgreich sein. Wir werden Ihnen alle Ihren bezahlten Summe zurückgeben, entweder Sie die Databricks-Machine-Learning-Professional Prüfung nicht bestehen, oder die Testaufgaben von Databricks Databricks-Machine-Learning-Professional irgend ein Qualitätsproblem haben. Darüber hinaus können Sie einjährige Aktualisierung kostenlos genießen, nachdem Sie unsere Produkte gekauft haben.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Exam Duration: | 120 minutes |
|---|
| Exam Price: | $200 USD |
|---|
| Real Exam Qty: | Approximately 45–60 |
|---|
| Passing Score: | Not publicly disclosed |
|---|
| Exam Format: | Multiple select, Multiple choice, Scenario-based questions |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Available Languages: | English |
|---|
| Recommended Training: | Databricks Academy Machine Learning Training |
|---|
| Exam Registration: | Databricks Certification Portal |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online proctored exam (typically delivered via Databricks certification partners such as Certiverse or Pearson VUE depending on region and current program structure) |
|---|
| Pre Condition: | Recommended experience with Databricks platform and machine learning workflows; Databricks Certified Machine Learning Associate certification is often recommended but not strictly required. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
|---|
>> Databricks-Machine-Learning-Professional Online Praxisprüfung <<
Hohe Qualität von Databricks-Machine-Learning-Professional Prüfung und Antworten
Wenn Sie sich noch anstrengend um die Databricks-Machine-Learning-Professional Zertifizierungsprüfung bemühen, dann kann ITZert in diesem Moment Ihnen helfen, Problem zu lösen. ITZert bietet Ihnen Schulungsunterlagen von hoher Qualität, damit Sie die Prüfung bestehen und exzellentes Mitglied der Databricks Databricks-Machine-Learning-Professional Zertifizierung werden können. Wenn Sie sich entscheiden, durch die Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung sich zu verbessern, dann wählen Sie bitte ITZert. ITZert zu wählen ist keinesfalls nicht falsch. Unser ITZert verspricht, dass Sie beim ersten Versuch die Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung bestehen und somit das Zertifikat bekommen können. So können Sie sich sicher verbessern.
Databricks Databricks-Machine-Learning-Professional Prüfungsplan:
| Thema | Einzelheiten |
|---|
| Thema 1 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Thema 2 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Thema 3 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Thema 4 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Thema 5 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Thema 6 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Thema 7 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Thema 8 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
Databricks Certified Machine Learning Professional Databricks-Machine-Learning-Professional Prüfungsfragen mit Lösungen (Q191-Q196):
191. Frage
A machine learning engineer is using the following code block as part of a batch deployment pipeline:
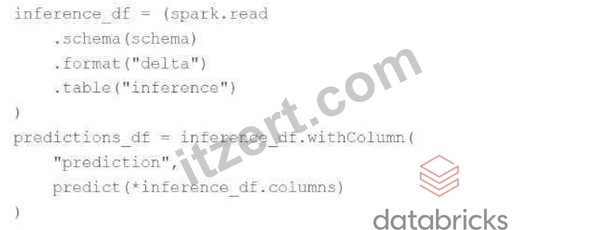
Which of the following changes needs to be made so this code block will work when the inference table is a stream source?
- A. Replace spark.read with spark.readStream
- B. Replace formatfdelta") with format("stream")
- C. Replace schema(schema) with option("maxFilesPerTriqqer", 1}
- D. Replace "inference" with the path to the location of the Delta table
- E. Replace predict with a stream-friendly prediction function
Antwort: C
192. Frage
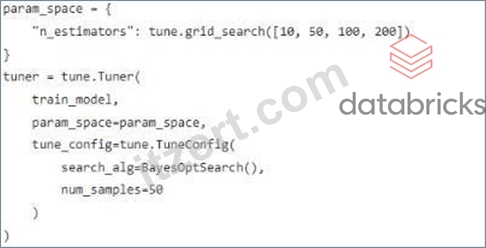
A Data Scientist has been performing hyperparameter tuning using Ray Tune with grid search.
After team discussions, they decide to switch to Bayesian optimization to more efficiently explore the parameter space.
Their current code is:
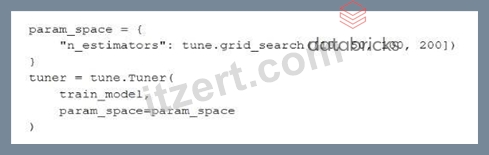
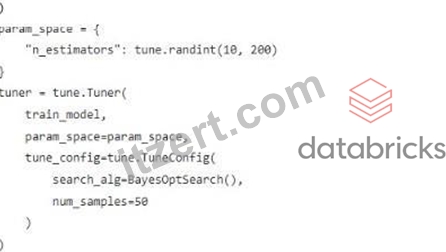
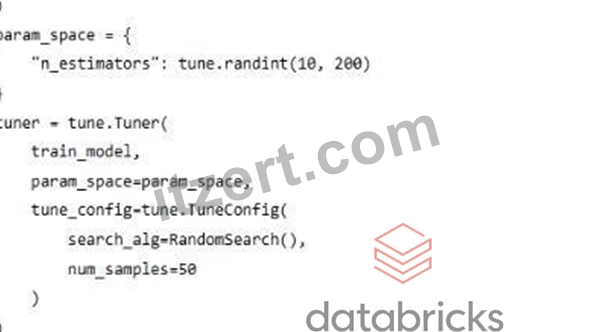
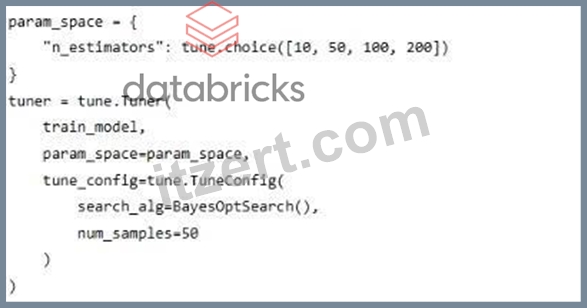
How can they implement this change?
Antwort: B
Begründung:
Bayesian optimization in Ray Tune requires defining a continuous or discrete search space (such as tune.randint) and explicitly configuring a Bayesian search algorithm. Using tune.randint defines a probabilistic parameter domain, and setting search_alg to BayesOptSearch enables Bayesian optimization to efficiently explore the space based on past trial results, rather than exhaustively enumerating all values as in grid search.
193. Frage
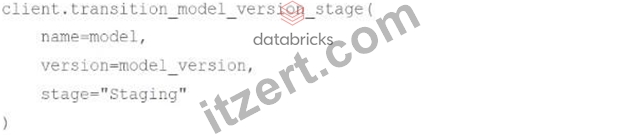
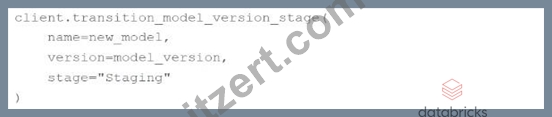
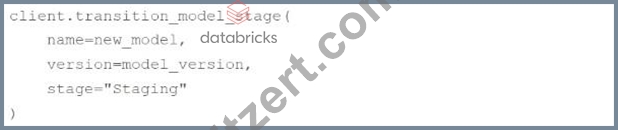
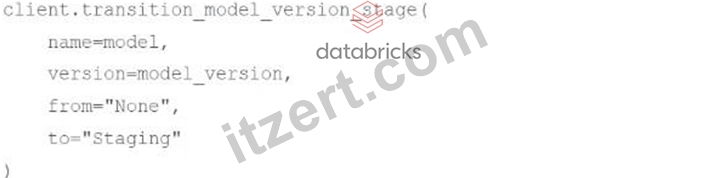
A machine learning engineer has created a webhook with the following code block:
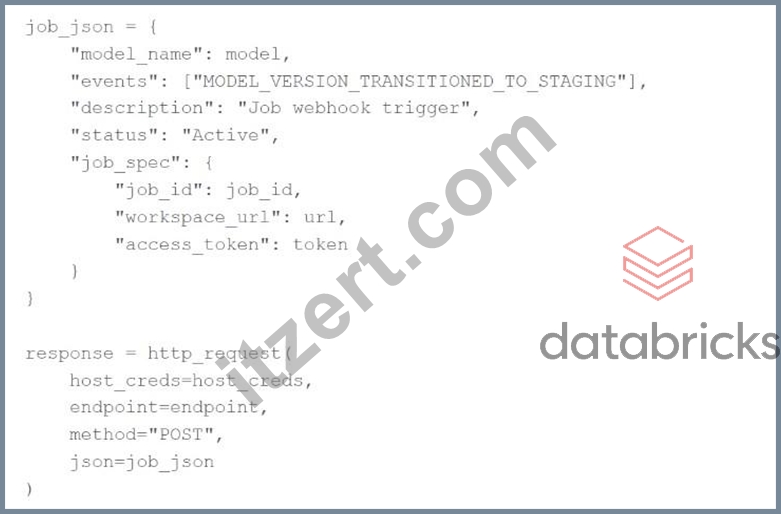
Which of the following code blocks will trigger this webhook to run the associate job?
Antwort: D
194. Frage
A machine learning engineer has developed a model and registered it using the FeatureStoreClient fs. The model has model URI model_uri. The engineer now needs to perform batch inference on customer-level Spark DataFrame spark_df, but it is missing a few of the static features that were used when training the model. The customer_id column is the primary key of spark_df and the training set used when training and logging the model.
Which of the following code blocks can be used to compute predictions for spark_df when the missing feature values can be found in the Feature Store by searching for features by customer_id?
- A. fs.score_batch(model_uri, df)
- B. fs.score_model(model_uri, spark_df)
- C. fs.score_batch(model_uri, spark_df)
- D. df = fs.get_missing_features(spark_df, model_uri)
fs.score_batch(model_uri, df)
df = fs.get_missing_features(spark_df) - E. df = fs.get_missing_features(spark_df, model_uri)
fs.score_model(model_uri, df)
Antwort: C
195. Frage
A Machine Learning Engineer has deployed a fraud detection model that processes 10,000 transactions per hour. The model was trained on data from Q1 2024, but it's now Q4 2024. The ML team notices three concerning trends: (1) the model's precision has dropped from 92% to
78% over the past month, (2) the average transaction amount in recent data has increased from
$150 to $220 and (3) the relationship between transaction frequency and fraud likelihood has weakened significantly due to new payment methods being introduced. The engineer needs to implement a monitoring solution that can detect the root cause of the performance degradation, identify why the precision dropped, and be able to do this at the scale needed. Which monitoring pipeline component will do this?
- A. Model Performance Monitoring Pipeline because it directly tracks precision metrics and can alert when thresholds are breached.
- B. Model Health Monitoring Pipeline because it ensures the infrastructure can handle the 10,000 transactions per hour load.
- C. Drift Detection Pipeline because it can identify both the data drift (transaction amount changes) and concept drift (weakened relationship between features and target).
- D. Logging and Monitoring Pipeline because it captures all prediction requests and can identify patterns in the fraud predictions.
Antwort: C
Begründung:
A drift detection pipeline is designed to diagnose the root causes of model performance degradation at scale. It can detect data drift, such as changes in the distribution of transaction amounts, and concept drift, where the relationship between input features and the fraud label changes due to new payment methods. This directly explains why precision dropped and provides actionable insight beyond simply observing metric degradation.
196. Frage
......
Databricks-Machine-Learning-Professional Fragenkatalog: https://www.itzert.com/Databricks-Machine-Learning-Professional_valid-braindumps.html
- Databricks-Machine-Learning-Professional Prüfungsunterlagen ❤️ Databricks-Machine-Learning-Professional Probesfragen 👐 Databricks-Machine-Learning-Professional Übungsmaterialien ☁ Suchen Sie auf der Webseite ⮆ www.zertfragen.com ⮄ nach 【 Databricks-Machine-Learning-Professional 】 und laden Sie es kostenlos herunter ⏺Databricks-Machine-Learning-Professional Prüfungen
- Das neueste Databricks-Machine-Learning-Professional, nützliche und praktische Databricks-Machine-Learning-Professional pass4sure Trainingsmaterial 😌 Suchen Sie jetzt auf ➡ www.itzert.com ️⬅️ nach 《 Databricks-Machine-Learning-Professional 》 und laden Sie es kostenlos herunter 🎴Databricks-Machine-Learning-Professional Quizfragen Und Antworten
- Databricks-Machine-Learning-Professional Übungsmaterialien - Databricks-Machine-Learning-Professional realer Test - Databricks-Machine-Learning-Professional Testvorbereitung 🍑 Suchen Sie einfach auf { www.itzert.com } nach kostenloser Download von ( Databricks-Machine-Learning-Professional ) 🅿Databricks-Machine-Learning-Professional Demotesten
- Databricks-Machine-Learning-Professional Deutsch Prüfungsfragen 👱 Databricks-Machine-Learning-Professional Prüfungsinformationen 🥿 Databricks-Machine-Learning-Professional Demotesten 💈 Suchen Sie jetzt auf “ www.itzert.com ” nach ✔ Databricks-Machine-Learning-Professional ️✔️ und laden Sie es kostenlos herunter 😥Databricks-Machine-Learning-Professional Examengine
- Databricks Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional braindumps PDF - Testking echter Test ⏭ Geben Sie ☀ www.pass4test.de ️☀️ ein und suchen Sie nach kostenloser Download von ▶ Databricks-Machine-Learning-Professional ◀ 🗯Databricks-Machine-Learning-Professional Prüfungen
- Databricks-Machine-Learning-Professional Lernressourcen 🐳 Databricks-Machine-Learning-Professional Quizfragen Und Antworten 🖍 Databricks-Machine-Learning-Professional Deutsch 🦝 URL kopieren ⏩ www.itzert.com ⏪ Öffnen und suchen Sie ➥ Databricks-Machine-Learning-Professional 🡄 Kostenloser Download 🐟Databricks-Machine-Learning-Professional Online Prüfungen
- Databricks-Machine-Learning-Professional Demotesten ☕ Databricks-Machine-Learning-Professional Deutsch 🚂 Databricks-Machine-Learning-Professional Quizfragen Und Antworten 🐬 ⏩ de.fast2test.com ⏪ ist die beste Webseite um den kostenlosen Download von ➽ Databricks-Machine-Learning-Professional 🢪 zu erhalten 🏫Databricks-Machine-Learning-Professional Quizfragen Und Antworten
- Databricks-Machine-Learning-Professional Deutsch Prüfungsfragen 🦠 Databricks-Machine-Learning-Professional Testantworten 🖋 Databricks-Machine-Learning-Professional Quizfragen Und Antworten 👳 Sie müssen nur zu ⏩ www.itzert.com ⏪ gehen um nach kostenloser Download von ▛ Databricks-Machine-Learning-Professional ▟ zu suchen 🏵Databricks-Machine-Learning-Professional Lerntipps
- Databricks-Machine-Learning-Professional Trainingsmaterialien: Databricks Certified Machine Learning Professional - Databricks-Machine-Learning-Professional Lernmittel - Databricks Databricks-Machine-Learning-Professional Quiz 🦡 Suchen Sie auf { www.zertsoft.com } nach kostenlosem Download von { Databricks-Machine-Learning-Professional } ♻Databricks-Machine-Learning-Professional Pruefungssimulationen
- Databricks Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional braindumps PDF - Testking echter Test 🆘 Suchen Sie jetzt auf 《 www.itzert.com 》 nach “ Databricks-Machine-Learning-Professional ” um den kostenlosen Download zu erhalten 🚾Databricks-Machine-Learning-Professional Deutsch Prüfungsfragen
- Databricks-Machine-Learning-Professional Dumps Deutsch 😿 Databricks-Machine-Learning-Professional Prüfungen 🥧 Databricks-Machine-Learning-Professional Dumps Deutsch 🧍 Öffnen Sie ▷ www.zertpruefung.de ◁ geben Sie ( Databricks-Machine-Learning-Professional ) ein und erhalten Sie den kostenlosen Download 🕒Databricks-Machine-Learning-Professional Musterprüfungsfragen
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Kostenlose und neue Databricks-Machine-Learning-Professional Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=1yXfN21LeoIVF_BUdaDusdCOBg4Wj5Tce