Databricks-Certified-Data-Engineer-Professional 100%시험패스자료 - Databricks-Certified-Data-Engineer-Professional자격증덤프

참고: PassTIP에서 Google Drive로 공유하는 무료, 최신 Databricks-Certified-Data-Engineer-Professional 시험 문제집이 있습니다: https://drive.google.com/open?id=1epOk3j4ASxcQ1pyn20FX8OsX28DFirCd
Databricks인증 Databricks-Certified-Data-Engineer-Professional시험을 패스하고 싶다면PassTIP에서 출시한Databricks인증 Databricks-Certified-Data-Engineer-Professional덤프가 필수이겠죠. Databricks인증 Databricks-Certified-Data-Engineer-Professional시험을 통과하여 원하는 자격증을 취득하시면 회사에서 자기만의 위치를 단단하게 하여 인정을 받을수 있습니다.이 점이 바로 많은 IT인사들이Databricks인증 Databricks-Certified-Data-Engineer-Professional시험에 도전하는 원인이 아닐가 싶습니다. PassTIP에서 출시한Databricks인증 Databricks-Certified-Data-Engineer-Professional덤프 실제시험의 거의 모든 문제를 커버하고 있어 최고의 인기와 사랑을 받고 있습니다. 어느사이트의Databricks인증 Databricks-Certified-Data-Engineer-Professional공부자료도PassTIP제품을 대체할수 없습니다.학원등록 필요없이 다른 공부자료 필요없이 덤프에 있는 문제만 완벽하게 공부하신다면Databricks인증 Databricks-Certified-Data-Engineer-Professional시험패스가 어렵지 않고 자격증취득이 쉬워집니다.
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Production Pipelines and Orchestration | - Databricks Workflows
- Error handling and recovery strategies
- Job scheduling and monitoring
|
| Topic 2: Data Ingestion and Processing | - Structured Streaming fundamentals
- ETL pipeline design patterns
- Batch and streaming ingestion with Auto Loader
|
| Topic 3: Databricks Lakehouse Platform Architecture | - Medallion architecture (Bronze, Silver, Gold)
- Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
|
| Topic 4: Data Modeling and Transformation | - Dimensional modeling concepts
- Performance optimization techniques
- Spark SQL transformations
|
| Topic 5: Delta Lake and Data Management | - Time travel and versioning
- Schema evolution and enforcement
- Delta Lake transactions and ACID properties
|
>> Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 <<
Databricks-Certified-Data-Engineer-Professional자격증덤프, Databricks-Certified-Data-Engineer-Professional최신 시험 최신 덤프
우리PassTIP에는 아주 엘리트한 전문가들로 구성된 팀입니다. 우리는 아주 정확하게 또한 아주 신속히Databricks Databricks-Certified-Data-Engineer-Professional관한 자료를 제공하며, 업데이트될경우 또한 아주 빠르게 뉴버전을 여러분한테 보내드립니다. PassTIP는 관련업계에서도 우리만의 브랜드이미지를 지니고 있으며 많은 고객들의 찬사를 받았습니다. 현재Databricks Databricks-Certified-Data-Engineer-Professional인증시험패스는 아주 어렵습니다, 하지만 PassTIP의 자료로 충분히 시험 패스할 수 있습니다.
최신 Databricks Certification Databricks-Certified-Data-Engineer-Professional 무료샘플문제 (Q119-Q124):
질문 # 119
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of 512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
- A. Set spark.sql.adaptive.advisoryPartitionSizeInBytes to 512 MB bytes, ingest the data, execute the narrow transformations, coalesce to 2,048 partitions (1TB*1024*1024/512), and then write to parquet.
- B. Set spark.sql.shuffle.partitions to 512, ingest the data, execute the narrow transformations, and then write to parquet.
- C. Ingest the data, execute the narrow transformations, repartition to 2,048 partitions (1TB*
1024*1024/512), and then write to parquet. - D. Set spark.sql.files.maxPartitionBytes to 512 MB, ingest the data, execute the narrow transformations, and then write to parquet.
- E. Set spark.sql.shuffle.partitions to 2,048 partitions (1TB*1024*1024/512), ingest the data, execute the narrow transformations, optimize the data by sorting it (which automatically repartitions the data), and then write to parquet.
정답:E
설명:
The key to efficiently converting a large JSON dataset to Parquet files of a specific size without shuffling data lies in controlling the size of the output files directly. Setting spark.sql.files.maxPartitionBytes to 512 MB configures Spark to process data in chunks of 512 MB. This setting directly influences the size of the part-files in the output, aligning with the target file size.
Narrow transformations (which do not involve shuffling data across partitions) can then be applied to this data.
Writing the data out to Parquet will result in files that are approximately the size specified by spark.sql.files.maxPartitionBytes, in this case, 512 MB. The other options involve unnecessary shuffles or repartitions (B, C, D) or an incorrect setting for this specific requirement (E).
질문 # 120
A table is registered with the following code:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
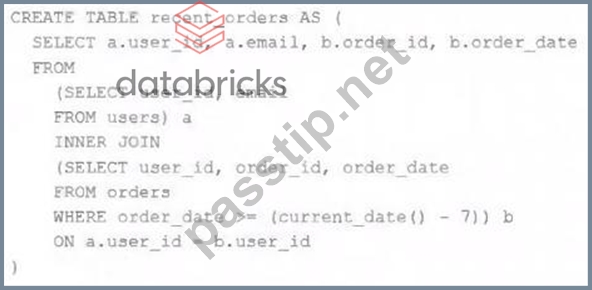
Both users and orders are Delta Lake tables. Which statement describes the results of querying recent_orders?
- A. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- C. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- D. Results will be computed and cached when the table is defined; these cached results will incrementally update as new records are inserted into source tables.
- E. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
정답:A
설명:
Table is created and data of join will be stored on DBFS and it will be returned on query time.
질문 # 121
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
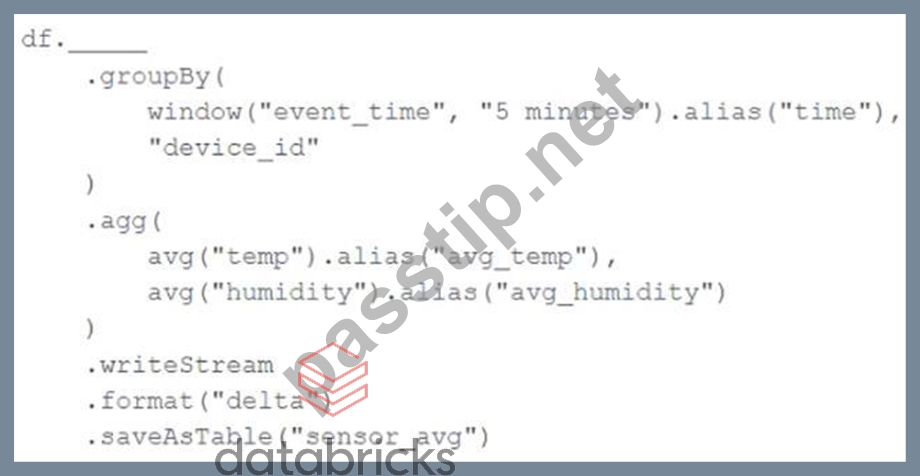
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. slidingWindow("event_time", "10 minutes")
- B. awaitArrival("event_time", "10 minutes")
- C. await("event_time + `10 minutes'")
- D. withWatermark("event_time", "10 minutes")
- E. delayWrite("event_time", "10 minutes")
정답:D
설명:
This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming.
질문 # 122
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- B. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- C. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- D. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- E. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
정답:C
질문 # 123
A developer has successfully configured credential for Databricks Repos and cloned a remote Git repository. Hey don not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace.
Use Response to pull changes from the remote Git repository commit and push changes to a branch that appeared as a changes were pulled.
- A. Use Repos to create a new branch commit all changes and push changes to the remote Git repertory.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - B. Use Repos to merge all differences and make a pull request back to the remote repository.
- C. Use repos to create a fork of the remote repository commit all changes and make a pull request on the source repository
- D. Use repos to merge all difference and make a pull request back to the remote repository.
- E. Use Repos to pull changes from the remote Git repository; commit and push changes to a branch that appeared as changes were pulled.
정답:A
설명:
In Databricks Repos, when a user does not have privileges to make changes directly to the main branch of a cloned remote Git repository, the recommended approach is to create a new branch within the Databricks workspace. The developer can then make changes in this new branch, commit those changes, and push the new branch to the remote Git repository. This workflow allows for isolated development without affecting the main branch, enabling the developer to propose changes via a pull request from the new branch to the main branch in the remote repository. This method adheres to common Git collaboration workflows, fostering code review and collaboration while ensuring the integrity of the main branch.
질문 # 124
......
Databricks-Certified-Data-Engineer-Professional인증시험은 IT업계에 종사하고 계신 분이시라면 최근 많은 인기를 누리고 있다는 것을 알고 계실것입니다. Databricks-Certified-Data-Engineer-Professional인증시험을 패스하여 자격증을 취득하는데 가장 쉬운 방법은 PassTIP에서 제공해드리는 Databricks-Certified-Data-Engineer-Professional덤프를 공부하는 것입니다. Databricks Databricks-Certified-Data-Engineer-Professional덤프에 있는 문제와 답만 기억하시면 Databricks-Certified-Data-Engineer-Professional시험을 패스하는데 많은 도움이 됩니다.덤프구매후 최신버전으로 업데이트되면 업데이트버전을 시스템 자동으로 구매시 사용한 메일주소로 발송해드려 덤프유효기간을 최대한 길게 연장해드립니다.
Databricks-Certified-Data-Engineer-Professional자격증덤프: https://www.passtip.net/Databricks-Certified-Data-Engineer-Professional-pass-exam.html
- 완벽한 Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 덤프문제 ⚓ { www.koreadumps.com }을 통해 쉽게「 Databricks-Certified-Data-Engineer-Professional 」무료 다운로드 받기Databricks-Certified-Data-Engineer-Professional최신버전 인기 덤프자료
- Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 인기시험덤프 🦖 무료 다운로드를 위해《 Databricks-Certified-Data-Engineer-Professional 》를 검색하려면▷ www.itdumpskr.com ◁을(를) 입력하십시오Databricks-Certified-Data-Engineer-Professional시험덤프문제
- Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 시험준비에 가장 좋은 인기 인증시험자료 ✊ 무료 다운로드를 위해 지금⇛ www.pass4test.net ⇚에서“ Databricks-Certified-Data-Engineer-Professional ”검색Databricks-Certified-Data-Engineer-Professional최신버전 덤프자료
- Databricks-Certified-Data-Engineer-Professional테스트자료 🍼 Databricks-Certified-Data-Engineer-Professional시험패스 🤸 Databricks-Certified-Data-Engineer-Professional시험대비 공부하기 🧍 ➠ Databricks-Certified-Data-Engineer-Professional 🠰를 무료로 다운로드하려면⇛ www.itdumpskr.com ⇚웹사이트를 입력하세요Databricks-Certified-Data-Engineer-Professional인기자격증 시험대비자료
- 100% 합격보장 가능한 Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 덤프 🕐 무료로 다운로드하려면☀ www.koreadumps.com ️☀️로 이동하여➥ Databricks-Certified-Data-Engineer-Professional 🡄를 검색하십시오Databricks-Certified-Data-Engineer-Professional퍼펙트 인증덤프
- 시험패스에 유효한 Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 최신버전 덤프샘풀문제 다운 받기 📂 「 Databricks-Certified-Data-Engineer-Professional 」를 무료로 다운로드하려면➽ www.itdumpskr.com 🢪웹사이트를 입력하세요Databricks-Certified-Data-Engineer-Professional적중율 높은 인증덤프
- 완벽한 Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 덤프문제 🌷 ( www.exampassdump.com )에서⏩ Databricks-Certified-Data-Engineer-Professional ⏪를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Engineer-Professional퍼펙트 인증덤프
- Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 완벽한 덤프샘플문제 ⛄ 시험 자료를 무료로 다운로드하려면⮆ www.itdumpskr.com ⮄을 통해⮆ Databricks-Certified-Data-Engineer-Professional ⮄를 검색하십시오Databricks-Certified-Data-Engineer-Professional최신 업데이트 인증덤프
- Databricks-Certified-Data-Engineer-Professional시험패스 😧 Databricks-Certified-Data-Engineer-Professional유효한 덤프공부 🔋 Databricks-Certified-Data-Engineer-Professional시험패스 🎭 오픈 웹 사이트➠ www.exampassdump.com 🠰검색➤ Databricks-Certified-Data-Engineer-Professional ⮘무료 다운로드Databricks-Certified-Data-Engineer-Professional인증 시험덤프
- Databricks-Certified-Data-Engineer-Professional 100%시험패스 자료 시험준비에 가장 좋은 인기 인증시험자료 📑 무료 다운로드를 위해▛ Databricks-Certified-Data-Engineer-Professional ▟를 검색하려면➠ www.itdumpskr.com 🠰을(를) 입력하십시오Databricks-Certified-Data-Engineer-Professional인증시험 공부자료
- Databricks-Certified-Data-Engineer-Professional인기자격증 시험대비자료 😝 Databricks-Certified-Data-Engineer-Professional유효한 덤프공부 🧕 Databricks-Certified-Data-Engineer-Professional최신 업데이트 인증덤프 🟨 “ www.koreadumps.com ”을 통해 쉽게▶ Databricks-Certified-Data-Engineer-Professional ◀무료 다운로드 받기Databricks-Certified-Data-Engineer-Professional퍼펙트 최신버전 공부자료
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, qiita.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! PassTIP Databricks-Certified-Data-Engineer-Professional 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1epOk3j4ASxcQ1pyn20FX8OsX28DFirCd