Test4Sure customizable practice exams (desktop and web-based) help students know and overcome their mistakes. The customizable Microsoft AI-300 practice test means that the users can set the Operationalizing Machine Learning and Generative AI Solutions (AI-300) Dumps and time according to their needs so that they can feel the real-based AI-300 exam scenario and learn to handle the pressure.
| Section | Objectives |
|---|---|
| Topic 1: Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Topic 2: Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Topic 3: Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Topic 4: Operationalizing machine learning solutions | - ML lifecycle management
|
>> Reliable AI-300 Exam Question <<
This certification gives us more opportunities. Compared with your colleagues around you, with the help of our AI-300 preparation questions, you will also be able to have more efficient work performance. Our AI-300 study materials can bring you so many benefits because they have the following features. I hope you can use a cup of coffee to learn about our AI-300 training engine. Perhaps this is the beginning of your change.
NEW QUESTION # 120
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
NEW QUESTION # 121
Hotspot Question
You have an Azure Machine Learning workspace.
You plan to set up logging and tracking experiments by using MLflow Tracking.
You need to log the accuracy as a numerical value and the training loss as a plot.
How should you complete the commands? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.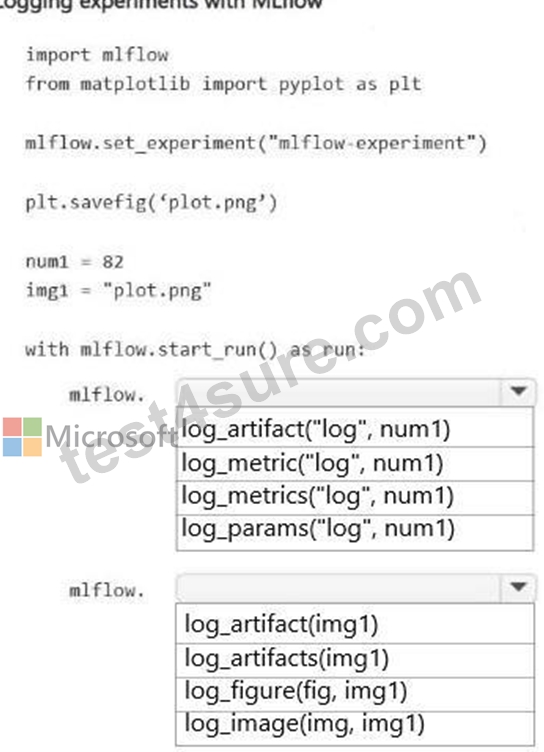
Answer:
Explanation: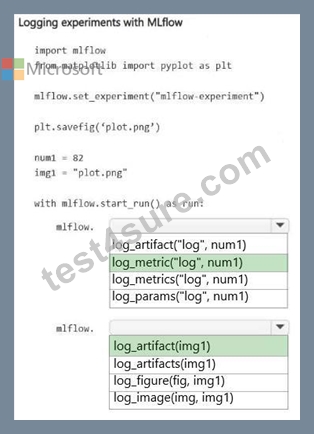
Explanation:
Box 1: log_metric("log", num1)
Log Numerical Metrics
To track a single numerical value that changes over time (like accuracy or evaluation scores), you use the mlflow.log_metric() function. This enables Azure Machine Learning to plot the value on a performance graph automatically.
Box 2: log_artifact(img1)
Log Plots and FilesTo save external files, images, or plots generated during training, you use the mlflow.log_artifact() function. This uploads the specified file (in this case, your saved Matplotlib image) to the run's artifact storage.
Reference:
https://levelup.gitconnected.com/mlflow-made-easy-your-beginners-guide-bf63f8fed915
NEW QUESTION # 122
Hotspot Question
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format. You must configure an autoscaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.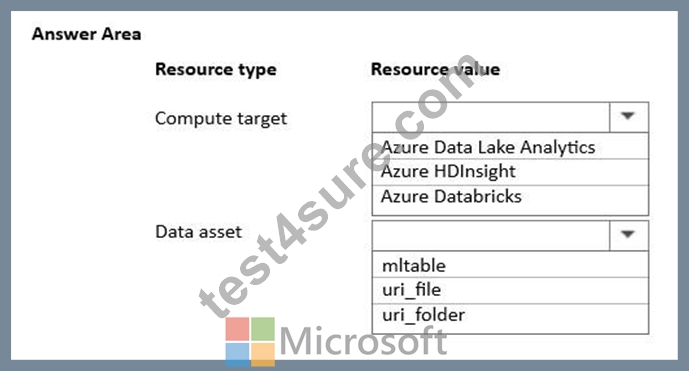
Answer:
Explanation: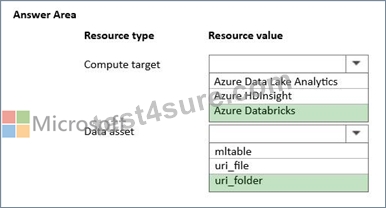
Explanation:
Box 1: Azure Databricks
Autoscaling: Out of the provided choices, Azure Databricks is the only compute target that natively supports the automated scaling up and down of worker nodes required to efficiently match the computation demands of your specific job.
Compatibility: Azure HDInsight and Azure Data Lake Analytics are legacy analytics platforms that do not offer the same direct, optimized, and auto-scaling compute integration within Azure ML SDK v2 pipelines for AutoML training.
Box 2: uri_folder
Directory access: Since your data consists of multiple data files stored in the Parquet format, pointing your asset type to a uri_folder allows the training job to automatically read and ingest all individual Parquet partition files stored inside that directory.
Reference:
https://github.com/Azure/MachineLearningNotebooks/blob/master/how-to-use-azureml/azure-databricks/automl/automl-databricks-local-01.ipynb
NEW QUESTION # 123
Hotspot Question
A team is preparing a generative AI application for production deployment. The application generates structured responses that must be evaluated for quality before each release.
The organization requires repeatable evaluation results that can be compared across builds and environments.
You need to configure evaluation inputs so quality metrics can be reliably calculated across test runs.
How should you prepare the evaluation inputs? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.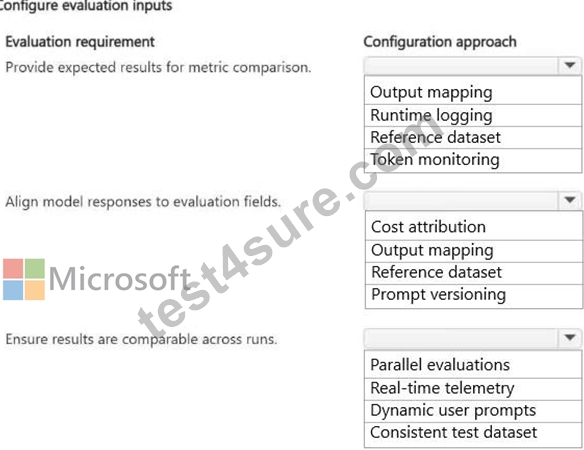
Answer:
Explanation: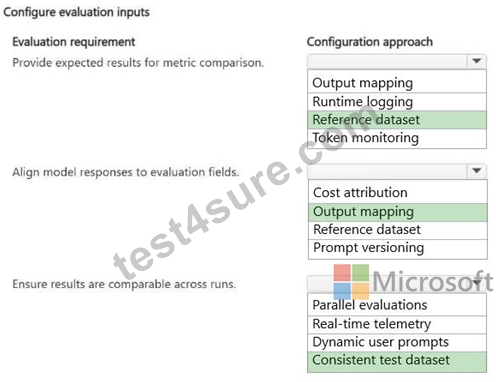
Explanation:
Box 1: Reference dataset
Provide expected results for metric comparison.
A reference dataset contains predefined input prompts matched with ground-truth "expected results" (or golden outputs). To calculate quality metrics reliably and compare them across builds and environments, the evaluation framework needs this baseline data to score the generated outputs against a consistent benchmark.
Box 2: Output mapping
Align model responses to evaluation fields.
Output mapping is the process of aligning generative model responses to specific evaluation fields. For structured outputs, your evaluation dataset needs to know exactly which part of the generated response corresponds to the ground truth or target metrics. Configuring output mapping ensures that data fields are aligned consistently across different test runs, making the evaluation repeatable and comparable across builds and environments.
Box 3: Consistent test dataset
Ensure results are comparable across runs.
A consistent test dataset is used to reliably compare evaluation metrics across different builds and environments, you must test the application using the exact same inputs each time. A fixed, high-quality test dataset ensures that changes in metrics reflect changes in the model or application logic rather than variations in the test data itself.
Reference:
https://testquality.com/llm-evaluation-metrics-testing-strategies/
https://www.freecodecamp.org/news/how-to-evaluate-and-select-the-right-llm-for-your-genai-application/
NEW QUESTION # 124
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to make model training repeatable and auditable to address Fabrikam Inc.'s current environment challenges and technical requirements. What should you use?
Answer: B
Explanation:
Azure Machine Learning (AML) training would be best. While the other options can execute code, they lack the native machine learning operations (MLOps) capabilities required for enterprise auditing and repeatability.
Azure ML pipelines are purpose-built for machine learning workflows. They natively solve your tracking and auditing requirements.
Built-in Lineage: Automatically tracks data inputs, code versions, environments, and output models.
Native Component Reuse: Steps are modular, containerized, and easily shared across teams.
Data Caching: Skips completed steps if inputs have not changed, saving time and compute costs.
Scenario, Technical Requirements:
Implement experiment tracking and model versioning for all training jobs.
Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models.
Reference:
https://medium.com/data-for-ai/mlops-with-a-feature-store-8dabc845584a
NEW QUESTION # 125
......
The passing rate of our study material is very high, and it is about 99%. We provide free download and tryout of the AI-300 question torrent, and we will update the AI-300 exam torrent frequently to guarantee that you can get enough test bank and follow the trend in the theory and the practice. We provide 3 versions for you to choose thus you can choose the most convenient method to learn. Our AI-300 Latest Questions are compiled by the experienced professionals elaborately. So it will be very convenient for you to buy our product and it will do a lot of good to you.
Best AI-300 Vce: https://www.test4sure.com/AI-300-pass4sure-vce.html