Maybe on other web sites or books, you can also see the related training materials. But as long as you compare Getcertkey's product with theirs, you will find that our product has a broader coverage of the certification exam's outline. You can free download part of exam practice questions and answers about Anthropic certification CCAR-P exam from Getcertkey website as a try to detect the quality of our products. Why Getcertkey can provide the comprehensive and high-quality information uniquely? Because we have a professional team of IT experts. They continue to use their IT knowledge and rich experience to study the previous years exams of Anthropic CCAR-P and have developed practice questions and answers about Anthropic CCAR-P exam certification exam. So Getcertkey's newest exam practice questions and answers about Anthropic certification CCAR-P exam are so popular among the candidates participating in the Anthropic certification CCAR-P exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Governance, Safety & Risk Management | 14% | - Human-in-the-loop validation - Regulatory and compliance requirements - Security and risk management - AI safety and guardrails - Ethical AI considerations |
| Topic 2: Solution Design & Architecture | 17% | - End-to-end architecture design - Alignment with business value, cost, performance, and SLAs - Decomposition techniques for complex problem solving - Translating business problems into Claude-based AI solutions - Architectural patterns
|
| Topic 3: Stakeholder Communication & Lifecycle Management | 14% | - Architecture documentation - Service-level agreements - Stakeholder management - Discovery and requirements gathering - Solution lifecycle management - Communicating architectural decisions |
| Topic 4: Developer Productivity & Operational Enablement | 7% | - Claude tooling configuration for teams - Developer enablement - AI-assisted developer workflows - Debugging and operational issue resolution |
| Topic 5: Integration | 19% | - Authentication and authorization analysis - Enterprise system integration - Claude integration mechanisms
|
| Topic 6: Evaluation, Testing & Optimization | 16% | - A/B testing - System issue diagnosis - Cost and performance optimization - Production monitoring and optimization - Evaluation metrics and datasets - Evaluation framework design |
| Topic 7: Claude Models, Prompting & Context Engineering | 13% | - Context window optimization - Claude model selection and trade-offs - Guardrails - Prompt reuse and context engineering strategies - System prompts and prompt templates |
If you have interests with our CCAR-P practice materials, we prefer to tell that we have contacted with many former buyers of our CCAR-P exam questions and they all talked about the importance of effective CCAR-P practice material playing a crucial role in your preparation process. Our CCAR-P practice materials keep exam candidates motivated and efficient with useful content based wholly on the real CCAR-P guide materials. There are totally three versions of CCAR-P practice materials which are the most suitable versions for you: pdf, software and app versions.
NEW QUESTION # 59
You are comparing two configurations for an internal compliance Q & A assistant. Configuration X reduces top-k retrieval and uses a lighter model, lowering p95 latency by 38 percent while producing a measured 2 percent reduction in the accuracy benchmark. Configuration Y retains the existing top-k retrieval setting and heavier model, with unchanged p95 latency and no measurable change in accuracy. The deployment's stated priorities are accuracy first and latency second.
Which configuration is the better recommendation?
Answer: C
Explanation:
Configuration Y is the appropriate recommendation because architectural optimization must follow the deployment's explicitly defined priorities and acceptance criteria. Accuracy is the primary requirement for this compliance assistant, and Configuration X introduces a measured two-percent accuracy regression. That reduction cannot be dismissed as ordinary benchmark variation unless repeated evaluation establishes that it is statistically insignificant. In a compliance workload, even a small accuracy decline can increase incorrect guidance, missed policy requirements, human-review effort, and regulatory exposure. Configuration Y preserves the established accuracy level while maintaining the current latency profile. Although its latency does not improve, latency is explicitly the secondary objective. Configuration X could be reconsidered only if further testing eliminates the accuracy regression or stakeholders formally approve a revised trade-off.
Options C and D incorrectly impose a general preference for latency over the documented deployment priorities.
NEW QUESTION # 60
After a prompt-template update, several previously passing test cases now produce unexpected outputs.
Which test type is specifically designed to detect this category of failure?
Answer: C
Explanation:
Regression tests determine whether behavior that previously met requirements still passes after a change. A stable reference set provides identical inputs, expected outcomes, and scoring rules across prompt versions, allowing the team to attribute failures to the update. Integration tests verify interactions among components but may not measure detailed output behavior. Adversarial tests target attacks and misuse cases, while smoke tests establish only that essential system paths remain available. The failed cases should be added to or retained within the regression suite, and the old and new prompt should be compared under the same model, parameters, tools, and retrieval context. Anthropic describes regression evaluations as protection against behavioral backsliding. Demystifying evals for AI agents
NEW QUESTION # 61
You are designing a content moderation classifier that processes high volumes of user-generated comments under a tight per-message latency budget using well-defined classification labels.
Which model selection best aligns with the workload?
Answer: C
Explanation:
Haiku is the appropriate starting point because the workload is high-volume, latency-sensitive, and based on a stable closed set of moderation labels. These characteristics favor a fast, cost-efficient model capable of consistent classification without incurring the additional inference time and expense associated with deeper reasoning.
Anthropic's model-selection guidance requires architects to balance capability, speed, and cost rather than automatically selecting the most capable model. Its content-moderation guidance specifically identifies Haiku as a cost-effective option for processing moderation workloads at substantial scale. Choosing the Right Model, Content Moderation Opus is disproportionate to a routine closed-set classification problem. Sonnet may become justified if evaluation demonstrates that Haiku fails materially on complex policy distinctions, multilingual ambiguity, or adversarial edge cases, but it should not be selected merely because it is larger. Enabling extended thinking on every request would further increase latency and token consumption without evidence that the additional reasoning improves the defined success metrics. The correct architectural practice is to establish a representative moderation evaluation set, validate Haiku against accuracy and safety thresholds, and escalate only the cases that genuinely need deeper reasoning.
Study Guide references/topics: Model selection; capability-latency-cost trade-offs; classification workloads; evaluation-driven routing; moderation architecture.
NEW QUESTION # 62
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.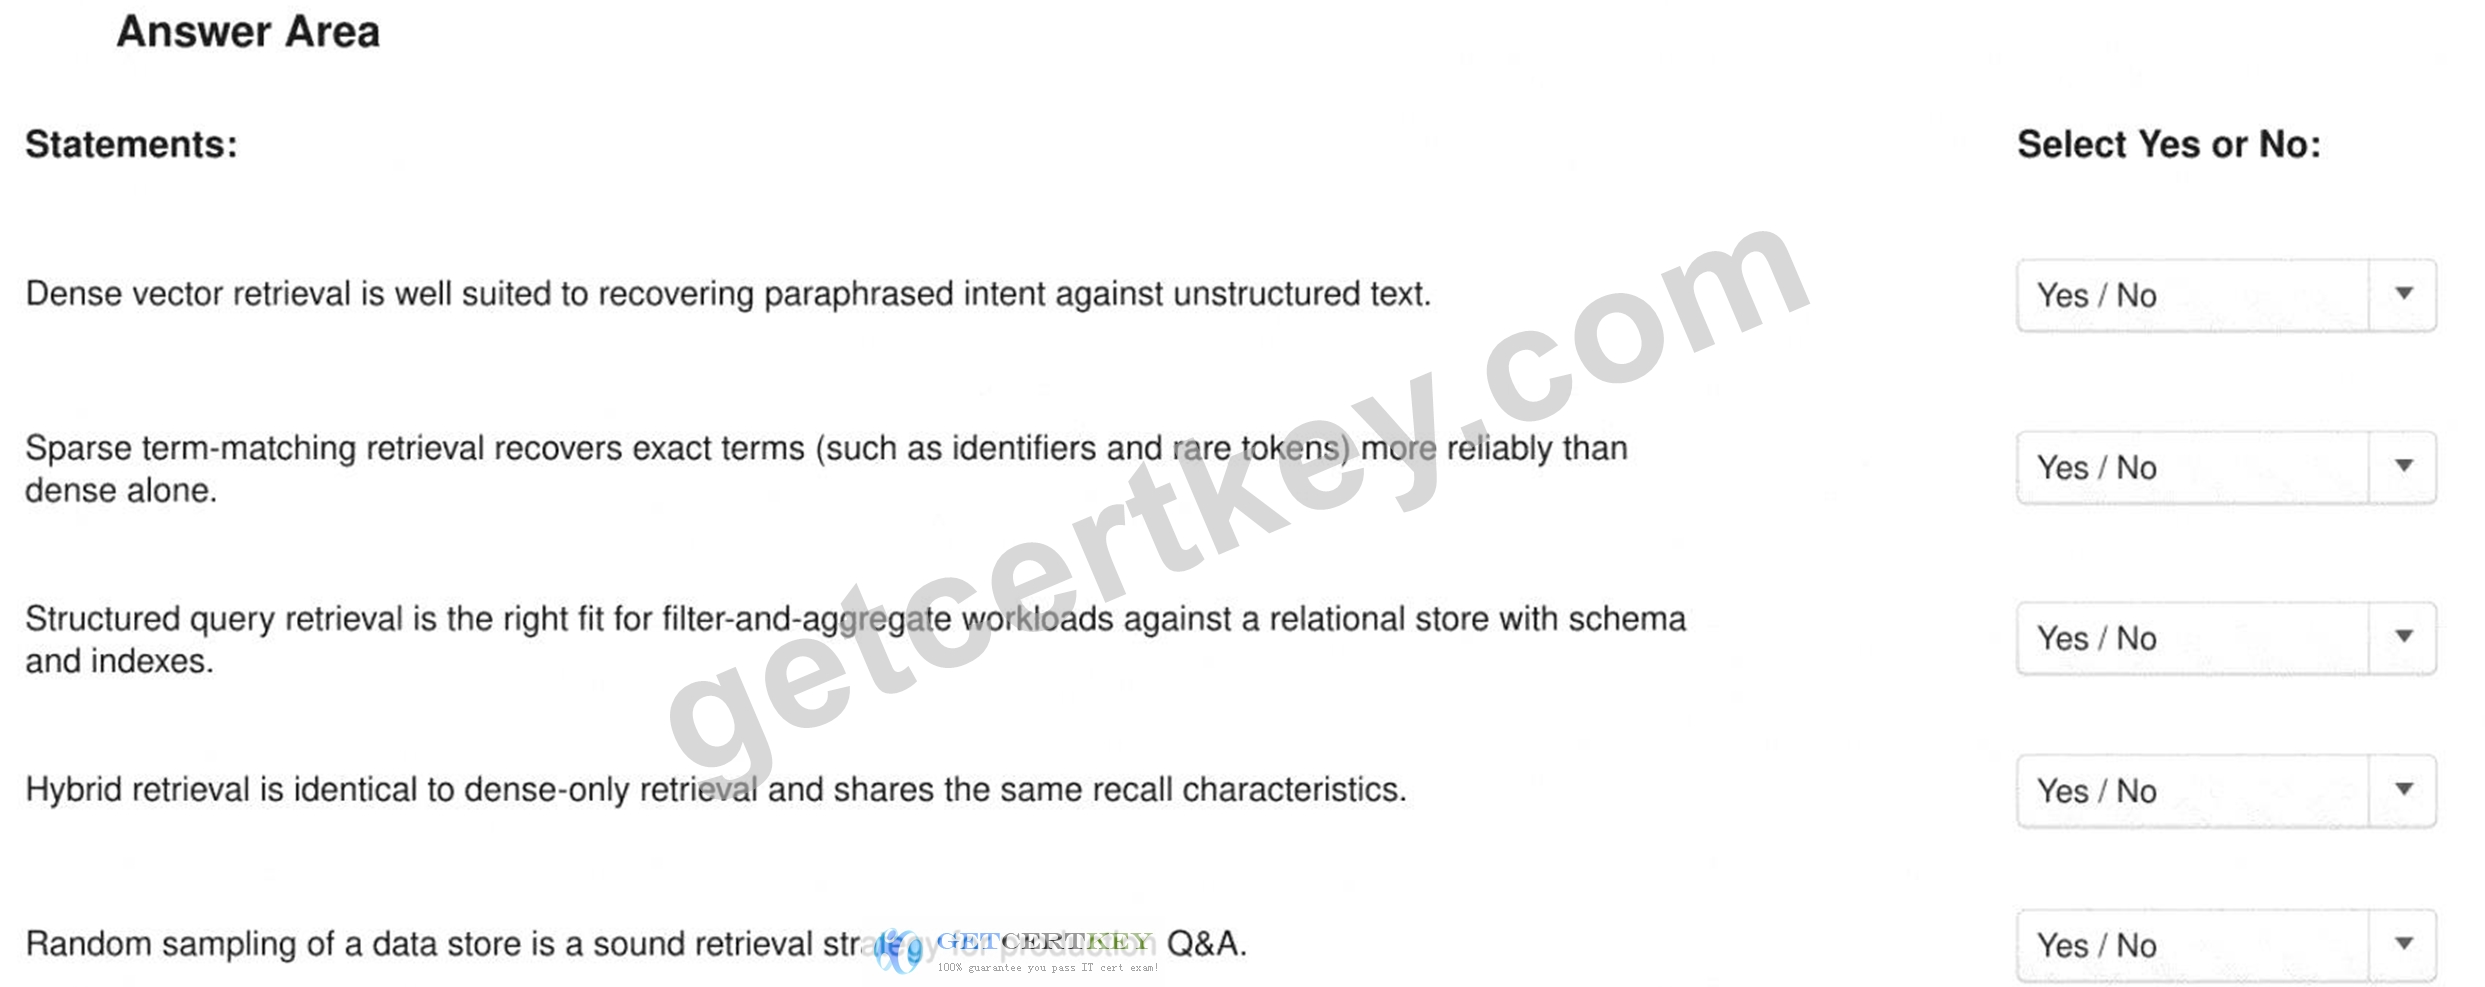
Answer:
Explanation: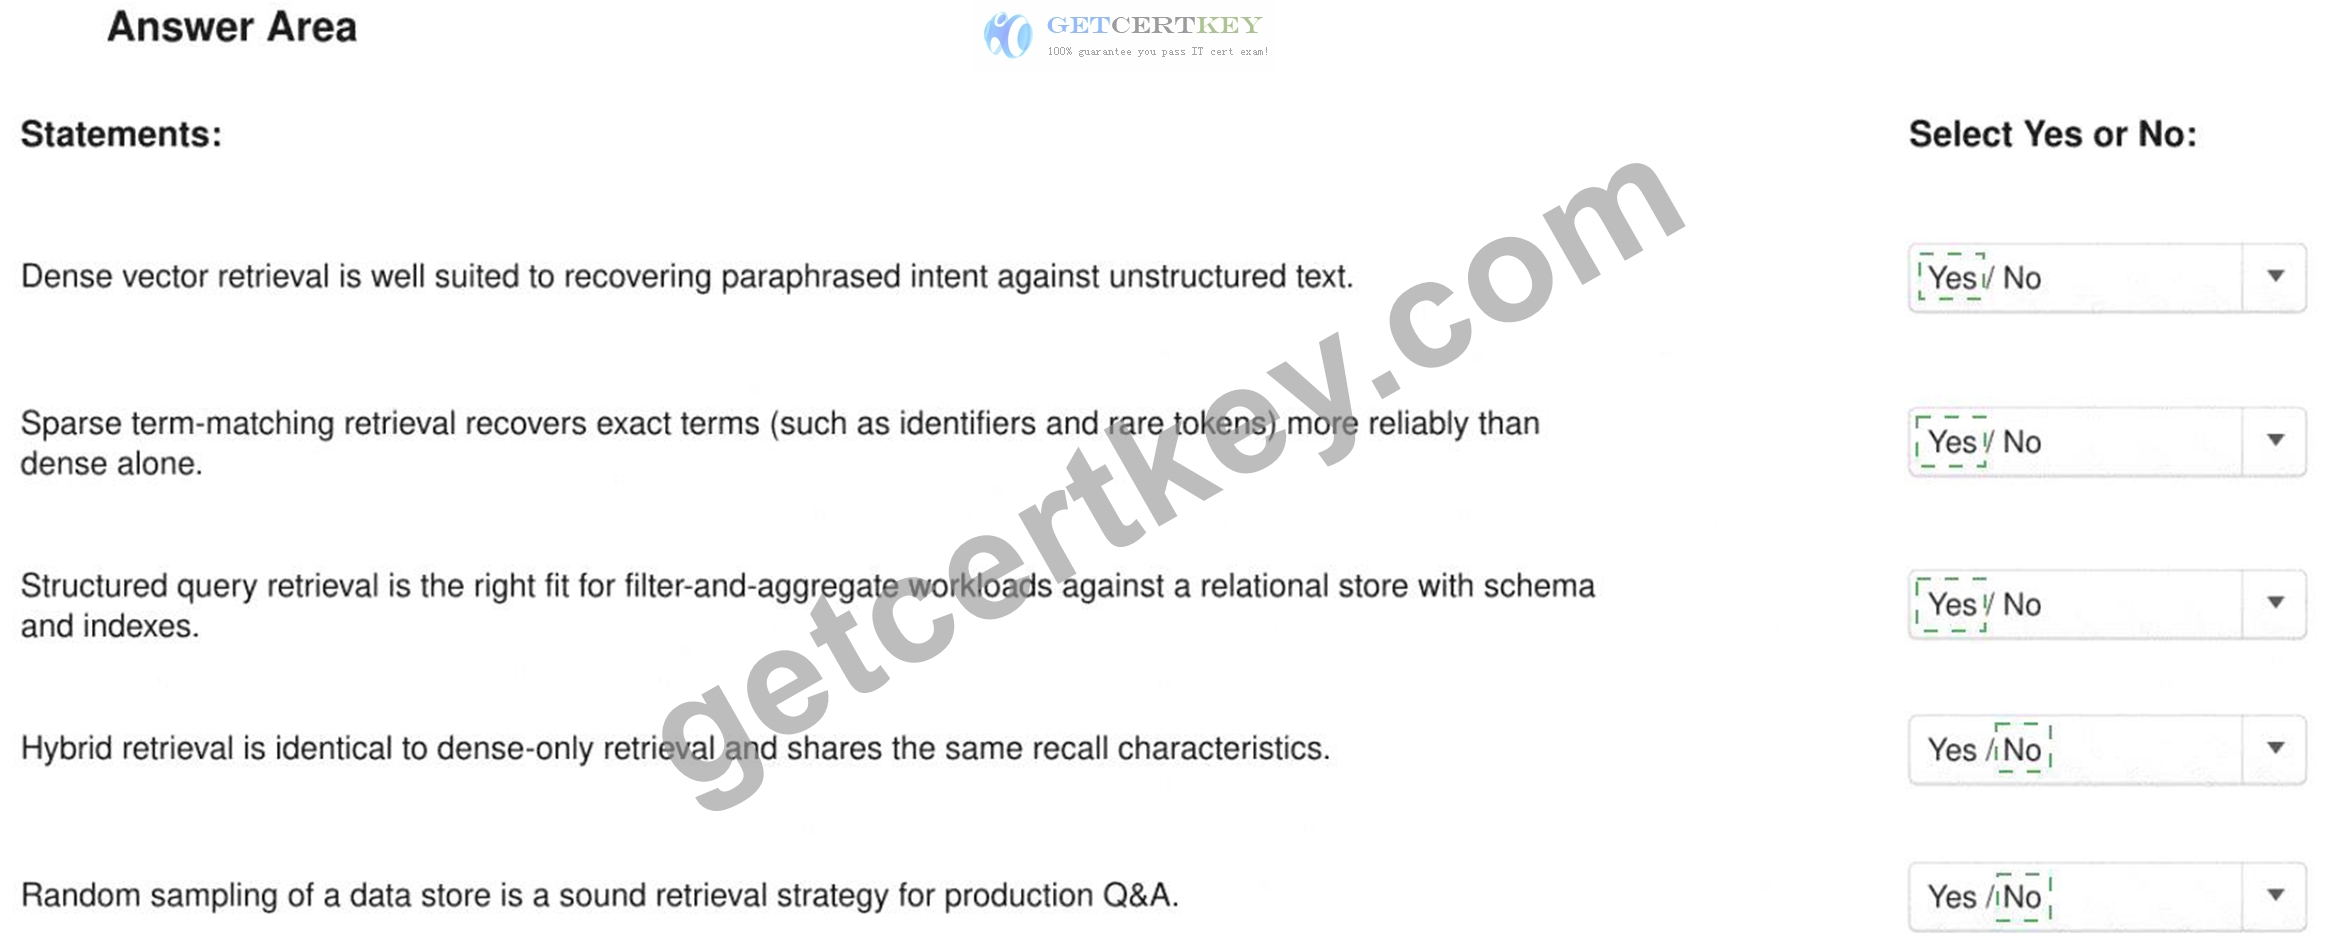
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval, Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k.
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 63
You are responding to an adversarial input pattern in which users include text claiming admin authority and instructing the model to bypass safety restrictions.
Which combination of controls most effectively mitigates this attack pattern?
Answer: C
Explanation:
Self-declared administrative authority inside a prompt is untrusted data, not authenticated identity or authorization evidence. Option B correctly combines independent controls across the model, runtime, authorization, and monitoring layers.
Prompt instructions establish that user content cannot override system policy. Runtime classifiers detect known and generalized attempts to bypass controls. Tool permissions are enforced outside the model and must derive from authenticated identity, role, and approved scope-not statements contained in the conversation. Audit logging records the actor, attempted override, classifier result, tool requests, and final disposition for investigation and control improvement.
Anthropic recommends input screening, hardened system prompts, safe handling of untrusted content, narrowly scoped permissions, red-team testing, and continuous monitoring. Mitigate Jailbreaks and Prompt Injections Option A depends entirely on model behavior and provides no containment if the model fails. Option C removes the protections the attacker is attempting to defeat. Option D commits a fundamental authorization error by accepting an unverified claim as privilege elevation.
The strongest design also rate-limits repeated attempts, escalates suspicious activity, validates outputs, and requires human confirmation for consequential actions.
Study Guide references/topics: Direct prompt injection; untrusted user content; runtime classifiers; non-model authorization; scoped tools; audit logging; defense in depth.
NEW QUESTION # 64
......
Someone always asks: Why do we need so many certifications? One thing has to admit, more and more certifications you own, it may bring you more opportunities to obtain better job, earn more salary. This is the reason that we need to recognize the importance of getting the test CCAR-P certifications. More qualified certification for our future employment has the effect to be reckoned with, only to have enough qualification certifications to prove their ability, can we win over rivals in the social competition. Therefore, the CCAR-P Guide Torrent can help users pass the qualifying examinations that they are required to participate in faster and more efficiently.
Latest CCAR-P Test Cram: https://www.getcertkey.com/CCAR-P_braindumps.html