Außerdem sind jetzt einige Teile dieser ExamFragen HPE7-J01 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1FDtt9VoFyxVYYAqpwGhQ-AuGOM1kx7KP
Die Schulungsunterlagen zur HP HPE7-J01 Zertifizierungsprüfung aus unserem ExamFragen kann Ihren Traum - die HPE7-J01 Prüfung bestehen - verwirklichen, denn sie alle Dinge für den Durchlauf der HP HPE7-J01 Zertifizierungsprüfung enthalten. Wählen Sie ExamFragen, können sie bestimmt die HP HPE7-J01 Zertifizierungsprüfung bestehen, so werden Sie auch ein Mitglied der Eliten im IT-Bereich. Worauf warten Sie? Bitte beeilen Sie sich!
| Section | Objectives |
|---|---|
| Storage Security and Best Practices | - Data encryption and access control - Secure storage architecture design |
| HPE Storage Platforms and Solutions | - HPE Primera and Nimble storage solutions - HPE Alletra storage systems - Legacy HPE 3PAR architecture concepts |
| SAN and NAS Technologies | - NAS protocols and file services - Fibre Channel and iSCSI fundamentals |
| Performance and Capacity Planning | - Performance optimization techniques - Workload analysis and sizing |
| Hybrid Cloud and Data Mobility | - Data migration and mobility strategies - Hybrid cloud storage integration |
| Data Protection and Availability | - High availability design considerations - Backup, replication, and disaster recovery concepts |
| HPE Storage Architecture Overview | - Enterprise storage fundamentals and architectures - HPE storage portfolio positioning |
Um die HP HPE7-J01 Zertifizierungsprüfung zu bestehen, brauchen Sie eine ausreichende Vorbereitung und eine vollständige Wissensstruktur. Die von ExamFragen gebotenen HP HPE7-J01 Ressourcen würden Ihre Bedürfnisse sicher abdecken.
65. Frage
A storage administrator is creating a disaster recovery solution for HPE Alletra 9000 storage arrays.
Currently, the company has three storage arrays at three different primary sites. When implementing the N-to-
1 Remote Copy (RC) feature, what is the minimum number of storage arrays the storage administrator needs to plan for at the disaster recovery site?
Antwort: B
Begründung:
The HPE Alletra 9000 (and its predecessor, HPE Primera) supports various Remote Copy (RC) topologies to meet different disaster recovery and data distribution requirements. These include 1-to-1, 1-to-N (fan-out), and N-to-1 (fan-in) configurations.
In an N-to-1 Remote Copy configuration, multiple source storage systems (represented by 'N') replicate their data to a single, centralized target system at a disaster recovery (DR) or secondary site. This architecture is particularly efficient for organizations with multiple regional or branch offices that wish to centralize their backup and DR operations into a single data center to reduce hardware costs and simplify management. In the scenario described, the company has three primary sites ($N = 3$), each with its own storage array. To implement an N-to-1 strategy, the administrator only needs to provide one storage array at the DR site. This single target array must be sized appropriately to handle the combined capacity and performance requirements (IOPS and throughput) of the incoming replication streams from all three source systems.
Architecturally, the Alletra 9000 uses Remote Copy Groups to manage these relationships. Each group on the source systems is mapped to a corresponding group on the single target system. It is important to note that while the hardware requirement is a single array, the administrator must ensure the target array has sufficient Remote Copy ports (RCIP or RCFC) and licensed capacity to accommodate the fan-in ratio. The Alletra
9000 management interface and HPE GreenLake Data Services Cloud Console (DSCC) provide the orchestration necessary to monitor these multiple inbound streams and ensure that the Recovery Point Objectives (RPOs) are met across all sites simultaneously.
66. Frage
Match the fibre channel topology to its use case. Each answer will be used once.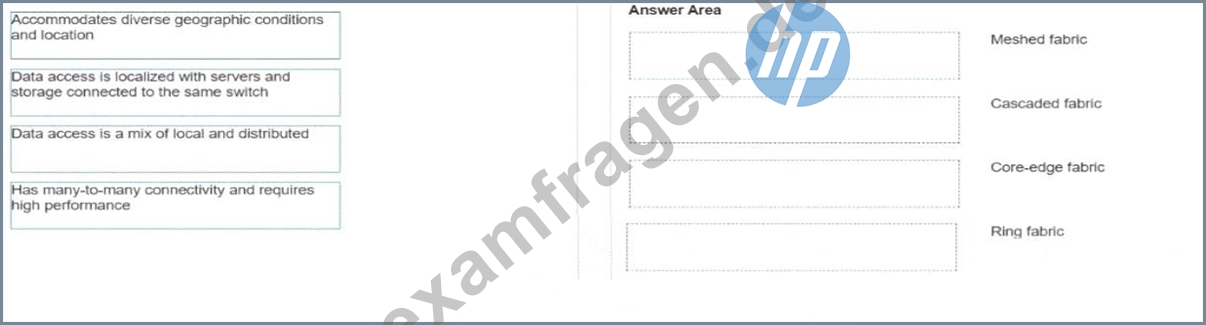
Antwort:
Begründung: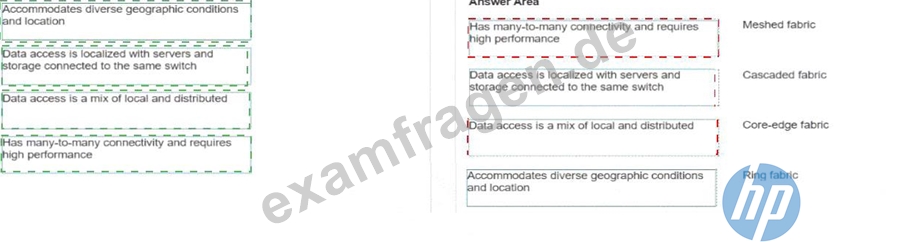
Explanation:
* Meshed fabric: Has many-to-many connectivity and requires high performance.
* Cascaded fabric: Data access is localized with servers and storage connected to the same switch.
* Core-edge fabric: Data access is a mix of local and distributed.
* Ring fabric: Accommodates diverse geographic conditions and location.
In the design of modern Storage Area Networks (SANs), selecting the right topology is critical for balancing performance, scalability, and cost. Each of these Brocade/HPE B-series architectures serves a specific workload profile:
Meshed Fabric: This design provides the highest level of redundancy and performance by connecting switches in an "any-to-any" pattern. Because every switch is connected to multiple other switches, it provides many-to- many connectivity and minimized "hop counts," making it ideal for high-performance environments where application traffic is unpredictable and widely distributed.
Cascaded Fabric: The simplest topology, where switches are connected in a serial or daisy-chain fashion. It is most effective in small environments where data access is localized-meaning the server and the storage it needs are physically connected to the same switch, minimizing Inter-Switch Link (ISL) traversal.
Core-Edge Fabric: The standard for enterprise data centers. Servers are connected to "Edge" switches, and storage is connected to a high-capacity "Core". This allows for a mix of local and distributed data access.
Large enterprises use this to scale easily by adding edge switches without disrupting the core storage connectivity.
Ring Fabric: By connecting switches in a closed loop, this topology is designed to accommodate diverse geographic conditions. If a single link between two locations fails, traffic can be re-routed the other way around the ring. This provides a cost-effective way to link multiple sites or campus buildings while maintaining fabric integrity.
67. Frage
An administrator needs to use a plug-in to provide monitoring of the performance of applications, servers, databases, tools, and services through an SaaS-based data analytics platform. Which Morpheus plug-in should the administrator install?
Antwort: C
Begründung:
HPE Morpheus Enterprise provides extensive native monitoring for provisioned resources, but for deep, full-stack observability into applications, databases, and third-party services via a specialized SaaS-based analytics platform, it integrates with external providers through plugins.
The Datadog Integration Plugin is a primary example of this capability. Datadog is an industry-leading SaaS data analytics platform that monitors performance across every layer of the stack-from infrastructure metrics to application traces and logs. By installing the Datadog plugin in Morpheus, the administrator bridges the gap between the orchestration engine (Morpheus) and the observability platform (Datadog). This plugin adds a contextual "Datadog" tab to instances within the Morpheus UI, pulling real-time performance telemetry directly from the SaaS backend into the Morpheus management pane. This allows the administrator to view workload health and deep-dive analytics without switching consoles.
While HPE OpsRamp (Option C) is part of the broader HPE CloudOps Software suite and provides similar observability features, it is often treated as a separate, complementary software component rather than a specific "SaaS plugin" used within the core Morpheus instance-level analytics in the same context as Datadog's marketplace integration. The Morpheus Agent (Option A) is a local software component used for guest-level automation and basic health checks, not a SaaS analytics platform. By choosing Datadog, the administrator leverages a purpose-built SaaS solution to gain the "monitoring of applications, servers, and databases" required by the prompt through a pre-validated community or enterprise plugin.
68. Frage
A customer using VMware wants storage provisioning automated directly from vCenter with policy-based management. Which HPE integration feature should be recommended?
Antwort: C
Begründung:
The HPE Storage Integration Plugin for VMware vCenter enables native storage provisioning and policy-driven administration directly from vCenter. It simplifies datastore creation and management. OneView manages broader infrastructure, InfoSight provides analytics, and SNMP only handles monitoring alerts.
69. Frage
Order the steps for a write data path and a successful write IO in HPE GreenLake for File Storage using NAS.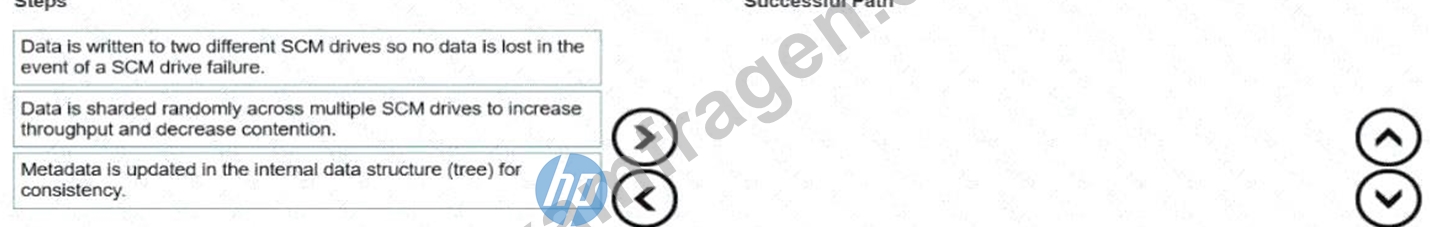
Antwort:
Begründung: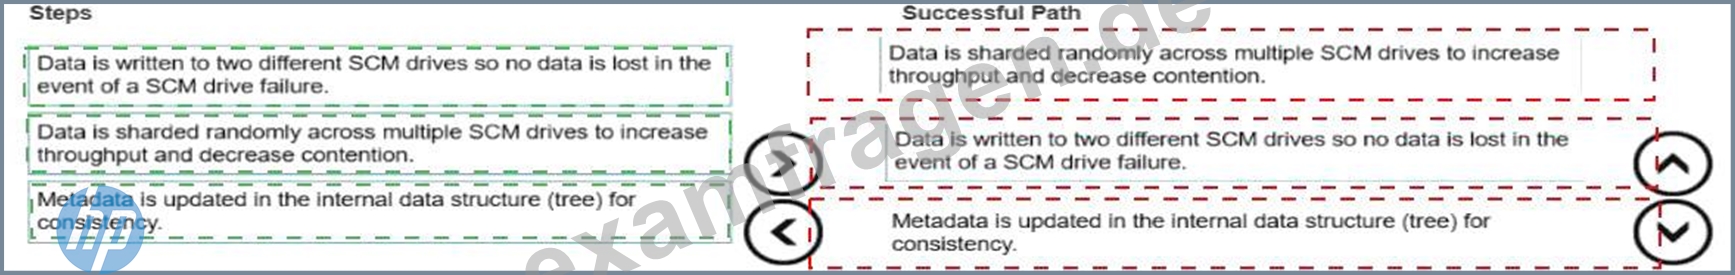
Explanation:
* Data is sharded randomly across multiple SCM drives to increase throughput and decrease contention.
* Data is written to two different SCM drives so no data is lost in the event of a SCM drive failure.
* Metadata is updated in the internal data structure (tree) for consistency.
Comprehensive and Detailed 250 to 300 words of Explanation From Advanced Storage Solutions Architect documents and knowledge guide:
The write data path in HPE GreenLake for File Storage (powered by Alletra MP X10000 hardware and VAST Data software) follows a unique Disaggregated Shared-Everything (DASE) architecture. Unlike legacy NAS systems that use front-end caching or complex controller-to-controller talk, this solution leverages Storage Class Memory (SCM) as a persistent write buffer to provide high-sustained performance without the need for traditional data movement between tiers.
The process begins with sharding. When a NAS write request arrives, the system immediately shards the data randomly across multiple SCM drives in the cluster. This sharding is critical because it eliminates hot spots and contention by ensuring that no single drive or node becomes a bottleneck, effectively parallelizing the IO load across the entire storage fabric.
Once the sharding logic is determined, the data is physically written to the SCM tier. To ensure mission- critical resilience, every write is mirrored (written to two different SCM drives). Because SCM is non-volatile random-access memory (NVRAM), the write is persistent the moment it hits the media. This allows the system to send an immediate acknowledgement back to the client while protecting against a drive or node failure.
Finally, the metadata is updated in the internal data structure (the V-Tree). This step ensures the "View" of the file system remains consistent and that the global namespace reflects the newly written data. After this point, the data is asynchronously moved from SCM to high-capacity NVMe SSDs using wide-stripe erasure coding for long-term, efficient storage. This disaggregated flow allows the Alletra MP X10000 to scale performance and capacity independently while maintaining strict data integrity and consistency at AI-scale.
70. Frage
......
HP HPE7-J01 Zertifizierungsprüfung ist heute sehr populär. Wollen Sie an der HPE7-J01 Prüfung teilnehmen? Tatsächlich ist diese Prüfung sehr schwierig. Aber es bedeutet nicht, diese Prüfung mit guter Note sehr leicht zu bestehen. So, wissen Sie den kürzesten Weg zum Erfolg? Das ist natürlich die HPE7-J01 Dumps von ExamFragen.
HPE7-J01 Prüfungsinformationen: https://www.examfragen.de/HPE7-J01-pruefung-fragen.html
P.S. Kostenlose und neue HPE7-J01 Prüfungsfragen sind auf Google Drive freigegeben von ExamFragen verfügbar: https://drive.google.com/open?id=1FDtt9VoFyxVYYAqpwGhQ-AuGOM1kx7KP