VCESoft 培訓資源是個很了不起的資源網站,包括了Microsoft 的 DP-750 考試材料,研究材料,技術材料。認證培訓和詳細的解釋和答案。還有完善的售后服務,我們對所有購買 DP-750 題庫學習資料的客戶提供跟蹤服務,在你購買 DP-750 題庫學習資料后的半年內,享受免費升級題庫學習資料的服務。如果在這期間,Microsoft DP-750 的考試知識點發生變動,我們會在第一時間更新相關題庫學習資料,并免費提供給你下載。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 3: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
VCESoft提供給你最權威全面的DP-750考試考古題,命中率極高,考試中會出現的問題可能都包含在這些考古題裏了,我們也會隨著大綱的變化隨時更新考古題。它可以避免你為考試浪費過多的時間和精力,助你輕鬆高效的通過考試。即便您沒有通過考試,我們也將承諾全額退款!所以你將沒有任何損失。機會是留給有準備的人的,希望你不要錯失良機。
問題 #84
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
答案:A
解題說明:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
問題 #85
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.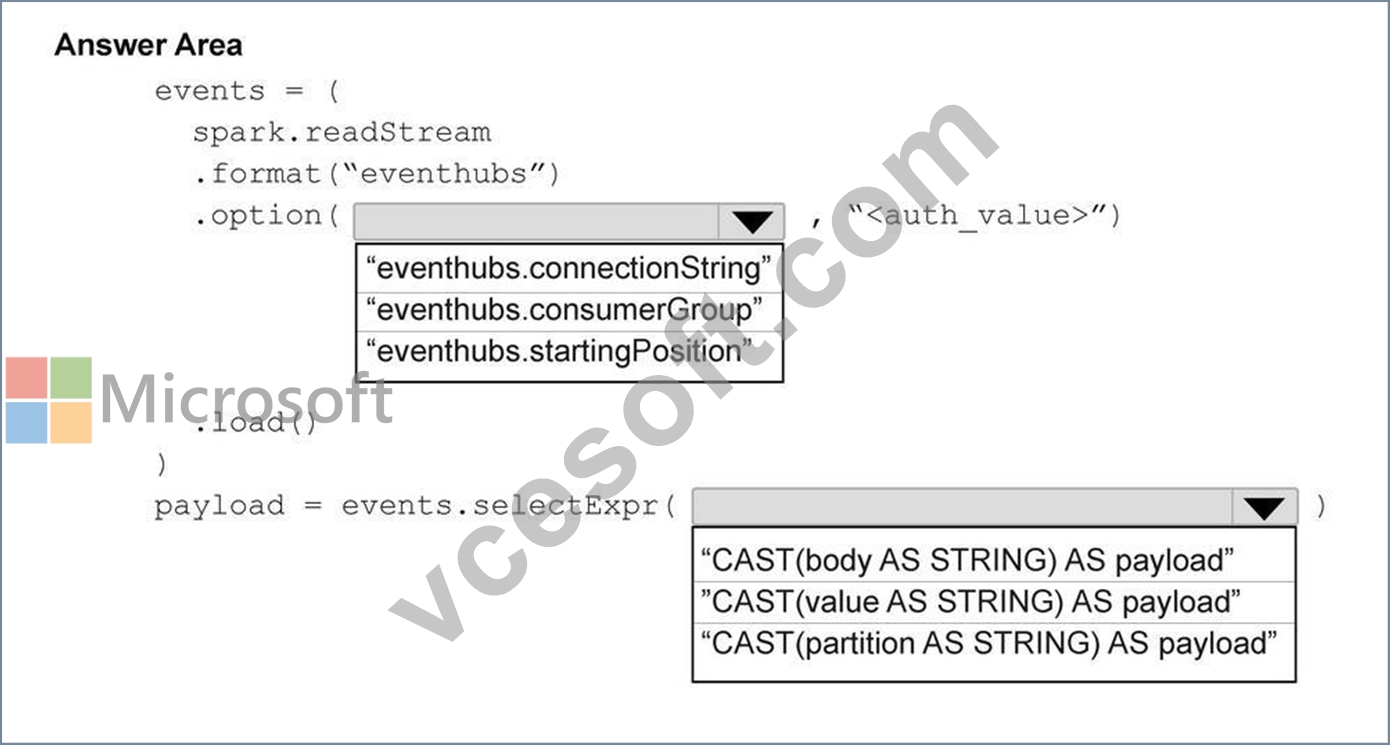
答案:
解題說明: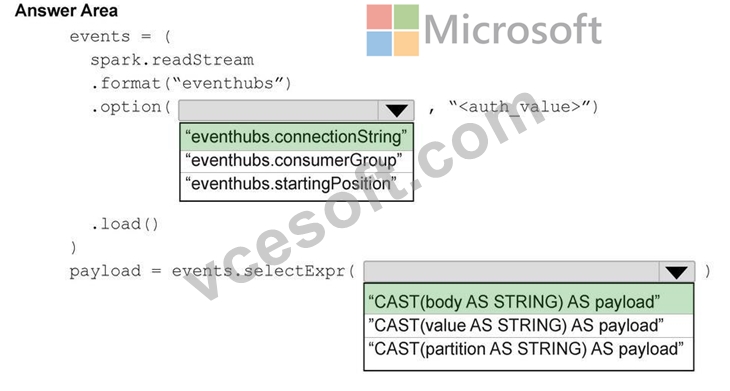
問題 #86
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
答案:A
解題說明:
The correct answer is D - Continuous trigger.
A Continuous trigger keeps the job running as a perpetual loop. As soon as one micro-batch or iteration completes, the next begins. New records are picked up with the shortest possible latency - as close to real- time as a Lakeflow Jobs pipeline gets.
File Arrival (Option B) is event-driven but introduces per-file trigger overhead and is best suited for file-based ingestion rather than continuous streaming workloads. Scheduled (Option C) runs at fixed clock intervals - if new data arrives between runs, it waits until the next scheduled execution. Manual (Option A) requires a human to start each run.
The question specifies serverless compute, which pairs naturally with Continuous trigger because serverless handles cluster lifecycle automatically - the job stays active without managing a persistent cluster. 'New records must be processed as soon as they become available' is the exact use case the Continuous trigger is designed for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers
問題 #87
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.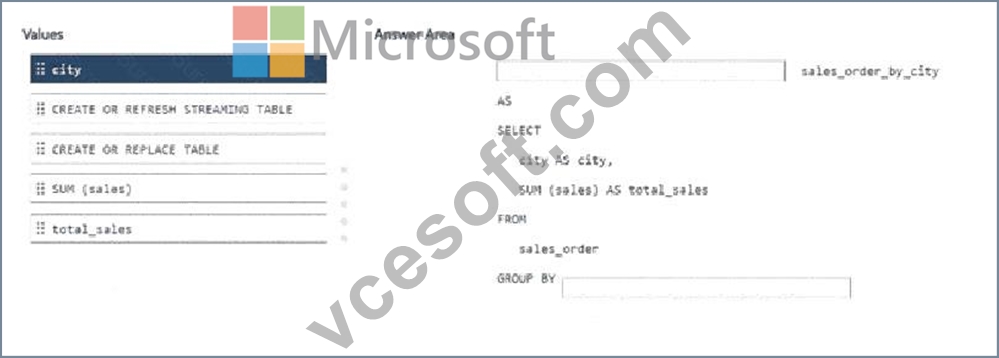
答案:
解題說明: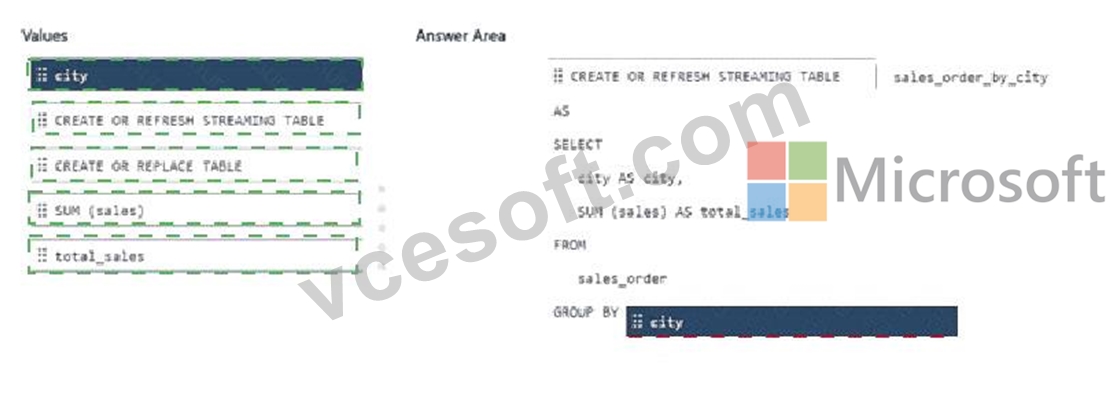
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
問題 #88
A data engineer notices slow query performance on a large Delta table in Azure Databricks. The table has frequent updates and deletes. Which action best improves query performance?
答案:A
解題說明:
OPTIMIZE compacts small files into larger ones, reducing file scan overhead. ZORDER improves data skipping by co-locating related column values. This combination significantly improves query performance on frequently filtered columns. Increasing cluster size does not address file fragmentation. Converting to Parquet removes Delta benefits like ACID transactions.
問題 #89
......
我們VCESoft網站的Microsoft培訓資料是沒有網站可以與之比較的。它是空前絕後的真實,準確,為了幫助每位考生順利通過考試,我們的DP-750精英團隊不斷探索。我可以毫不猶豫的說這絕對是一份具有針對性的培訓資料。我們VCESoft網站不僅產品真實,而且價格也很合理,當你選擇我們的產品,我們還提供一年的免費更新,讓你更在充裕的時間裏準備DP-750考試,這樣也可以消除你對考試緊張的心理,達到一個兩全其美的辦法了。
最新DP-750考古題: https://www.vcesoft.com/DP-750-pdf.html