Pass Guaranteed 2026 Professional-Cloud-DevOps-Engineer: Accurate Google Cloud Certified - Professional Cloud DevOps Engineer Exam Certification Questions

P.S. Free & New Professional-Cloud-DevOps-Engineer dumps are available on Google Drive shared by BraindumpsIT: https://drive.google.com/open?id=1wCNwBBFWylOCaArceqX1wS57-ULSX_Z-
The APP version of our Professional-Cloud-DevOps-Engineer study guide provides you with mock exams, time-limited exams, and online error correction and let you can review on any electronic device. So that you can practice our Professional-Cloud-DevOps-Engineer exam questions on Phone or IPAD, computer as so on. At the same time, for any version, we do not limit the number of downloads and the number of concurrent users, you can even buy Professional-Cloud-DevOps-Engineer Learning Materials together with your friends, which undoubtedly saves you a lot of overhead.
| Section | Weight | Objectives |
|---|
| Implementing observability and troubleshooting | 20% | - Optimize observability strategy
- 1. Reduce noise and prioritize signals
- 2. Integrate observability into development
- 3. Scale monitoring for large environments
- Troubleshoot complex issues
- 1. Trace requests end-to-end
- 2. Isolate problems across layers
- 3. Analyze performance and latency
- Build monitoring and logging systems
- 1. Create dashboards and alerts
- 2. Collect and analyze metrics, logs, traces
- 3. Use Cloud Monitoring, Cloud Logging, Cloud Trace
|
| Building and implementing CI/CD pipelines | 25% | - Design CI/CD pipelines
- 1. Integrate artifact management
- 2. Plan pipelines for apps, infrastructure, ML workloads
- 3. Support hybrid/multi-cloud deployment
- Implement and secure pipelines
- 1. Automate build, test, and deployment stages
- 2. Manage pipeline secrets and credentials
- 3. Enforce security scanning and compliance checks
- Optimize and maintain pipelines
- 1. Improve speed and reliability
- 2. Monitor pipeline performance
- 3. Handle rollbacks and versioning
|
| Applying site reliability engineering practices | 18% | - Define reliability goals
- 1. Align reliability with business needs
- 2. Use error budgets to balance change and stability
- 3. Establish SLIs, SLOs, SLAs
- Design for resilience
- 1. Test failure scenarios and recovery
- 2. Automate remediation and self-healing
- 3. Plan redundancy and fault tolerance
- Manage incidents and outages
- 1. Detect and respond to issues quickly
- 2. Perform postmortems and root cause analysis
- 3. Implement improvements to prevent recurrence
|
| Bootstrapping and maintaining a Google Cloud organization | 20% | - Design resource hierarchy
- 1. Plan shared networking and connectivity
- 2. Organize resources by project/folder/application
- 3. Define IAM policies and access control
- Set up governance and compliance
- 1. Manage resource quotas and limits
- 2. Implement organization policies
- 3. Configure audit logging and monitoring
- Manage configuration and deployment
- 1. Enforce consistency across environments
- 2. Use Infrastructure as Code tools
- 3. Automate resource provisioning
|
| Optimizing performance and cost | 17% | - Balance cost, performance, and reliability
- 1. Make tradeoff decisions based on data
- 2. Optimize over time
- 3. Plan capacity and scaling
- Improve system performance
- 1. Tune applications and infrastructure
- 2. Optimize resource allocation
- 3. Use caching and content delivery
- Apply FinOps practices
- 1. Use spot instances and committed use discounts
- 2. Monitor and analyze cloud costs
- 3. Right-size resources and eliminate waste
|
>> Professional-Cloud-DevOps-Engineer Certification Questions <<
Answers Professional-Cloud-DevOps-Engineer Real Questions - Latest Professional-Cloud-DevOps-Engineer Test Simulator
The Professional-Cloud-DevOps-Engineer Practice Questions are designed and verified by experienced and renowned Google Cloud Certified - Professional Cloud DevOps Engineer Exam exam trainers. They work collectively and strive hard to ensure the top quality of BraindumpsIT Professional-Cloud-DevOps-Engineer exam practice questions all the time. The Professional-Cloud-DevOps-Engineer Exam Questions are real, updated, and error-free that helps you in Google Cloud Certified - Professional Cloud DevOps Engineer Exam exam preparation and boost your confidence to crack the upcoming Professional-Cloud-DevOps-Engineer exam easily.
Google Cloud Certified - Professional Cloud DevOps Engineer Exam Sample Questions (Q85-Q90):
NEW QUESTION # 85
You manage an application that runs in Google Kubernetes Engine (GKE) and uses the blue/green deployment methodology Extracts of the Kubernetes manifests are shown below
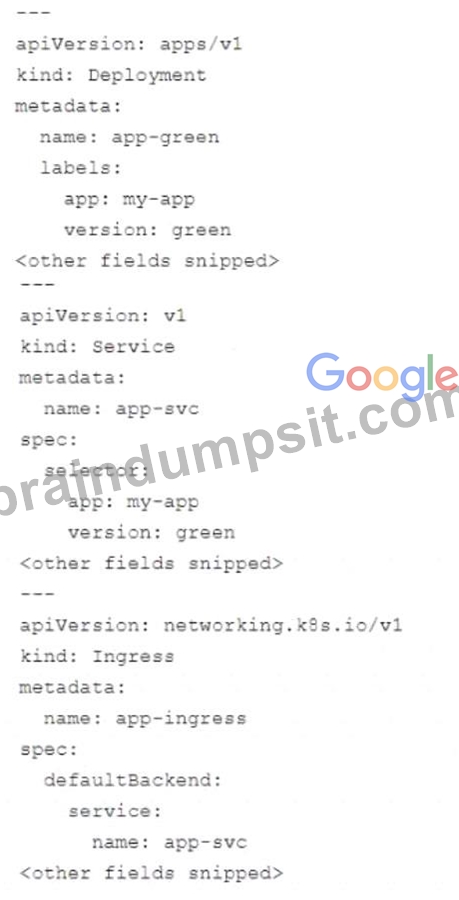
The Deployment app-green was updated to use the new version of the application During post-deployment monitoring you notice that the majority of user requests are failing You did not observe this behavior in the testing environment You need to mitigate the incident impact on users and enable the developers to troubleshoot the issue What should you do?
- A. Update the Deployment ape-green to use the previous version of the application
- B. Change the selector on the Service app-2vc to app: my-app.
- C. Update the Deployment app-blue to use the new version of the application
- D. Change the selector on the Service app-svc to app: my-app, version: blue
Answer: D
Explanation:
Explanation
The best option for mitigating the incident impact on users and enabling the developers to troubleshoot the issue is to change the selector on the Service app-svc to app: my-app, version: blue. A Service is a resource that defines how to access a set of Pods. A selector is a field that specifies which Pods are selected by the Service. By changing the selector on the Service app-svc to app: my-app, version: blue, you can ensure that the Service only routes traffic to the Pods that have both labels app: my-app and version: blue. These Pods belong to the Deployment app-blue, which uses the previous version of the application. This way, you can mitigate the incident impact on users by switching back to the working version of the application. You can also enable the developers to troubleshoot the issue with the new version of the application in the Deployment app-green without affecting users.
NEW QUESTION # 86
You are designing a system with three different environments: development, quality assurance (QA), and production. Each environment will be deployed with Terraform and has a Google Kubernetes Engine Enterprise (GKE Enterprise) cluster created so that application teams can deploy their applications. Config Sync will be used and templated to deploy infrastructure-level resources in each GKE Enterprise cluster. All users (for example, infrastructure operators and application owners) will use GitOps. How should you structure your source control repositories for both infrastructure as code (IaC) and application code?
- A. Cloud Infrastructure (Terraform) repository is shared: different branches are different environmentsGKE Enterprise Infrastructure (Config Sync Kustomize manifests) repository is shared:
different overlay directories are different environmentsApplication (app source code) repository is shared: different directories are different features - B. Cloud Infrastructure (Terraform) repository is shared: different directories are different environmentsGKE Enterprise Infrastructure (Config Sync Kustomize manifests) repositories are separated: different branches are different environmentsApplication (app source code) repositories are separated: different branches are different features
- C. Cloud Infrastructure (Terraform) repositories are separated: different branches are different environmentsGKE Enterprise Infrastructure (Config Sync Kustomize manifests) repositories are separated: different overlay directories are different environmentsApplication (app source code) repositories are separated: different branches are different features
- D. Cloud Infrastructure (Terraform) repository is shared: different directories are different environmentsGKE Enterprise Infrastructure (Config Sync Kustomize manifests) repository is shared:
different overlay directories are different environmentsApplication (app source code) repositories are separated: different branches are different features
Answer: D
Explanation:
Comprehensive and Detailed Explanation:
To follow GitOps best practices and Google Cloud's recommended repository structure for Terraform (IaC), Config Sync, and application code, we should use a shared repository for Terraform and Config Sync while keeping application repositories separate.
Cloud Infrastructure (Terraform) repository is shared # This allows infrastructure teams to manage all environments in a single repository with different directories per environment (dev, QA, production). This is the standard approach to structuring Terraform repositories.
GKE Enterprise Infrastructure (Config Sync) repository is shared # Using Kustomize overlays per environment (instead of separate repositories) aligns with Config Sync's best practices and makes managing configurations easier.
Application repositories are separated, using different branches for features # This allows application teams to follow the Git branching model (feature branches, main branch, release branches, etc.) without affecting infrastructure.
#Official Reference:
Config Sync Best Practices
Terraform Structure Best Practices
GitOps Best Practices
NEW QUESTION # 87
Your company is migrating its production systems to Google Cloud. You need to implement site reliability engineering (SRE) practices during the migration to minimize customer impact from potential future incidents. Which two SRE practices should you implement?
Choose 2 answers
- A. Ensure that all teams can modify the production environment to resolve issues.
- B. Ensure that full autonomy and permissions are only granted to the on-call team.
- C. Automate common tasks to analyze key impact information and intelligently suggest mitigating actions for the on-call team.
- D. Create an alerting mechanism for your SRE team based on your system's internal behavior.
- E. Create up-to-date playbooks with instructions for debugging and mitigating issues.
Answer: C,E
Explanation:
Comprehensive and Detailed Explanation From General SRE Principles and Google Cloud Knowledge:
Site Reliability Engineering (SRE) emphasizes reliability, automation, and a data-driven approach to operations. The goal is to minimize the "time to detect" (TTD) and "time to resolve" (TTR) for incidents.
Option A (Ensure that full autonomy and permissions are only granted to the on-call team): While the on-call team needs appropriate permissions to act decisively during an incident, granting full autonomy and only to them can be a bottleneck and goes against the principle of least privilege if not carefully scoped. Broader teams might need specific, controlled access for their responsibilities. SRE encourages empowering teams but within a structured framework.
Option B (Automate common tasks to analyze key impact information and intelligently suggest mitigating actions for the on-call team): This is a core SRE practice. Automation reduces toil, speeds up response, and ensures consistency. Analyzing impact and suggesting mitigations helps the on-call team resolve issues faster and more effectively.
Option C (Ensure that all teams can modify the production environment to resolve issues): This is generally a bad practice and against SRE principles of controlled changes and reducing the blast radius of errors.
Production changes should be managed, audited, and ideally automated, not open to modification by all teams, as this increases the risk of unintended incidents.
Option D (Create an alerting mechanism for your SRE team based on your system's internal behavior): While alerting is crucial, SRE emphasizes alerting on symptoms that affect users (Service Level Objectives - SLOs) rather than just internal behavior or causes. Alerting solely on internal behavior can lead to alert fatigue and may not correlate directly with user impact. Good alerting focuses on user-facing impact first.
Option E (Create up-to-date playbooks with instructions for debugging and mitigating issues): Playbooks (or runbooks) are essential in SRE. They document known issues, troubleshooting steps, and mitigation procedures. Keeping them up-to-date ensures that on-call engineers can respond to incidents quickly and consistently, even for less common issues, thereby minimizing customer impact.
Therefore, automating incident response tasks (B) and maintaining clear, actionable playbooks (E) are two key SRE practices to implement for minimizing customer impact.
Reference (Based on SRE principles):
The SRE books by Google (e.g., "Site Reliability Engineering: How Google Runs Production Systems") heavily emphasize automation to reduce toil and the importance of playbooks for incident management.
Google Cloud SRE solutions: https://cloud.google.com/sre
Specifically, regarding playbooks and automation:"Playbooks should be living documents, updated regularly as systems change and new incidents provide new lessons."
"SREs aim to automate repetitive tasks (toil) to free up time for engineering projects that improve reliability."
NEW QUESTION # 88
You have an application that runs on Cloud Run. You want to use live production traffic to test a new version of the application while you let the quality assurance team perform manual testing. You want to limit the potential impact of any issues while testing the new version, and you must be able to roll back to a previous version of the application if needed. How should you deploy the new version?
Choose 2 answers
- A. Deploy the application as a new Cloud Run service.
- B. Deploy the new application version and use the -no-traffic option Route production traffic to the revision's URL.
- C. Deploy the new application version and split traffic to the new version.
- D. Deploy a new Cloud Run revision with a tag and use the -no-traffic option.
- E. Deploy a new Cloud Run revision without a tag and use the -no-traffic option.
Answer: C,D
NEW QUESTION # 89
You have migrated an e-commerce application to Google Cloud Platform (GCP). You want to prepare the application for the upcoming busy season. What should you do first to prepare for the busy season?
- A. Pre-provision double the compute power used last season, expecting growth.
- B. Create a runbook on inflating the disaster recovery (DR) environment if there is growth.
- C. Enable AutoScaling on the production clusters, in case there is growth.
- D. Load teat the application to profile its performance for scaling.
Answer: C
NEW QUESTION # 90
......
Your purchase with BraindumpsIT is safe and fast. We use Paypal for payment and committed to keep your personal information secret and never share your information to the third part without your permission. In addition, our Google Professional-Cloud-DevOps-Engineer practice exam torrent can be available for immediate download after your payment. Besides, we guarantee you 100% pass for Professional-Cloud-DevOps-Engineer Actual Test, in case of failure, you can ask for full refund. The refund procedure is very easy. You just need to show us your Professional-Cloud-DevOps-Engineer failure certification, then after confirmation, we will deal with your case.
Answers Professional-Cloud-DevOps-Engineer Real Questions: https://www.braindumpsit.com/Professional-Cloud-DevOps-Engineer_real-exam.html
- Customizable PDF Questions for Improved Success in Google Professional-Cloud-DevOps-Engineer Certification Exam 🌷 Open website ➡ www.examcollectionpass.com ️⬅️ and search for ➠ Professional-Cloud-DevOps-Engineer 🠰 for free download 🌃Exam Professional-Cloud-DevOps-Engineer Dumps
- 100% Pass Quiz 2026 Google Perfect Professional-Cloud-DevOps-Engineer Certification Questions ➖ ⮆ www.pdfvce.com ⮄ is best website to obtain 【 Professional-Cloud-DevOps-Engineer 】 for free download 😈Professional-Cloud-DevOps-Engineer Latest Cram Materials
- Exam Professional-Cloud-DevOps-Engineer Braindumps 🚣 Vce Professional-Cloud-DevOps-Engineer Download 🤟 Exam Professional-Cloud-DevOps-Engineer Dumps 🐊 Search for ➠ Professional-Cloud-DevOps-Engineer 🠰 and download it for free immediately on ☀ www.troytecdumps.com ️☀️ 🥖Professional-Cloud-DevOps-Engineer New Dumps Files
- High Hit Rate Professional-Cloud-DevOps-Engineer Certification Questions Provide Prefect Assistance in Professional-Cloud-DevOps-Engineer Preparation 😢 Enter ⮆ www.pdfvce.com ⮄ and search for 「 Professional-Cloud-DevOps-Engineer 」 to download for free 🧢Professional-Cloud-DevOps-Engineer Latest Cram Materials
- Professional-Cloud-DevOps-Engineer Valid Study Guide ⭐ Valid Exam Professional-Cloud-DevOps-Engineer Preparation 🌷 Vce Professional-Cloud-DevOps-Engineer Download ➕ Search for ▷ Professional-Cloud-DevOps-Engineer ◁ and download exam materials for free through ➠ www.vceengine.com 🠰 🐝Real Professional-Cloud-DevOps-Engineer Exam Questions
- Professional-Cloud-DevOps-Engineer Test Simulator Online 🏀 Professional-Cloud-DevOps-Engineer Valid Test Pdf 🍝 Exam Professional-Cloud-DevOps-Engineer Dumps 🔎 Search for ➤ Professional-Cloud-DevOps-Engineer ⮘ and download exam materials for free through ☀ www.pdfvce.com ️☀️ 🍁Exam Dumps Professional-Cloud-DevOps-Engineer Pdf
- Exam Dumps Professional-Cloud-DevOps-Engineer Pdf 🍳 Professional-Cloud-DevOps-Engineer Valid Study Guide 🏥 Professional-Cloud-DevOps-Engineer Test Simulator Online 😱 Simply search for ▶ Professional-Cloud-DevOps-Engineer ◀ for free download on 《 www.exam4labs.com 》 🥢Professional-Cloud-DevOps-Engineer Valid Test Pdf
- Professional-Cloud-DevOps-Engineer Valid Study Guide 🐪 Reliable Professional-Cloud-DevOps-Engineer Braindumps 💛 Professional-Cloud-DevOps-Engineer New Dumps Files 🧩 Enter ➥ www.pdfvce.com 🡄 and search for ▷ Professional-Cloud-DevOps-Engineer ◁ to download for free 🎴Vce Professional-Cloud-DevOps-Engineer Download
- Free PDF Google - Efficient Professional-Cloud-DevOps-Engineer Certification Questions 🚺 The page for free download of 【 Professional-Cloud-DevOps-Engineer 】 on ➡ www.vceengine.com ️⬅️ will open immediately 🔍Professional-Cloud-DevOps-Engineer Minimum Pass Score
- Professional-Cloud-DevOps-Engineer Online Test 🤾 Professional-Cloud-DevOps-Engineer Valid Study Guide 🚅 Exam Professional-Cloud-DevOps-Engineer Dumps 🤑 Go to website ➠ www.pdfvce.com 🠰 open and search for ➽ Professional-Cloud-DevOps-Engineer 🢪 to download for free 🌾Exam Dumps Professional-Cloud-DevOps-Engineer Pdf
- Professional-Cloud-DevOps-Engineer Hot Questions 🚟 Exam Professional-Cloud-DevOps-Engineer Dumps 🥛 Professional-Cloud-DevOps-Engineer Discount 🦋 Simply search for ➽ Professional-Cloud-DevOps-Engineer 🢪 for free download on 「 www.prep4sures.top 」 🕓Professional-Cloud-DevOps-Engineer New Dumps Files
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of BraindumpsIT Professional-Cloud-DevOps-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1wCNwBBFWylOCaArceqX1wS57-ULSX_Z-