Revision of your Databricks-Certified-Data-Engineer-Professional exam learning is as essential as the preparation. For that purpose, Databricks-Certified-Data-Engineer-Professional exam dumps contains specially created real exam like practice questions and answers. They are in fact meant to provide you the opportunity to revise your learning and overcome your Databricks-Certified-Data-Engineer-Professional Exam fear by repeating the practice tests as many times as you can. Preparation for Databricks-Certified-Data-Engineer-Professional exam using our Databricks-Certified-Data-Engineer-Professional exam materials are sure to help you obtain your targeted percentage too.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Governance | 7% | - Manage data assets and metadata - Enforce data policies and standards - Use Unity Catalog for governance |
| Topic 2: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management - Enforce data quality standards - Apply data cleansing and validation rules |
| Topic 3: Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing - Manage cross-platform data access - Implement Lakehouse Federation |
| Topic 4: Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs - Troubleshoot and debug pipelines - Implement CI/CD and DevOps practices |
| Topic 5: Data Modelling | 6% | - Design Medallion Architecture - Implement dimensional and relational models - Optimize table design and partitioning |
| Topic 6: Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit - Ensure data privacy and compliance - Implement access control and permissions |
| Topic 7: Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic - Use Databricks-specific libraries and APIs - Write efficient and maintainable code |
| Topic 8: Monitoring and Alerting | 10% | - Set up alerts and notifications - Track data lineage and metrics - Monitor pipeline performance and health |
| Topic 9: Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Apply cost management best practices - Optimize compute and storage resources |
| Topic 10: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Ingest data from diverse sources - Use Auto Loader and structured streaming |
>> Latest Databricks-Certified-Data-Engineer-Professional Test Voucher <<
Databricks-Certified-Data-Engineer-Professional learning materials have a variety of self-learning and self-assessment functions to test learning outcomes. Databricks-Certified-Data-Engineer-Professional study guide is like a tutor, not only gives you a lot of knowledge, but also gives you a new set of learning methods. Databricks-Certified-Data-Engineer-Professional Exam Practice is also equipped with a simulated examination system that simulates the real exam environment so that you can check your progress at any time.
NEW QUESTION # 118
A junior developer complains that the code in their notebook isn't producing the correct results in the development environment. A shared screenshot reveals that while they're using a notebook versioned with Databricks Repos, they're using a personal branch that contains old logic. The desired branch named dev-2.3.9 is not available from the branch selection dropdown.
Which approach will allow this developer to review the current logic for this notebook?
Answer: D
Explanation:
This is the correct answer because it will allow the developer to update their local repository with the latest changes from the remote repository and switch to the desired branch. Pulling changes will not affect the current branch or create any conflicts, as it will only fetch the changes and not merge them. Selecting the dev-2.3.9 branch from the dropdown will checkout that branch and display its contents in the notebook.
NEW QUESTION # 119
A job runs four independent tasks (X, Y, Z, W) in parallel to process regional sales data. The Data Engineering team recently updated its cluster policy to ban cost-prohibitive instance types. Task Y now fails due to the newly enforced cluster policy restricting the use of a specific instance type.
A data engineer needs to resolve the failure quickly without disrupting the other tasks. How should the data engineer resolve the failure of tasks?
Answer: D
Explanation:
Repair run allows re-running only the failed task without affecting successfully completed tasks.
Overriding the cluster configuration for the specific task resolves the policy violation quickly while keeping the rest of the job intact and minimizing disruption.
NEW QUESTION # 120
A data engineer needs to implement column masking for a sensitive column in a Unity Catalog- managed table. The masking logic must dynamically check if users belong to specific groups defined in a separate table (group_access) that maps groups to allowed departments. Which approach should the engineer use to efficiently enforce this requirement?
Answer: D
Explanation:
Databricks Unity Catalog supports dynamic column masking, where masking logic can be implemented using SQL functions or UDFs that reference external mapping tables or metadata for context-aware access control.
By referencing the group_access table inside the masking function, the mask dynamically evaluates whether a requesting user belongs to an authorized group. If permitted, the original column value is returned; otherwise, a masked value (such as NULL or asterisks) is shown.
This method enables fine-grained, data-driven masking policies while maintaining a single authoritative access mapping source.
Hardcoding values (A) reduces flexibility, and row filters (D) apply to entire rows rather than specific columns. Therefore, C correctly aligns with Databricks best practices for dynamic masking.
NEW QUESTION # 121
The data engineering team maintains the following code: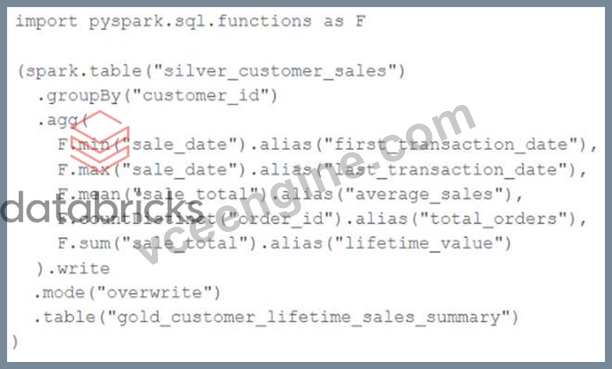
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: C
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 122
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
Answer: E
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 123
......
Without no doubt that accuracy of information is of important for a Databricks-Certified-Data-Engineer-Professional study material. It can be said exactly that the precision and accuracy of our VCEEngine’s Databricks-Certified-Data-Engineer-Professional study materials are beyond question. All questions and answers have passed the test of time and are approved by experienced professionals who recommend them as the easiest route to certification testing. Every customer who has used our Databricks-Certified-Data-Engineer-Professional Study Materials consider this to be a material that changes their life a lot, so they recommend it as the easiest way to pass the certification test. Our Databricks-Certified-Data-Engineer-Professional study materials are constantly updated by our experts and improved according to the changing standards of the actual examination standards. We can guarantee that the information on our questions is absolutely true and valid.
Databricks-Certified-Data-Engineer-Professional Latest Exam Cost: https://www.vceengine.com/Databricks-Certified-Data-Engineer-Professional-vce-test-engine.html